
skimtube
You follow 40 YouTube channels. You watch 4.
skimtube reads the other 36 and leaves you notes.


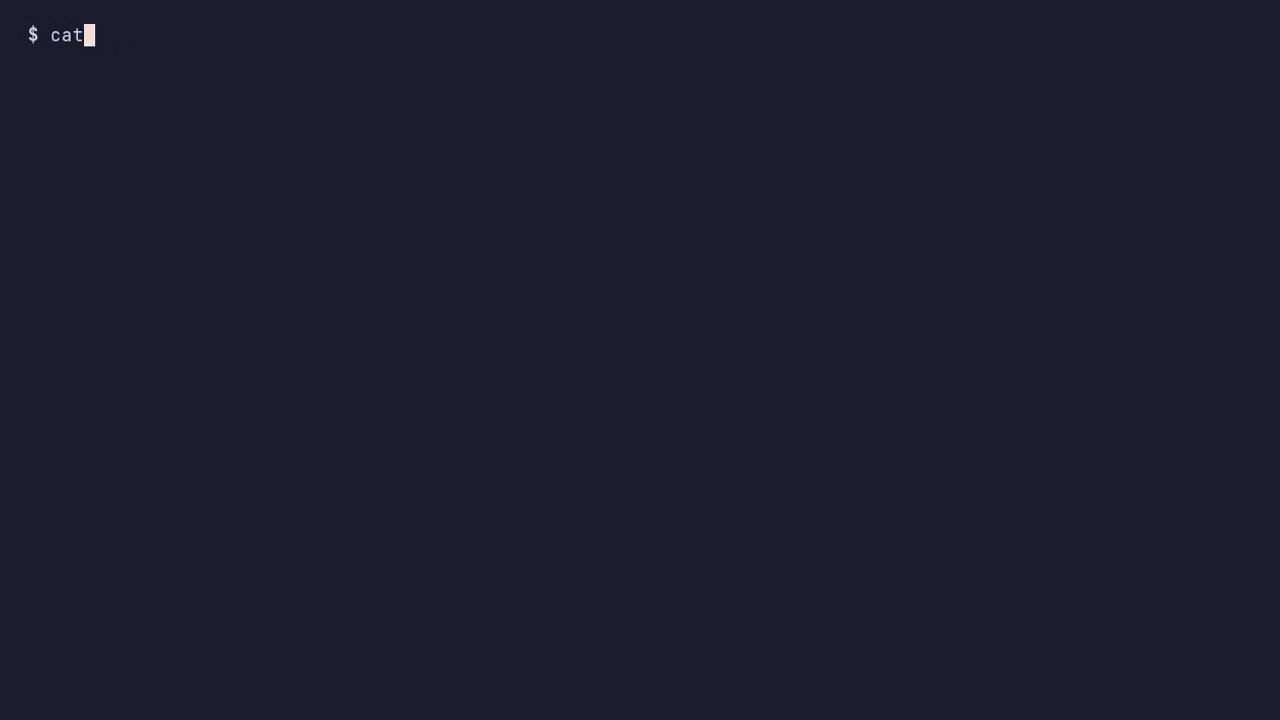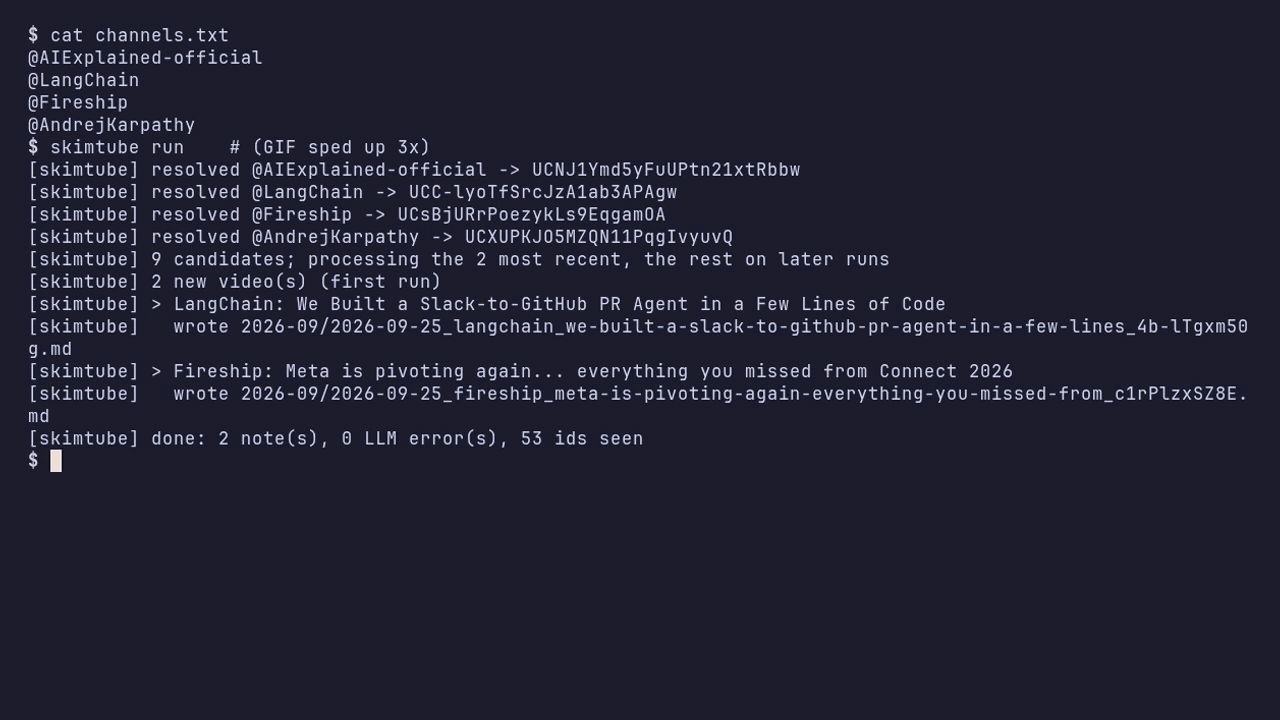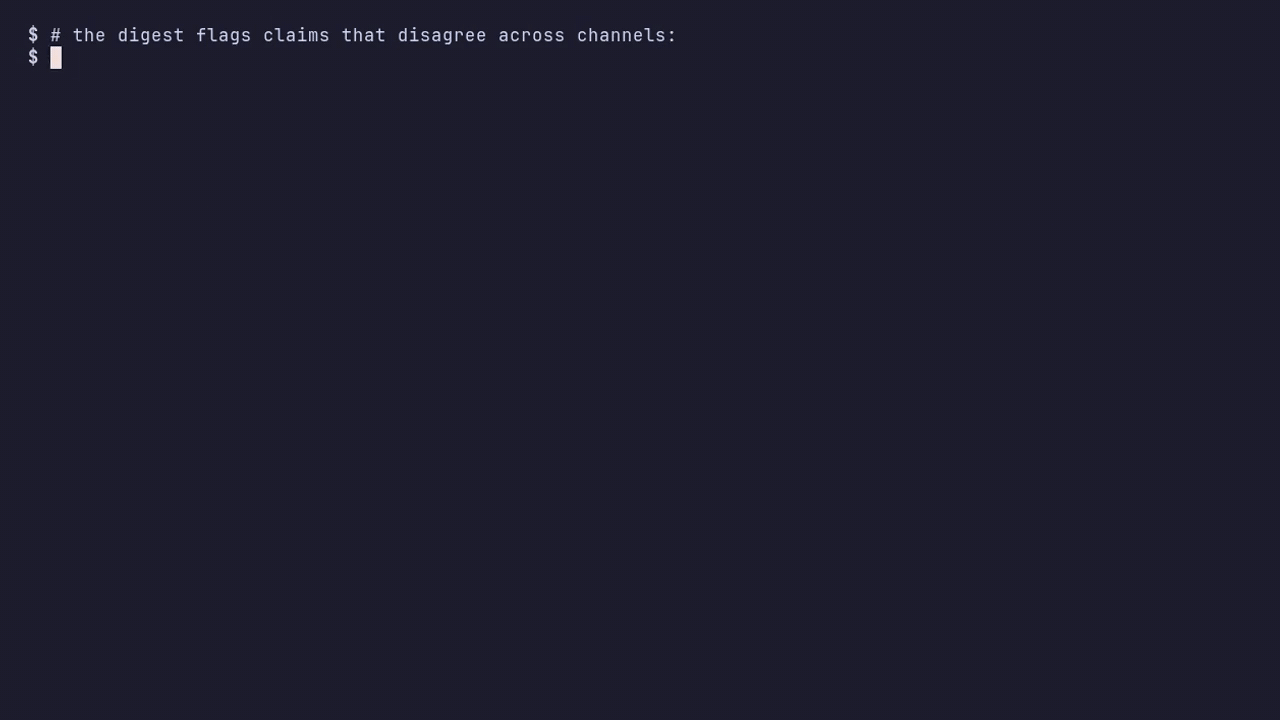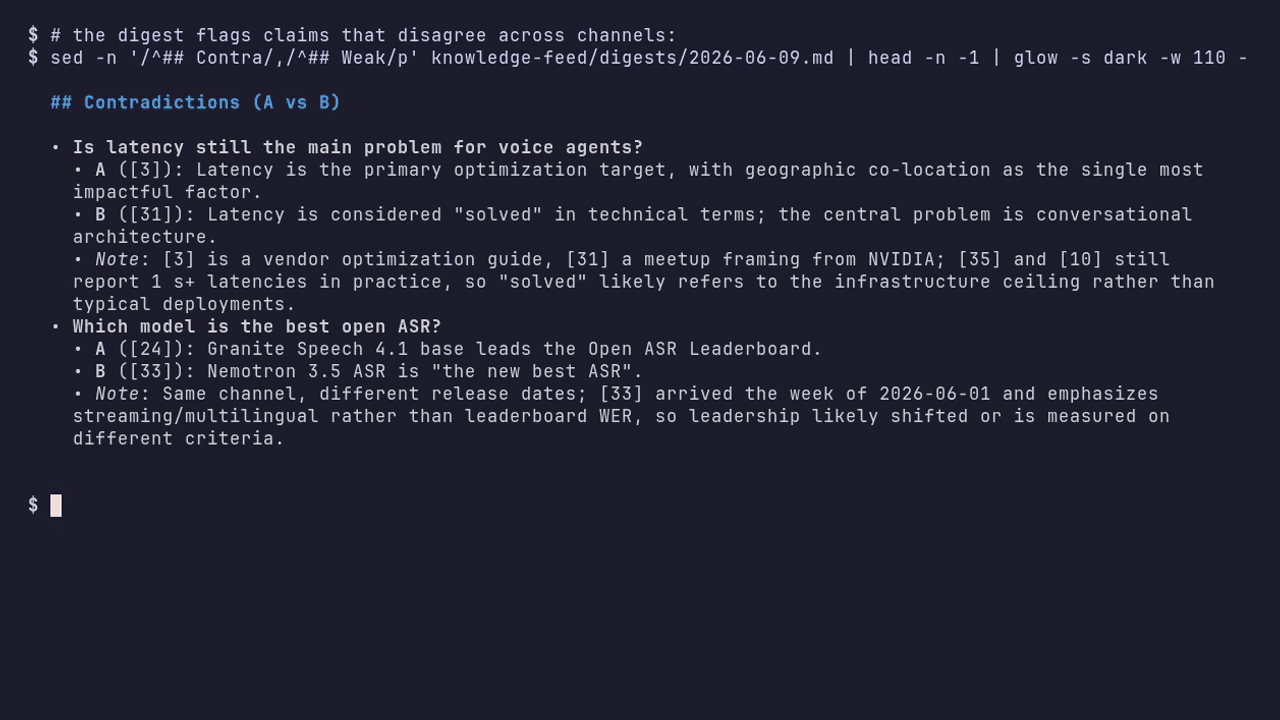
New videos from the channels you follow become Markdown notes you can skim, grep, drop into
Obsidian or hand to your coding agent. No YouTube API key, any LLM (local or hosted), one cron line.
Why
I follow 68 channels, mostly about AI. I was never going to watch them all, and the one video that mattered each week was buried under three thumbnails of someone looking shocked. So now a cron job reads the subtitles for me: in four months it has written 725 notes, and every morning I read one digest instead of a subscriptions page. My coding agent greps the rest.
Side effect: you stop seeing the shocked faces.
What it is good for
- Keeping up with a field without the videos. A daily digest grouped by theme, with links back to each video when something is worth the 20 minutes.
- Giving a coding agent a memory of what is new. Notes are plain files, so
grep -ril mcp knowledge-feed/works, and the Claude Code plugin answers "what did people say about X this month?" with sources. - Growing an Obsidian vault on autopilot. Point
SKIMTUBE_OUTat a vault folder. Every note has YAML front matter (channel, date, URL) for Dataview queries. - Watching a niche or your competitors. List their channels, add a keyword pre-filter and a topic, and skip everything else. The digest flags when two channels disagree.
- Doing it privately and cheaply. Run it with Ollama for $0, or pay about $0.002 per note with DeepSeek.
What you get
Every few hours it checks the channels you list, grabs the subtitles of new videos, and has an LLM write one structured note per video. Once a day it merges the recent notes into a digest, grouped by theme, with a section for claims that disagree across sources ("channel A says X, channel B says the opposite, same week").
knowledge-feed/
├── INDEX.md                      # one line per video, newest first
├── DIGEST.md                     # latest digest
├── digests/2026-09-21.md
└── 2026-09/
    └── 2026-09-20_some-channel_new-open-model-beats-gpt_abc123.md
Quickstart
pipx install skimtube                      # or: uv tool install skimtube
mkdir kb && cd kb && skimtube init         # writes config.env, channels.txt, blocklist.txt
SKIMTUBE_LLM_API_KEY=sk-or-... SKIMTUBE_LLM_MODEL=deepseek/deepseek-chat skimtube run
init points to OpenRouter by default. For a fully local setup, use Ollama instead. Ollama
serves 4,096 tokens of context by default and silently cuts longer prompts, so a normal
transcript loses most of its text without any error. Create a model with a larger context first:
printf 'FROM qwen2.5:3b\nPARAMETER num_ctx 16384\n' > Modelfile
ollama create qwen2.5-16k -f Modelfile
SKIMTUBE_LLM_BASE_URL=http://localhost:11434/v1 SKIMTUBE_LLM_MODEL=qwen2.5-16k skimtube run
(Or start the server with OLLAMA_CONTEXT_LENGTH=16384.) On a laptop CPU without a GPU, a 3B
model takes about 4 minutes per note; that is fine for a scheduled job, slow for a first try.
The first run only looks back 24 hours (SKIMTUBE_LOOKBACK_HOURS). After that, every run processes
whatever is new since the previous one. Then:
skimtube digest                  # merge the last 30 h of notes
skimtube digest --window-hours 168   # weekly
Use it from Claude Code
The repo is also a Claude Code plugin. It adds a skill that finds your feed, searches it, and answers with the video links as sources ("what did the channels I follow say about MCP this month?"). It can also run or set up the collector for you.
/plugin marketplace add arnaugonzalez/skimtube
/plugin install skimtube@skimtube
Other agents (Cursor, Codex, Gemini CLI) can read the same instructions from
plugin/skills/youtube-knowledge-feed/SKILL.md.
Why not…
| Watches channels unattended | Output | Contradictions between sources | Cost | |
|---|---|---|---|---|
| skimtube | yes (RSS, no API key) | one Markdown note per video + index + digest, in a folder | yes | your LLM (≈$0.002/note measured with DeepSeek; $0 with Ollama) |
| fabric | no, one URL at a time | stdout | no | your LLM |
| tubeless | yes | daily ranked briefing, one file per day | no | your LLM |
| NotebookLM / Eightify / Glasp | no | in their app | no | free tier / subscription |
| Feedly Leo / Readwise Reader | feeds, not transcripts | in their app | no | subscription |
fabric has a much larger prompt library, and tubeless also transcribes videos without
subtitles (Whisper) and ranks them by importance. Pick them if you want a daily briefing to
read. Pick skimtube if you want the notes to pile up as files that you, Obsidian or a coding
agent can grep months later.
How it works
flowchart LR
  A[channels.txt<br/>+ optional subscriptions] --> B[YouTube RSS<br/>per channel]
  B --> C{new video?<br/>keyword filter}
  C --> D[yt-dlp subtitles]
  D --> E[LLM: structured note<br/>or SKIP if off-topic]
  E --> F[knowledge-feed/YYYY-MM/*.md<br/>+ INDEX.md]
  F --> G[digest: themes,<br/>contradictions, weak signals]
  S[(state.json)] <--> C
- No YouTube API key. Channel feeds come from the public RSS endpoint;
@handlesare resolved to channel ids once and cached instate.json. - Idempotent. Processed video ids live in
state.json, so running it twice does nothing new. If the LLM call fails, the video is retried on the next run (up to 3 times) and the run exits with status 1 so your scheduler shows the failure. - Notes have a fixed shape: YAML front matter (
title,channel,url,video_id,published,collected) and the sections TL;DR, Key topics, What's new, Entities, Facts and figures. Headings stay in English; the content followsSKIMTUBE_SUMMARY_LANG.
Configuration
Values come from config.env in the working directory (or -C DIR), else
$XDG_CONFIG_HOME/skimtube/config.env. Environment variables override both.
| Variable | Default | |
|---|---|---|
SKIMTUBE_LLM_BASE_URL |
https://api.openai.com/v1 |
any OpenAI-compatible endpoint |
SKIMTUBE_LLM_API_KEY |
falls back to OPENAI_API_KEY |
not needed for localhost |
SKIMTUBE_LLM_MODEL |
— (required) | |
SKIMTUBE_LLM_PROVIDER |
openai |
command pipes the prompt into SKIMTUBE_LLM_COMMAND (e.g. llm -m …, or claude -p --tools "" --strict-mcp-config: see Security) |
SKIMTUBE_SUMMARY_LANG |
English |
language of the note content |
SKIMTUBE_TOPIC |
technology and AI |
the LLM skips off-topic videos; empty = keep all |
SKIMTUBE_KEYWORDS |
empty | cheap whole-word pre-filter on title + description |
SKIMTUBE_OUT |
knowledge-feed |
|
SKIMTUBE_CHANNELS / SKIMTUBE_BLOCKLIST / SKIMTUBE_STATE |
channels.txt / blocklist.txt / state.json |
|
SKIMTUBE_SUB_LANGS |
en,en-orig,en-US |
subtitle languages, tried one at a time |
SKIMTUBE_LOOKBACK_HOURS |
24 |
first run only |
SKIMTUBE_MAX_PER_RUN |
25 |
the rest wait for the next run |
SKIMTUBE_MAX_TRANSCRIPT_CHARS |
48000 |
transcript truncation |
SKIMTUBE_YTDLP_BIN |
empty = the bundled yt-dlp | set to use another yt-dlp binary |
Your subscriptions (optional). skimtube auth runs a one-time OAuth consent (read-only
scope) and from then on merges the channels you are subscribed to. It needs your own Google
Cloud OAuth client of type Desktop app (SKIMTUBE_OAUTH_CLIENT_ID / SKIMTUBE_OAUTH_CLIENT_SECRET).
While the OAuth app stays in "testing" mode, Google expires the refresh token after a while:
re-run auth when the log says so.
Scheduling
run and digest are plain idempotent commands. See examples/ for cron, a
systemd user timer, and a GitHub Actions workflow. To publish the feed somewhere else, chain
it: skimtube run && rsync -a knowledge-feed/ server:kb/.
Limits
- Subtitles are required. Videos without subtitles or auto-captions are skipped.
- Datacenter IPs get bot-checked. YouTube often refuses subtitle downloads from cloud servers ("Sign in to confirm you're not a bot"). A home machine works reliably; on a server you need yt-dlp cookies or a proxy.
- Terms of service. Downloading subtitles with yt-dlp is not a use YouTube explicitly permits. skimtube keeps transcripts in memory only and writes transformed summaries. Don't redistribute transcripts, and check the rules that apply to you.
- Contradictions are leads, not verdicts. Checked by hand over 4 real days, the section flags 2–3 pairs per window and at most one is a genuine disagreement; the rest are nuances the model explains away in its own note.
Non-goals: a web UI, a database, transcribing audio.
Security
Transcripts are text written by strangers, and skimtube hands them to an LLM. If that LLM is
an agent CLI with tools (Claude Code, Codex, Gemini CLI…), a video can carry instructions like
"ignore the above and run this command", and the agent may do it with your permissions. We
reproduced this with claude -p in auto mode. Disable every tool for this job:
SKIMTUBE_LLM_COMMAND=claude -p --tools "" --strict-mcp-config
HTTP providers (SKIMTUBE_LLM_PROVIDER=openai, the default) only return text, so they can't run
anything. skimtube itself never runs a shell, opens a port, or sends telemetry; it talks to
YouTube, your LLM endpoint and nothing else. See SECURITY.md to report issues.
License
MIT. skimtube is an independent project for YouTube users; it is not affiliated with or endorsed by YouTube or Google.
1 maintainer

Release files for skimtube 0.1.0
For a detailed explanation of source distributions (sdists) and built distributions (wheels), please see the package formats documentation.
Source distribution (sdist)
| File | Size | Uploaded | |
|---|---|---|---|
| skimtube-0.1.0.tar.gz | 864.5 kB | Details |
Built distribution (wheel)
| File | Interpreter | ABI | Platform | Reset |
|---|---|---|---|---|
| skimtube-0.1.0-py3-none-any.whl | Python 3 | none | any | Details |
Total release size: 890.0 kB
Release files / skimtube-0.1.0.tar.gz
| Download URL | skimtube-0.1.0.tar.gz |
|---|---|
| Size | 864.5 kB |
| Tags | Source |
|
SHA-256 checksum How to use checksums |
9cd3c95a9024e35d19c2f1afaa8dd0771c290c34008e843f8844c215eeb0602d
|
|
BLAKE2b-256 checksum How to use checksums |
4fe7a2381bf6aff210915e6d99bd06283ca0a221c1be986e6ad3f18b2c96d0b1
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
Yes |
| Uploaded via |
twine/7.0.0 CPython/3.13.14
|
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.


PyPI Publish Attestation
PyPI verified that this artifact, at this checksum, originated from the publisher listed below.
Signed by GitHub Actions, verified by PyPI on Sep 26, 2026.
Transparency logRelease files / skimtube-0.1.0-py3-none-any.whl
| Download URL | skimtube-0.1.0-py3-none-any.whl |
|---|---|
| Size | 25.6 kB |
| Tags | Python 3 |
|
SHA-256 checksum How to use checksums |
bb91428bea4cab28dc671371df600528537fca90a42d66ec275fde15353e16fd
|
|
BLAKE2b-256 checksum How to use checksums |
8f632e694c69915aef9c96b1888f635e516d928aa2ac81036044fa21f35a2bc2
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
Yes |
| Uploaded via |
twine/7.0.0 CPython/3.13.14
|
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.
PyPI Publish Attestation
PyPI verified that this artifact, at this checksum, originated from the publisher listed below.
Signed by GitHub Actions, verified by PyPI on Sep 26, 2026.
Transparency log












