
smallbatch
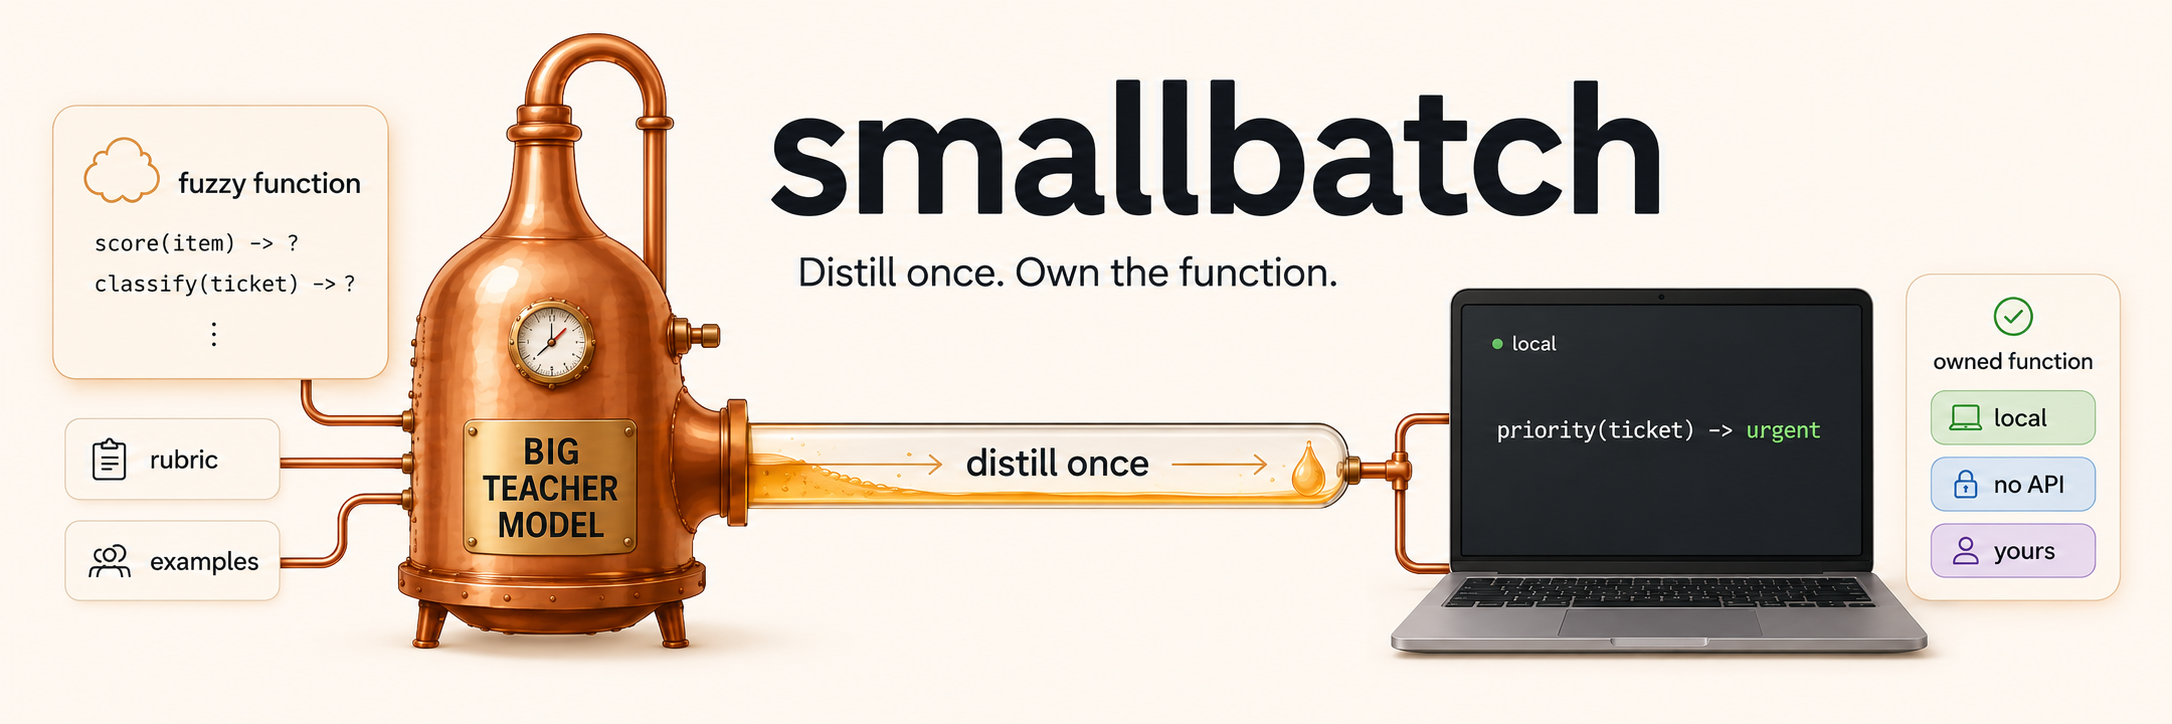
Smallbatch distills prompt-driven LLM decisions into small, tested local functions that run on a CPU.
Replace repeated LLM inference with a local CPU function you control, with clear evidence about the quality and operating tradeoffs.
Smallbatch is an alpha release. It measures decision fidelity: how closely a local function reproduces the supplied decisions on examples kept out of training. It does not establish that those decisions are correct or validate the prompt, imported decisions, or teacher behavior.
You provide a constrained decision prompt and representative inputs, either with existing decisions or with a callable LLM teacher: the larger model whose example decisions you approve and want the local function to reproduce. Smallbatch builds and compares CPU-runnable candidates, meaning alternative local implementations of those decisions. You explicitly select one or none.
When It Fits
Use Smallbatch when the same constrained prompt is repeatedly producing a bounded integer, one choice from a fixed list (an enum), or a structured combination of those outputs, and the prompt, output meaning, and input distribution are stable enough to compile.
Keep the original LLM call when the task is open-ended, the prompt changes frequently, examples are not representative, or a local function cannot express the output.
What It Builds
You do not need to predict which local approach will work best. Configure the ones you want Smallbatch to try; it trains each candidate, runs each through the same CPU evaluation, and reports the quality and operating tradeoffs.
| Approach | What it is | Why it might fit |
|---|---|---|
| TF-IDF (term frequency-inverse document frequency) | A conventional classifier driven mostly by which words and phrases appear in the input. | Usually the fastest and smallest option. It works well for literal wording patterns but may miss similar meanings expressed in different language. |
| SetFit | A small model that learns useful sentence representations, often called embeddings, and trains a classifier on top of them. | A middle tier that can recognize semantic similarity without running a generative language model locally. |
| LoRA (low-rank adaptation) | An efficient fine-tuning method that adapts a small foundation language model by training a relatively small set of additional weights, called an adapter. | The heaviest option, but potentially useful for subtler decisions. It takes more training resources and produces a larger, slower CPU function. |
The options are a ladder, not a required progression. A TF-IDF candidate may be the best choice when it already reproduces the decisions well enough. See How Smallbatch Works for the technical details.
Install
pip install smallbatch
The v0.2 package is intentionally a full installation containing all three training approaches. The final function wheel contains only the selected candidate's runtime dependencies and never depends on Smallbatch.
Workflow
smallbatch init classifier ticket-priority

# Inspect/edit the generated prompt, contract, teacher, and candidates.
smallbatch doctor ticket-priority/spec.yaml \
  --items ticket-priority/items.json

# Imported decisions skip the teacher. Unlabeled inputs start with calibration.
smallbatch label ticket-priority/spec.yaml \
  --items ticket-priority/items.json

# Build every configured candidate and evaluate each through its CPU runtime.
smallbatch compile ticket-priority/spec.yaml

# Review artifacts/ticket-priority/builds/<build>/report.md, then choose or stop.
smallbatch select ticket-priority tfidf

smallbatch run ticket-priority \
  --json '{"title":"Production down","body":"All requests return 503"}'
compile never chooses a candidate. select builds a standalone package:
an inspectable source project and installable Python wheel that can run without
Smallbatch. It evaluates that package on the complete held-out evaluation split
(the examples not used for training or checkpoint selection) before updating
the active selection.
from smallbatch_functions.ticket_priority import classify, classify_batch, metadata

priority = classify({"title": "Production down", "body": "All requests return 503"})
The generated package does not import Smallbatch. A LoRA package still requires the recorded base model plus Torch, Transformers, and PEFT (the supporting parameter-efficient fine-tuning library) at runtime.
Item Format
Unlabeled JSONL records use one envelope:
{"input":{"title":"Production down","body":"All requests return 503"}}
To reuse existing production decisions, add output to every record:
{"input":{"title":"Production down","body":"All requests return 503"},"output":"urgent"}
Files must be entirely labeled or entirely unlabeled. Input fields are required
and strictly typed as string, integer, number, or boolean.
Candidate failures are isolated. A build succeeds when at least one candidate fully trains and completes CPU evaluation; unavailable or failed candidates remain visible in the report.
Evidence
Every completed candidate is run over the same held-out evaluation decisions on CPU. Reports include:
- Exact and within-one behavior, mean absolute error (MAE), error distribution, p90/max error, signed error, and correlations for bounded integers.
- Decision agreement, class-averaged and frequency-weighted F1 scores, balanced accuracy, per-class behavior, worst-class recall, and confusion for enums.
- Joint and per-field results for structured outputs.
- Cold load, median/tail (p50/p95) single-item latency, peak resident memory (RSS), candidate-owned bytes, required shared/base bytes, runtime dependencies, CPU, OS, and thread count.
- A train-fitted constant diagnostic and one zero-shot diagnostic, using the unadapted base model, per LoRA base.
Smallbatch may report observed strict dominance, but it never declares a winner or PASS/FAIL. Comparing candidates on one evaluation split introduces selection bias; v0.2 reports that limitation and does not claim independent confirmation. CPU time, memory, and footprint are operating proxies, not energy measurements.
Case Study
Assign a 0-4 review priority to public CFPB consumer complaints. A
self-hosted open-weights teacher (gpt-oss-120b) labeled 600 frozen inputs;
Smallbatch trained five local functions on 420 of its decisions and evaluated
all of them, on the same machine, against the same 120 held-out decisions.
One thing to know before reading the table: the teacher itself is not deterministic evidence. Re-labeling the same 120 evaluation rows with the shipped rubric (shuffled order, temperature 0), it repeated its own decision only 82% of the time — that's the ceiling any student can reliably reach, so the table below includes the teacher as a reference row rather than an implied 100%.
| exact agreement | mean error (0-4 scale) | p50 latency | ships as | |
|---|---|---|---|---|
| teacher vs. itself (ceiling) | 82% | 0.22 | GPU only | 65 GB |
| TF-IDF | 54% | 0.60 | 1.2 ms | 27 MB |
| SetFit (bge-small, 33M) | 57% | 0.55 | 42 ms | 135 MB |
| LoRA (Qwen3-0.6B) | 63% | 0.45 | 0.8 s | 1.6 GB |
| LoRA (Qwen3-1.7B) | 64% | 0.43 | 1.9 s | 4.1 GB |
| LoRA (Qwen3-4B) | 69% | 0.38 | 4.3 s | 8.1 GB |
Consistency numbers are in
teacher_consistency.json;
raw candidate metrics with confidence intervals are in
results.json.
The trained functions never see the prompt's rubric — the teacher's decisions moved it into their weights. Prompting the same base models with the full rubric instead, on the same evaluation rows:
| base model | rubric in the prompt, no training | trained on 420 decisions, no rubric | ||
|---|---|---|---|---|
| exact | p50 | exact | p50 | |
| Qwen3-0.6B | 18% | 3.9 s | 63% | 0.8 s |
| Qwen3-1.7B | 3% | 7.2 s | 64% | 1.9 s |
| Qwen3-4B | 48% | 16.5 s | 69% | 4.3 s |
No winner is declared — which row is worth its latency depends on the workload, and agreement measures fidelity to the teacher's decisions, not correctness. What the tables do show: 420 teacher decisions moved more of the rubric into each model's weights than the rubric itself could carry in a prompt, and the resulting functions run in milliseconds to seconds on a CPU. Protocol, evidence, and the honest caveats: case-study/cfpb-complaint-priority.
Responsible use
Smallbatch trains candidate functions on teacher outputs, so your teacher provider's terms govern what you may build. Constrained classifiers and scorers like these fit the "specialized, non-competing tool" category that major providers expressly allow (e.g. content categorization, sentiment) — but general chatbots or open-ended generators trained on provider outputs are prohibited, and some providers restrict distribution of models trained on their outputs. Using a self-hosted open-weights teacher (Ollama/vLLM) sidesteps the question for labeling. Read docs/responsible-use.md before pointing a hosted teacher at a dataset.
A LoRA adapter remains subject to its base model's license. The default
LoRA student (ibm-granite/granite-4.0-350m) is Apache-2.0. The selected
function's prompt, contract, generated source, and trained state ship in its
standalone package — review them like code before sharing.
Commands
| Command | Purpose |
|---|---|
smallbatch init |
Generate a prompt-first starter project. |
smallbatch doctor |
Validate the contract, data mode, teacher, candidates, and environment. |
smallbatch label |
Import complete decisions or generate them after teacher calibration. |
smallbatch compile |
Train, CPU-evaluate, and compare every configured candidate. |
smallbatch select |
Package and activate one candidate, or clear the active selection. |
smallbatch run |
Call the active function or an explicit build/candidate. |
smallbatch status |
Show builds, failures, integrity, drift, and active selection. |
Development
pip install -e '.[dev]'
pytest -q
ruff check src tests case-study
python -m build
See docs/how-it-works.md for identities and artifacts, docs/responsible-use.md for decision limitations, and docs/cloud.md for compiling on a rented GPU.
1 maintainer

Metadata
1 maintainer
Release files for smallbatch 0.2.0
For a detailed explanation of source distributions (sdists) and built distributions (wheels), please see the package formats documentation.
Source distribution (sdist)
| File | Size | Uploaded | |
|---|---|---|---|
| smallbatch-0.2.0.tar.gz | 104.6 kB | Details |
Built distribution (wheel)
| File | Interpreter | ABI | Platform | Reset |
|---|---|---|---|---|
| smallbatch-0.2.0-py3-none-any.whl | Python 3 | none | any | Details |
Total release size: 190.0 kB
Release files / smallbatch-0.2.0.tar.gz
| Download URL | smallbatch-0.2.0.tar.gz |
|---|---|
| Size | 104.6 kB |
| Tags | Source |
|
SHA-256 checksum How to use checksums |
3829c6e0209f19dbce42cd8353adb0a1527ec2785b7e7b9c167f1fc1838edaf2
|
|
BLAKE2b-256 checksum How to use checksums |
7a510a2b8104d1c3ab73981d0342b64d6009ac4fd85ae5e34dc386e3dab40052
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
Yes |
| Uploaded via |
twine/6.1.0 CPython/3.13.12
|
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.


PyPI Publish Attestation
PyPI verified that this artifact, at this checksum, originated from the publisher listed below.
Signed by GitHub Actions, verified by PyPI on Jul 15, 2026.
Transparency logRelease files / smallbatch-0.2.0-py3-none-any.whl
| Download URL | smallbatch-0.2.0-py3-none-any.whl |
|---|---|
| Size | 85.4 kB |
| Tags | Python 3 |
|
SHA-256 checksum How to use checksums |
b0f4d5f2e2b3227bcf5cfb8d28b55d8f4b51c286233474cd74e241d3288926db
|
|
BLAKE2b-256 checksum How to use checksums |
fece55b50d9ff078111faf830b2c50fa197ce7fb87b0657b927115e4905ed4af
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
Yes |
| Uploaded via |
twine/6.1.0 CPython/3.13.12
|
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.
PyPI Publish Attestation
PyPI verified that this artifact, at this checksum, originated from the publisher listed below.
Signed by GitHub Actions, verified by PyPI on Jul 15, 2026.
Transparency log












