
TASEP-Smarticles



Overview
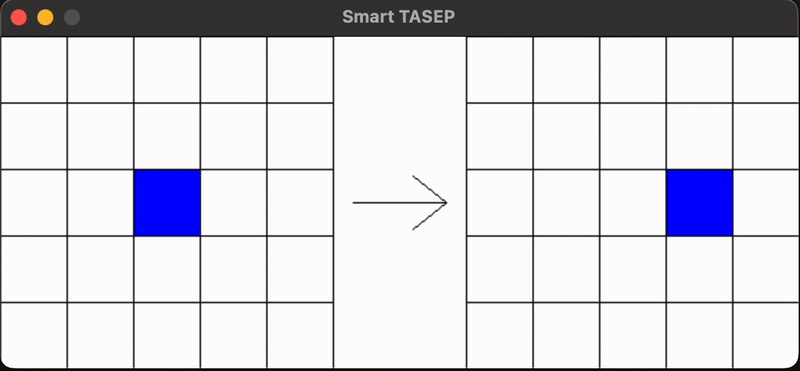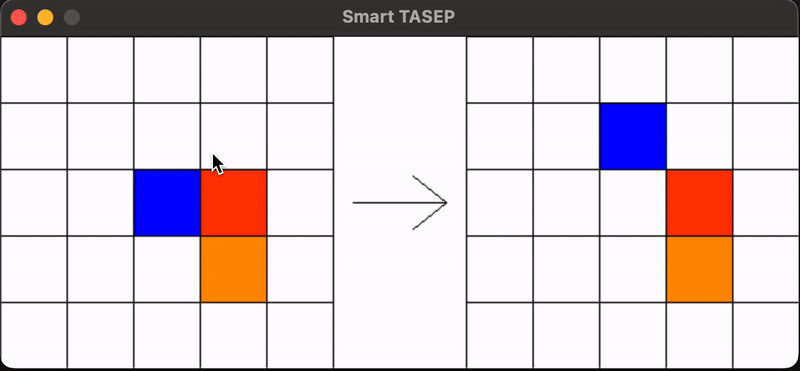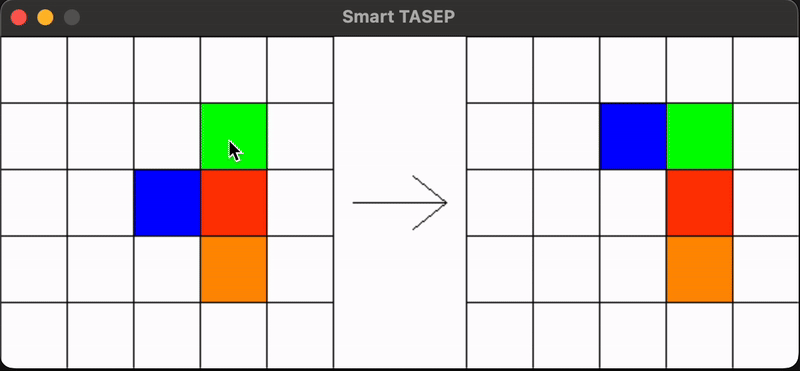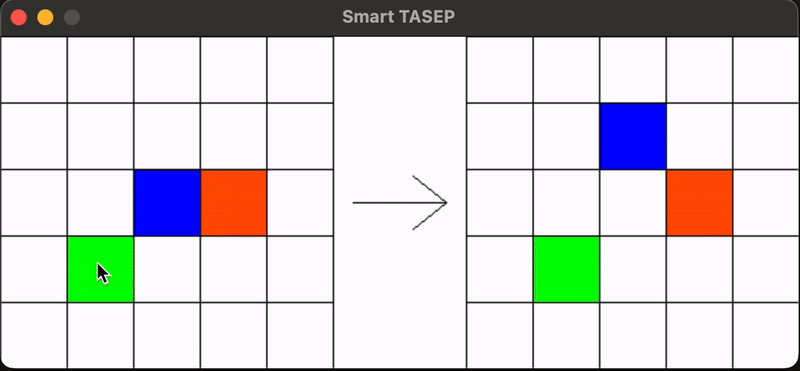
The SmartTasep package implements a Totally Asymmetric Simple Exclusion Process (TASEP) using reinforcement learning (RL) agents. In this simulation, particles perceive their environment at each time step, and a neural network decides their next action (move forward, up, or down) to maximize the total current. The repository employs Double Deep Q Learning (DDQN) with a policy network and a target network that is updated using a soft update mechanism. Experience replay is used to sample from a buffer of past experiences, facilitating learning.
Features
- TASEP simulation with RL agents
- Double Deep Q Learning (dDQN)
- Policy network and target network with soft updates
- (Prioritized) Experience replay for improved learning
- Real-time training visualization with pygame and matplotlib
- Saving trained networks
- Loading and running pretrained simulations
- Testing learned policies interactively
- Customizable reward functions
Files
Classes in TASEP-Smarticles:
DQN.py: Neural network RL agent classGridEnvironment.py: Environment class that computes states, transitions, and rewardsTrainer.py: Wrapper class for training the network, saving, loading and running simulationsPlayground.py: Class for testing learned policies interactively
Setup
-
Install the package using pip:
pip install smarttasep
Using the package
-
Import the package:
from smarttasep import Trainer, EnvParams, Hyperparams, Playground
-
Run a training session:
envParams = EnvParams(render_mode="human",
                       length=128,
                       width=24,
                       moves_per_timestep=200,
                       window_height=200,
                       observation_distance=3,
                       distinguishable_particles=True,
                       initial_state_template="checkerboard",
                       social_reward=True,
                       use_speeds=True,
                       sigma=10,
                       allow_wait=True,
                       invert_speed_observation=True)
 hyperparams = Hyperparams(BATCH_SIZE=32,
                           GAMMA=0.85,
                           EPS_START=0.9,
                           EPS_END=0.05,
                           EPS_DECAY=100_000,
                           TAU=0.005,
                           LR=0.001,
                           MEMORY_SIZE=500_000)

 trainer = Trainer(envParams,
                     hyperparams,
                     reset_interval=100_000, fl
                     total_steps=500_000,
                     plot_interval=4000,
                     new_model=True)

 trainer.train_and_save()
-
Load a pretrained model and run a simulation:
trainer = trainer.load() # shows a list of available models and prompts the user to choose one
trainer.run()
-
Test a learned policy interactively:
Playground() # shows a list of available models and prompts the user to choose one

Author
Jonas Märtens
GitHub: https://github.com/jonasmaertens
Version
Current Version: 0.1.0
License
This project is licensed under the MIT License - see the LICENSE.md file for details
1 maintainer

Metadata
1 maintainer
Release files for smarttasep 0.1.4
For a detailed explanation of source distributions (sdists) and built distributions (wheels), please see the package formats documentation.
Source distribution (sdist)
| File | Size | Uploaded | |
|---|---|---|---|
| smarttasep-0.1.4.tar.gz | 27.0 kB | Details |
Built distribution (wheel)
| File | Interpreter | ABI | Platform | Reset |
|---|---|---|---|---|
| smarttasep-0.1.4-py3-none-any.whl | Python 3 | none | any | Details |
Total release size: 55.6 kB
Release files / smarttasep-0.1.4.tar.gz
| Download URL | smarttasep-0.1.4.tar.gz |
|---|---|
| Size | 27.0 kB |
| Tags | Source |
|
SHA-256 checksum How to use checksums |
700af83bc7018611e70f87a881261eab6ebebab4fbe75038816f506b2ac019a0
|
|
BLAKE2b-256 checksum How to use checksums |
45369451ef248400e11663c25ec8f117539ca02935a10250b6c7fdd6e88bbf5c
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
No |
| Uploaded via |
twine/6.2.0 CPython/3.12.11
|
Release files / smarttasep-0.1.4-py3-none-any.whl
| Download URL | smarttasep-0.1.4-py3-none-any.whl |
|---|---|
| Size | 28.6 kB |
| Tags | Python 3 |
|
SHA-256 checksum How to use checksums |
9ba9a347b0daf9ee82f6bf8a6cdf1855b7dc9d3e1c2bc7633d1d361add839f99
|
|
BLAKE2b-256 checksum How to use checksums |
9ec075431c4ed8def582b0ebffaa1040c8ea7af3d97dca9dde53ec9b54e0e42b
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
No |
| Uploaded via |
twine/6.2.0 CPython/3.12.11
|













