

source-to-skill
Turn YouTube videos, podcasts, papers, books, docs sites, and your own notes into AI agent skills.
One command in Claude Code, Codex, Cursor, Gemini CLI, GitHub Copilot, Amp, or any Agent Skills host. Answers link to the exact second. Local Whisper, no API keys.



Quick start · Examples · Sources · Study & eval · How it works · FAQ · Website

You watched the two-hour lecture, listened to the podcast, skimmed the paper, sat through the planning call. A week later your coding agent knows none of it, and pasting the transcript costs the full token bill on every question.
source-to-skill distills any of these into a structured agent skill: a short SKILL.md your agent loads on demand, plus support files it reads only when a question needs them. Answers cite the source, and for video and audio they link back to the exact second (&t=842s).
/source-to-skill https://www.youtube.com/watch?v=zjkBMFhNj_g
intro-to-large-language-models/
├── SKILL.md                         # core ideas + timestamped segment index (1.5k tokens)
├── segments/
│   ├── 01-intro-and-llm-inference.md  # one file per chapter, loaded only when needed,
│   ├── 02-llm-training.md             #   each opening with its &t= deep link
│   └── ...
├── cheatsheet.md                    # numbers, mental models, decision rules
├── evals/evals.json                 # grounded questions to score the skill against its source
└── source.json                      # lets `/source-to-skill update` refresh it later
Quick start
Claude Code plugin (recommended):
/plugin marketplace add michalstrnadel/source-to-skill
/plugin install source-to-skill@source-to-skill
As a plugin the commands are namespaced: /source-to-skill:source-to-skill, /source-to-skill:skill-study, and so on. Plain requests ("turn this video into a skill") load the right skill on their own.
Codex, Cursor, Gemini CLI, Copilot, Amp, OpenCode, and other agents, with the skills CLI:
npx skills add michalstrnadel/source-to-skill
Or with uv, which also gives you the source-to-skill CLI:
uvx --from git+https://github.com/michalstrnadel/source-to-skill source-to-skill install                 # -> ~/.claude/skills/
uvx --from git+https://github.com/michalstrnadel/source-to-skill source-to-skill install --agent codex   # -> ~/.agents/skills/
--agent takes claude, agents/codex, copilot, gemini, cursor, opencode, kiro, windsurf, or factory; add --project to install into the current repo. Once the package is on PyPI this shortens to uvx source-to-skill install.
Manual: git clone this repo and symlink skills/source-to-skill/ into your agent's skills folder (details).
Then install the extractors for the sources you use, and ask:
pip install yt-dlp PyMuPDF        # YouTube + PDFs; EPUB, articles and repos need nothing
pip install mlx-whisper           # podcasts & captionless videos (Apple Silicon)
pip install faster-whisper        #   ... or this one anywhere else
/source-to-skill https://www.youtube.com/watch?v=...      # 1. extract, see the token estimate, pick where to install
/intro-to-large-language-models what is the LLM OS?       # 2. ask - answers cite and deep-link the source
Supported sources

| Source | Example | What your agent gets |
|---|---|---|
| YouTube video | /source-to-skill https://youtube.com/watch?v=... |
chapter-segmented skill; every answer deep-links the exact &t= second |
| YouTube playlist | /source-to-skill https://youtube.com/playlist?list=... |
course skill: lesson index, one linked lesson per video, course cheatsheet |
| YouTube channel | /source-to-skill https://youtube.com/@3blue1brown |
the channel's latest 20 videos (--limit N) as one skill |
| Podcast episode | /source-to-skill https://podcasts.apple.com/...?i=... |
local Whisper transcript, chapters or 10-min segments, [hh:mm:ss] citations |
| Podcast show (RSS) | /source-to-skill https://feeds.megaphone.fm/... |
the latest 5 episodes (--limit N) as one skill, one transcribed lesson per episode |
| Any video site | /source-to-skill https://vimeo.com/... --type audio |
anything yt-dlp can download (1,000+ sites), transcribed locally |
| Local recording | /source-to-skill ~/Downloads/all-hands.mp4 |
meetings, lectures, voice memos: .mp3 .m4a .wav .mp4 .mov .webm ... |
| Academic paper | /source-to-skill https://arxiv.org/abs/1706.03762 |
TL;DR, key claims with evidence, methods, findings, limitations, glossary, citations |
| Book | /source-to-skill book.epub (PDF: --type book) |
mental models, chapter index with on-demand chapter files, glossary, cheatsheet |
| Web article | /source-to-skill https://example.com/post |
byline, thesis, key claims linked to the original, quotable highlights |
| GitHub repo | /source-to-skill https://github.com/pallets/flask |
library skill from README + docs (Markdown, MDX, reStructuredText): install, usage, guides, cheatsheet |
| Docs site (llms.txt) | /source-to-skill https://svelte.dev/llms.txt (any docs URL: --type docs) |
every linked docs page distilled into guides and a cheatsheet, each citing the live page |
| Your notes | /source-to-skill ~/Obsidian/work |
Obsidian vault or Markdown folder: your own frameworks, hub notes, decisions and open questions; wikilinks resolved, stays local |
| Word / PowerPoint | /source-to-skill strategy.pptx |
sections or slide groups, with speaker notes kept (.docx .pptx .odt .odp) |
| HN / Reddit thread | /source-to-skill https://news.ycombinator.com/item?id=... |
consensus, strongest arguments, attributed tips, and dissent kept apart, each linked to its comment |
| Meeting transcript | /source-to-skill ~/Downloads/planning.vtt |
Zoom / Teams / Meet .vtt or .srt: decisions, action items with owners, who said what, [hh:mm:ss] |
| Several at once | /source-to-skill <paper> <video> <article> |
one topic skill, ideas tagged by source, plus disagreements.md |
Videos without captions are transcribed with Whisper automatically when a backend is installed (--transcribe forces it).
Examples gallery
Every skill in examples/ was generated by this tool from the linked source. Browse them to see the output quality before installing, or copy one into your skills folder and start asking.
| Skill | Source | Type | Source tokens | SKILL.md |
Whole skill |
|---|---|---|---|---|---|
| intro-to-large-language-models | Andrej Karpathy, [1hr Talk] Intro to Large Language Models | video | 16.4k | 1.5k | 7.8k |
| neural-networks-3blue1brown | 3Blue1Brown, Neural networks (10 videos) | course | 52.6k | 1.8k | 11.7k |
| attention-is-all-you-need | Vaswani et al., arXiv 1706.03762 | paper | 8.1k | 1.1k | 7.2k |
| pro-git | Chacon & Straub, Pro Git (CC BY-NC-SA 3.0) | book | 186.5k | 1.7k | 51.2k |
| building-effective-agents | Anthropic, Building effective agents | article | 3.7k | 2.0k | 2.4k |
| flask | pallets/flask README + 77 docs pages |
repo | 78.9k | 1.6k | 16.7k |
| karpathy-agi-decade-away | Dwarkesh Patel with Andrej Karpathy, AGI is still a decade away (2h25m) | podcast | 42.1k | 1.5k | 11.6k |
| uv | Astral, uv docs via llms.txt (56 pages) |
docs | 243.6k | 1.7k | 44.3k |
| how-transformers-work | the paper above + 3Blue1Brown video + Jay Alammar's Illustrated Transformer | topic | 20.3k | 1.2k | 8.5k |
Token counts are estimates (words × 1.33). The agent loads only SKILL.md when the skill is relevant, then opens a segment, chapter, or guide when a question needs it. Asking about Pro Git costs about 1.7k tokens plus one chapter, not 186k; asking about uv costs 1.7k plus one guide, not 244k.
Study, test and manage your skills
The plugin ships three companion skills that work on anything source-to-skill made:
| Skill | What it does | Try |
|---|---|---|
| skill-study | quizzes you one question at a time with spaced repetition (Leitner boxes), checks your explanations Feynman-style, plans study sessions over the lessons, and exports Anki cards that link back to the exact second | quiz me on pro-git |
| skill-eval | answers the skill's grounded questions blind, using only the skill, grades each expectation, and lists the facts the skill is missing or hides | is the flask skill any good? |
| skill-library | lists every skill you made across all agents' folders, finds which one covers a question, flags playlists, channels, feeds and docs that moved on, and refreshes them | which of my skills covers backprop? |
Measured, not claimed
Every generated skill ships evals/evals.json (the skill-creator format): questions drafted from the original source while it is in context, each with checkable expectations. For the gallery, an agent holding only the skill answered questions drafted from each re-extracted source:
| Gallery skill | Expectations passed |
|---|---|
| attention-is-all-you-need | 15 / 15 |
| building-effective-agents | 13 / 14 |
| flask | 15 / 15 |
| how-transformers-work | 14 / 14 |
| intro-to-large-language-models | 13 / 13 |
| karpathy-agi-decade-away (podcast) | 16 / 16 |
| neural-networks-3blue1brown | 13 / 13 |
| pro-git | 14 / 14 |
| uv (docs site) | 14 / 14 |
| total | 127 / 128 |
Questions and per-expectation results live in each example's evals/ folder. The questions were written by the same project that wrote the skills, so treat the score as a regression check, not an independent benchmark. The plugin itself is tested with claude plugin eval: 12 cases check that the right skill loads for real requests and stays out of unrelated ones.
Why a skill?
| Paste the transcript | RAG pipeline | NotebookLM | source-to-skill | |
|---|---|---|---|---|
| Lives inside your coding agent | yes | with work | no | yes |
| Cost per question | full source, every time | retrieved chunks | n/a | ~4k-token index + files it needs |
| Structure (frameworks, decision rules, numbers) | no | no | partial | yes |
| Deep links to the exact second | no | no | no | yes |
| Infrastructure (vector DB, embeddings, API keys) | none | yes | cloud account | none |
| Runs locally, sources stay on your machine | yes | depends | no | yes (your agent's model aside) |
| Measured answer accuracy | n/a | rarely | no | yes (evals/evals.json + skill-eval) |
| Works across Claude Code, Codex, Cursor, Gemini, Copilot | n/a | custom | no | yes (open standard) |
Documentation-site scrapers such as Skill_Seekers turn API docs into skills, and book-to-skill does books. source-to-skill focuses on what you watch, listen to, and discuss: talks, courses, podcasts, meetings and threads, with links to the exact second, alongside papers, books, docs and your own notes.
How it works
flowchart LR
S["YouTube · podcast · audio · meeting .vtt<br/>arXiv / PDF · EPUB · article · repo<br/>llms.txt docs · notes · .docx/.pptx · HN/Reddit"] --> X
subgraph X["Extractor: deterministic Python"]
D[detect source] --> P[yt-dlp · Whisper · PyMuPDF · stdlib parsers]
end
X --> O["full_text.txt<br/>metadata.json<br/>source.json"]
O --> G
subgraph G["Generator: your own agent"]
C[confirm token cost] --> T[distill via the source-type template] --> V[validate]
end
G --> K["~/.claude/skills/<slug>/<br/>SKILL.md + on-demand files"]
The work is split in two halves. A deterministic extractor (Python, standard library plus optional yt-dlp, PyMuPDF, and Whisper) normalizes every source into the same text-plus-metadata contract. Your own agent then distills that contract through the template for the source type, following the skill's SKILL.md. Nothing calls a cloud API: transcription runs on your machine, and generation uses whatever model your agent already runs. Details in docs/ARCHITECTURE.md.
Generated skills hold structure, not summaries: frameworks, decision rules, anti-patterns, and concrete numbers, front-loaded into a SKILL.md capped at about 4k tokens. tools/validate_skill.py checks every run: frontmatter, links that resolve, no empty files.
Power features
Topic skills from several sources. Pass several sources and get one skill. Every idea is tagged with the sources behind it ([S1], [S2]), and disagreements.md records where they contradict each other or use different numbers or definitions. Disagreements are kept side by side, never averaged into one claim. See how-transformers-work.
/source-to-skill https://arxiv.org/abs/1706.03762 https://youtu.be/eMlx5fFNoYc https://jalammar.github.io/illustrated-transformer/ how-transformers-work
Skills that stay fresh. Every skill keeps a source.json. When the playlist or channel publishes new videos:
/source-to-skill update ~/.claude/skills/neural-networks-3blue1brown
The tool re-extracts the source, diffs it against the manifest, and generates only the new lessons.
Podcasts and recordings, fully local. Whisper runs on your machine through mlx-whisper on Apple Silicon (whisper-large-v3-turbo by default) or faster-whisper elsewhere. To trade accuracy for speed or disk space, set SOURCE_TO_SKILL_WHISPER_MODEL=mlx-community/whisper-small-mlx (or a faster-whisper size such as base).
Extractor reference
The skill drives this for you. It also works standalone (source-to-skill extract ... from the CLI, or python3 skills/source-to-skill/scripts/extract.py ...):
extract.py <source> [--type youtube|playlist|audio|paper|book|article|repo|
                           docs|notes|document|thread|transcript]
                    [--limit N] [--transcribe] [--work-dir PATH]
extract.py --check
| Flag | Effect |
|---|---|
--type |
override detection: book for a PDF book, playlist for a watch?v=...&list=... URL, audio for any page with a video or audio track, docs for a docs site URL (its llms-full.txt or llms.txt is looked up) |
--limit N |
only the first N videos of a playlist (channels default to the latest 20) |
--transcribe |
Whisper even when captions exist (useful for poor auto-captions) |
--work-dir |
output directory for full_text.txt, metadata.json, source.json |
--check |
report installed extractors, Whisper backend and model, ffmpeg, and a stale yt-dlp |
Requirements
- Python 3.10 or newer
- Optional, install only what you use:
yt-dlpfor YouTube videos, playlists, and channels, and for podcast downloadsPyMuPDFfor PDF papers and booksmlx-whisper(Apple Silicon) orfaster-whisperfor podcasts, audio files, and captionless videos;mlx-whisperalso needsffmpeg
- EPUB books, web articles, GitHub repos, docs sites, notes folders, Word/PowerPoint files, threads, and
.srt/.vtttranscripts need only the standard library pip install "source-to-skill[all] @ git+https://github.com/michalstrnadel/source-to-skill"installs the CLI with every extractor for your platform
Install for other agents
Each folder in skills/ is self-contained (source-to-skill/ carries the extractor and validator). npx skills add michalstrnadel/source-to-skill or source-to-skill install --agent <name> [--project] puts all four in place; --only installs just source-to-skill. Or symlink or copy the folders yourself:
| Agent | User folder | Project folder | --agent |
|---|---|---|---|
| Claude Code | ~/.claude/skills/ |
.claude/skills/ |
claude |
| Codex, Amp, Goose, and most others | ~/.agents/skills/ |
.agents/skills/ |
agents / codex |
| GitHub Copilot (CLI, VS Code) | ~/.copilot/skills/ |
.github/skills/ |
copilot |
| Gemini CLI | ~/.gemini/skills/ |
.gemini/skills/ |
gemini |
| Cursor | ~/.cursor/skills/ |
.cursor/skills/ |
cursor |
| OpenCode | ~/.config/opencode/skills/ |
.opencode/skills/ |
opencode |
| Kiro | ~/.kiro/skills/ |
.kiro/skills/ |
kiro |
| Windsurf | ~/.codeium/windsurf/skills/ |
.windsurf/skills/ |
windsurf |
| Factory Droid | ~/.factory/skills/ |
.factory/skills/ |
factory |
Cursor, Gemini CLI, Copilot and OpenCode also read ~/.agents/skills/, so one install there covers several agents. A symlink picks up git pull updates; a copy stays on the version you copied.
FAQ
How do I turn a YouTube video into a Claude skill?
Install the plugin, then run /source-to-skill <youtube-url> in Claude Code. The extractor pulls the captions with yt-dlp (or transcribes the audio when there are none), splits them along the video's chapters, and your agent writes a skill whose answers link to the exact timestamp.
Can Claude Code learn from a podcast?
Yes. Pass an Apple Podcasts episode link, a direct .mp3 URL, a downloaded file, or a show's RSS feed (its latest episodes become one skill). With mlx-whisper or faster-whisper installed, the episode is transcribed on your machine and becomes a skill with [hh:mm:ss] citations. Spotify episodes are DRM-protected and not supported.
Is this a NotebookLM alternative for Claude Code?
For learning sources, mostly yes: you get grounded answers about your videos, papers, and books, inside the agent you already code with, as plain files you own. NotebookLM is a hosted notebook. source-to-skill produces portable skills that work in Claude Code, Copilot CLI, Amp, and any Agent Skills host.
How do I make an agent skill from a PDF or a book?
/source-to-skill paper.pdf treats a PDF as an academic paper (methods, findings, limitations). For a book, use /source-to-skill book.epub, or add --type book for a PDF book, which takes chapters from the PDF outline.
How much does it cost?
The tool is free and MIT-licensed. Generation reads the source once through your agent; the skill shows the token estimate and asks before it starts. After that, each question loads a SKILL.md of at most about 4k tokens plus only the files it needs.
Does it need an API key or send my files anywhere?
No. Extraction and transcription run locally. The only model involved is the one your agent already uses.
Does it work with Codex, Cursor, or Gemini CLI?
Yes. Skills are an open standard. Run npx skills add michalstrnadel/source-to-skill, or source-to-skill install --agent codex (also cursor, gemini, copilot, opencode, kiro, windsurf, factory). Generated skills go wherever you choose; ~/.agents/skills/ is read by most agents.
How do I turn documentation into a skill?
If the site publishes llms.txt (most Mintlify, GitBook and Fern docs do), pass that URL, or the docs URL with --type docs. Every linked page is fetched and distilled into guides that cite the live page. For docs that live in a repo, pass the GitHub URL instead.
Can I turn my Obsidian vault or notes into a skill?
Pass the folder: /source-to-skill ~/Obsidian/work. Frontmatter, tags and [[wikilinks]] are resolved, the most-linked notes become the skill's hubs, and the skill surfaces your own frameworks and recorded decisions. It stays on your machine; the generator is told to leave out credentials, other people's personal data and journal-style entries.
How do I know a generated skill is any good?
Every skill ships evals/evals.json, questions drafted from the original source. Run /skill-eval <skill>: an agent holding only the skill answers them, each expectation is graded, and you get a score plus the facts the skill is missing. The gallery scores 127 of 128 (details).
What is an agent skill?
A folder with a SKILL.md (a name, a description, and instructions) plus optional files, defined by the open Agent Skills standard. The agent sees only the description until a task needs the skill, then loads it, so skills cost almost nothing while unused.
Troubleshooting
- "No captions available": install a Whisper backend (
pip install mlx-whisperorfaster-whisper) and re-run; the video is then transcribed locally. - YouTube errors or "Sign in to confirm you're not a bot": update yt-dlp (
pip install -U yt-dlp).--checkwarns when your copy is over 60 days old. - "needs ffmpeg":
brew install ffmpegorsudo apt install ffmpeg. mlx-whisper decodes audio through ffmpeg; faster-whisper does not need it. - Transcription is slow or the model download is too big: set
SOURCE_TO_SKILL_WHISPER_MODELto a smaller model, for examplemlx-community/whisper-small-mlx. - "skipping [NN] ..." on a playlist: those videos had no usable transcript. They are listed under
skippedinmetadata.json, and the run fails only when every video is skipped. - A channel extracted only 20 videos: that is the default; pass
--limit 50. - "Couldn't extract a readable article": the page renders with JavaScript or needs a login. Save it as a PDF and pass the file.
- "GitHub returned 404": the repository does not exist or is private; private repos are not supported.
- A
watch?v=...&list=...link extracted a single video: that is the default; pass--type playlistfor the whole playlist. - A PDF book parsed as a paper: pass
--type book. - "no usable text layer (scanned PDF?)": run the PDF through OCR first.
- "Missing dependency": run
--checkand install what it lists. --checksays a Whisper backend is "BROKEN": it is installed but its native libraries fail to load (often a wheel built for another OS release); reinstall it or use another Python version.- "no llms.txt found": the docs site publishes neither
llms-full.txtnorllms.txt. Pass a single page as an article, or the docs' GitHub repo. - Reddit answers HTTP 403: some networks block anonymous access to Reddit's JSON. Try another network, or print the thread to PDF and pass it with
--type book. - ".doc / .ppt is not supported": open the file and save it as
.docx/.pptxfirst.
Roadmap
- OCR for scanned PDFs
- Speaker labels (diarization) for multi-speaker podcasts
- An MCP server exposing extraction to agents without shell access
- Independent eval questions for the gallery, written by people who have not seen the skills
Ideas and new source types are welcome: open an issue.
Repository layout
skills/source-to-skill/     the installable skill, self-contained
├── SKILL.md                  agent instructions: extract → confirm → generate → verify
├── scripts/extract.py        deterministic extractor (YouTube, audio, arXiv, PDF, EPUB, web, GitHub,
│                               llms.txt docs, notes, Office files, HN/Reddit, .srt/.vtt)
└── tools/                    validate_skill.py, diff_source.py
skills/skill-study/         quizzes, spaced repetition, Anki export
skills/skill-eval/          blind, grounded scoring of a generated skill
skills/skill-library/       inventory, search and refresh of every skill you made
evals/                      claude plugin eval suite: does the right skill load
examples/                   gallery of skills generated by the tool
src/source_to_skill/        CLI package (install / extract / check / validate)
.claude-plugin/             plugin + marketplace manifests
docs/                       architecture, landing page, assets
tests/                      offline test suite, no network
Contributing
Bug reports, new source types, and gallery examples are all welcome. See CONTRIBUTING.md. The test suite runs offline in under a second: pip install -e ".[dev]" && pytest.
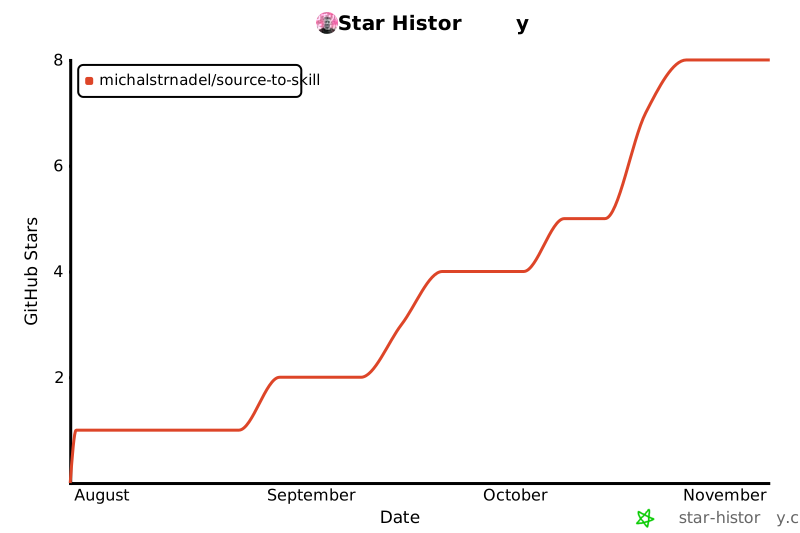
If source-to-skill saved you a rewatch, a star helps other people find it.
License
MIT. Cite it with CITATION.cff. Gallery skills are derived from their sources; each one names its source and keeps quotations short.
1 maintainer

Metadata
1 maintainer
Release files for source-to-skill 0.7.0
For a detailed explanation of source distributions (sdists) and built distributions (wheels), please see the package formats documentation.
Source distribution (sdist)
| File | Size | Uploaded | Provenance | Actions |
|---|---|---|---|---|
| source_to_skill-0.7.0.tar.gz | 175.7 kB | With provenance | Details for source_to_skill-0.7.0.tar.gz |
Built distribution (wheel)
| File | Interpreter | ABI | Platform | Actions Reset |
|---|---|---|---|---|
| source_to_skill-0.7.0-py3-none-any.whl | Python 3 | none | any | Details for source_to_skill-0.7.0-py3-none-any.whl |
Total release size: 290.0 kB
Release files / source_to_skill-0.7.0.tar.gz
| Download URL | source_to_skill-0.7.0.tar.gz |
|---|---|
| Size | 175.7 kB |
| Tags | Source |
|
SHA-256 checksum How to use checksums |
cd36cd70e354756f84b540728513dbfcfaa4cae90f82a5982b297ee869ad045e
|
|
BLAKE2b-256 checksum How to use checksums |
65fbd75a2b9e09ebd194855a53ae53a2de52b80e82a01bfc9aaad40a40128476
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
Yes |
| Uploaded via |
twine/7.0.0 CPython/3.13.16
|
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.


PyPI Publish Attestation
PyPI verified that this artifact, at this checksum, originated from the publisher listed below.
Signed by GitHub Actions, verified by PyPI on Oct 26, 2026.
Transparency logRelease files / source_to_skill-0.7.0-py3-none-any.whl
| Download URL | source_to_skill-0.7.0-py3-none-any.whl |
|---|---|
| Size | 114.3 kB |
| Tags | Python 3 |
|
SHA-256 checksum How to use checksums |
9d0f8b41da9e2d4163d5fa79d8a1f67f0bf5fd921da0833635a1617f7db7cb12
|
|
BLAKE2b-256 checksum How to use checksums |
60fa9d401fae2602ec9a9cd8be0e7af9fe2f02c179002f2c6800f520a5d35354
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
Yes |
| Uploaded via |
twine/7.0.0 CPython/3.13.16
|
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.
PyPI Publish Attestation
PyPI verified that this artifact, at this checksum, originated from the publisher listed below.
Signed by GitHub Actions, verified by PyPI on Oct 26, 2026.
Transparency logSecurity for source-to-skill 0.7.0
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.
Full provenance
Both files in this release have been uploaded with provenance metadata.
Attestation for source_to_skill-0.7.0.tar.gz
PyPI Publish Attestation
PyPI verified that this artifact, at this checksum, originated from the publisher listed below.
Signed by GitHub Actions, verified by PyPI on Oct 26, 2026.
Transparency logA note on package security
PyPI is a repository for distributing packages, not a service for auditing them. While third-party security researchers and our staff do their best to detect and remove malicious packages, PyPI cannot guarantee the quality, security or suitability of any given package.
To learn more about protecting yourself from malicious actors, visit our package security documentation.













