
sparx trains spiking neural networks and simulates circuits of biological neurons, in JAX. Its spiking layers are Flax modules, so they train with optax or dew and work with jit, grad, vmap and sharding. The same neuron models also run in millivolts and milliseconds, wired into circuits and whole connectomes, and there they match NEST and Brian2.
sparxml.dev: a course from one neuron to a spiking network that drives from events, the docs and the API reference.
Guide · Train, serve and export · From NEST and Brian2 · Fit a circuit · Units · Status · Fidelity ledger · Design · Performance
Install
sparx is published as sparxml and imported as sparx, as dew is published as dewml and imported as dew:
| Where | Install |
|---|---|
| CPU | pip install sparxml |
| NVIDIA GPU (CUDA 12 or 13) | pip install "sparxml[cuda12]" or "sparxml[cuda13]" |
| TPU | pip install "sparxml[tpu]" |
| SHD and MNIST readers, connectome tables, NIR | add the extras datasets, connectome and nir |
From a clone, on the dew commit and the jax build the tests run on:
git clone https://github.com/AshishKumar4/sparx.git && cd sparx
uv venv --python 3.12 && source .venv/bin/activate
uv pip install -e ".[datasets,test]" -c constraints.txt && pytest -q
sparx needs Python 3.12 or later, and CI tests it on 3.12, 3.13 and 3.14 on Linux and on 3.12 on macOS, with JAX 0.11.2 and Flax 0.12 on CPU. The API may change before 1.0.
A first network
import flax.linen as nn
import jax
import jax.numpy as jnp
import optax

import sparx


class Net(nn.Module):
    @nn.compact
    def __call__(self, spikes):                     # [T, B, 784]
        x = sparx.nn.LIF(tau=2.0)(nn.Dense(256)(spikes))
        return sparx.nn.LI(tau=2.0)(nn.Dense(10)(x))  # membrane [T, B, 10]


net = Net()
images = jax.random.uniform(jax.random.key(0), (32, 784))  # intensities in [0, 1]
labels = jnp.zeros(32, jnp.int32)
spikes = sparx.encode.RateEncoder(steps=8)(jax.random.key(1), images)  # [8, 32, 784]
params = net.init(jax.random.key(2), spikes)


def loss(params):
    logits = jnp.mean(net.apply(params, spikes), axis=0)  # mean membrane over time
    return optax.softmax_cross_entropy_with_integer_labels(logits, labels).mean()


grads = jax.grad(loss)(params)
LIF turns input currents into spikes, exactly 0 or 1, and LI integrates them into a membrane, which is the readout. Everything else is Flax and optax. examples/train_mnist.py trains a network like this on MNIST under dew's Trainer.
A 784-200-10 network of LIF neurons learning MNIST by surrogate gradients. It follows one test digit through 400 training steps, showing the hidden layer's spikes, the ten output neurons' spike counts and the test accuracy, which reaches 92.8%.
How sparx fits together
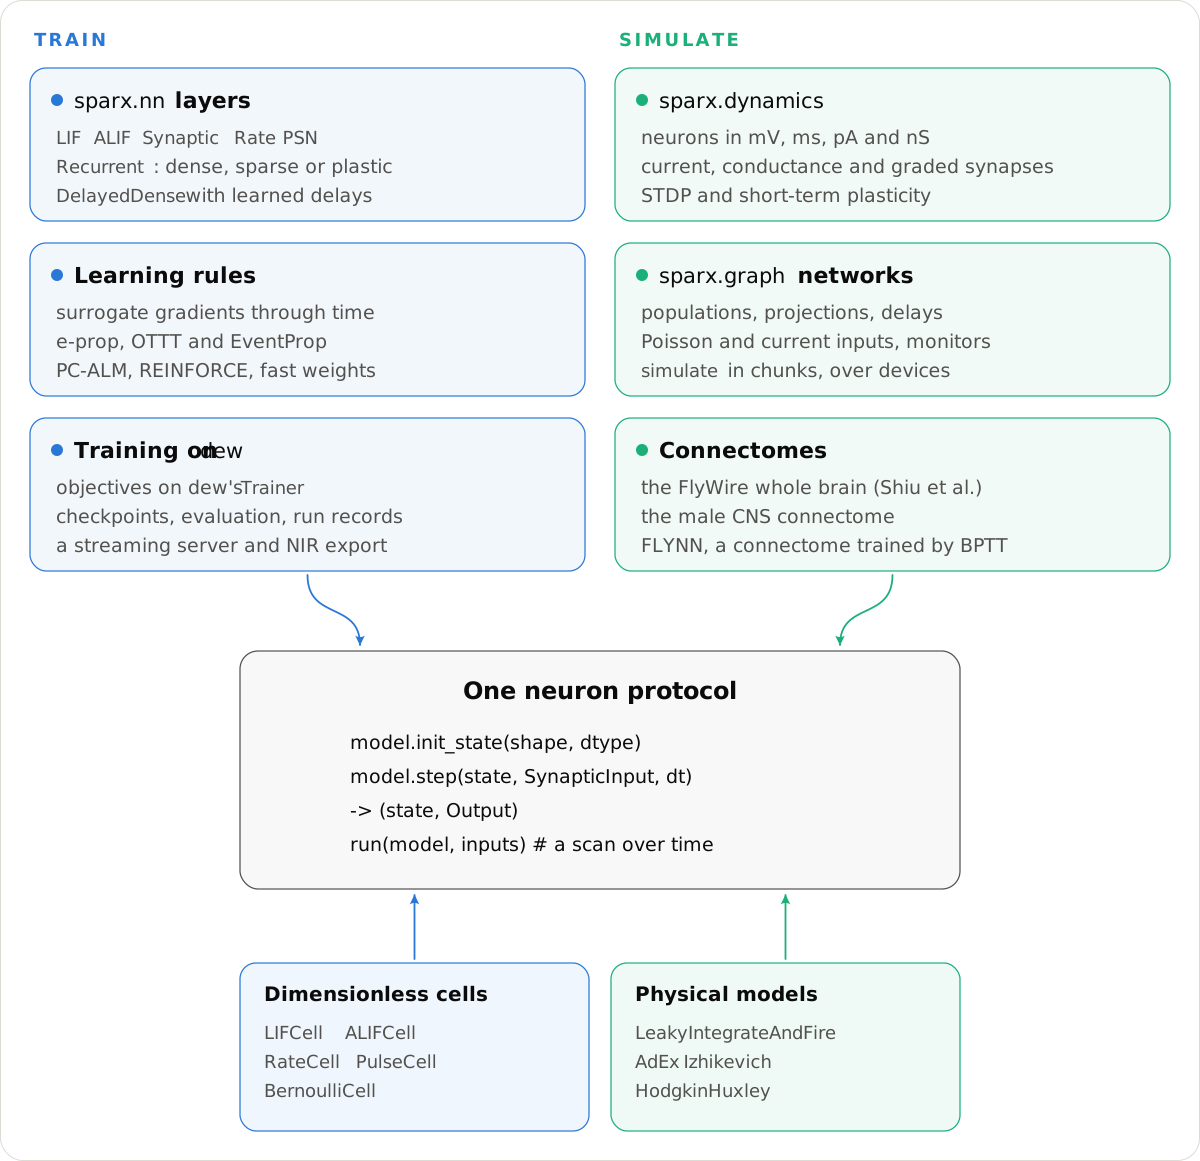
Every neuron model implements one protocol, init_state and step, and run scans a model over time. Dimensionless cells serve deep learning, and physical models in mV and ms serve neuroscience. The two halves mix: a layer can hold a physical model (nn.Dynamics(AdEx())), and a simulated population can hold a dimensionless cell.
A spiking layer over time
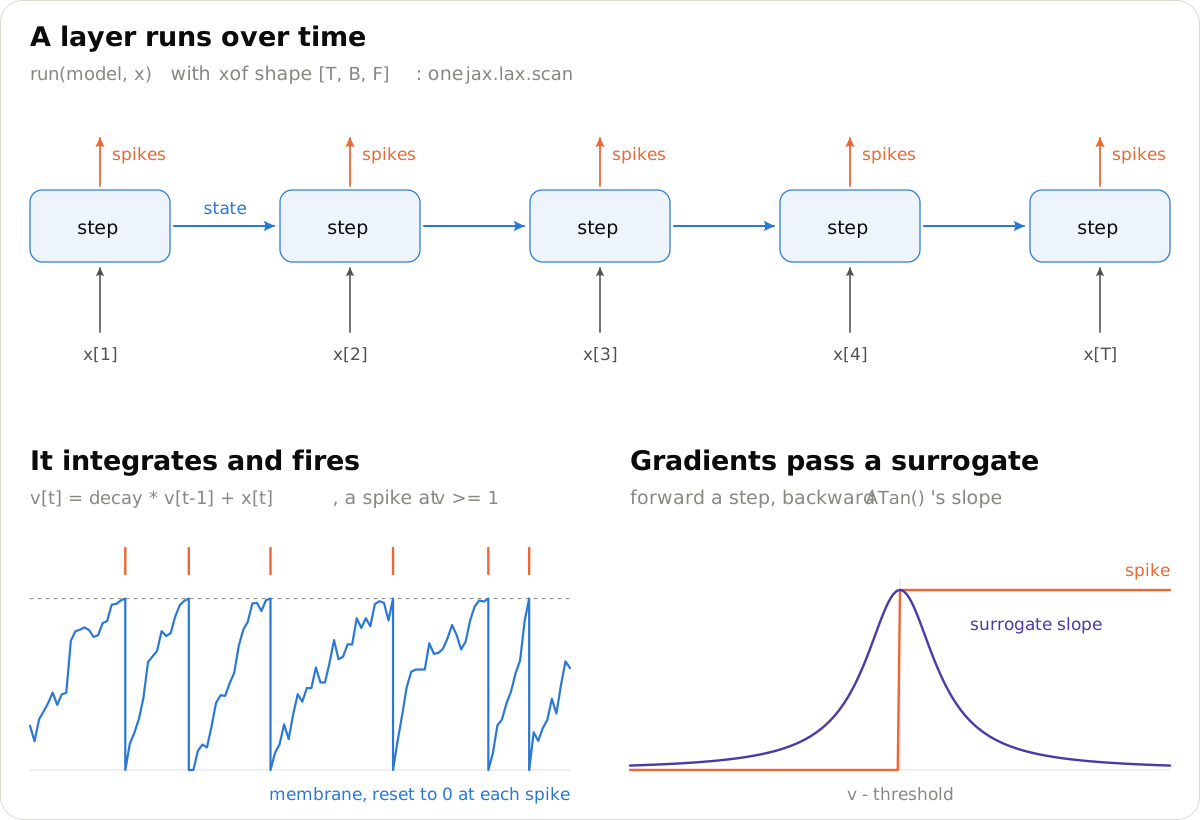
Arrays are time-major, [T, B, ...]. Synaptic layers run over all steps in one matrix product, and only the neurons step through time. A spike is a step function with zero derivative almost everywhere, so the backward pass uses a surrogate's slope instead. The layers are LIF, IF, LI, current-based synaptic LIF, adaptive LIF (ALIF), rate units, parallel spiking neurons and dense layers with learned delays (guide).
Recurrence and fast weights
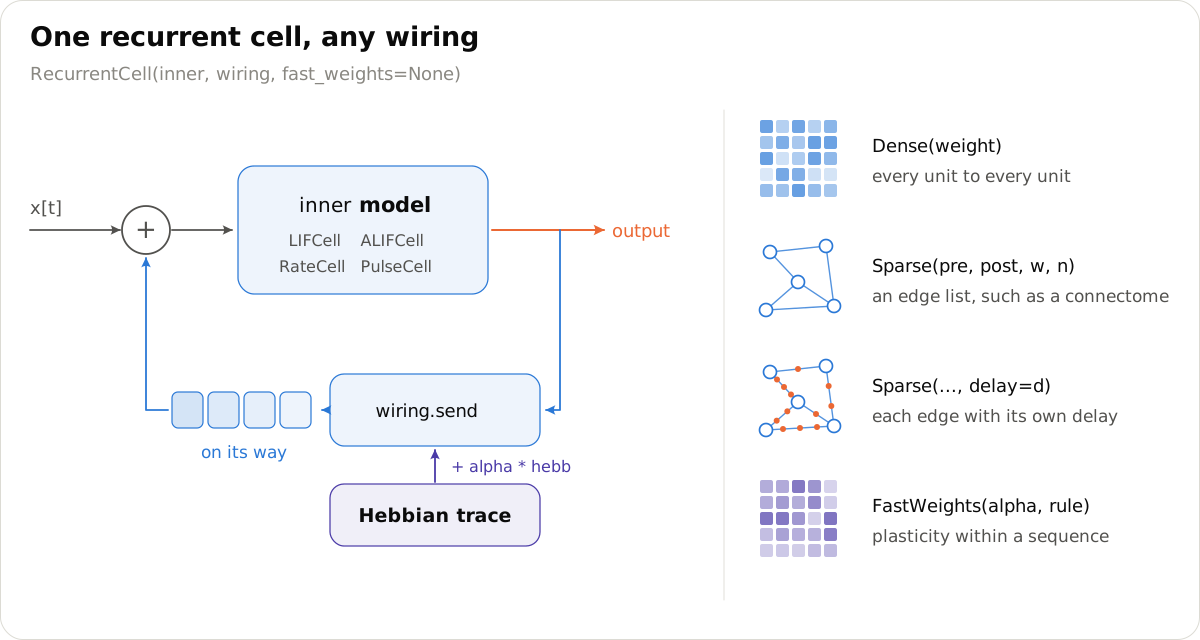
RecurrentCell feeds any model's output back through a wiring: dense, an edge list such as a connectome's, or edges with their own delays. Fast weights add a Hebbian trace that each sequence writes as it runs (Miconi et al. 2018, 2019). Against Miconi et al.'s four networks in PyTorch, activity, traces and gradients agree within 5e-14. On their pattern completion task, the plastic network gets 0.3% of the zeroed bits wrong, and the same network without fast weights 50.1%.
Learning rules
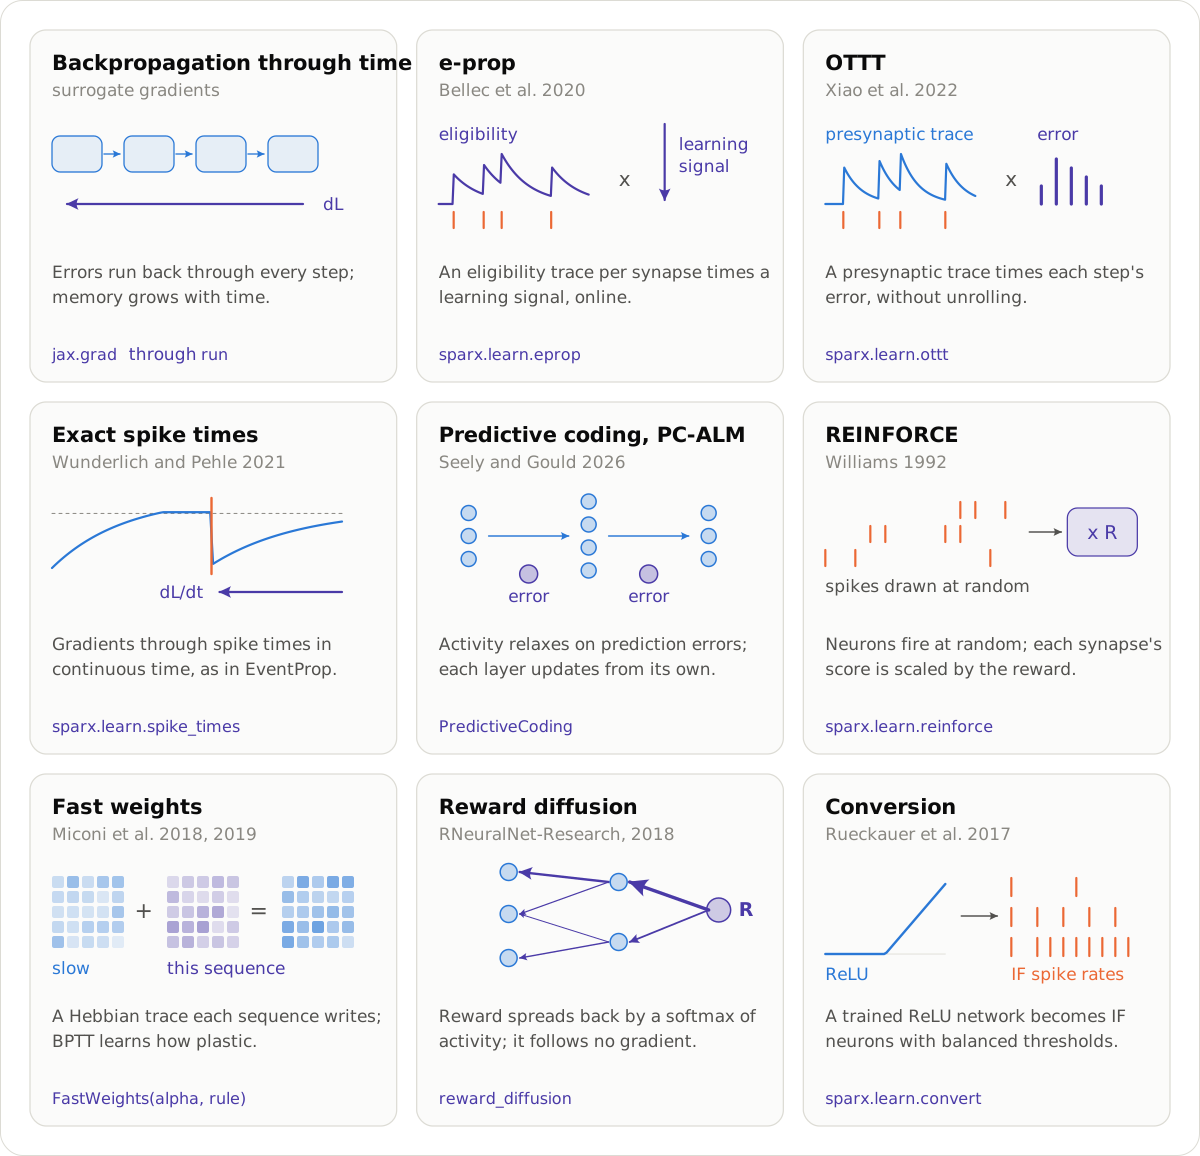
Each rule is checked against what defines it. e-prop meets the two identities its authors verify their code with, OTTT matches their PyTorch modules, PC-ALM matches their JAX reference to 5e-14, and conversion matches their toolbox. REINFORCE is checked on enumerated trajectories, and exact spike times against finite differences. The guide describes each rule.
Simulating circuits
import jax
from sparx.graph import PopulationRate, SpikeRaster, simulate
from sparx.graph.models import brunel

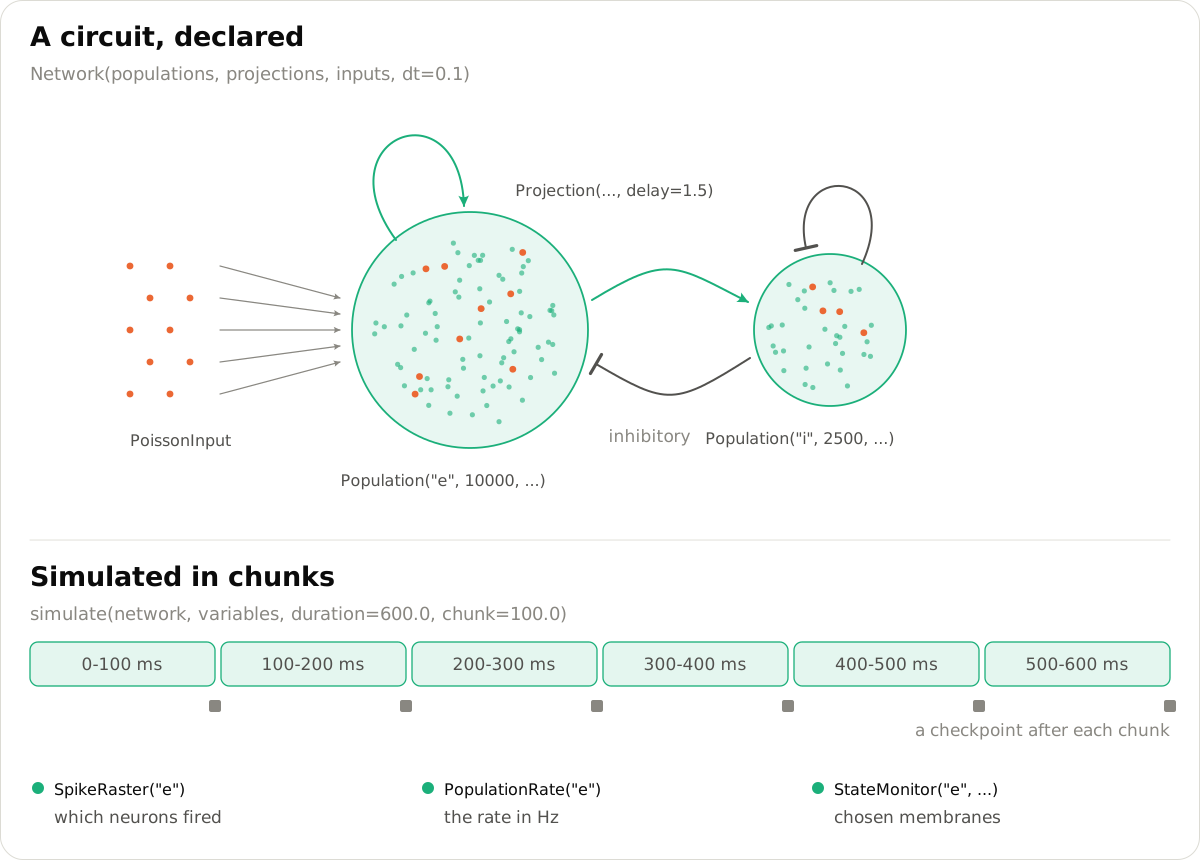
network = brunel(250, g=5.0, eta=2.0)        # 1,250 LIF neurons; brunel(2500) is the paper's 12,500
result = simulate(network, network.init(jax.random.key(0)), duration=200.0, key=jax.random.key(1),
                  monitors={"spikes": SpikeRaster("e"), "rate": PopulationRate("e")})
spikes = result.records["spikes"]             # [2000, 1000]: one row of booleans per 0.1 ms step
Brunel's balanced network at the paper's size, 10,000 excitatory and 2,500 inhibitory LIF neurons, in its asynchronous irregular regime at 37 Hz.
The physical models match NEST 3.10 and Brian2 2.10 spike for spike where the dynamics are deterministic, for the integration scheme, dtype and step each check states (status), and in rate, irregularity and synchrony where they are chaotic. Potjans and Diesmann's cortical microcircuit, built as its reference implementation builds it, fires spike for spike with NEST on the same network (from NEST and Brian2). On a 4-core CPU, sparx simulates a second of Brunel's network in 9.6 s, NEST in 7.5 s and Brian2 in 11.8 s (performance). Populations can hold graded neurons and connect through stochastic release, gap junctions and neuromodulators. Projections can carry STDP, triplet STDP, dopamine-modulated STDP and short-term plasticity (guide).
Connectomes
sparx.graph.connectome builds Shiu et al.'s (2024) model of the whole fly brain from FlyWire. It reproduces their published runs, with a rate correlation of 0.999 and the motor neuron MN9 at 67.1 Hz against their 67.0 ± 6.6, at about 30 s per simulated second on 4 CPU cores. FLYNN (Wang and Chen 2026) trains a connectome as a recurrent rate network with one learned weight per synapse; against their PyTorch cell its activity and gradients agree within 1e-15.
RNeuralNet
sparx.learn.RNeuralNet rebuilds RNeuralNet-Research (2018), an early project of the author's, deterministically. Graded neurons sit on a random graph, each connection delivers its messages after its own delay, and a reward spreads backward by a softmax of activity. Compiled and run in a fixed order, the original C++ and sparx agree within 7.2e-7. On a delayed cue-order task, REINFORCE through the same network learns the task on four of five seeds, and the reward-diffusion rule never changes the network's choice. AGREL's update, a signed error sent back from the chosen output through the weights, learns it on the same four seeds; the same error spread by the original's shares does not.
Training on dew
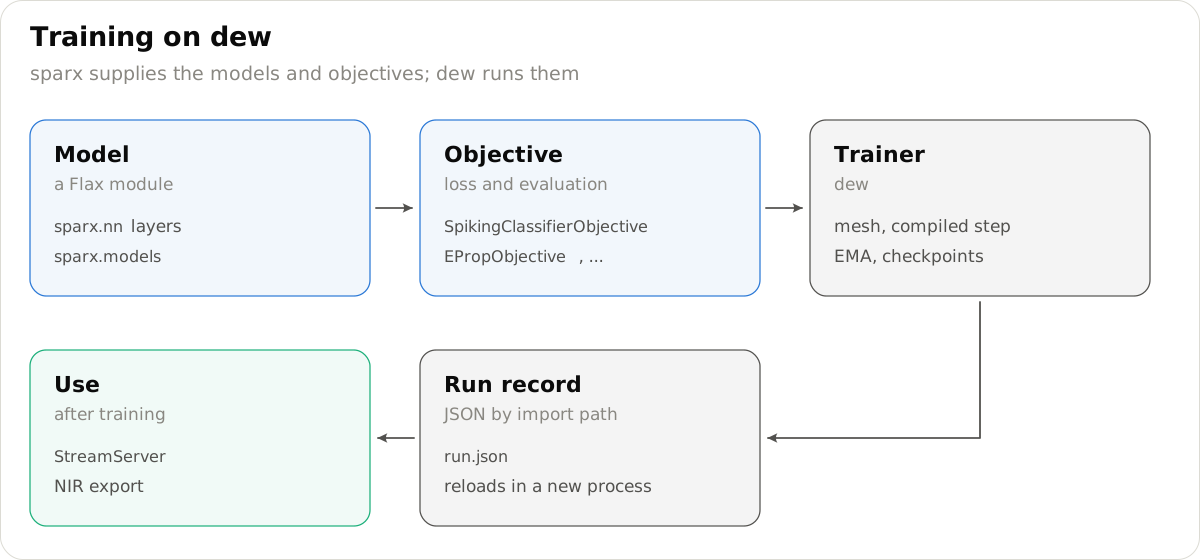
The Trainer from dew runs sparx's objectives for classification, activity fitting, e-prop, predictive coding and RNeuralNet's rewards. A run's record names every class by import path, so dew.pipeline("runs/shd", trust=("sparx",)) loads a trained network in a new process, and sparx.serve.StreamServer serves it to many streams at once. The guide has a full SHD script.
Results
| Task | Network | Test accuracy |
|---|---|---|
| MNIST, rate-coded, 8 steps | 784-512-512 LIF | 97.5% after 2 epochs |
| SHD, Hammouamri et al.'s recipe, 150 epochs, three seeds | 140-256-256 LIF with learned delays | 93.99 ± 0.29% at the last epoch (their code on the same GPU: 93.89 ± 0.26%) |
| SHD, 140 channels | 140-128 ALIF, with and without learned delays | 74.6% and 64.5% |
| Fashion-MNIST, Seely and Gould's headline cell | ReLU residual MLP, depth 32 | PC-ALM 75.1%, PC 62.2%, backpropagation 77.8% |
| Pattern completion, Miconi et al.'s task | plastic recurrent network | 0.3% of bits wrong; 50.1% without fast weights |
The SHD row is the full recipe beside the authors' code, both on an A100, three seeds each (research/shd). Both train on every training recording and score the test set after each epoch. The paper's 95.07 ± 0.24% (a 95% confidence interval over ten runs) is the best epoch on the test set, which chooses with the test set; here, as mean ± standard deviation over three seeds, their code's best epoch is 95.17 ± 0.61% and sparx's 94.96 ± 0.89%. With a tenth of the training set held out to choose the epoch, sparx scores 94.14 ± 0.98% on test. The other rows are short, untuned runs on a 4-core CPU; the guide gives their commands, times and comparisons.
Correctness
Every model is checked against a reference: a float64 loop of its equations, the original authors' code, or NEST and Brian2. docs/fidelity.md lists each model's reference, the check, the observed error and every known difference. pytest -q runs all of it on CPU in about 16 minutes.
tools/make_figures.py draws the banner and diagrams, and tools/make_clips.py renders the clips. The spikes in the banner and the clips come from sparx runs.
License
MIT
1 maintainer

Metadata
1 maintainer
Release files for sparxml 0.1.0
For a detailed explanation of source distributions (sdists) and built distributions (wheels), please see the package formats documentation.
Source distribution (sdist)
| File | Size | Uploaded | |
|---|---|---|---|
| sparxml-0.1.0.tar.gz | 280.3 kB | Details |
Built distribution (wheel)
| File | Interpreter | ABI | Platform | Reset |
|---|---|---|---|---|
| sparxml-0.1.0-py3-none-any.whl | Python 3 | none | any | Details |
Total release size: 469.3 kB
Release files / sparxml-0.1.0.tar.gz
| Download URL | sparxml-0.1.0.tar.gz |
|---|---|
| Size | 280.3 kB |
| Tags | Source |
|
SHA-256 checksum How to use checksums |
007a5f24f4a8ce0eab3fb6fcb6a625fe272112e6b020bbbacf5b7934c083b43e
|
|
BLAKE2b-256 checksum How to use checksums |
16ab84286d45c01ae547bafe7fb298399e7ac404e1403a5fa1e6cef8673293c0
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
Yes |
| Uploaded via |
twine/7.0.0 CPython/3.13.14
|
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.


PyPI Publish Attestation
PyPI verified that this artifact, at this checksum, originated from the publisher listed below.
Signed by GitHub Actions, verified by PyPI on Oct 10, 2026.
Transparency logRelease files / sparxml-0.1.0-py3-none-any.whl
| Download URL | sparxml-0.1.0-py3-none-any.whl |
|---|---|
| Size | 189.0 kB |
| Tags | Python 3 |
|
SHA-256 checksum How to use checksums |
46cb04cffcaf38a9273f7a0d700023280fff7974fbd1e913f6c0ca3b1fe33de9
|
|
BLAKE2b-256 checksum How to use checksums |
9f1a6efeaf0ca5d1e4f2ebc4776762b0ee3e283541d0785e5713a1f5b9b1604b
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
Yes |
| Uploaded via |
twine/7.0.0 CPython/3.13.14
|
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.
PyPI Publish Attestation
PyPI verified that this artifact, at this checksum, originated from the publisher listed below.
Signed by GitHub Actions, verified by PyPI on Oct 10, 2026.
Transparency log












