
Delete your subprocess wrappers around claude, codex, and gemini. spawnllm subshells all three CLIs — or drives Claude in-process through the bundled Agent SDK — plus local MLX and Apple's on-device Foundation Models, and returns one Pydantic-validated Response, so the per-model plumbing you hand-rolled goes away.


Get started
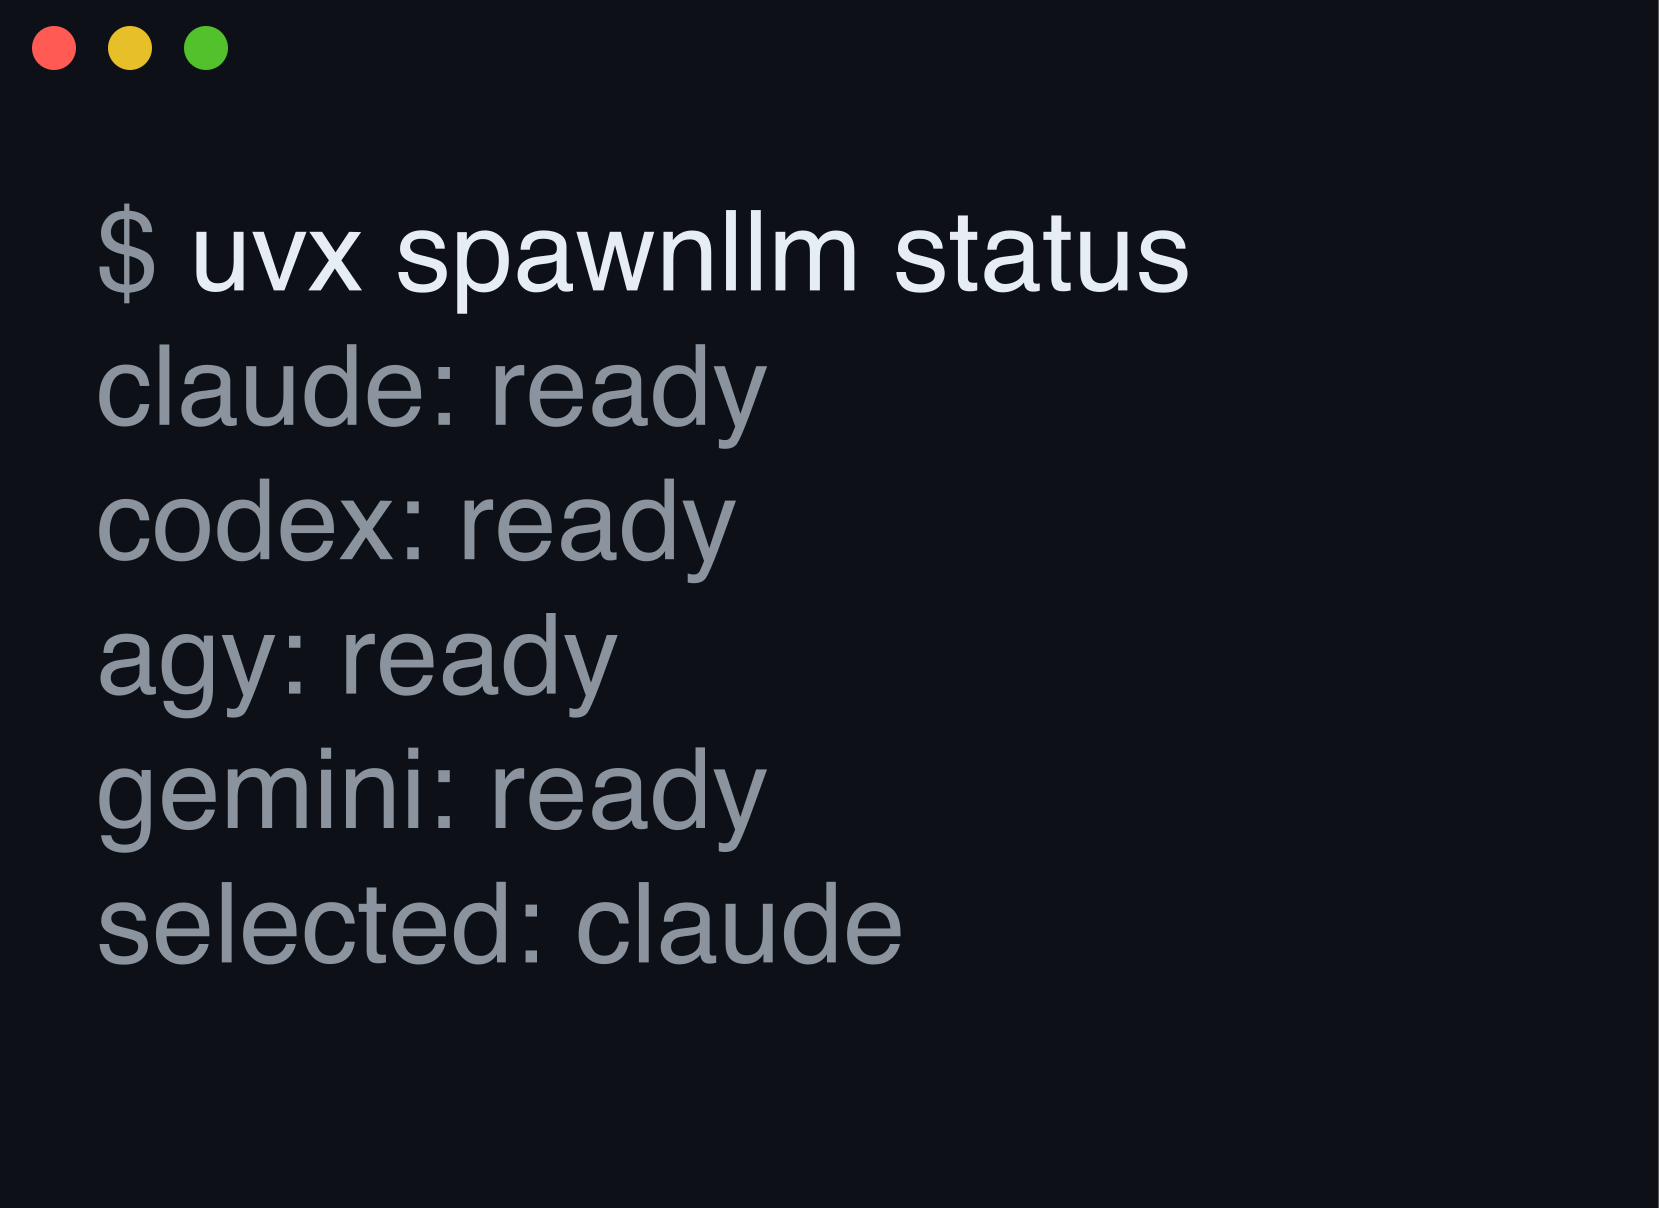
uvx spawnllm status
Driving with an agent? Paste this:
Run `uv add spawnllm` in this project.
Replace our hand-rolled claude/codex subprocess code with spawnllm's `call_sync`,
or `extract_sync` with a Pydantic response model for structured output.
Verify available backends with `uvx spawnllm status`.
Docs: https://yasyf.github.io/spawnllm/
Use cases
Delete your hand-rolled claude/codex subprocess plumbing
Every small tool grows its own subprocess.run(["claude", "-p", ...]) — argv quirks, stdin piping, exit-code guesswork — and each copy drifts. One call replaces all of it:
from spawnllm import call_sync

print(call_sync("Reply with just the word: pong"))
Prints pong. With no backend=, spawnllm auto-selects the first installed, authenticated backend — a CLI backend gets the prompt over stdin — and retries transient 529/overloaded/rate-limit failures with capped backoff.
Get a validated Pydantic object back, not a string to parse
Scraping JSON out of a model's stdout means regexes, code fences, and silent schema drift. extract_sync validates instead:
from pydantic import BaseModel

from spawnllm import extract_sync


class Capital(BaseModel):
    country: str
    capital: str


result = extract_sync("What is the capital of France?", Capital)
print(result.capital)  # Paris
The backend turns Capital into a JSON-schema constraint on the call itself, and a non-conforming reply raises pydantic.ValidationError instead of sneaking downstream.
Keep billing on your subscription, not a stray API key
An ANTHROPIC_API_KEY left in your shell silently flips the claude CLI from your logged-in plan to per-token API billing. spawnllm strips each provider's key vars from the child environment by default, so every run bills the login:
from spawnllm import call_sync

print(call_sync("Reply with just the word: pong"))
Prints pong, billed to your Claude plan even with ANTHROPIC_API_KEY exported. Pass api_auth=True to opt back into key auth. The same guard covers codex (OPENAI_API_KEY/CODEX_API_KEY) and the Gemini family, in Python, Go, and Rust alike; an explicit RunSpec.env entry always wins.
Call Claude with zero installs
The sdk extra adds a backend over the Claude Agent SDK, whose wheel bundles the Claude Code CLI — no separate claude install:
uv add "spawnllm[sdk]"
claude-sdk registers first in the auto-selection chain and signs in with your existing subscription credentials (keychain login or CLAUDE_CODE_OAUTH_TOKEN), so the call_sync above works on a machine that has never installed the CLI.
Run Apple-Silicon MLX models with fused adapters and prompt-cache reuse
Shipping a LoRA-tuned local model means hand-rolling adapter fusion, model caching, and worker-thread lifecycle. The MLX extra owns all three:
uv add "spawnllm[mlx]"
AdapterFuser.ensure_fused fuses your compressed adapter into the base model once and caches the result in the Hugging Face hub layout; MlxEngine loads it on a dedicated worker thread, precomputes a prompt cache for your shared prefix messages, and batches generation. Wrap the engine in an MlxBackend and the same run_sync call works.
Call Apple's on-device model with zero downloads
Even local MLX starts with a multi-gigabyte model fetch. On a Mac with Apple Intelligence, AppleBackend skips that too: a prebuilt Swift sidecar inside the macOS wheel drives Apple's Foundation Models framework against the model already resident on the device. No extra, no compiler, no credentials, no network — installing spawnllm is the whole setup, uvx spawnllm included:
from spawnllm import AppleBackend, call_sync

print(call_sync("Reply with just the word: pong", backend=AppleBackend()))
Auto-selection tries this backend last and only for model="small"; an explicit backend=AppleBackend() always reaches it. Session and decoding knobs (use_case, guardrails, instructions, temperature, sampling) ride in via RunSpec(provider_configs={"apple": AppleConfig(...)}). Structured extract_sync works too, nested models included, and schema constraints now bind during decoding: minimum/maximum, minItems/maxItems, and string-valued enums are enforced exactly (a non-string enum such as Literal[1, 2] fails before generation, extract_sync raising BackendCallError), and a Field(pattern=...) constrains the value's shape — length, separators, and character families. Apple's decoder rejects bracket character classes, so the sidecar widens each to the narrowest escape it accepts (^[A-Z]{3}-\d{4}$ decodes as \w{3}-\d{4}), and pydantic stays the exact validator: a value that fits the widened shape but violates your regex raises a plain ValidationError. Self-referential models extract cleanly; a mutually recursive pair (A referencing B referencing A) fails cleanly instead, extract_sync raising BackendCallError and run returning an error Response. Requires macOS 26+ on Apple Silicon with Apple Intelligence enabled — every other platform gets the pure-Python wheel and reports the backend as not installed.
Ask a yes/no, label, or score question in about 120 ms
A classifier that runs on every hook event or every PR comment can't wait seconds for a chat model to write JSON. decide_sync asks TypeSafe's Jev or OpenAI Decisions instead. Both return probabilities, not prose, and one question set runs unchanged on either:
from spawnllm import Binary, Label, decide_sync

decision = decide_sync(
    "Our nightly release has failed for 3 days. Please roll it back now.",
    {
        "rollback": Binary("Does the message ask to roll back a release?"),
        "action": Label("Which release action does it ask for?", {"none": None, "release": None, "rollback": None}),
    },
)
print(decision.answers["rollback"].p_yes)  # 0.99
print(decision.answers["action"].choice)  # rollback
On a warm keep-alive connection from a Mac, a three-question Jev call took 120 to 130 ms end to end. Pass provider=OPENAI to ask gpt-6-luna instead. Retries cover 408, 429, 5xx, and 529 and stop at timeout. Keys come from TYPESAFE_API_KEY or OPENAI_API_KEY, or on macOS from a Keychain item that spawnllm key set jev (or openai) writes from stdin.
Call the same backends from Go or Rust
All three languages run the identical engine: argv planning, output parsing, schema strictification, and retry policy live once in a Rust core — linked natively by the Rust crate, embedded as WASM by the Go module and the Python package — pinned by a shared golden-vector suite and released in lockstep.
go get github.com/yasyf/spawnllm/go   # pure Go, no cgo — the core embeds as WASM
cargo add spawnllm                    # async-first, with a blocking mirror
Both expose Call/call and typed Extract/extract against your existing CLI logins, and both reach Apple's on-device model on a capable Mac with binrun installed to fetch the digest-pinned sidecar — see the Go README and the Rust README. MLX stays Python-only.
More in the docs
- Spec-driven runs — a literal model id, per-provider flag passthrough, and envelope-aware retry via
RunSpec— Running reference - Decisions — every question and answer type, the provider pins, and the retry and key-lookup rules — Deciding reference
- Backend selection — the priority chain, plus
specialty=routing (debuggingandreviewgo to Codex,generalto the Claude Agent SDK backend) — Backends reference - Transport helpers —
run_cli,collect_process, andmap_concurrent, the subprocess plumbing shared by every CLI backend — Transport reference - The CLI —
spawnllm call,status,backends, andkey setfrom any shell — CLI reference - MLX internals — the adapter codec, fuser, and runtime patches behind the local engine — MLX reference
Read the docs for the full guide and API reference. Licensed under MIT.
1 maintainer

Metadata
1 maintainer
Release files for spawnllm 0.17.0
For a detailed explanation of source distributions (sdists) and built distributions (wheels), please see the package formats documentation.
Source distribution (sdist)
| File | Size | Uploaded | |
|---|---|---|---|
| spawnllm-0.17.0.tar.gz | 317.7 kB | Details |
Built distributions (wheels)
| File | Interpreter | ABI | Platform | Reset |
|---|---|---|---|---|
| spawnllm-0.17.0-py3-none-macosx_26_0_arm64.whl | Python 3 | none | macOS 26.0+ ARM64 | Details |
| spawnllm-0.17.0-py3-none-any.whl | Python 3 | none | any | Details |
Total release size: 1.1 MB
Release files / spawnllm-0.17.0.tar.gz
| Download URL | spawnllm-0.17.0.tar.gz |
|---|---|
| Size | 317.7 kB |
| Tags | Source |
|
SHA-256 checksum How to use checksums |
f6a19f6fef516f0f395464fdd02a78de1a16581560b8e471cad77e09f4725d32
|
|
BLAKE2b-256 checksum How to use checksums |
3bc4b488f878d4bb75ecb1586d16afeb3ff8a80365b01336d794d45deeeaa663
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
Yes |
| Uploaded via |
twine/6.1.0 CPython/3.13.14
|
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.


PyPI Publish Attestation
PyPI verified that this artifact, at this checksum, originated from the publisher listed below.
Signed by GitHub Actions, verified by PyPI on Oct 7, 2026.
Transparency logRelease files / spawnllm-0.17.0-py3-none-macosx_26_0_arm64.whl
| Download URL | spawnllm-0.17.0-py3-none-macosx_26_0_arm64.whl |
|---|---|
| Size | 416.0 kB |
| Tags | Python 3 macOS 26.0+ ARM64 |
|
SHA-256 checksum How to use checksums |
cf4380c044b88b916194ee5df97a2d84a9a9ad51f8117d8bf2b9e647db2cf716
|
|
BLAKE2b-256 checksum How to use checksums |
ef0b7f9d11d4371777db5b8e34f48ab5bfb0839fca29d89dc4194a249ae7fb07
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
Yes |
| Uploaded via |
twine/6.1.0 CPython/3.13.14
|
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.
PyPI Publish Attestation
PyPI verified that this artifact, at this checksum, originated from the publisher listed below.
Signed by GitHub Actions, verified by PyPI on Oct 7, 2026.
Transparency logRelease files / spawnllm-0.17.0-py3-none-any.whl
| Download URL | spawnllm-0.17.0-py3-none-any.whl |
|---|---|
| Size | 330.4 kB |
| Tags | Python 3 |
|
SHA-256 checksum How to use checksums |
8643d5650a33a752da6bc421a3d170d7ebb886169255297e3d9a0fc527af19a0
|
|
BLAKE2b-256 checksum How to use checksums |
25a7c188dcba7e18b7fba3e56dedecc2ce593bc7a07d81b0f4cd9e8b20133d0e
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
Yes |
| Uploaded via |
twine/6.1.0 CPython/3.13.14
|
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.
PyPI Publish Attestation
PyPI verified that this artifact, at this checksum, originated from the publisher listed below.
Signed by GitHub Actions, verified by PyPI on Oct 7, 2026.
Transparency log













