
SpecKit
A Python toolkit for dynamic-resolution spectral analysis
SpecKit is a high-performance Python toolkit for advanced spectral analysis, designed for scientists and engineers who require high-fidelity, high-dynamic-range spectral estimates.
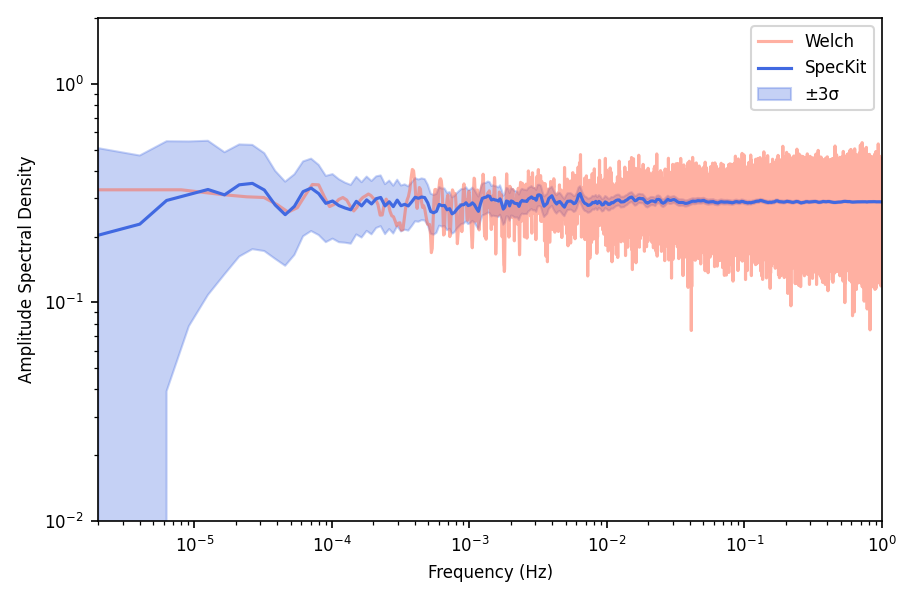
The library's core feature is its logarithmically-spaced frequency scheduling algorithm. Unlike traditional methods such as Welch’s, which use a fixed segment length and resolution across all frequencies, SpecKit dynamically adjusts the frequency resolution. The result is that, for a given dataset, this method provides many more high-resolution spectral estimates at low frequencies, while minimizing statistical uncertainty (via more averages) at high frequencies. This method is ideally suited for analyzing signals that span many decades in frequency.
Built on rigorous, textbook-backed theory, SpecKit also provides comprehensive error analysis for all its estimates, making it a reliable tool for scientific research.
Key Features
-
Logarithmic Frequency Scheduling
Dynamically adapts segment length and averaging to deliver optimal resolution and stability across the entire frequency spectrum. -
High-Performance Engine
Leveragesnumbafor JIT-compiling and parallelizing performance-critical code. Provides pure NumPy fallbacks for full portability. -
Comprehensive Spectral Quantities
Calculates a full suite of auto-spectral and cross-spectral estimates, including:- Power Spectral Density (PSD) and Amplitude Spectral Density (ASD)
- Cross Spectral Density (CSD)
- Transfer Functions and Coherence
- Conditioned spectra for MISO/SISO systems
-
Rigorous Error Analysis
Provides analytically derived standard deviations and normalized random errors for all key estimates, following Bendat & Piersol.
Additionally, SpecKit computes empirical errors directly from segment scatter using Welford-style accumulation (see below). -
Advanced DSP Utilities
Includes tools for:- Multi-file data loading/resampling
- High-order Lagrange interpolation for fractional time shifting
- Optimal linear combination for noise subtraction
- Specialized flat-top windows with known Equivalent Noise Bandwidth (ENBW)
-
High-Quality Noise Generation
Ultra-fast, numerically stable generators for white, red (Brownian), pink, and general 1/f^α colored noise. -
Publication-Ready Plotting
Built-in, user-friendly plotting interface for creating clear and professional figures.
Installation
Install SpecKit directly from PyPI:
pip install speckit
For development:
git clone https://github.com/mdovale/speckit.git
cd speckit
pip install -e '.[dev]'
Quickstart
The main user-facing function is speckit.compute_spectrum.
Here’s a simple example of computing the Amplitude Spectral Density (ASD) of a noisy signal and comparing it to SciPy’s Welch method:
import numpy as np
import matplotlib.pyplot as plt
from scipy.signal import welch
from speckit import compute_spectrum

N = int(1e6)  # samples
fs = 2.0      # Hz
x = np.random.randn(N)

# Welch (fixed resolution)
f_welch, psd_welch = welch(x, fs, window="hann", nperseg=N // 8)

# SpecKit (dynamic resolution)
result = compute_spectrum(x, fs=fs, Jdes=1000, Kdes=100, win="Kaiser", psll=200)

fig, ax = plt.subplots(figsize=(8, 5), dpi=150)
ax.loglog(f_welch, np.sqrt(psd_welch), label="Welch", color="tomato", alpha=0.7)
result.plot(which="asd", errors=True, sigma=3, ax=ax, label="SpecKit", color="royalblue")
ax.set_xlabel("Frequency (Hz)")
ax.set_ylabel(r"ASD (units / $\sqrt{\rm Hz}$)")
ax.legend()
ax.grid(True, which="both", linestyle="--", linewidth=0.5)
plt.show()
API Overview
Top-level entry point
speckit.compute_spectrum(data, fs, **kwargs)
Configures, plans, and executes a spectral analysis in one line.
Core classes
-
SpectrumAnalyzer
Configuration + computation object.
Methods:.plan()→ returns frequency/segmentation plan..compute()→ full spectrum analysis..compute_single_bin(freq, fres or L)→ analyze a single frequency bin.
-
SpectrumResult
Immutable container with all results and helper methods.
Attributes are lazily computed and cached on demand:psd,asd,csd,tf,coh,ENBW, …- Errors:
Gxx_dev,Hxy_dev,coh_error, etc. - Empirical errors:
XY_emp_dev,Gxy_emp_dev, … - Utilities:
.plot(),.to_dataframe(),.get_rms(),.get_measurement().
Performance Strategies
SpecKit is designed for datasets with millions of samples. Performance comes from:
-
Numba JIT Kernels
- Core bin-by-bin statistics are computed with hand-optimized Goertzel recurrences.
- Parallelized across segments using
numba.prange.
-
Selective Detrending
- Order =
-1: windowing only. - Order =
0: mean removal. - Order =
1,2: polynomial detrend via orthonormal basis (_build_Q). - The detrend mode changes which JIT kernel is dispatched.
- Order =
-
Window/Polynomial Caching
- Expensive objects like windows and polynomial bases are cached per segment length.
-
Fallback to NumPy
- If Numba is unavailable, pure-NumPy helpers vectorize segment processing.
- NumPy path uses highly optimized
polyfit/polyvalfor detrending.
-
Single-Bin Evaluation
.compute_single_bin()avoids planning full spectra and is highly efficient for probing specific frequencies.
Error Analysis and Welford’s Algorithm
Textbook formulas
SpecKit implements Bendat & Piersol-style analytic formulas:
- Standard deviations of PSD, CSD, and coherence estimates scale as
1/√n_d, wheren_d = ν/2is the equivalent number of independent averages. ν(SpectrumResult.nu) is the per-bin equivalent degrees of freedom from the window's overlap correlation at the actual segment starts (Percival & Walden 1993, p. 292). Without overlapν = 2K. At 75% Hann overlapν ≈ 1.04 K, soGxx_dev = Gxx·√(2/ν)is about 1.39× the independent-segment value.- Coherence errors scale with
(1 - γ²) / √n_d. The transfer-function phase errorHxy_rad_erroris√(1 - γ²) / (|γ| √(2 n_d))radians.
Empirical scatter (M2)
In addition, the JIT kernels compute:
MXX,MYY: mean segment powers.M2: mean squared deviation of per-segment cross-spectra about the mean.
This is essentially Welford’s algorithm for streaming variance, adapted to complex quantities.
From M2, SpecKit derives:
XY_emp_var: variance of the averaged cross-spectrum,M2 / n_d(the overlap correction above, so notM2 / K).XY_emp_dev: empirical standard deviation.Gxx_emp_dev,Gxy_emp_dev: empirical deviations mapped into spectral density units.
These provide non-parametric uncertainty estimates, complementing the analytic formulas. They are particularly useful when:
- The Gaussian assumptions of textbook theory may not hold.
- One wants to validate that statistical convergence is as expected.
M2 measures the per-segment scatter directly. Turning it into the error of the average still needs the overlap correlation, so the empirical errors use the same n_d = ν/2 as the analytic ones.
Why both?
- Analytic errors are fast, interpretable, and match the literature.
- Empirical errors reflect actual scatter in the data.
Together, they provide a complete picture of uncertainty.
References and Acknowledgements
-
General Spectral Analysis and Uncertainty
- Bendat, Piersol. Random Data: Analysis and Measurement Procedures. John Wiley & Sons.
- Bendat, Piersol. Engineering Applications of Correlation and Spectral Analysis. John Wiley & Sons.
-
Logarithmic Frequency Scheduling
- Tröbs, M., Heinzel, G. Improved spectrum estimation from digitized time series on a logarithmic frequency axis. doi:10.1016/j.measurement.2005.10.010
- Heinzel, G., Rüdiger, A., & Schilling, R. (2002). Spectrum and spectral density estimation by the Discrete Fourier transform (DFT), including a comprehensive list of window functions and some new flat-top windows. Max-Planck-Institut für Gravitationsphysik.
- Basis for SpecKit’s
schedulers.lpsd_planandschedulers.ltf_plan, inspired by algorithms developed for LISA Pathfinder data analysis.
-
Colored Noise Generation
- Plaszczynski, S. (2007). Generating long streams of 1/f^α noise. Fluctuation and Noise Letters. doi:10.1142/S0219477507003635
- Provides the stable cascade-of-filters method used in SpecKit.
- Numba-optimized version of original code by Jan Waldmann
-
High-order Lagrange Interpolation
lagrange.timeshiftandlagrange.lagrange_tapsare adapted from the PyTDI project and re-exported asdsp.timeshiftanddsp.lagrange_taps.- Credit to: Staab, Martin, Bayle, Jean-Baptiste, Hartwig, Olaf. Copyright 2022, California Institute of Technology and the Max Planck Institute for Gravitational Physics. See NOTICE.
License
BSD 3-Clause License. See LICENSE. Third-party copyrights are listed in NOTICE.
Contributing
Contributions are welcome!
Please open issues or PRs for bug reports, feature requests, or ideas.
1 maintainer

Metadata
1 maintainer
Release files for speckit 1.0.3
For a detailed explanation of source distributions (sdists) and built distributions (wheels), please see the package formats documentation.
Source distribution (sdist)
| File | Size | Uploaded | Provenance | |
|---|---|---|---|---|
| speckit-1.0.3.tar.gz | 111.3 kB | Without provenance | Details |
Built distribution (wheel)
| File | Interpreter | ABI | Platform | Reset |
|---|---|---|---|---|
| speckit-1.0.3-py3-none-any.whl | Python 3 | none | any | Details |
Total release size: 203.4 kB
Release files / speckit-1.0.3.tar.gz
| Download URL | speckit-1.0.3.tar.gz |
|---|---|
| Size | 111.3 kB |
| Tags | Source |
|
SHA-256 checksum How to use checksums |
0b6c42647e310237de7b84a343939f726301517cf6484dd7489125cfac630393
|
|
BLAKE2b-256 checksum How to use checksums |
e9a9407467396418efba59e63d81777e59c2068c718badf7a0800f5d1b50355d
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
No |
| Uploaded via |
twine/7.0.0 CPython/3.12.15
|
Release files / speckit-1.0.3-py3-none-any.whl
| Download URL | speckit-1.0.3-py3-none-any.whl |
|---|---|
| Size | 92.1 kB |
| Tags | Python 3 |
|
SHA-256 checksum How to use checksums |
585dd916b535caa1417484b8f45c2dd5c4884e669dded6560476d0912c625837
|
|
BLAKE2b-256 checksum How to use checksums |
4f962759aeb4de1291683709cfeb58353850f258affef96814738fcb6acb2c98
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
No |
| Uploaded via |
twine/7.0.0 CPython/3.12.15
|
Security for speckit 1.0.3
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.
No provenance found
None of the files in this release were uploaded with provenance metadata.
A note on package security
PyPI is a repository for distributing packages, not a service for auditing them. While third-party security researchers and our staff do their best to detect and remove malicious packages, PyPI cannot guarantee the quality, security or suitability of any given package.
To learn more about protecting yourself from malicious actors, visit our package security documentation.














