


specsr sharpens low-resolution galaxy spectra by roughly a factor of ten in
resolving power (R ~ 100 → R ~ 1000), recovering narrow emission-line structure —
including blended doublets such as [O III] λλ4959,5007 and Hβ — that is
unresolvable at prism resolution. It is trained on paired JWST/NIRSpec
observations from JADES, where each galaxy contributes a prism spectrum and a
stitched medium-resolution grating reference.
from specsr.inference import SpecSRPipeline

pipeline = SpecSRPipeline.from_pretrained()      # weights fetched from the Hub
result = pipeline(flux_low, wavelength_low)      # your own wavelength grid

result.sr1           # super-resolved spectrum
result.sr2           # after physics-informed line refinement
result.sr2_sigma     # wavelength-dependent predictive uncertainty
result.z             # inferred redshift, with result.z_sigma
result.wavelength    # the model's grid, in microns
Pass wavelength_low unless your spectrum is already on pipeline.wavelength:
the input is then resampled onto the model's grid by integration rather than
interpolation, so line flux is preserved. SpecSRPipeline.from_checkpoints(dir)
loads a local set of weights instead of the Hub.
Installation
pip install "specsr[hub]"
PyTorch is required. On a GPU machine, install the build matching your driver
from the official index before
installing specsr, so pip does not resolve a mismatched CUDA stack. Extras:
[hub] for automatic weight download, [train] for the training stack,
[all] for everything. To track main instead of a release:
pip install "git+https://github.com/aryana-haghjoo/specsr.git#egg=specsr[hub]".
Tutorials
Three executable notebooks in tutorials_for_user/, with
real held-out JADES spectra bundled so they run with no survey data and no
configuration:
| notebook | covers |
|---|---|
01_quickstart.ipynb |
run the chain on one spectrum, read the output, plot it fairly |
02_your_own_spectrum.ipynb |
arbitrary wavelength grids, resampling, and what grid coarseness does to lines |
03_batches_and_trust.ipynb |
batches, uncertainty calibration, flux recovery vs line brightness, failure modes |
How it works
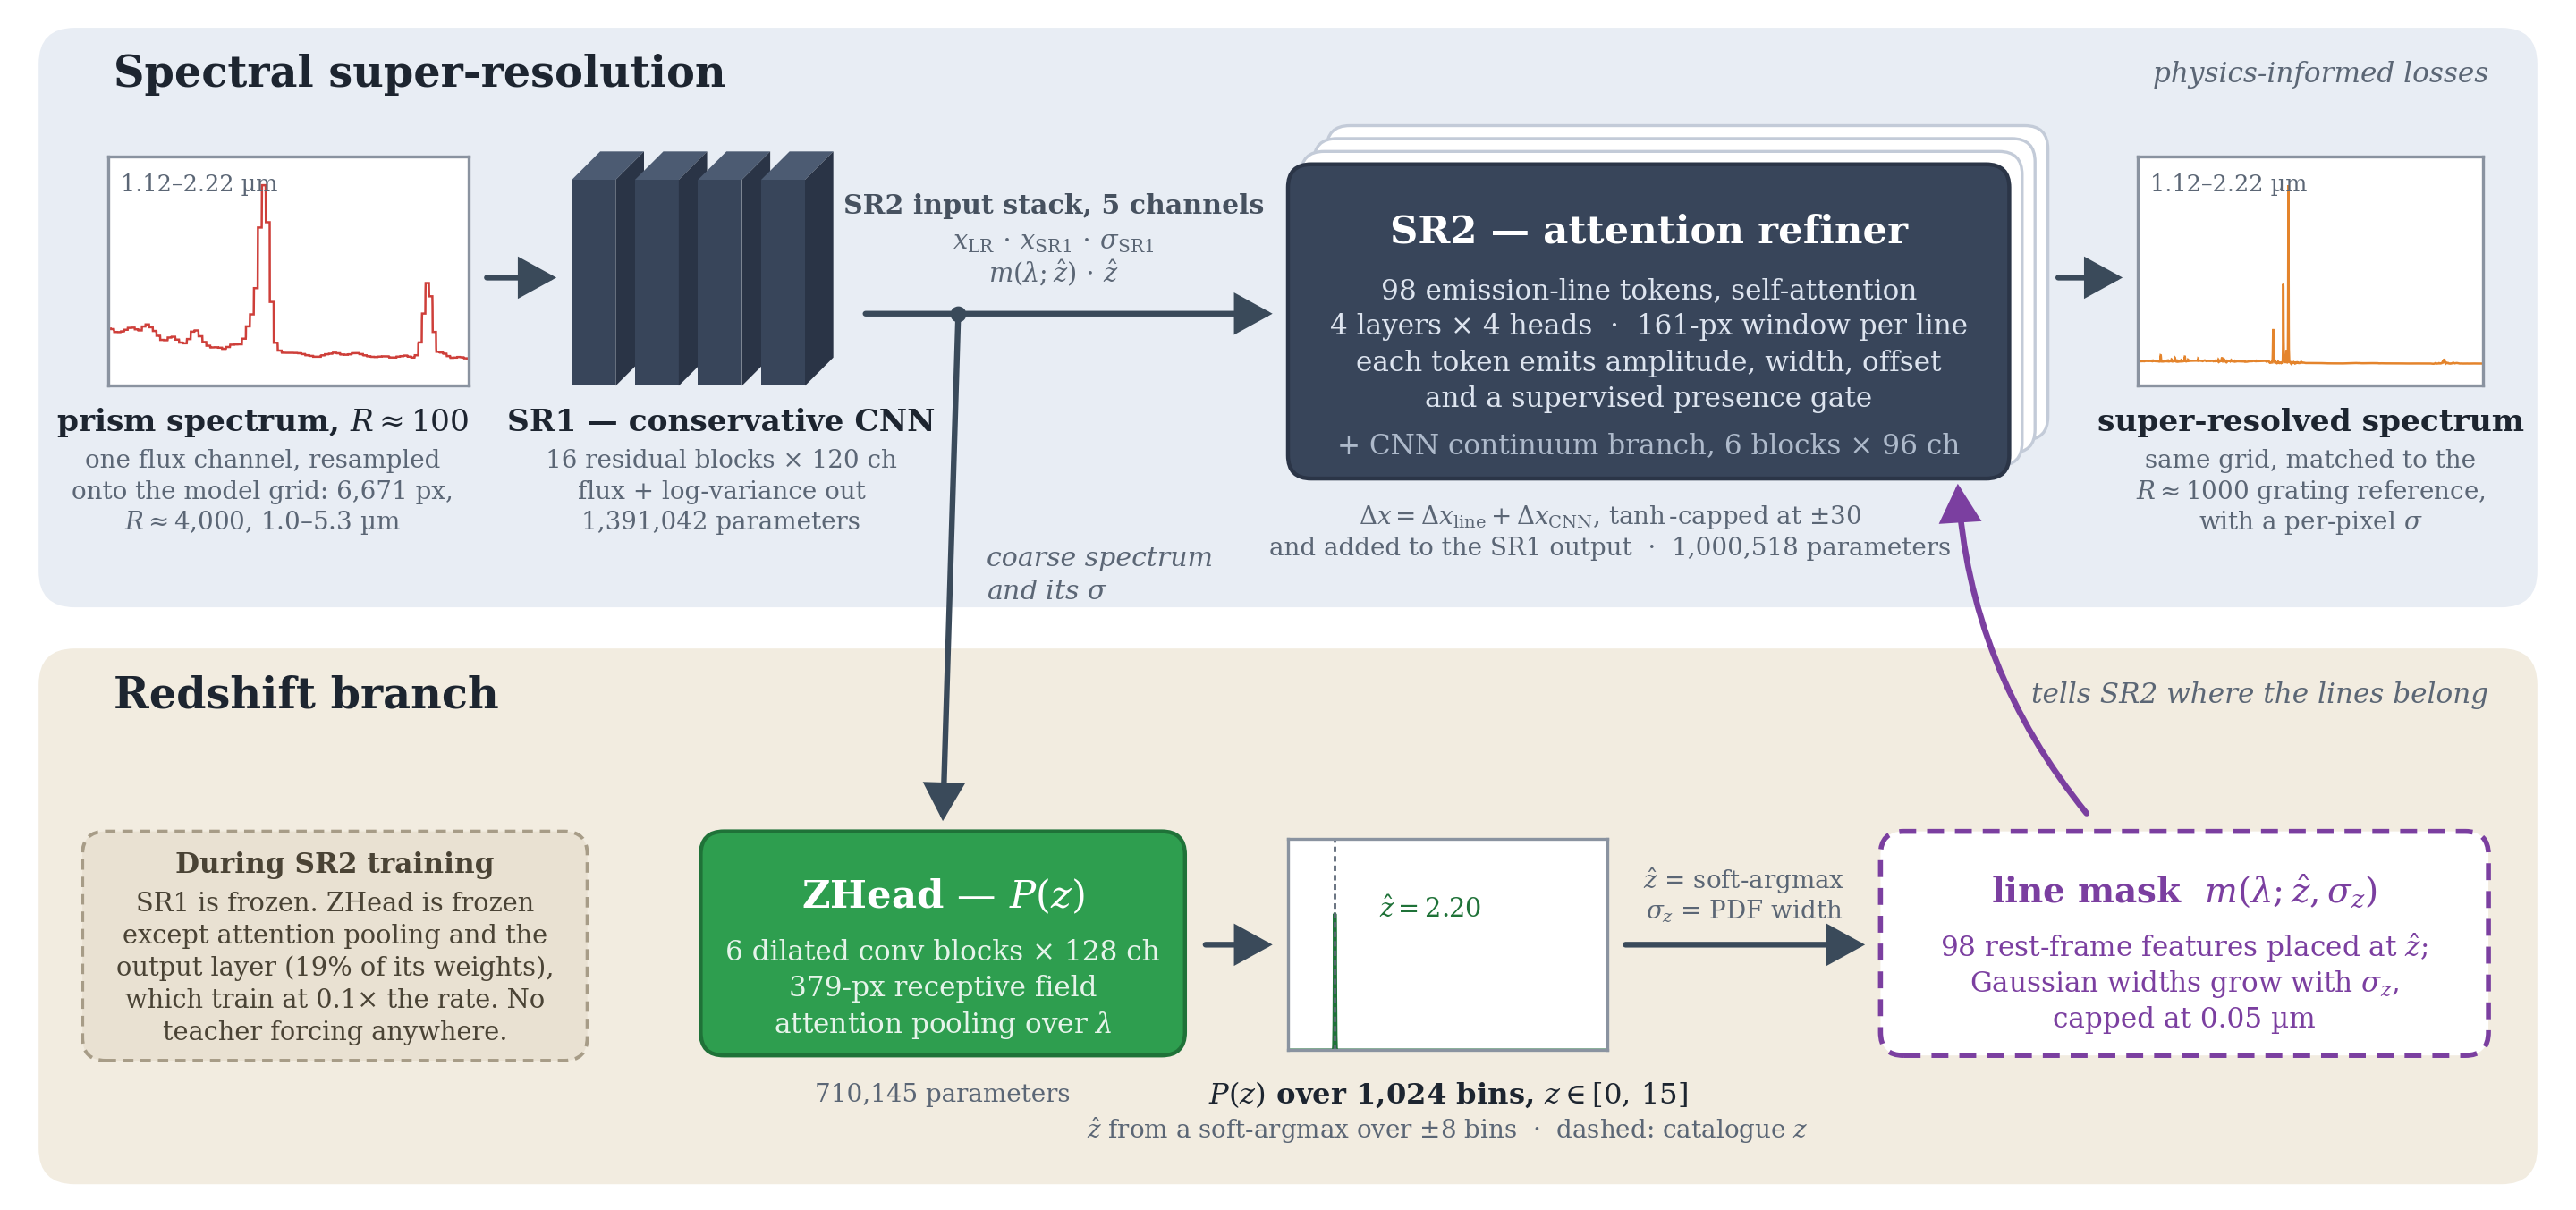
Three stages, trained in sequence, each freezing the one before it:
| stage | role | parameters |
|---|---|---|
| SR1 | 1D residual CNN backbone: prism → grating-like reconstruction, with a per-pixel variance | 1,391,042 |
| ZHead | redshift inference from SR1's output; a softmax PDF over 1,024 bins spanning 0 ≤ z ≤ 15 | 710,145 |
| SR2 | residual refiner: attention over 98 emission-line tokens, each a parametric Gaussian gated by a supervised presence probability, plus a CNN continuum branch | 1,000,518 |
Every number on the diagram is read off the released checkpoints at draw time by
scripts/make_architecture_figure.py, and
its inset panels are real predictions for a held-out galaxy — a retrain that
changes a width or a depth changes the figure rather than silently invalidating
it. ARCHITECTURE.md explains the design and the invariants
the code enforces.
What it does and does not do
Deblends features unresolved at prism resolution, improves emission-line S/N for [O II], Hβ, [O III] and Hα, reaches noise-limited residuals above ~2 µm, and recovers redshift information approaching that of the high-resolution reference. It applies a learned prior from the training distribution: it cannot reconstruct features that have no statistical relationship with the prism data.
Limitations, all measured rather than suspected:
- Absolute flux scale is not predicted — only spectral shape.
- Line-flux recovery is a strong function of line brightness. Bright lines keep most of their flux; faint ones are systematically under-recovered. Any flux-accuracy figure quoted without a signal-to-noise cut attached is meaningless.
- Super-resolution does not improve line fluxes over the input. Measured with profile fits, the prism already recovers the total flux of strong lines (median ratio to the reference 0.91–1.09, 2–11% of lines off by more than a factor of two); the reconstruction is lower and more scattered (0.72–0.87, 24–30%). Take total line fluxes from the input spectrum.
- The redshift head is a conditioning stage, not a redshift pipeline. Its catastrophic-outlier rate is high enough that a redshift should be checked against the line positions it implies.
- Super-resolution does not beat direct fitting of the prism on the [O III] doublet-ratio test.
- The paired training sample is small by machine-learning standards, and generalisation to populations underrepresented in JADES — very dusty systems, low-mass galaxies, the highest-redshift sources — is not established.
- Performance degrades below ~1.5 µm, where both the input and the reference have low S/N.
The model card carries the full performance tables, with scatter and sample sizes.
Command line
specsr build-dataset --release DR4      # raw JADES x1d products -> paired dataset

specsr train sr1   --config configs/sr1.yaml --out-dir runs/sr1
specsr train zhead --config configs/zhead.yaml --source sr1 --out-dir runs/zhead \
    --sr1-ckpt runs/sr1/best_superres_model.pth --sr1-config configs/sr1.yaml
specsr train sr2   --config configs/sr2.yaml --out-dir runs/sr2 \
    --sr1-ckpt runs/sr1/best_superres_model.pth --sr1-config configs/sr1.yaml \
    --zhead-ckpt runs/zhead/best_zhead.pth

specsr infer --dataset data/paired_DR4_logR.npz --idx 0 10 42 --save predictions.npz
specsr evaluate line-flux
Upstream checkpoints are named explicitly rather than discovered, so every model
records what it was trained on top of. Everything the package writes — figures,
predictions, evaluation tables — goes under SPECSR_OUTPUT_DIR (default
./outputs). See the training guide.
Data
Raw JWST/JADES data is not distributed with the package. You need it only to rebuild the dataset or retrain — running the released models on your own spectra requires nothing but the weights, which download on first use.
export SPECSR_JADES_ROOT=/path/to/JADES_data   # contains DR3/, DR4/, ...
export SPECSR_DATA_DIR=/path/to/derived        # where built products are written
specsr build-dataset --release DR4
The data guide covers where to download each release and the directory layout the builder expects.
Splits are drawn over parent galaxies, never over rows. Each galaxy contributes 21 highly correlated rows — one real spectrum plus 20 augmented realisations — and only training galaxies are augmented, so a held-out galaxy contributes exactly its real spectrum and nothing synthetic derived from it. The splitter refuses to return a split that leaks a galaxy across the boundary.
from specsr.data.splits import get_training_split
train_idx, val_idx, path = get_training_split("data/paired_DR4_logR.npz")
Repository layout
src/specsr/          all library code (see ARCHITECTURE.md)
configs/             stage configs and W&B sweep definitions
scripts/             thin entry points: argument parsing and file IO only
tests/               unit tests plus checkpoint-reproduction guards
tutorials_for_user/  executable notebooks with bundled sample spectra
docs/                Sphinx documentation
Documentation is at https://aryana-haghjoo.github.io/specsr/, or build it
locally with pip install "specsr[docs]" then
sphinx-build -b html docs docs/_build/html.
Citation
Please cite the paper for the method, and the Zenodo record if you need to reference a specific version of the code:
@software{haghjoo2026specsr_code,
  author    = {Haghjoo, Aryana},
  title     = {specsr: physics-informed super-resolution of JWST/NIRSpec prism spectra},
  year      = {2026},
  publisher = {Zenodo},
  doi       = {10.5281/zenodo.21943196},
  url       = {https://doi.org/10.5281/zenodo.21943196},
  note      = {Concept DOI; resolves to the latest version}
}
@article{haghjoo2026specsr,
  title   = {Learning to See Sharper: A Physics-Informed Artificial Intelligence
             Framework for Super-Resolving Galaxy Spectra},
  author  = {Haghjoo, Aryana and Hemmati, Shoubaneh and Mobasher, Bahram and others},
  journal = {The Astrophysical Journal},
  year    = {2026},
  eprint  = {2603.18357},
  archivePrefix = {arXiv},
  primaryClass  = {astro-ph.GA}
}
License
MIT — see LICENSE.
1 maintainer

Metadata
1 maintainer
Release files for specsr 1.2.0
For a detailed explanation of source distributions (sdists) and built distributions (wheels), please see the package formats documentation.
Source distribution (sdist)
| File | Size | Uploaded | Provenance | Actions |
|---|---|---|---|---|
| specsr-1.2.0.tar.gz | 2.1 MB | With provenance | Details for specsr-1.2.0.tar.gz |
Built distribution (wheel)
| File | Interpreter | ABI | Platform | Actions Reset |
|---|---|---|---|---|
| specsr-1.2.0-py3-none-any.whl | Python 3 | none | any | Details for specsr-1.2.0-py3-none-any.whl |
Total release size: 2.2 MB
Release files / specsr-1.2.0.tar.gz
| Download URL | specsr-1.2.0.tar.gz |
|---|---|
| Size | 2.1 MB |
| Tags | Source |
|
SHA-256 checksum How to use checksums |
dc467a2f5c0f6c79d5874e7c902776f805fc68928140dd43698528441cd410df
|
|
BLAKE2b-256 checksum How to use checksums |
7e5c09de38424ef6346bd737df335e9de2a19e3712f45eb1e98cb41da393fa85
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
Yes |
| Uploaded via |
twine/7.0.0 CPython/3.13.14
|
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.


PyPI Publish Attestation
PyPI verified that this artifact, at this checksum, originated from the publisher listed below.
Signed by GitHub Actions, verified by PyPI on Oct 6, 2026.
Transparency logRelease files / specsr-1.2.0-py3-none-any.whl
| Download URL | specsr-1.2.0-py3-none-any.whl |
|---|---|
| Size | 177.7 kB |
| Tags | Python 3 |
|
SHA-256 checksum How to use checksums |
dde466980a9889b6b532ffa96bf5367aec81ccb001bf29594078113608072246
|
|
BLAKE2b-256 checksum How to use checksums |
4408e5d7528d5e6df8bb2b4c422940aea8623d13537f4a793ef90a2dfd31b6ca
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
Yes |
| Uploaded via |
twine/7.0.0 CPython/3.13.14
|
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.
PyPI Publish Attestation
PyPI verified that this artifact, at this checksum, originated from the publisher listed below.
Signed by GitHub Actions, verified by PyPI on Oct 6, 2026.
Transparency logSecurity for specsr 1.2.0
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.
Full provenance
All 2 files in this release have been uploaded with provenance metadata.
Attestation for specsr-1.2.0.tar.gz
PyPI Publish Attestation
PyPI verified that this artifact, at this checksum, originated from the publisher listed below.
Signed by GitHub Actions, verified by PyPI on Oct 6, 2026.
Transparency logA note on package security
PyPI is a repository for distributing packages, not a service for auditing them. While third-party security researchers and our staff do their best to detect and remove malicious packages, PyPI cannot guarantee the quality, security or suitability of any given package.
To learn more about protecting yourself from malicious actors, visit our package security documentation.














