
SQErzo Tiny ORM for Graph databases
- What is SQErzo
- Which databases are supported
- Why use SQErzo?
- Project status
- Install
- Usage examples
- ChangeLog
- TODO
- References
- Authors
- Contributions
- License
What is SQErzo
SQErzo is simple and tiny ORM (Object-Relational Mapping) for graph databases for Python developers.
It's compatible with databases that supports Open Cypher language.
Which databases are supported
| Database | Status |
|---|---|
| Neo4j | Supported |
| Redis Graph | Supported |
| Arango DB | Looking for contributor |
| AWS Neptune | Looking for contributor |
| Gremlin | Looking for contributor |
Why use SQErzo?
SQErzo intermediates between the graph database and your application logic in a database agnostic way. As such, SQErzo abstracts the differences between the different databases. For examples:
- RedisGraph doesn't support Date times or CONSTRAINTS,
SQErzodoes the magic to hide that. - Neo4j need different channels for writing than for read.
SQErzodoes the magic to hide that. SQErzointegrates a in memory cache to avoid queries to Graph DB and try to improve the performance.- Every database uses their own Node/Edge identification system. You need to manage and understand then to realize when a node already exits in Graph DB.
SQErzodo this for you. It doesn't matter the Graph DB engine you use. SQErzowas made to avoid you to write useless code. You can create and manage Nodes and Edges in a few lines of code without know Graph DB internals.SQErzosupports Graph DB bases on Open cypher language (a Graph databases query language). You don't need to learn them to perform day a day operations.
Project status
Project is in a very early stage. If you want to use them, have in count that.
Install
Install is easy. Only run:
> pip install sqerzo
Usage examples
Run databases uses Docker.
Start Neo4j
> docker run -d -p7474:7474 -p7687:7687 -e NEO4J_AUTH=neo4j/s3cr3t neo4j
Start RedisGraph
> docker run -p 7000:6379 -d --rm redislabs/redisgraph
Simple usage
Create some nodes and setup database in both databases:
- Neo4j
- RedisGraph
Without the need to change any code:
from dataclasses import dataclass

from sqerzo import GraphEdge, GraphNode, SQErzoGraph

class MeetEdge(GraphEdge):
    pass

@dataclass
class UserNode(GraphNode):
    name: str = None


def create_graph(connection_string: str):
    gh = SQErzoGraph(connection_string)
    gh.truncate()  # Drop database

    u1 = UserNode(name=f"UName-1")
    gh.save(u1)

    d1 = UserNode(name=f"DName-2")
    gh.save(d1)

    u1_meet_g1 = MeetEdge(
        source=u1,
        destination=d1
    )
    gh.save(u1_meet_g1)


if __name__ == '__main__':
    create_graph("redis://127.0.0.1:7000/?graph=email")
    create_graph("neo4j://neo4j:s3cr3t@127.0.0.1:7687/?graph=email")
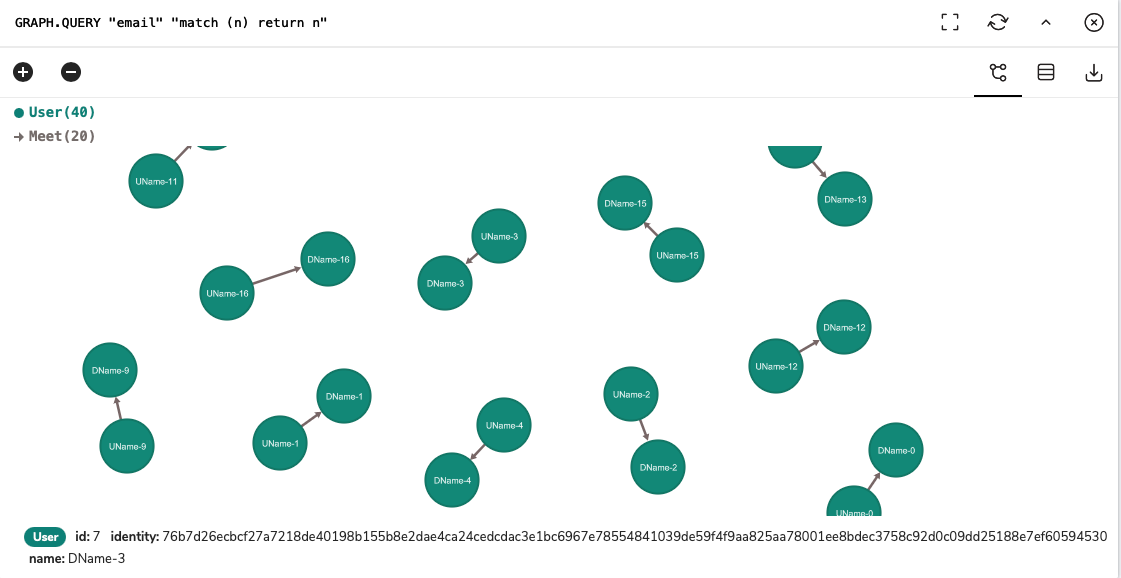
This is the result database in Node4j:

This is the result database in RedisGrap:
Recovering database nodes by their ID
from dataclasses import dataclass

from sqerzo import GraphEdge, GraphNode, SQErzoGraph
from sqerzo.exceptions import SQErzoElementExistException

@dataclass
class UserNode(GraphNode):
    name: str = None

def create_graph(connection_string: str):
    gh = SQErzoGraph(connection_string)
    gh.truncate()  # Drop database

    user = UserNode(name=f"UName-{n}")
    gh.save(user)

    # First argument: node ID we want to recover
    # Second argument: node class in which we want to map the result
    recovered_user = gh.get_node_by_id(user.id, UserNode)
Recovering database nodes by their properties
Getting one node:
from dataclasses import dataclass

from sqerzo import GraphEdge, GraphNode, SQErzoGraph

@dataclass
class UserNode(GraphNode):
    __keys__ = ["name"]

    name: str = None

def create_graph(connection_string: str):
    gh = SQErzoGraph(connection_string)
    gh.truncate()  # Drop database

    u1 = UserNode(name="Eustaquio")
    gh.save(u1)
    u2 = UserNode(name="Guachinche")
    gh.save(u2)

    # First argument: node ID we want to recover
    # Second argument: node class in which we want to map the result
    node = gh.fetch_one(UserNode, name="Eustaquio")

if __name__ == '__main__':
  create_graph("redis://127.0.0.1:7000/?graph=email")
  create_graph("neo4j://neo4j:s3cr3t@127.0.0.1:7687/?graph=email")
Getting multiple nodes:
from dataclasses import dataclass

from sqerzo import GraphEdge, GraphNode, SQErzoGraph

@dataclass
class UserNode(GraphNode):
    name: str = None
    age: int = None

def create_graph(connection_string: str):
    gh = SQErzoGraph(connection_string)
    gh.truncate()  # Drop database

    u1 = UserNode(name="Eustaquio", age=22)
    gh.save(u1)
    u2 = UserNode(name="Guachinche", age=22)
    gh.save(u2)

    # First argument: node ID we want to recover
    # Second argument: node class in which we want to map the result
    for n in gh.fetch_many(UserNode, age=22):
        print(n)

if __name__ == '__main__':
  create_graph("redis://127.0.0.1:7000/?graph=email")
  create_graph("neo4j://neo4j:s3cr3t@127.0.0.1:7687/?graph=email")
from dataclasses import dataclass

from sqerzo import GraphEdge, GraphNode, SQErzoGraph
from sqerzo.exceptions import SQErzoElementExistException

@dataclass
class UserNode(GraphNode):
    name: str = None

def create_graph(connection_string: str):
    gh = SQErzoGraph(connection_string)
    gh.truncate()  # Drop database

    user = UserNode(name=f"UName-{n}")
    gh.save(user)

    #
    # First argument: node ID we want to recover
    # Second argument: node class in which we want to map the result
    recovered_user = gh.get_node_by_id(user.id, UserNode)

if __name__ == '__main__':
  create_graph("redis://127.0.0.1:7000/?graph=email")
  create_graph("neo4j://neo4j:s3cr3t@127.0.0.1:7687/?graph=email")
Raw queries
SQErzo try to be simple. So, if you want to do complex queries, you'll write them in the DB Engine language.
This example explains how to perform a query in Open Cypher language and map the results to Python Classes:
from dataclasses import dataclass

from sqerzo import GraphEdge, GraphNode, SQErzoGraph

class MeetEdge(GraphEdge):
    pass

class WorksWithEdge(GraphEdge):
    pass

@dataclass
class UserNode(GraphNode):
    __keys__ = "email"

    name: str = None
    email: str = None


def create_graph(connection_string: str, nodes_count = 500):
    gh = SQErzoGraph(connection_string)
    gh.truncate()  # Drop database

    #
    # Add some data and relations: User1 -[meet]-> User 2
    #
    with gh.transaction() as tx:

        for n in range(nodes_count):
            u1_name = f"uname{n}"
            d1_name = f"dname{n}"

            u1 = UserNode(name=u1_name, email=f"{u1_name}@{u1_name}.com")
            d1 = UserNode(name=d1_name, email=f"{d1_name}@{d1_name}.com")

            tx.add(u1)
            tx.add(d1)

            u2_meet_u1 = MeetEdge(
                source=u1,
                destination=d1
            )
            u1_meet_u2 = MeetEdge(
                source=d1,
                destination=u1
            )
            tx.add(u1_meet_u2)
            tx.add(u2_meet_u1)

    #
    # HERE STARTS THE QUERY
    #

    # Execute will return a list of lists: [
    #   [UserNode("u1"), UserNode("u2")],
    #   [UserNode("u1"), UserNode("u2")],
    #   ...
    # ]
    q = gh.Query.raw(
        "match (u1:User)-[:Meet]->(u2:User) return u1, u2"
    ).execute(map_to={"u1": UserNode, "u2": UserNode})

    print(q)

if __name__ == '__main__':
  count = 1000
  create_graph("redis://127.0.0.1:7000/?graph=email", nodes_count=count)
  create_graph("neo4j://neo4j:s3cr3t@127.0.0.1:7687/?graph=email", nodes_count=count)
Transactions
Transactions are useful if you need add a lot of data. You add nodes and edges to a transaction. When they finish then perform the insertions to the database in a very efficient way:
from dataclasses import dataclass

from sqerzo import GraphEdge, GraphNode, SQErzoGraph

class MeetEdge(GraphEdge):
    pass

@dataclass
class UserNode(GraphNode):
    __keys__ = ["name"]

    name: str = None

def create_graph(connection_string: str):
    gh = SQErzoGraph(connection_string)
    gh.truncate()  # Drop database

    with gh.transaction() as tx:  # Transaction starts here

        for n in range(500):  # Inserts 1000 nodes (500 * 2) and 500 relations
            u1 = UserNode(name=f"UName-{n}")
            d1 = UserNode(name=f"DName-{n}")

            tx.add(u1)
            tx.add(d1)

            u1_meet_g1 = MeetEdge(
                source=u1,
                destination=d1
            )
            tx.add(u1_meet_g1)


if __name__ == '__main__':
    print("Redis...")
    create_graph("redis://127.0.0.1:7000/?graph=email")
    print("Neo4j...")
    create_graph("neo4j://neo4j:s3cr3t@127.0.0.1:7687/?graph=email")
More complex example: Load mails to a Graph
If you need a more complex example, you can find in it examples/email_graph.py.
At this example we load a random generated mail inbox (generation script is also available) into a Graph Database following this Neo4j Blog Post suggestions.
ChangeLog
Release 0.1.2
Core
- fixed - Node/Edge id generation when not explicit identity field was provided.
- fixed -
get_node_by_id(...)methods that raises execution. - fixed - Improved error control.
- fixed -
fetch_nodes(...)method, that raises when a query returns more than 1 result. - Improved -
fetch_many(...)andfetch_one(...).
Other
- Added new examples in
examplesfolder. - Added new examples in README.
- Updated examples for new SQErzo API.
- Updated docker-compose with some fixes.
Release 0.1.1
- Added queries support for raw queries in DB engine language
Release 0.1.0
- Improved speed at insertion by 100x
- Add support for
UNIQUEcreate_constraints_nodes - Add support for
INDEXEScreate_constraints_nodes - Add support for raw Cypher query
- Errors, issues, new features and something else
- Complete refactor to easy add new backends
- Complete refactor to easy add new backends
- Add new methods: fetch_many, fetch_one, raw_query, save, update & transaction
- Add new examples
- Improved the way to build the Node to avoid waste memory.
TODO
- Implement update operations
- Improve documentation
- Improve cypher query to avoid query raises when a transaction insert a duplicate node
- Add support for Arango DB
- Add support for AWS Neptune
- Add support for Gremlin
- Add support for dates to RedisGraph using transformation of dates to numbers
- Implementation of Query builder. Add some method to
Querybuilder class. Here some possible examples:
from dataclasses import dataclass

from sqerzo import GraphEdge, GraphNode, SQErzoGraph


class MeetEdge(GraphEdge):
    pass

class WorksWithEdge(GraphEdge):
    pass

@dataclass
class UserNode(GraphNode):
    __keys__ = "email"

    name: str = None
    email: str = None

@dataclass
class OtherUserNode(GraphNode):
    __keys__ = "email"

    name: str = None
    email: str = None


gh = SQErzoGraph("redis://")
gh.Q().from(Node1).to(node2).execute()
gh.Q().from(name="me").to(UserNode).execute()
gh.Q().from(name="me", email="me@me.com").to((UserNode, "User")).execute()
gh.Q().from(name="me").across((WorksWithEdge, "WorksWith")).to((UserNode, "OtherUser")).execute()
gh.Q().to((UserNode, "OtherUser")).execute()
gh.Q().from(OtherUserNode).execute()
gh.Q().from(UserNode).execute()
References
I tried to use good practices for building SQErzo. Some references I used:
- https://medium.com/neo4j/cypher-query-optimisations-fe0539ce2e5c
- https://hub.packtpub.com/advanced-cypher-tricks/
- https://gist.github.com/jexp/caeb53acfe8a649fecade4417fb8876a
Authors
SQErzo is being developed by BBVA-Labs Security team members.
Contributions
Contributions are of course welcome. See CONTRIBUTING or skim existing tickets to see where you could help out.
License
SQErzo is Open Source Software and available under the Apache 2 license
1 maintainer

Metadata
1 maintainer
Release files for sqerzo 0.1.3.post2
For a detailed explanation of source distributions (sdists) and built distributions (wheels), please see the package formats documentation.
Source distribution (sdist)
| File | Size | Uploaded | Provenance | |
|---|---|---|---|---|
| sqerzo-0.1.3.post2.tar.gz | 20.5 kB | Without provenance | Details |
Built distribution (wheel)
| File | Interpreter | ABI | Platform | Reset |
|---|---|---|---|---|
| sqerzo-0.1.3.post2-py3-none-any.whl | Python 3 | none | any | Details |
Total release size: 45.5 kB
Release files / sqerzo-0.1.3.post2.tar.gz
| Download URL | sqerzo-0.1.3.post2.tar.gz |
|---|---|
| Size | 20.5 kB |
| Tags | Source |
|
SHA-256 checksum How to use checksums |
0e50c681707d7b1b996c9034921118f8b135b1f6930d5d1da8a9ed8ef69c24fa
|
|
BLAKE2b-256 checksum How to use checksums |
d87e04c56ee2906ebf25fd1014a710ba9b4498757da825cb50bf58fbc8bc204e
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
No |
| Uploaded via |
twine/3.3.0 pkginfo/1.7.0 requests/2.25.1 setuptools/52.0.0 requests-toolbelt/0.9.1 tqdm/4.56.0 CPython/3.8.7
|
Release files / sqerzo-0.1.3.post2-py3-none-any.whl
| Download URL | sqerzo-0.1.3.post2-py3-none-any.whl |
|---|---|
| Size | 25.0 kB |
| Tags | Python 3 |
|
SHA-256 checksum How to use checksums |
d9fc2a20449818d3a4383b2a9a9cf2a27f4f5bc10843b540eb725f8bb6a1e2c7
|
|
BLAKE2b-256 checksum How to use checksums |
517927cd868d060fed51e7304b6f3ad0a9d6305d671053bafc01f89f3ca8764f
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
No |
| Uploaded via |
twine/3.3.0 pkginfo/1.7.0 requests/2.25.1 setuptools/52.0.0 requests-toolbelt/0.9.1 tqdm/4.56.0 CPython/3.8.7
|
Security for sqerzo 0.1.3.post2
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.
No provenance found
None of the files in this release were uploaded with provenance metadata.
A note on package security
PyPI is a repository for distributing packages, not a service for auditing them. While third-party security researchers and our staff do their best to detect and remove malicious packages, PyPI cannot guarantee the quality, security or suitability of any given package.














