
strands-plan-tool
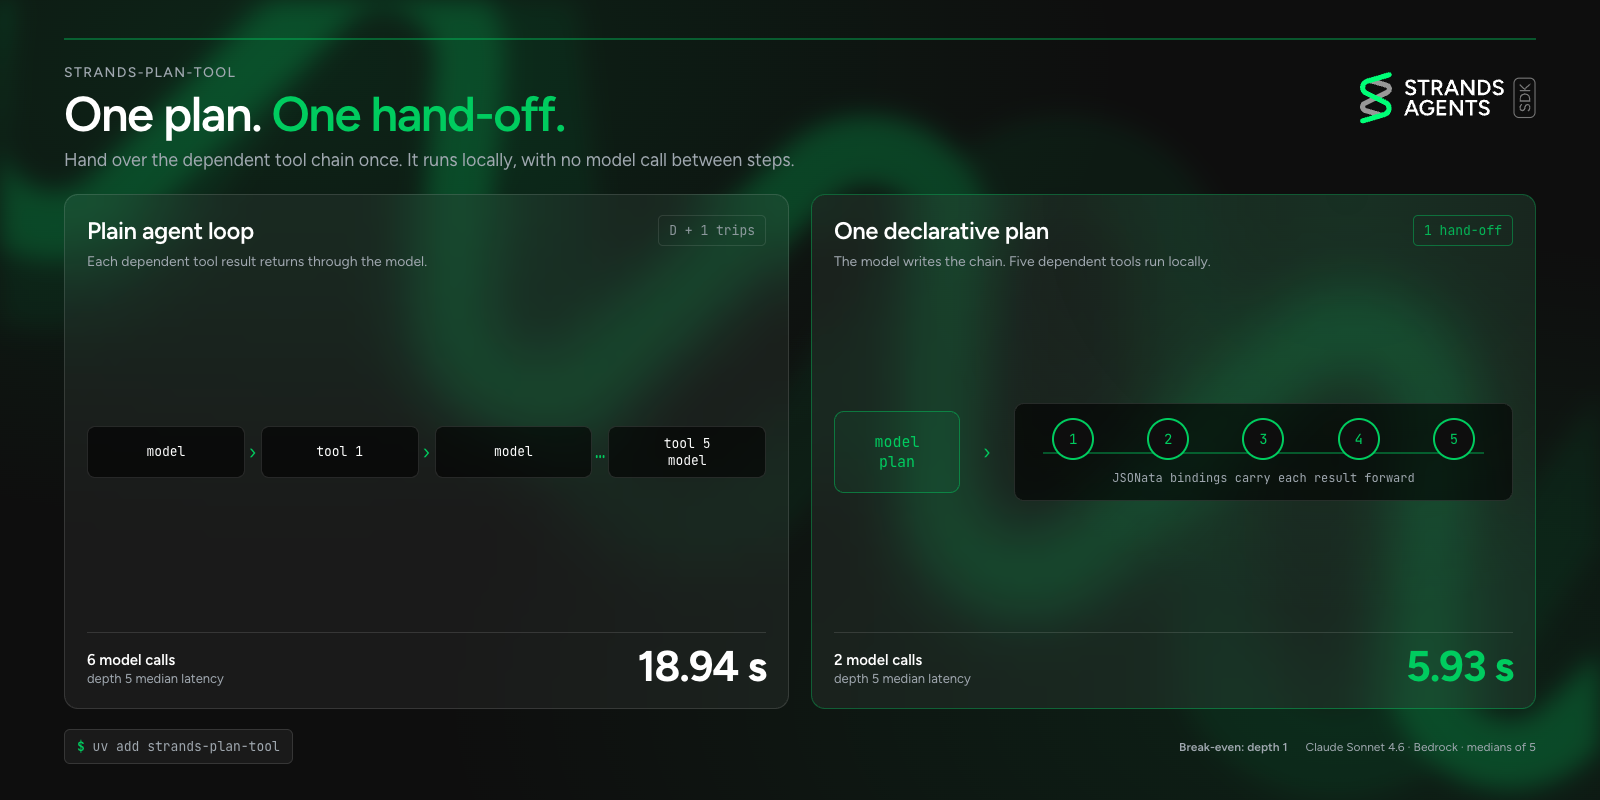
When your agent needs three tool calls in a row, you wait for the model three times — not because it is thinking, but because it has to be asked again before it can make the next call.
This adds one tool that lets the model hand over the whole chain at once. A plain loop calls the model D + 1 times for a chain of depth D; with a plan, no model call happens between steps.
uv add strands-plan-tool
A complete example
A Game Master resolving an attack: look up the monster, roll against its armour, apply the damage. Three tools, each needing the one before it.
Needs AWS credentials and Bedrock model access — export AWS_PROFILE=... and
export AWS_REGION=.... Pass Agent(model=BedrockModel(model_id=...)) to pick a model
explicitly; omitted here, so Strands uses its default.
from typing import TypedDict

from strands import Agent, tool

from strands_plan_tool.strands_adapter import WorkflowPlanPlugin


class Monster(TypedDict):
    name: str
    hp: int
    armour: int


BESTIARY: dict[str, Monster] = {"goblin": {"name": "goblin", "hp": 7, "armour": 15}}


@tool
def look_up_monster(name: str) -> dict[str, object]:
    """Look up a monster's stat block.

    Args:
        name: Monster name, e.g. "goblin".

    Returns:
        An object shaped {"name": str, "hp": int, "armour": int}.
    """
    return dict(BESTIARY[name.lower()])


@tool
def roll_attack(armour: int) -> dict[str, object]:
    """Roll an attack against an armour value.

    Args:
        armour: The target's armour, from look_up_monster's "armour" field.

    Returns:
        An object shaped {"roll": int, "hits": bool, "damage": int}.
    """
    roll = 18
    return {"roll": roll, "hits": roll >= armour, "damage": 6 if roll >= armour else 0}


@tool
def apply_damage(monster: str, damage: int) -> dict[str, object]:
    """Apply damage to a monster.

    Args:
        monster: Monster name, from look_up_monster's "name" field.
        damage: Damage dealt, from roll_attack's "damage" field.

    Returns:
        An object shaped {"hp_after": int, "defeated": bool}.
    """
    hp_after = max(BESTIARY[monster.lower()]["hp"] - damage, 0)
    return {"hp_after": hp_after, "defeated": hp_after == 0}


agent = Agent(
    system_prompt=(
        "You are a Game Master for a tabletop role-playing game.\n\n"
        "You have a submit_workflow_plan tool. When you already know which tools to call "
        "and each call's arguments come from an earlier call's result, submit one plan "
        "instead of calling the tools one at a time. Each step's `bind` maps an argument "
        'to a JSONata expression over {"steps": {<id>: <result>}}, for example '
        '{"armour": "steps.monster.armour"}. Read each tool\'s documented return shape.'
    ),
    tools=[look_up_monster, roll_attack, apply_damage],
    plugins=[WorkflowPlanPlugin()],
)

response = agent("The mage attacks the goblin. Resolve the attack and tell me the outcome.")

print(response.message["content"][0]["text"])
print(f"model round trips: {response.metrics.cycle_count}  (a plain loop needs 4)")
Tool #1: submit_workflow_plan

{"lookup": {"name": "goblin", "hp": 7, "armour": 15},
 "attack": {"roll": 18, "hits": true, "damage": 6},
 "damage": {"hp_after": 1, "defeated": false}}
model round trips: 1  (a plain loop needs 4)
One tool call. Three tools ran. You wrote no plan — the model did.
The integration is the two lines you already saw: import WorkflowPlanPlugin, pass it in
plugins=. Tool choice stays automatic, so the model plans when it helps and ignores the
tool when it does not.
Three things to know
1. Document your tools' return shapes. Tool schemas describe inputs only. A model
binding to steps.lookup.ac when your field is armour is your docstring's fault, not the
model's — so every tool above ends with a Returns: line naming the exact shape. This is the
single biggest factor in whether plans work for you.
2. Tell the model when to plan. One paragraph in the system prompt, as above. Without it the model usually keeps calling tools one at a time — not wrong, just slower.
3. A final plan ends the turn, so the answer is JSON. The model marked its plan final,
meaning its results are the answer, so the turn ended there instead of sampling the model
again to restate them. That is the round trip you saved. It also means the final message is
appended rather than streamed, which is why the example prints it explicitly. Want prose?
WorkflowPlanPlugin(honor_final=False) — one more round trip, nicer output.
Also expect the JSON keys to vary: lookup and attack are step ids the model chose. Three
runs of this exact example produced lookup, monster and goblin_stats for the first step.
The values are stable; the names are its own.
When not to bother
| Shape | Plan? |
|---|---|
| One tool call | No — the plan schema costs more tokens than it saves |
| Two or more mechanically dependent calls | Yes — this is the point |
| A lookup, then a fan-out over its results | Yes — the most common winning shape |
| Independent calls in one turn | No — already concurrent in the agent loop |
| Each result needs your judgement before the next | No — call them one at a time |
Break-even is depth 2.
Judgement inside a plan
That last row has a way around it. When the judgement is a narrow, rote one (pick a desk, yes or no, a score on a rubric), wrap it in a tool backed by a small decision model such as strands-decider. It is a normal tool, so the plan does not know a model is behind it, and the chain becomes mechanical again:
{"steps": [
  {"id": "ticket", "tool": "read_ticket",   "args": {"ticket_id": 7}},
  {"id": "triage", "tool": "triage_ticket", "bind": {"text": "steps.ticket.text"}},
  {"id": "route",  "tool": "route_ticket",  "bind": {"ticket_id": "steps.ticket.id",
                                                     "desk": "steps.triage.desk",
                                                     "urgent": "steps.triage.urgent"}}
 ], "returns": ["route"], "final": true}
triage_ticket asks strands-decider which desk owns the ticket and whether it is urgent, and
returns {"desk": str, "confidence": float, "urgent": bool}. On Claude Sonnet 4.6 the plan
took 1 round trip in 2.3 to 3.0 s; the same chain with the LLM making the triage decision took
3 round trips in 5.4 to 6.0 s (three runs each, decider served locally on Apple silicon at
146 to 245 ms per warm call). Keep the confidence in the return shape: it is what you branch
on to hand a borderline ticket to a person.
To act on the answer, give a step a when: a JSONata condition that must evaluate to true
or false. A false when marks the step not_taken and prunes everything downstream of it,
so two steps with opposite conditions form a branch decided inside the plan:
{"steps": [
  {"id": "ticket",   "tool": "read_ticket",       "args": {"ticket_id": 7}},
  {"id": "triage",   "tool": "triage_ticket",     "bind": {"text": "steps.ticket.text"}},
  {"id": "refund",   "tool": "refund_payment",    "bind": {"ticket_id": "steps.ticket.id"},
   "when": "steps.triage.desk = \"treasury\" and steps.triage.confidence >= 0.8"},
  {"id": "escalate", "tool": "escalate_to_human", "bind": {"ticket_id": "steps.ticket.id"},
   "when": "$not(steps.triage.desk = \"treasury\" and steps.triage.confidence >= 0.8)"}
 ], "returns": ["refund", "escalate"], "final": true}
The ticket scores 0.54 for treasury, so escalate runs and refund is not_taken, with no
model call in between. On Claude Sonnet 4.6 with the real decider, the model wrote this shape
in 21 runs out of 21: 1 round trip each time, exactly one side effect, the right branch at both
thresholds tried (0.5 refunds, 0.8 escalates). Without when, one run in six planned the
refund and the escalation unconditionally, and both ran. A final plan with a branch not
taken still ends the turn.
Three JSONata details that bite in conditions:
- There is no
notor!operator. Negate with$not(...), or write the opposite comparison. - Equality is
=, not==.!=,and,orandinwork as you would expect. - A misspelled field matches nothing, and
$notof nothing is still nothing. The step fails with "matched no value" instead of guessing, so neither side of a branch runs.
A step that binds to both sides of a branch is always not_taken, because one of its inputs
never arrives. Join after a branch with a direct call for now.
Measured
Bedrock, global.anthropic.claude-sonnet-4-6 in eu-central-1, 2026-09-29. Same model,
tools and prompt in both arms; each tool sleeps 250ms so the gap is attributable to round
trips, not tool speed. Medians of 5 trials.
depth |            loop            |            plan            | verdict
      |  wall   trips   tokens     |  wall   trips   tokens  pl%|
------+----------------------------+----------------------------+---------------
  1   |  3.79s   2.0     1358    |  3.35s   1.0     1819 100| plan +11%
  2   |  6.83s   3.0     2595    |  2.56s   1.0     1983 100| plan +63%
  3   |  9.43s   4.0     3983    |  3.21s   1.0     2133 100| plan +66%
  4   |  9.22s   5.0     5687    |  4.05s   1.0     2296 100| plan +56%
  5   | 18.94s   6.0     8269    |  5.93s   2.0     4752 100| plan +69%
The loop's round trips grow with depth; the plan's stay at 1 through depth 4. At depth 5 the
model often reads the first result itself, then hands over the rest as one plan — 2 round
trips, still under a third of the wall clock. At depth 1 the model planned every time; the
plan schema costs more tokens than it saves there, and the wall-clock gain is within noise.
Reproduce with
AWS_PROFILE=... AWS_REGION=... uv run python -m bench.breakeven --model global.anthropic.claude-sonnet-4-6 --trials 5.
Safety
JSONata is a query language: no imports, no filesystem, no network, no subprocess. Its one
dynamic surface is $eval — which evaluates further JSONata, never Python — and it is off by
default, so a plan's bindings can be read completely before anything runs.
Cycles, duplicate ids, dangling references and step-count overruns are rejected before any
tool runs, so a bad plan costs one cheap repair round trip and leaves no side effects. A
binding that fails is a step failure, never a silently substituted None.
Approval-gated tools cannot be planned. A direct tool call refuses interrupts, so such a
tool is rejected at validation and the model is told to call it directly — the gate keeps
working, it just is not batchable. If your agent has interventions attached, name what is safe
to batch: WorkflowPlanPlugin(plannable=["*", "!delete_files"]). Leave it out and
construction fails loudly rather than silently skipping a human approval.
Going further
A bigger shape — one RPG combat round for three players, in examples/rpg.py:
L0  read_action_log                      1 step
L1  get_character   x3   (fan-out)       3 steps
L2  roll_check      x3                   3 steps
L3  resolve_action  x3                   3 steps
L4  tally_round          (join, in-degree 3)
L5  narrate_round
uv run python -m examples.game_master          # offline, deterministic
uv run python -m examples.game_master --live   # the model writes its own plan
Twelve steps, depth 6, three wide, and ten of the twelve results never reach the model. The
join is where JSONata beats a path syntax: tally_round wants one array of damages living in
three different steps, so a binding builds it inline —
{"damages": "[steps.a.damage, steps.b.damage, steps.c.damage]"}. No glue tool, no extra
round trip.
Run it --live and the model does something worth seeing: it calls read_action_log
directly first, because it cannot know how many characters to fetch until it has seen the
actions, then plans the eleven mechanical steps that follow. It uses the loop where judgement
is needed and the plan where it is not.
You can also drive the engine without an agent at all — execute_plan(plan, invoker) takes
any async (name, args) -> result callable, which is how the tests and the offline example
run with no model and no credentials.
Development
Tool invocation sits behind a ToolInvoker protocol, so the engine imports no agent
framework — steps run in-process with no hop to the model provider between them. Ordering is
Kahn's algorithm over in-degree counts and execution is barrier-free: each step starts the
instant its own dependencies land, so wall clock tracks the critical path.
uv sync --extra dev
uv run ruff check . && uv run ruff format --check .
uv run mypy src tests examples bench demo.py demo_bedrock.py
uv run pytest -q
MIT licensed.
1 maintainer

Metadata
1 maintainer
Release files for strands-plan-tool 0.4.0
For a detailed explanation of source distributions (sdists) and built distributions (wheels), please see the package formats documentation.
Source distribution (sdist)
| File | Size | Uploaded | |
|---|---|---|---|
| strands_plan_tool-0.4.0.tar.gz | 421.3 kB | Details |
Built distribution (wheel)
| File | Interpreter | ABI | Platform | Reset |
|---|---|---|---|---|
| strands_plan_tool-0.4.0-py3-none-any.whl | Python 3 | none | any | Details |
Total release size: 449.5 kB
Release files / strands_plan_tool-0.4.0.tar.gz
| Download URL | strands_plan_tool-0.4.0.tar.gz |
|---|---|
| Size | 421.3 kB |
| Tags | Source |
|
SHA-256 checksum How to use checksums |
c1882aed82d358329507e9f924700c3d3abaad1dcb3e47a55d655899f54b5d76
|
|
BLAKE2b-256 checksum How to use checksums |
dcb6bae0ce56dc853cddbe52367498b7213ff7571d2bf32b9db1c0a48d0ea331
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
Yes |
| Uploaded via |
uv/0.12.23 {"installer":{"name":"uv","version":"0.12.23","subcommand":["publish"]},"python":null,"implementation":{"name":null,"version":null},"distro":{"name":"Ubuntu","version":"24.04","id":"noble","libc":null},"system":{"name":null,"release":null},"cpu":null,"openssl_version":null,"setuptools_version":null,"rustc_version":null,"ci":true}
|
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.


PyPI Publish Attestation
PyPI verified that this artifact, at this checksum, originated from the publisher listed below.
Signed by GitHub Actions, verified by PyPI on Oct 5, 2026.
Transparency logRelease files / strands_plan_tool-0.4.0-py3-none-any.whl
| Download URL | strands_plan_tool-0.4.0-py3-none-any.whl |
|---|---|
| Size | 28.2 kB |
| Tags | Python 3 |
|
SHA-256 checksum How to use checksums |
957ccc5124fef2d1ad314407b0ad2ef0b4a42ce1c3e90142d9d8a403d24287ca
|
|
BLAKE2b-256 checksum How to use checksums |
03b7c8acda159c4164d0050313b073e51fbf2136913ff5d05e4aba652f4e19ad
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
Yes |
| Uploaded via |
uv/0.12.23 {"installer":{"name":"uv","version":"0.12.23","subcommand":["publish"]},"python":null,"implementation":{"name":null,"version":null},"distro":{"name":"Ubuntu","version":"24.04","id":"noble","libc":null},"system":{"name":null,"release":null},"cpu":null,"openssl_version":null,"setuptools_version":null,"rustc_version":null,"ci":true}
|
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.
PyPI Publish Attestation
PyPI verified that this artifact, at this checksum, originated from the publisher listed below.
Signed by GitHub Actions, verified by PyPI on Oct 5, 2026.
Transparency log













