
superPDF AI for Python (superpdf)

superpdf.ai · Python docs · GitHub · Changelog
Read, convert, edit and compare PDFs on your computer: Markdown, HTML or JSON with headings, tables, charts as data and OCR for scanned pages; Word, PowerPoint, Excel and EPUB; forms, signatures, merging and splitting. Nothing is uploaded.
This package is a thin Python wrapper around the superPDF command-line tool
(npm package @superpdf/cli), so you get exactly what superpdf export produces. Every superPDF tool is a typed
Python function (Word, PowerPoint and EPUB export, tables to Excel or CSV, forms, merge, split, rotate, page
numbers, watermark, protect, compare, Office to PDF, pipelines and batches), and it includes a LangChain document loader and a LlamaIndex reader.
Requirements
Python 3.10 or later on macOS, Linux or Windows. Nothing else: Node.js comes with the package through
nodejs-wheel-binaries.
The first call installs the superPDF reader (@superpdf/cli, about 220 MB with its PDF engine and OCR language
data) from npm into your cache folder, once. To do that ahead of time, for example in a Docker image or before going offline:
python -c "import superpdf; superpdf.install_cli()"
Install
pip install superpdf
pip install "superpdf[langchain]"      # with the LangChain loader
pip install "superpdf[llama-index]"    # with the LlamaIndex reader
uv add superpdf                        # in a uv project
Or run the command without installing anything:
uvx superpdf export report.pdf --output report.md
pipx run superpdf export report.pdf --output report.md
Use
import superpdf

markdown = superpdf.export("report.pdf")  # the whole document as Markdown
html = superpdf.export("report.pdf", "html")
structure = superpdf.export_json("report.pdf")  # pages, blocks with type and position, sections

for page in superpdf.export_pages("report.pdf"):  # Markdown per page
    print(page["page"], page["markdown"][:80])

superpdf.export("report.pdf", pages="1,3-5", tables="html", ocr=False)
| Option | Meaning |
|---|---|
format |
"markdown" (default), "html" or "json" |
pages |
A selection such as "1,3-5"; all pages when omitted |
tables |
"html" writes Markdown tables as HTML, keeping merged header cells (Markdown only) |
ocr |
True (default) reads scanned pages with OCR in 15 languages; False skips it |
timeout |
Seconds before giving up (default 600) |
Errors raise superpdf.SuperPDFError with superPDF's own message, for example No file at report.pdf.
Every PDF tool
Every superPDF tool is a Python function: the same 30 tools as the MCP server and the local API, with the same validation and results. Each returns a typed dict; outputs are always new files (an existing file is never overwritten), and a call only touches the folders of the files you give it.
import superpdf

superpdf.merge(["a.pdf", "b.pdf"], "combined.pdf")  # {"output": ..., "pages": 7, "bytes": ...}
superpdf.extract_pages("report.pdf", "1, 3-5", "selected.pdf")
superpdf.rotate_pages("scan.pdf", "upright.pdf", pages="2", angle=180)
superpdf.split("book.pdf", "chapters/", pages="1-10, 11-20")  # one PDF per range
superpdf.add_page_labels("report.pdf", "numbered.pdf", text="Page {page} of {total}")
superpdf.add_watermark("contract.pdf", "DRAFT", "draft.pdf")
superpdf.protect("payslip.pdf", "a long password", "locked.pdf")  # AES-256
superpdf.unlock("locked.pdf", "open.pdf", password="a long password")
superpdf.from_office("slides.pptx", "slides.pdf")  # needs LibreOffice

superpdf.to_docx("report.pdf", "report.docx")  # editable Word: headings, lists, tables
superpdf.extract_tables("report.pdf", "tables.xlsx")  # or tables.csv with format="csv"
superpdf.fill_form("form.pdf", {"Name": "Ada Lovelace", "Agree": True}, "filled.pdf")
superpdf.add_text("contract.pdf", "Signed: Ada Lovelace", "signed.pdf", pages="3", x=72, y=96)
changes = superpdf.compare("v1.pdf", "v2.pdf")  # per page: same, changed, added or removed

info = superpdf.info("report.pdf")  # pages, sizes, form fields, properties
text = superpdf.read_text("report.pdf", pages="1-2")  # the text layer, page by page
| Function | What it does | Returns |
|---|---|---|
info(path) |
Page count, page sizes and rotation, form fields, properties | PdfInfo |
list_files(folder=".") |
The PDFs in a folder | Folder |
read_text(path, pages=, max_chars=) |
The text layer, page by page | Text |
extract_structure(path, pages=, format=, max_chars=) |
Markdown, HTML or JSON plus the outline; OCR for scans | Structure |
merge(inputs, output) |
Combine PDFs in order | Written |
extract_pages(path, pages, output) |
Keep only some pages | Written |
remove_pages(path, pages, output) |
Drop pages | Written |
rotate_pages(path, output, pages=, angle=90|180|270) |
Rotate clockwise | Written |
split(path, output_folder, pages=, mode="ranges"|"pages") |
One PDF per range or per page | SplitResult |
add_page_labels(path, output, pages=, text="{page} / {total}", position="bottom"|"top") |
Page numbers, a footer or a header | Written |
add_watermark(path, text, output, pages=) |
Stamp text such as DRAFT diagonally | Written |
remove_metadata(path, output) |
Strip document properties | Written |
repair(path, output) |
Rebuild a damaged PDF | RepairResult |
protect(path, password, output) |
Encrypt with AES-256 | Written |
unlock(path, output, password=) |
Decrypt with a password you know | Written |
from_office(path, output) |
Word, Excel, PowerPoint or OpenDocument to PDF (LibreOffice) | OfficeResult |
add_text(path, text, output, pages=, x=36, y=36, size=12) |
Draw text such as a typed signature (points from bottom-left) | Written |
resize_pages(path, output, mode="crop"|"scale", pages=, margin=24, factor=1) |
Crop a margin from each edge, or scale | Written |
fill_form(path, values, output, flatten=False) |
Fill form fields by name (info lists them) |
Written |
flatten(path, output) |
Make form fields part of the page | Written |
to_docx(path, output, pages=) |
Editable Word: headings, bold and italic, lists, tables; OCR for scans | WordResult |
to_pptx(path, output, pages=) |
PowerPoint, one slide per page, text as text boxes | SlidesResult |
to_epub(path, output, title=, author=, language="en", split="headings"|"pages") |
EPUB 3 e-book in chapters | EpubResult |
extract_tables(path, output, pages=, format="xlsx"|"csv"|"json"|"markdown") |
Tables and vector charts; output ends in the format's extension |
TablesResult |
from_images(inputs, output) |
JPG or PNG images to PDF, one page each | Written |
from_markdown(path, output, page_size="A4"|"Letter", title=) |
Typeset a Markdown file as a PDF | Written |
compare(before, after, max_chars=20000) |
The words that changed, page by page, marked [-old-] and {+new+} |
Comparison |
outline(path, format="markdown"|"json") |
The outline, with the pages each section covers | Outline |
run_pipeline(path, steps, output) |
Up to 10 steps on one PDF, saved once | Written |
run_batch(inputs, steps, output_folder, suffix=) |
The same steps on up to 50 PDFs; failures listed, not raised | BatchResult |
pages takes numbers and ranges such as "1, 3-5". Pipeline and batch steps are dicts such as
{"action": "rotate", "options": {"pages": "1", "angle": 90}}; the actions are extract, remove, rotate, crop
(margin), scale (factor), flatten, labels, watermark and metadata-clear.
superpdf.tools() lists every tool with its JSON input schema, and superpdf.run_tool(name, arguments, allow=[...])
runs any of them by name, for tools added to the CLI before this package catches up.
LangChain
from superpdf.langchain import SuperPDFLoader

docs = SuperPDFLoader("report.pdf").load()  # one Document per page
docs[0].metadata  # {"source": "report.pdf", "page": 1}
LlamaIndex
from superpdf.llama_index import SuperPDFReader

docs = SuperPDFReader(tables="html").load_data("report.pdf")  # one Document per page
Command line
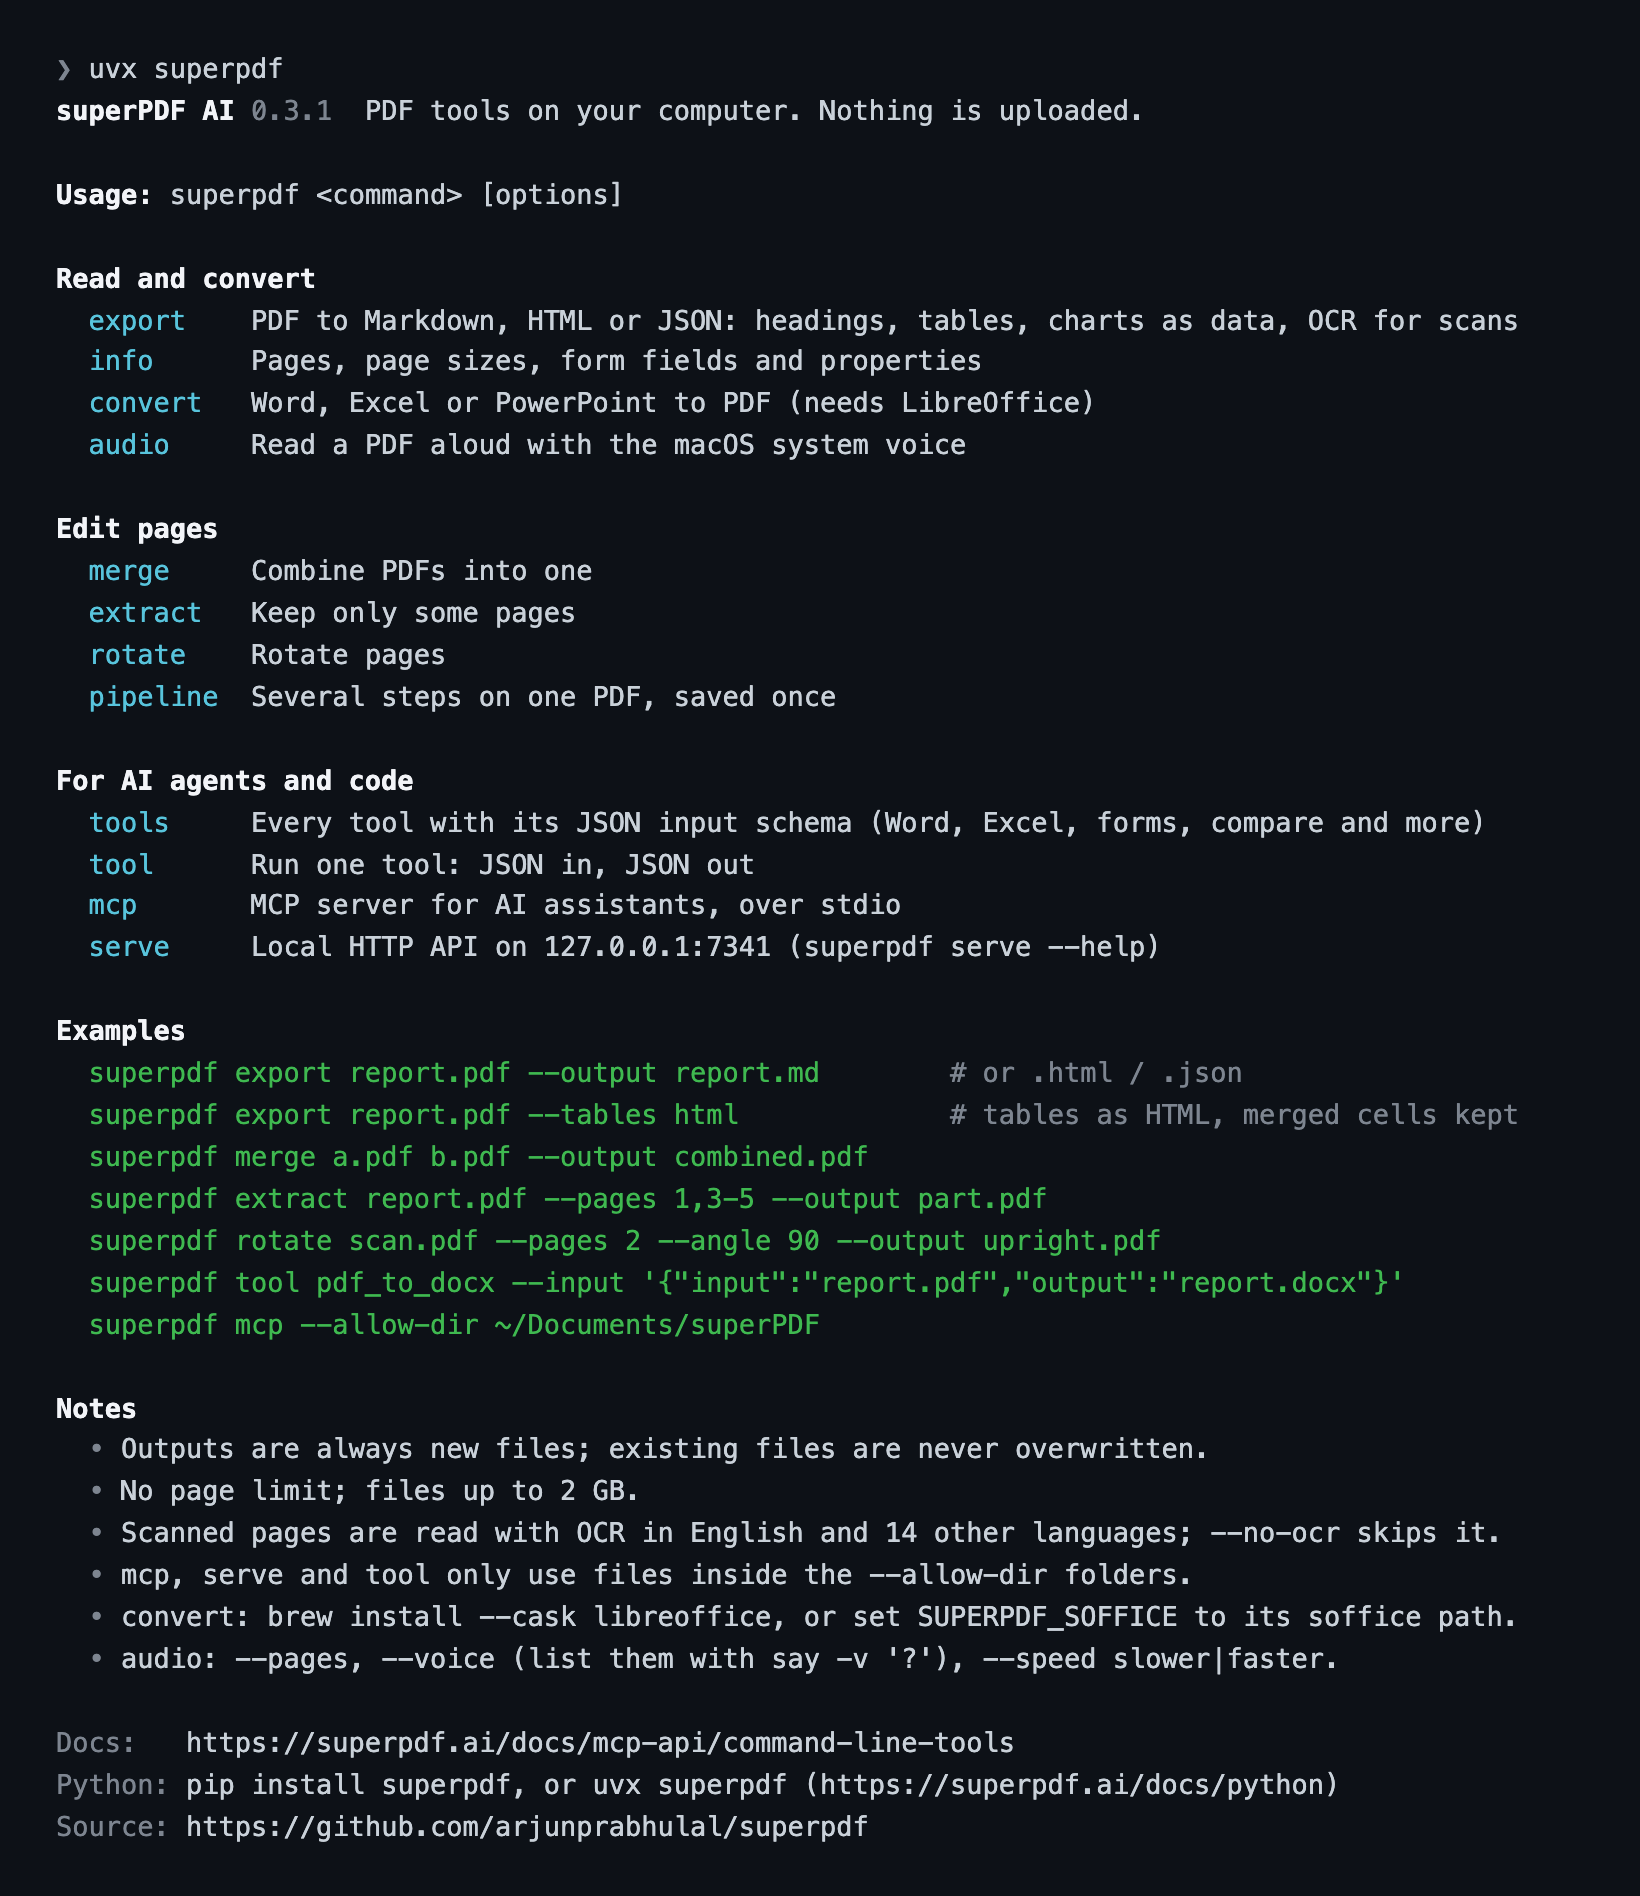
The package installs a superpdf command that runs the full CLI (the same as python -m superpdf):
superpdf export report.pdf --output report.md
superpdf export report.pdf --tables html --output report.md
superpdf help
uvx superpdf … and pipx run superpdf … run it in a temporary environment, with nothing to install first.
How it works
Each call runs superpdf export in a subprocess (no shell) with the bundled Node.js and reads its output as UTF-8.
The reader is @superpdf/cli at the version this package is tested with, installed once into your cache folder:
~/Library/Caches/superpdf on macOS, ~/.cache/superpdf on Linux and %LOCALAPPDATA%\superpdf\Cache on Windows
(set SUPERPDF_CACHE_DIR to change it). To use your own build instead, set SUPERPDF_BIN to a superpdf command or
superpdf.js. The reader, its tables, charts and OCR are described in the
main README.
License
1 maintainer

Metadata
1 maintainer
Release files for superpdf 0.3.1
For a detailed explanation of source distributions (sdists) and built distributions (wheels), please see the package formats documentation.
Source distribution (sdist)
| File | Size | Uploaded | |
|---|---|---|---|
| superpdf-0.3.1.tar.gz | 26.2 kB | Details |
Built distribution (wheel)
| File | Interpreter | ABI | Platform | Reset |
|---|---|---|---|---|
| superpdf-0.3.1-py3-none-any.whl | Python 3 | none | any | Details |
Total release size: 47.5 kB
Release files / superpdf-0.3.1.tar.gz
| Download URL | superpdf-0.3.1.tar.gz |
|---|---|
| Size | 26.2 kB |
| Tags | Source |
|
SHA-256 checksum How to use checksums |
5252db835335b7a79defec5b37339e9e6a6446d9f8a40247a305fb9783d1785a
|
|
BLAKE2b-256 checksum How to use checksums |
c1ce385332f224a4796f6e4f03725ef698dd02666e6f91e2d4dbd46f1f77d100
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
Yes |
| Uploaded via |
twine/7.0.0 CPython/3.13.14
|
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.


PyPI Publish Attestation
PyPI verified that this artifact, at this checksum, originated from the publisher listed below.
Signed by GitHub Actions, verified by PyPI on Oct 14, 2026.
Transparency logRelease files / superpdf-0.3.1-py3-none-any.whl
| Download URL | superpdf-0.3.1-py3-none-any.whl |
|---|---|
| Size | 21.4 kB |
| Tags | Python 3 |
|
SHA-256 checksum How to use checksums |
80aea520d41539e21b8835dd5764a273d93424074c50faf4d51cdc7bce42f3f2
|
|
BLAKE2b-256 checksum How to use checksums |
e23187f834e9f2f0d19a886751d59fd286cebf42bc9c9480c34f5f2942f31fc6
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
Yes |
| Uploaded via |
twine/7.0.0 CPython/3.13.14
|
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.
PyPI Publish Attestation
PyPI verified that this artifact, at this checksum, originated from the publisher listed below.
Signed by GitHub Actions, verified by PyPI on Oct 14, 2026.
Transparency log













