
SwarmCore


Multi-agent orchestration for Python. Compose AI agents into sequential and parallel flows with automatic context sharing.
Installation
pip install swarmcore
Quickstart
import asyncio
from swarmcore import Swarm, researcher, writer

result = asyncio.run(Swarm(flow=researcher() >> writer()).run("AI agent trends in 2025"))
print(result.output)
The default model is anthropic/claude-opus-4-6 (requires ANTHROPIC_API_KEY). To use Google Gemini's free tier instead:
flow = researcher(model="gemini/gemini-2.5-flash") >> writer(model="gemini/gemini-2.5-flash")
result = asyncio.run(Swarm(flow=flow).run("AI agent trends in 2025"))
Features
- Agent factories — pre-built
researcher,analyst,writer,editor, andsummarizerwith sensible defaults - Flow operators —
>>for sequential,|for parallel, compose freely - Automatic context — each agent receives prior outputs automatically, with smart summarization
- Any model — works with any LiteLLM-compatible provider (Anthropic, OpenAI, Gemini, Groq, Ollama, etc.)
- Tool calling — pass plain Python functions as tools, sync or async
- Observability — built-in
console_hooks()for live progress, or wire up custom event hooks
Agent factories
Pre-built factories for common workflow roles. Zero-config defaults for prototyping, full override for production.
from swarmcore import researcher, analyst, writer, editor, summarizer
| Factory | Default tools | Role |
|---|---|---|
researcher() |
search_web |
Gathers information, finds data and sources |
analyst() |
— | Analyzes data, identifies insights and trends |
writer() |
— | Drafts structured content from context |
editor() |
— | Polishes and synthesizes multiple inputs |
summarizer() |
— | Condenses into an executive-level brief |
Every parameter is optional and keyword-only:
# Zero-config
researcher()

# Fine-tuned
researcher(
    name="market_researcher",
    model="openai/gpt-4o",
    instructions="Focus on TAM and competitive landscape.",
    tools=[my_custom_search],   # replaces default search_web
    timeout=30.0,
)
Or build agents from scratch:
from swarmcore import Agent

agent = Agent(name="researcher", instructions="Research the topic.", model="anthropic/claude-opus-4-6")
Flows
>> for sequential, | for parallel:
researcher() >> writer()                            # sequential
(analyst() | writer()) >> editor()                  # parallel then sequential
researcher() >> (analyst() | writer()) >> editor()  # mixed
Parallel groups can contain multi-step sub-flows:
(researcher >> analyst) | (critic >> editor) >> writer
researcher ──► analyst ──┐
                         ├──► writer
critic ──► editor ───────┘
Each branch runs its steps sequentially; branches run concurrently via asyncio.gather.
Functional API:
from swarmcore import chain, parallel

chain(planner, parallel(researcher, critic), writer)
Context management
Each agent in a flow receives context from prior steps automatically:
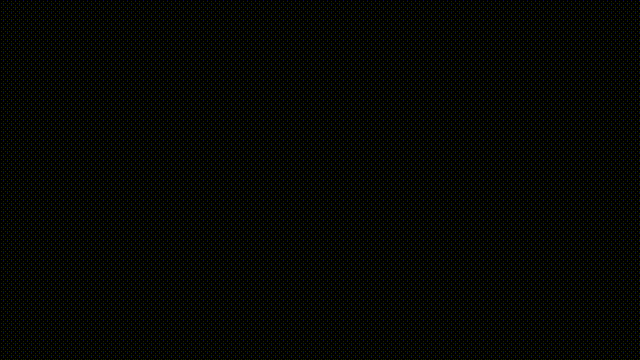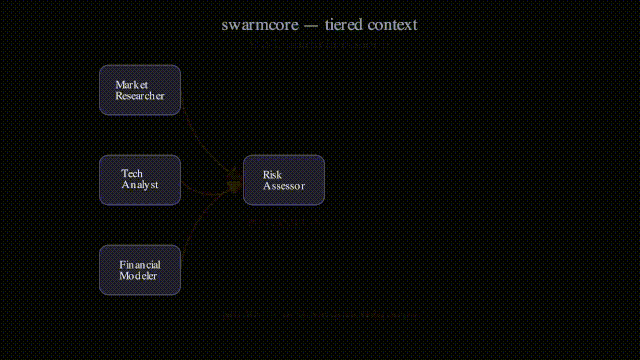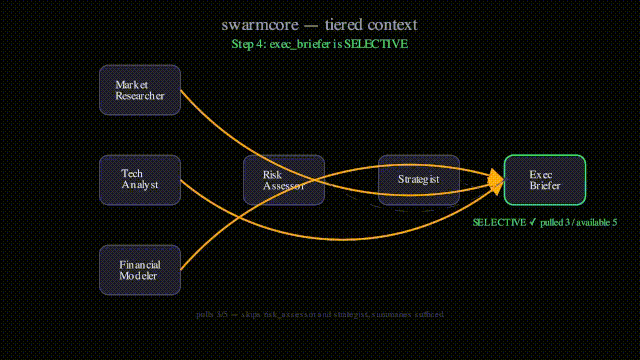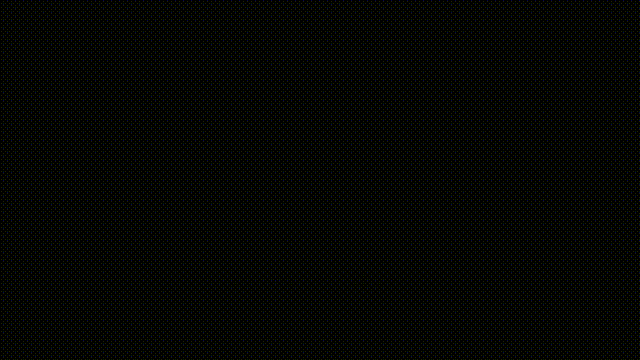
- Previous step — full output
- Earlier steps — summaries only
- On demand — agents call
expand_contextto retrieve any prior agent's full output
agent_1 >> agent_2 >> ... >> agent_10

agent_10 sees: agents 1-8 [SUMMARIES] + agent_9 [FULL]
               (can expand any earlier agent on demand)
Agents produce summaries via <summary> tags in their output. If omitted, the full output is used as both.
Tools
Tools are plain Python functions. Type hints and docstrings are converted to tool schemas automatically.
def search_web(query: str) -> str:
    """Search the web for information."""
    return results

agent = Agent(name="researcher", instructions="...", tools=[search_web])
Sync and async functions both work.
Models
Any LiteLLM-compatible model. Set the API key for your provider:
export ANTHROPIC_API_KEY=sk-...    # for anthropic/ models (default)
export GEMINI_API_KEY=...          # for gemini/ models (free tier available)
export OPENAI_API_KEY=sk-...       # for openai/ models
researcher(model="anthropic/claude-opus-4-6")    # default
researcher(model="gemini/gemini-2.5-flash")      # free tier, no credit card needed
researcher(model="openai/gpt-4o")
researcher(model="groq/llama-3.1-8b-instant")
researcher(model="ollama/llama3")                # local, no API key needed
Example: single agent vs. multi-agent flow
Both outputs below use the same model and prompt — the difference is orchestration.
Evaluate the opportunity for launching an AI-powered personal nutrition coach app that uses computer vision to analyze meals and provides real-time dietary recommendations.
Single agent — high-level strategic assessment
The opportunity for an AI-powered personal nutrition coach targeting health-conscious US millennials is compelling, driven by high smartphone usage, strong interest in personalized wellness, and frustration with manual calorie tracking. Computer vision–based meal analysis directly addresses a major pain point by reducing friction, while real-time dietary feedback aligns well with millennials' preference for on-demand, data-driven guidance integrated into daily life.
That said, the market is competitive and execution-sensitive: differentiation will require demonstrably accurate food recognition, culturally diverse meal coverage, and actionable recommendations that go beyond basic calorie counts. Trust will be critical, making privacy safeguards, transparent AI limitations, and careful positioning to avoid medical claims essential, alongside a clear monetization strategy (e.g., premium personalization or partnerships with fitness and health platforms).
Five-agent flow — market sizing, unit economics, go-to-market strategy
The opportunity is meaningful if we position this as frictionless meal logging plus actionable micro-coaching, not "perfect" automated nutrition. The US mHealth apps market is estimated at ~$12.75B (2024), and meal occasions are increasingly "trackable" (Circana reports 86% of eating occasions are sourced from home), creating high usage frequency for a camera-first workflow. Strategically, we should launch with a hybrid CV + user-confirmation experience (detect items, then prompt 1–2 quick portion inputs) and focus differentiation on (1) speed/low-friction capture, (2) trustworthy, goal-based recommendations, and (3) privacy-first handling of images. MVP is technically feasible in ~4–6 months using pretrained vision + a constrained food ontology + human-in-the-loop QA; true defensibility likely requires 9–18 months of data collection, model tuning, and nutrition governance.
Key risks are (a) portion estimation accuracy (single-photo volume inference is unreliable), (b) trust/privacy (food photos can reveal sensitive context), and (c) regulatory/claims creep—we must stay clearly on the "wellness" side of FDA medical-device boundaries. Financially, a base-case model supports attractive unit economics: by Year 3 ~32k paying subscribers at $17.99/mo can drive ~$5–6M revenue, with ~74% gross margin, blended CAC ~ $52, and LTV:CAC ~4.1x. Estimated break-even ~month 20–22 with ~$2.6M upfront/early operating investment, contingent on holding paid churn ≲6% and maintaining recommendation quality to prevent post-novelty attrition.
API reference
Agent(name, instructions, model, tools, timeout, max_retries, max_turns)
| Param | Type | Default | Description |
|---|---|---|---|
name |
str |
required | Identifier used in context keys |
instructions |
str |
required | System prompt |
model |
str |
"anthropic/claude-opus-4-6" |
LiteLLM model string |
tools |
list[Callable] |
None |
Tool functions |
timeout |
float | None |
None |
Per-agent LLM call timeout in seconds |
max_retries |
int | None |
None |
Per-agent LLM retry count |
max_turns |
int | None |
None |
Max tool-calling loop iterations |
Swarm(flow, hooks, timeout, max_retries)
| Param | Type | Default | Description |
|---|---|---|---|
flow |
Flow |
required | Execution plan from operators or chain()/parallel() |
hooks |
Hooks | None |
None |
Event hooks (e.g. console_hooks()) |
timeout |
float | None |
None |
Default timeout for all agents |
max_retries |
int | None |
None |
Default retry count for all agents |
SwarmResult
| Field | Type | Description |
|---|---|---|
output |
str |
Final agent's output |
context |
dict[str, str] |
All outputs keyed by agent name |
history |
list[AgentResult] |
Ordered execution results |
AgentResult
| Field | Type | Description |
|---|---|---|
agent_name |
str |
Agent that produced this result |
output |
str |
Text output (summary tags stripped) |
summary |
str |
Summary from <summary> tags, or full output |
model |
str |
Model used |
duration_seconds |
float |
Wall-clock time |
token_usage |
TokenUsage |
Token counts |
License
MIT
1 maintainer

Metadata
1 maintainer
Release files for swarmcore 0.3.1
For a detailed explanation of source distributions (sdists) and built distributions (wheels), please see the package formats documentation.
Source distribution (sdist)
| File | Size | Uploaded | Provenance | |
|---|---|---|---|---|
| swarmcore-0.3.1.tar.gz | 23.2 kB | With provenance | Details |
Built distribution (wheel)
| File | Interpreter | ABI | Platform | Reset |
|---|---|---|---|---|
| swarmcore-0.3.1-py3-none-any.whl | Python 3 | none | any | Details |
Total release size: 51.9 kB
Release files / swarmcore-0.3.1.tar.gz
| Download URL | swarmcore-0.3.1.tar.gz |
|---|---|
| Size | 23.2 kB |
| Tags | Source |
|
SHA-256 checksum How to use checksums |
2be83463a0884551ac6e3c2be168cd528f62dcc4ab4619657e9c7619fa543b5e
|
|
BLAKE2b-256 checksum How to use checksums |
37b3047584bf00666bae4c2b2bcc707fd8e55e954afdd6c51856ad52b3f97566
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
Yes |
| Uploaded via |
twine/6.1.0 CPython/3.13.7
|
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.


PyPI Publish Attestation
PyPI verified that this artifact, at this checksum, originated from the publisher listed below.
Signed by GitHub Actions, verified by PyPI on Feb 12, 2026.
Transparency logRelease files / swarmcore-0.3.1-py3-none-any.whl
| Download URL | swarmcore-0.3.1-py3-none-any.whl |
|---|---|
| Size | 28.7 kB |
| Tags | Python 3 |
|
SHA-256 checksum How to use checksums |
5f2ae3809bfe1753fb8a21667d2b16f88e2aaa90d6b3012e08fb18d887a95325
|
|
BLAKE2b-256 checksum How to use checksums |
fadc4115b36eac6877e6e38eb492f9bf649eea8983300b01df31dd37bb67f279
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
Yes |
| Uploaded via |
twine/6.1.0 CPython/3.13.7
|
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.
PyPI Publish Attestation
PyPI verified that this artifact, at this checksum, originated from the publisher listed below.
Signed by GitHub Actions, verified by PyPI on Feb 12, 2026.
Transparency logSecurity for swarmcore 0.3.1
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.
Full provenance
All 2 files in this release have been uploaded with provenance metadata.
Attestation for swarmcore-0.3.1.tar.gz
PyPI Publish Attestation
PyPI verified that this artifact, at this checksum, originated from the publisher listed below.
Signed by GitHub Actions, verified by PyPI on Feb 12, 2026.
Transparency logA note on package security
PyPI is a repository for distributing packages, not a service for auditing them. While third-party security researchers and our staff do their best to detect and remove malicious packages, PyPI cannot guarantee the quality, security or suitability of any given package.














