
Taskpenny
Frontier prices only for frontier work.
Taskpenny splits a request only when it expects splitting to pay, gives each task to the cheapest model that does it well, checks every result, and shows you the receipt. Open source, Python, one command to try.



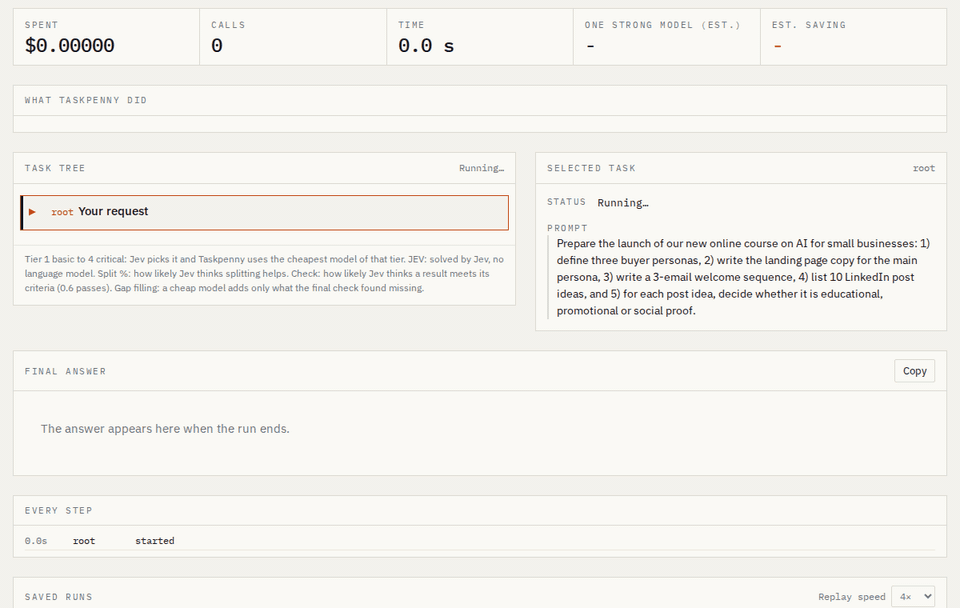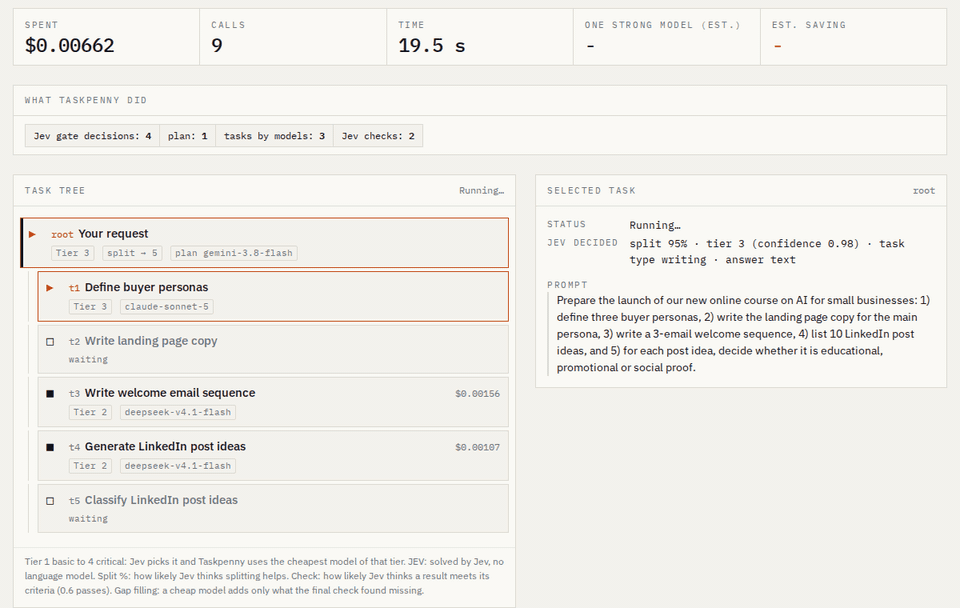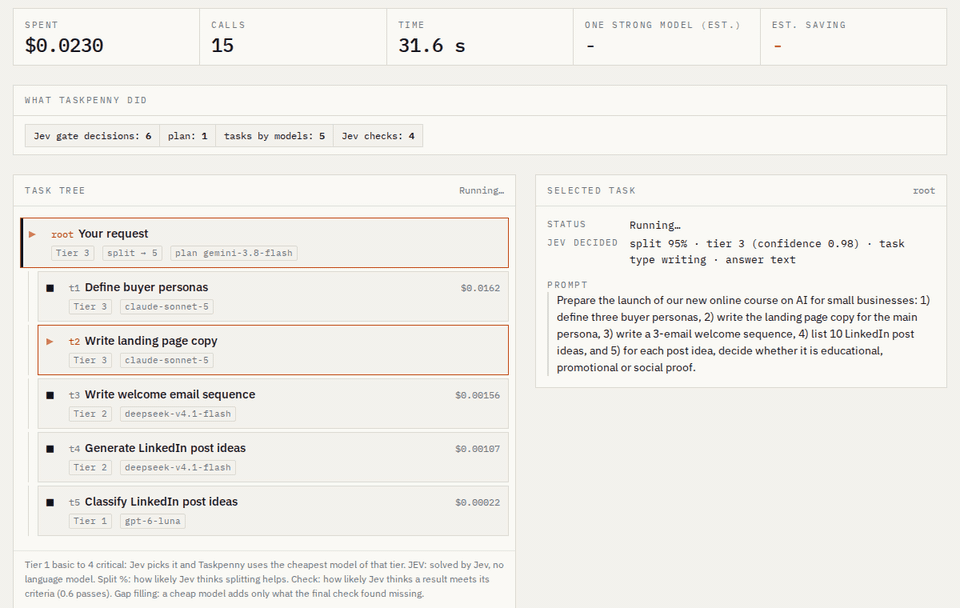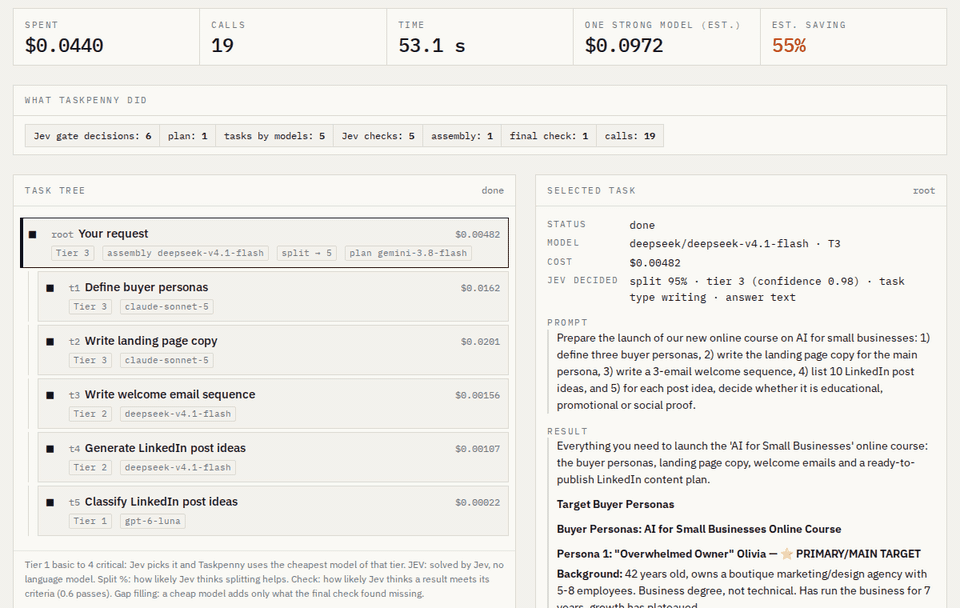
A real run replayed at 4x. Watch it in your browser: live demo (no key, no cost). The saving on the page is the receipt's estimate against Claude Opus 5.5; the benchmark below runs the models it compares with for real.
Measured, not promised
On 50 English tasks Taskpenny had never seen (40 Arena-Hard prompts and 10 requests with four asks each), judged pair by pair by Gemini 3.1 Pro (full report):
| Against | Taskpenny's setup | Taskpenny cost | As good or better |
|---|---|---|---|
| Claude Sonnet 5 alone | Sonnet 5 as its strongest model, on equal footing (same worker instruction and reasoning cap) | 38% less (19 to 56) | 74% (62 to 86): 11 wins, 26 ties, 13 losses |
| Claude Opus 5.5 alone | the default | 78% less (66 to 86) | 50% (35 to 65): 1 win, 23 ties, 24 losses |
The ranges are 95% intervals: fifty tasks give a direction, not a precise figure. What they say:
- Sonnet-class answers for less, on equal footing. Basic and standard tasks cost about a tenth (88% less), as good or better in 77%.
- Most of an Opus bill saved, but not Opus quality on hard prompts. Taskpenny's cheap tiers were judged worse than Opus about half the time; critical tasks go to Opus itself and tied. If every answer must match Opus, Taskpenny is not there yet.
- Labelling customer messages (first benchmark): 95% cheaper than Sonnet 5, same accuracy (96 of 100 on both sides).
Costs are the ones the gateway reported for each call, with Jev at its list price (it was billed in the Opus run and free before; the report has both). Each pair was judged twice with the order swapped, and a tie includes the pairs where the two orders disagreed. The judge prefers longer answers, and Taskpenny's workers are told to show the key steps while the baselines get no instruction; Taskpenny also caps hidden reasoning (off on tiers 1 and 2, low on tiers 3 and 4) while the baselines use each model's default, so part of the saving comes from that setting and not from routing. The control that gives the baseline both the same worker instruction and the same reasoning cap was run on 1 October 2026: on equal footing the saving is 38% (not 52.5%) and Taskpenny is as good or better in 74% (not 82%), which is the headline above. See the full report. The author also voted blind on 20 pairs (as good or better in 18, where the judge said 14), with limits the report spells out.
We publish where Taskpenny loses too: against Opus, in the first full run (only 13% cheaper than Sonnet 5), and in Catalan, our weakest set. It is all in the report.
Try it
pip install taskpenny
taskpenny demo                     # replays a real run in the terminal: no key, no cost
Then give it a key:
export AI_GATEWAY_API_KEY=...      # one Vercel AI Gateway key: Jev decides, and it reaches Claude, GPT and Gemini
taskpenny run "Write a short email to move tomorrow's meeting to Thursday"
taskpenny ui                       # the live task tree in your browser
The Vercel key is required: every decision is Jev's, and Jev is reached through Vercel AI Gateway. Your own OpenAI, Anthropic or Gemini keys can be added next to it; see "Keys" below.
Every run is saved in runs/ as JSON. taskpenny export runs/<id>.json turns one into a Markdown report.
Who it is for
- You send most of your requests to one strong model, and the bill grows with usage.
- Your requests mix easy and hard parts: a summary plus a decision, ten labels plus a reply, a plan plus copy.
- You want to see why each model was chosen and what each step cost.
Who it is not for (yet): if every answer must match Claude Opus on hard prompts (see above), or if your calls are one short classification each, where a per-request router is enough. Tool calling, images and JSON mode are not supported yet; Taskpenny returns a clear error.
How it is different
| Project | What it routes | What Taskpenny adds |
|---|---|---|
| RouteLLM, OpenRouter Auto, Not Diamond, LiteLLM's auto router | A whole request, to one model | It can split a request when the parts go to cheaper models, and Jev checks every result before the answer goes out |
| ROMA | Subtasks, recursively, with a model set for each module | Jev picks the tier of every subtask and the cheapest model of that tier does it; a plan is dropped when splitting would not pay |
| JevRouter | The steps of a plan, with Jev deciding | Taskpenny also does the work, checks it and gives you the cost receipt |
From each project's own README and docs, September 2026. All of them are good at what they do, several report what each request cost, and several can sit next to Taskpenny: it speaks the OpenAI API.
How it works
request
  |
  v
[gate]       Jev: split it? which tier (1-4)? what kind of work? what form of answer?
  |                                   |
  | clearly worth splitting           | one task
  v                                   v
[planner]    subtasks with prompt,  [router]    closed question -> Jev answers it
  success criteria and                         anything else -> cheapest model of the tier
  dependencies; each one goes                  |
  back to the gate                             v
  |                                 [worker]    result + notes for the tasks that depend on it
  |                                            |
  |                                            v
  |                                 [check]     Jev: does it meet the criteria?
  |                                            no -> repair, then one tier up (at most 2)
  v
[assembly]   an outline from a cheap model; the parts are stitched in, not rewritten
  |
  v
[final check] Jev against the request; only what is missing gets written
  |
  v
answer + cost receipt + full task tree
Every decision is a closed question (split or not, which tier, is this good enough), and closed questions are what Jev, TypeSafe AI's decision model, answers well and cheaply. When a request, or a part of a plan, is itself a closed question about texts it gives (label these messages, yes or no for each email, rate each ticket), Jev answers it item by item; the cheapest model only writes the question, and answers the items Jev is unsure about. Jev does not solve problems: maths, code and quiz questions always go to a language model.
Splitting uses more tokens in total. The saving is in money: most tokens go to models that cost a fraction of a frontier model, and Taskpenny drops a plan when the parts would not go to clearly cheaper models (5 of 11 plans in the Sonnet-ceiling run on the 50 new tasks). Details, thresholds and fallbacks: docs/how-it-works.md. Every option and variable: docs/configuration.md.
Reading the live page
- What Taskpenny did: how many Jev decisions, plans, model calls, Jev-solved tasks and checks the run needed.
- Task tree: every task with its tier (1 basic to 4 critical), who did it (a model, or JEV) and what it cost. Click a task to see its prompt, what Jev decided about it, each attempt and its result.
- Warnings: when a result did not pass Jev's check, a check could not run or a part failed, the page says so above the answer, and the task is marked in the tree.
- Cost receipt: planning, work, Jev decisions, checks and assembly add up to the total. The comparison with one strong model (Claude Opus 5.5) is an estimate: the same request sent once, with an answer as long as Taskpenny's, scaled by the hidden reasoning Taskpenny's own models used in that run.
Use it from any tool
taskpenny serve starts an OpenAI-compatible endpoint on http://127.0.0.1:8765/v1, with the live page on the
same address. Change only the base URL:
from openai import OpenAI
client = OpenAI(base_url="http://127.0.0.1:8765/v1", api_key="unused", max_retries=0)  # each call is a paid run
reply = client.chat.completions.create(
    model="taskpenny",             # or "taskpenny/anthropic" to use only Claude models
    messages=[{"role": "user", "content": "Draft a polite reminder for an unpaid invoice."}],
)
print(reply.choices[0].message.content)
print(reply.model_extra["taskpenny"])   # run id, status, warnings, cost in USD, baseline estimate, saving
- Chat Completions and Responses both work, so n8n's OpenAI Chat Model node needs only the new base URL. A ready-to-import workflow: examples/n8n.
- Every request is one Taskpenny run, saved in
runs/and visible live on the page while it works. - System messages and earlier turns are passed as context; the last user message is the request.
stream: trueworks, but the answer arrives in one piece at the end: Taskpenny checks the work before answering. The headers and a keep-alive line go out at once.- Nothing fails in silence:
taskpenny.statussaysdone,unverified(complete, but a check did not pass or could not run) orpartial(stopped early,finish_reason: "length"), with the reasons intaskpenny.warnings; a run with no answer is an HTTP 502 error. - Each request is a paid run: set
max_retries=0in your client, or send anIdempotency-Keyheader so a retry gets the first run's answer. A client that disconnects without that header cancels its run. TASKPENNY_CEILING=anthropic/claude-sonnet-5makes the model you use today the strongest one Taskpenny may use.- Per request:
"taskpenny": {"max_cost": 0.2, "no_split": true}in the body, or the headerX-Taskpenny-Max-Cost. - The server listens only on your machine. If you open it, set a long random
TASKPENNY_API_KEY(openssl rand -hex 24) and put an https proxy in front: then the API and the page need the key (the page asks for it once). A request's budget is a ceiling, and it can ask for at mostTASKPENNY_MAX_COST(2 USD by default).
Docker
docker compose up                  # page and API on http://127.0.0.1:8765
# or: docker build -t taskpenny . && docker run -p 127.0.0.1:8765:8765 -e AI_GATEWAY_API_KEY taskpenny
Keys come from your environment and are never written into the image. Runs are kept in the taskpenny-runs
volume.
Keys
| You set | What Taskpenny does |
|---|---|
AI_GATEWAY_API_KEY (required) |
Jev decides every step and every model is reached through Vercel AI Gateway, with the real cost of every call. |
That, plus TASKPENNY_DIRECT=anthropic,openai and those providers' keys |
Those providers' models go straight to their own API; everything else, Jev included, through Vercel. |
That, plus TASKPENNY_LOCAL |
Basic tasks go first to a free local model (below). |
Without the Vercel key there is no real run: Taskpenny tells you so, and taskpenny demo and --dry-run still
work. taskpenny doctor shows what your keys reach and whether each model name exists on its provider's API,
without spending tokens.
Local models (free)
With Ollama running, basic tasks can run on your machine at no cost:
ollama pull qwen3:4b
export TASKPENNY_LOCAL=qwen3:4b          # tier 1 goes local; "qwen3:8b@2" also covers tier 2; "auto" = all installed
Jev still checks every result. A weak answer is first repaired by the same local model, then moves one tier up, where a cloud model does it unless a local model covers that tier too. Use a model of at least 3 to 4 billion parameters: tiny ones answer fast but badly.
What leaves your machine
Your prompt goes to Jev and the models through Vercel AI Gateway, and to any provider you call directly. Keys are
read from environment variables only and are never written to disk, run files or logs; set the server's own key
with TASKPENNY_API_KEY too, since a key on the command line shows in the process list. Saved runs contain your
requests and answers. The page loads nothing from other sites (its fonts come with it). See
SECURITY.md.
All results
First public benchmark: 142 tasks against Claude Sonnet 5, by route
With Jev at its list price. The report also has the figures with Jev free, as it was during the run.
| What Taskpenny did | Tasks | Taskpenny cost | As good or better |
|---|---|---|---|
| Basic and standard tasks, one cheap model | 103 | 92% less | 76% |
| Of those, labelling customer messages (true labels) | 10 | 95% less | same accuracy, 96 of 100 |
| Advanced tasks, one model | 16 | 11% less | 69% |
| Critical tasks, sent to Claude Opus | 8 | 2.0x as much | 100% |
| Requests split into parts | 15 | 2.2x as much | 73% |
| All | 142 | 13% less | 76% |
That run is why the ceiling and the "split only when it pays" rule exist. The 50 new tasks above were run after both changes. Method, raw data and how to rerun it: bench/public.
What we have learned so far
- Jev's gate chooses well when to split and what kind of answer is expected (41 of 42 on our development set).
- The saving comes from everyday requests going to models that cost a small fraction of a frontier model.
- Splitting only pays when the parts can go to cheaper tiers than the whole; at advanced level it did not.
- Cheap models give correct but bare answers. The automatic judge prefers more explanation; in a blind check of 20 pairs, the author often preferred the short answer that did only what was asked.
- Against Opus 5.5 the cheap tiers are not enough on hard prompts. The next thing to measure is a setting that sends more of that work to the strong tiers.
FAQ
Can you trust an LLM judge? It is from a third provider, compares each pair twice in both orders, and counts
a tie when the two orders disagree. It does like longer answers: many of Taskpenny's losses on basic tasks were
short, correct answers against longer ones. You can rerun the benchmark with your own judge, or give the baseline
Taskpenny's own worker instruction (--baseline-system worker) to see how much that matters.
Do I need Vercel? Yes. Every decision in Taskpenny is Jev's, and Jev is only reached through Vercel AI Gateway. Earlier versions let a small language model stand in for Jev; it made decisions that cost more and were never measured for accuracy, so it is gone. Your own provider keys still work next to the Vercel key.
Why Jev? Every decision Taskpenny makes is a closed question. Jev answers those with a probability and a confidence, costs about 4 cents per thousand decisions at list price (about 1,000 tokens each in our benchmark), and never writes text.
What if Jev changes? The development cases (bench/run_dev.py) show quickly whether its decisions moved, and
the thresholds that use them are in one place (Settings in decider.py).
Contributing
Adding a model is a few lines in models.yaml.
Translations of the page and good first issues: CONTRIBUTING.md
and docs/good-first-issues.md.
If Taskpenny saves you money, a star helps other people find it.
License
The code is MIT. The benchmark's task texts keep their own licences (Apache 2.0, CC BY-SA 3.0, CC BY 4.0): see bench/public/LICENSES.md. Made by Cinto Casals · SerIA Nativa.
1 maintainer

Metadata
1 maintainer
Release files for taskpenny 0.7.1
For a detailed explanation of source distributions (sdists) and built distributions (wheels), please see the package formats documentation.
Source distribution (sdist)
| File | Size | Uploaded | |
|---|---|---|---|
| taskpenny-0.7.1.tar.gz | 482.3 kB | Details |
Built distribution (wheel)
| File | Interpreter | ABI | Platform | Reset |
|---|---|---|---|---|
| taskpenny-0.7.1-py3-none-any.whl | Python 3 | none | any | Details |
Total release size: 945.4 kB
Release files / taskpenny-0.7.1.tar.gz
| Download URL | taskpenny-0.7.1.tar.gz |
|---|---|
| Size | 482.3 kB |
| Tags | Source |
|
SHA-256 checksum How to use checksums |
8667f3f158d0d9ad9a5f050b9cf9e5c3d9018e42d7cedaf15d9a4aba403642aa
|
|
BLAKE2b-256 checksum How to use checksums |
048adcd29b12d2f7950c0682f5b7b4ef8f5837daafa61a00a0901ca344514dc7
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
Yes |
| Uploaded via |
twine/7.0.0 CPython/3.13.14
|
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.


PyPI Publish Attestation
PyPI verified that this artifact, at this checksum, originated from the publisher listed below.
Signed by GitHub Actions, verified by PyPI on Oct 15, 2026.
Transparency logRelease files / taskpenny-0.7.1-py3-none-any.whl
| Download URL | taskpenny-0.7.1-py3-none-any.whl |
|---|---|
| Size | 463.2 kB |
| Tags | Python 3 |
|
SHA-256 checksum How to use checksums |
0058ab0c472e5a9394f59aa9828dfae571db2ea9d20930161c67f3a9ec32c35a
|
|
BLAKE2b-256 checksum How to use checksums |
e32c7ab6682e33c53f3a03e47e7aedf9fa4bff43af2d3654c166111b00f430ec
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
Yes |
| Uploaded via |
twine/7.0.0 CPython/3.13.14
|
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.
PyPI Publish Attestation
PyPI verified that this artifact, at this checksum, originated from the publisher listed below.
Signed by GitHub Actions, verified by PyPI on Oct 15, 2026.
Transparency log












