
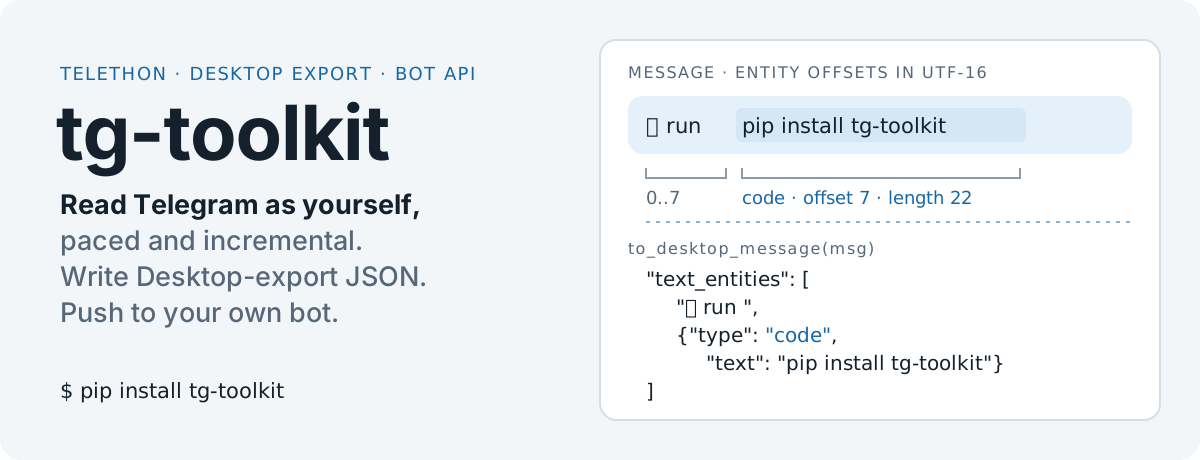



tg-toolkit is a small Python library for scripts that read Telegram through your own user account (Telethon), not through a bot. It reads channels and chats in a loop that waits between requests, continues from where the last run stopped, and sits out FloodWait instead of crashing. It also converts messages to and from the JSON that Telegram Desktop's "Export chat history" writes, and sends plain-text pushes to your own bot.
It has three modules, and you can use any one without the others:
| module | needs telethon | what it does |
|---|---|---|
tg_toolkit.reader |
only when called | paced, incremental, bounded message reads |
tg_toolkit.export |
no | Telegram Desktop export, both directions |
tg_toolkit.push |
no (stdlib urllib) |
Bot API message and desktop notify-send |
telethon is the only dependency and it is imported lazily, so push and export work on a machine
where telethon isn't installed.
Install
pip install tg-toolkit
# or
uv add tg-toolkit
Python 3.12 or newer. Reading needs a Telegram api_id / api_hash from
my.telegram.org and a Telethon session; export and push need neither.
What you get back
A message with an emoji and a code entity, run through to_desktop_message (output from the test fakes):
>>> to_desktop_message(msg)["text_entities"]
['🎉 run ', {'type': 'code', 'text': 'pip install tg-toolkit'}]
Telegram counts entity offsets in UTF-16 code units, and 🎉 takes two of them. Slicing the Python
string at offset 7 would cut one character too far; export slices through utf-16-le, so the code
span comes out whole.
How the reader works
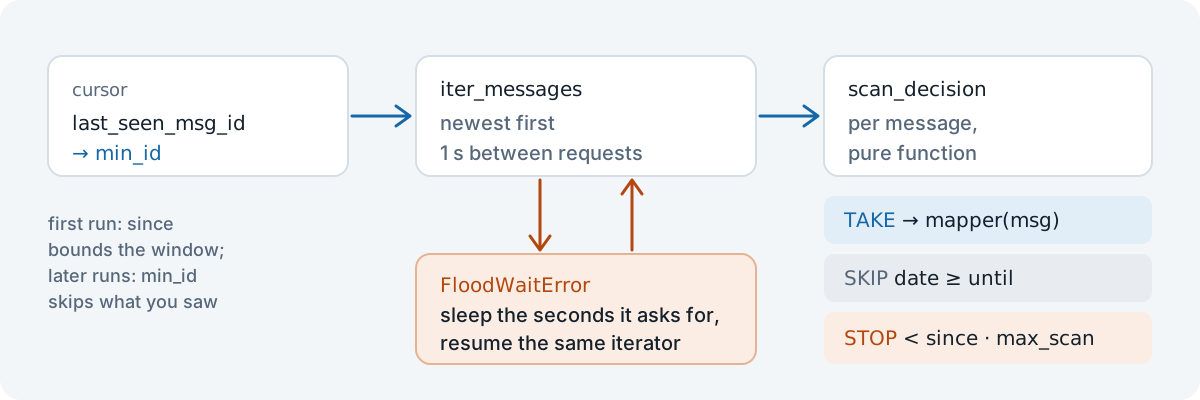
- User session, never a bot token. A bot can't read arbitrary public channels or your own dialogs.
- Every request is paced.
wait_time=1.0between GetHistory calls stays under Telegram's limit of about 10 requests per 30 s.flood_sleep_threshold=10lets Telethon absorb short waits. Longer ones raiseFloodWaitError;iter_flood_safesleeps the seconds the server asked for and resumes the same iterator, so no messages are lost across the wait. - Scans are bounded. Iteration goes newest-first and stops at the first message older than
since, because everything after it is older too.max_scanis the backstop for a very busy chat. Without both, a first run turns into a full-history backfill. - Incremental by
min_id. Telegram filters on the server side.last_seen_msg_idaccepts a bare id or a namespaced one ("telegram:<handle>:<msg_id>") and turns an unparseable cursor into0(a full windowed scan) instead of raising, so a corrupt cursor doesn't stop collection. - Unseen entity ids get one retry.
resolve_entitycallsget_entityagain after priming the dialog cache withclient.iter_dialogs(). - No event loop of its own. It uses
telethon.sync.
Usage
Incremental channel collect:
from tg_toolkit import last_seen_msg_id, read_messages, window_cutoff

def to_post(msg):
    text = (msg.message or "").strip()
    if not text:
        return None                       # returning None skips the message
    return RawPost(post_id=f"telegram:{handle}:{msg.id}", text=text, ...)

posts = read_messages(
    api_id=api_id, api_hash=api_hash, session=session, target=f"@{handle}",
    mapper=to_post,
    min_id=last_seen_msg_id(cursor),      # incremental
    since=window_cutoff(60),              # recency window, days
    max_scan=500,                         # backstop
    label=f"@{handle}",
    sort_key=lambda p: int(p.post_id.rsplit(":", 1)[-1]),   # last row = new cursor
)
Several chats over one connection. Prefer this to calling read_messages once per chat:
from tg_toolkit import collect, dialogs_by_name, make_client

with make_client(api_id, api_hash, session) as client:
    for entity, title in dialogs_by_name(client, chats):
        rows += collect(client, entity, lambda m: to_row(title, m),
                        since=since_dt, until=until_dt)
Live fetch in the Desktop export shape, so a parser written for offline exports keeps working:
from tg_toolkit import (desktop_payload, make_client, resolve_entity,
                        scan_messages, to_desktop_message, write_export)

with make_client(api_id, api_hash, session) as client:
    entity = resolve_entity(client, chat)
    # reverse=True gives chronological order; extra kwargs go straight to iter_messages
    msgs = [r for m in scan_messages(client, entity, reverse=True, limit=limit)
            if (r := to_desktop_message(m)) is not None]
write_export(desktop_payload(entity, msgs), out_dir / "result.json")
Offline, no API at all:
from tg_toolkit import parse_exports     # -> rows: chat, date, from, from_id, text
rows = parse_exports("data/*/result.json")
Push, no telethon needed:
from tg_toolkit import bot_send, notify, notify_with_action

notify("New mention", body, urgent=True, app_name="chat-watch", bot=(token, owner_id))
notify_with_action("New mention", body, action_label="Collect",
                   on_action=lambda: launch_investigate(ref), bot=(token, owner_id))
bot_send(token, owner_id, "plain text")   # -> bool, never raises
Export rules
- Entity offsets are UTF-16 code units, as Telegram defines them. A plain
strslice misaligns every message that contains an emoji. - Overlapping or nested entities are skipped, not merged. Merging would duplicate the covered text.
- Entity names match Desktop exactly (
code,pre,link,mention,bot_command,hashtag, …), because downstream parsers strip noise by name. A test pins them. - Telethon objects are matched by class name (
Message,Channel,User), which keeps the module free of telethon imports and testable with plain fakes. Service messages (class name other thanMessage) becomeNone.
Push rules
- Push is best-effort: every failure is logged and swallowed, never raised. The desktop toast is the primary channel and the bot is a mirror.
- Bot tokens are scrubbed from every log line (
scrub_token), because urllib puts the full URL, token included, into its exception messages:https://api.telegram.org/bot***/sendMessage. - Plain text, no
parse_mode, which avoids markdown-escaping bugs. Text over 4000 characters is truncated, never split. - The bot mirror runs in a daemon thread, so a slow or dead Bot API can't block your loop.
notifyreturns that thread (orNone) if you want to join it. - Send only to your own private chat with the bot (
chat_id), never to a chat you are monitoring.
API
reader:  resolve_credentials(api_id=None, api_hash=None, *, cache_path=None, env=None) -> (int, str)
         make_client(api_id, api_hash, session, *, flood_sleep_threshold=10)
         resolve_entity(client, target)                # @handle | id | title, dialog-primed retry
         dialogs_by_name(client, names) -> [(entity, title)]
         last_seen_msg_id(cursor) -> int
         window_cutoff(days=60, *, tz=None, now=None) -> datetime
         scan_decision(msg_date, scanned, *, since, until, max_scan) -> "take"|"skip"|"stop"
         iter_flood_safe(iterator, *, sleep, flood_error=None, label="") -> Iterator
         scan_messages(client, entity, *, min_id=0, since=None, until=None, max_scan=None,
                       wait_time=1.0, progress=None, progress_every=25, label="",
                       **iter_kwargs) -> Iterator
         collect(client, entity, mapper, *, sort_key=None, **scan_kwargs) -> list
         read_messages(*, api_id, api_hash, session, target, mapper, **collect_kwargs) -> list

export:  text_segments(raw, entities) -> list        sender_name(sender) -> str | None
         reactions(msg) -> list                      to_desktop_message(msg) -> dict | None
         chat_type(entity) -> str                    desktop_payload(entity, messages, *, title=None)
         write_export(payload, path) -> Path         flatten_text(text) -> str
         parse_export(path) -> [row]                 parse_exports(glob_or_paths) -> [row]
         ENTITY_TYPES, ROW_FIELDS

push:    scrub_token(s) -> str
         bot_send(token, chat_id, text, *, api_base=BOT_API, timeout=10) -> bool
         send_async(token, chat_id, text, **kw) -> Thread
         notify(title, body, *, urgent=False, app_name=..., bot=None) -> Thread | None
         notify_with_action(title, body, *, action_label, on_action, urgent=False,
                            app_name=..., bot=None) -> Thread
resolve_credentials looks in this order: explicit args (cached if you pass cache_path), then the
cache file, then TG_API_ID / TG_API_HASH. Without cache_path nothing is written to disk.
Migration notes for the projects it was extracted from
The code was pulled out of four copies of the same logic in the author's projects (dialogue-lens, get_cool_event and chat-watch). Differences from those copies:
scan_messagescounts differently from get_cool_event's loop. The old code incrementedscannedand then broke on>=, soMAX_SCAN_PER_RUN=500yielded 499 messages; heremax_scan=500yields exactly 500.resolve_credentialsgained the env fallback (TG_API_ID/TG_API_HASH) that dialogue-lens' docstring promised but its code never implemented. Passcache_pathto keep thedata/.telegram.jsonbehaviour.exportno longer imports telethon;Channel/User/Messageare matched by class name. Exotic entity subclasses that used to satisfyisinstancenow take theuser/group_chatbranch. No known Telethon type does this.- Consumer tests fake the client object (see
tests/fakes.py); nothing needstelethonpatched.
Tests
uv sync --extra dev && uv run pytest -q
No network, no session file, no real TelegramClient. tests/test_no_telethon.py blocks telethon
in the import system to prove that push, export and reader all import without it.
License
1 maintainer

Metadata
1 maintainer
Release files for tg-toolkit 0.1.3
For a detailed explanation of source distributions (sdists) and built distributions (wheels), please see the package formats documentation.
Source distribution (sdist)
| File | Size | Uploaded | |
|---|---|---|---|
| tg_toolkit-0.1.3.tar.gz | 84.0 kB | Details |
Built distribution (wheel)
| File | Interpreter | ABI | Platform | Reset |
|---|---|---|---|---|
| tg_toolkit-0.1.3-py3-none-any.whl | Python 3 | none | any | Details |
Total release size: 101.7 kB
Release files / tg_toolkit-0.1.3.tar.gz
| Download URL | tg_toolkit-0.1.3.tar.gz |
|---|---|
| Size | 84.0 kB |
| Tags | Source |
|
SHA-256 checksum How to use checksums |
df89ac3474af2e0853ad96a5ec324154884732afdf106b6ba2a0ecb1d7424175
|
|
BLAKE2b-256 checksum How to use checksums |
c236aa7a7a12e18f0882452a312a0f3d52151e86b152de32adb8ddd5c28bb0ec
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
Yes |
| Uploaded via |
twine/7.0.0 CPython/3.13.14
|
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.


PyPI Publish Attestation
PyPI verified that this artifact, at this checksum, originated from the publisher listed below.
Signed by GitHub Actions, verified by PyPI on Oct 15, 2026.
Transparency logRelease files / tg_toolkit-0.1.3-py3-none-any.whl
| Download URL | tg_toolkit-0.1.3-py3-none-any.whl |
|---|---|
| Size | 17.8 kB |
| Tags | Python 3 |
|
SHA-256 checksum How to use checksums |
56e80d1b1f84da64fcc634bc0d1343d4f6ed368503b55a778799b0368bac5926
|
|
BLAKE2b-256 checksum How to use checksums |
d13ffb1d6a8269bbb5b1eae4cd5d526f0b98c53d9ae7454c5e1e903e2cf685fd
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
Yes |
| Uploaded via |
twine/7.0.0 CPython/3.13.14
|
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.
PyPI Publish Attestation
PyPI verified that this artifact, at this checksum, originated from the publisher listed below.
Signed by GitHub Actions, verified by PyPI on Oct 15, 2026.
Transparency log













