
thomas
Give thomas a case set and a reward function. It gives you a baseline card, a training run, and a before/after comparison, with gonogo making the ship / don't-ship call at each end. The domain supplies the case shape and the reward; thomas supplies the plumbing.
thomas.train(): named after Thomas the Tank Engine (it's a train) and Thomas
Barrow of Downton Abbey (it's the undercrogue that earns its place).
                    ┌── encoder SFT ── (text, label) → Modal L4 → calibrated classifier
  Case set ──► thomas ┼── RL (Tinker) ── Case → TinkerEnv → LoRA RL → checkpoint
                    └── RL (Modal) ─── Case → TRL GRPO + vLLM colocate → LoRA adapter
                                  │
                                  └──► gonogo: verdict, interval, operating point
For RL tasks, the baseline, gradient reward and before/after eval use the
same domain score_text. Encoder classification is a separate exact-label
metric (prediction == expected); it does not call a Task's score_text.
Where thomas sits
thomas is one tile of a small ecosystem that takes a task from which model? to ship it or not:
your task ──► evalroute ─ choose a (model, effort) arm;
                │         measured where available, priors marked
                ▼
your cases ──► thomas ── train on labels (encoder) or score_text (RL);
                │         evaluate on untouched cases with gonogo
                ▼
              gonogo ── ship it, test a threshold on fresh cases, or walk away
- thomas (this repo) — the training
harness. RL shares
score_textacross training and held-out evaluation; encoder SFT instead learns labels and needs a separate held-out evaluation. - gonogo — the decision layer, and the root of the map. Any agent, your real cases, a target; the verdict comes with the interval behind it.
- evalroute — the routing layer: classify the task, hand back the arm with measured costs where available and priors otherwise; collect ratings to prioritize the next controlled batch.
- The Hermes plugins — the same three, inside your agent's session:
gonogo for decisions,
thomas with a human approval
hook on its training tool, and
/routebefore the first turn.
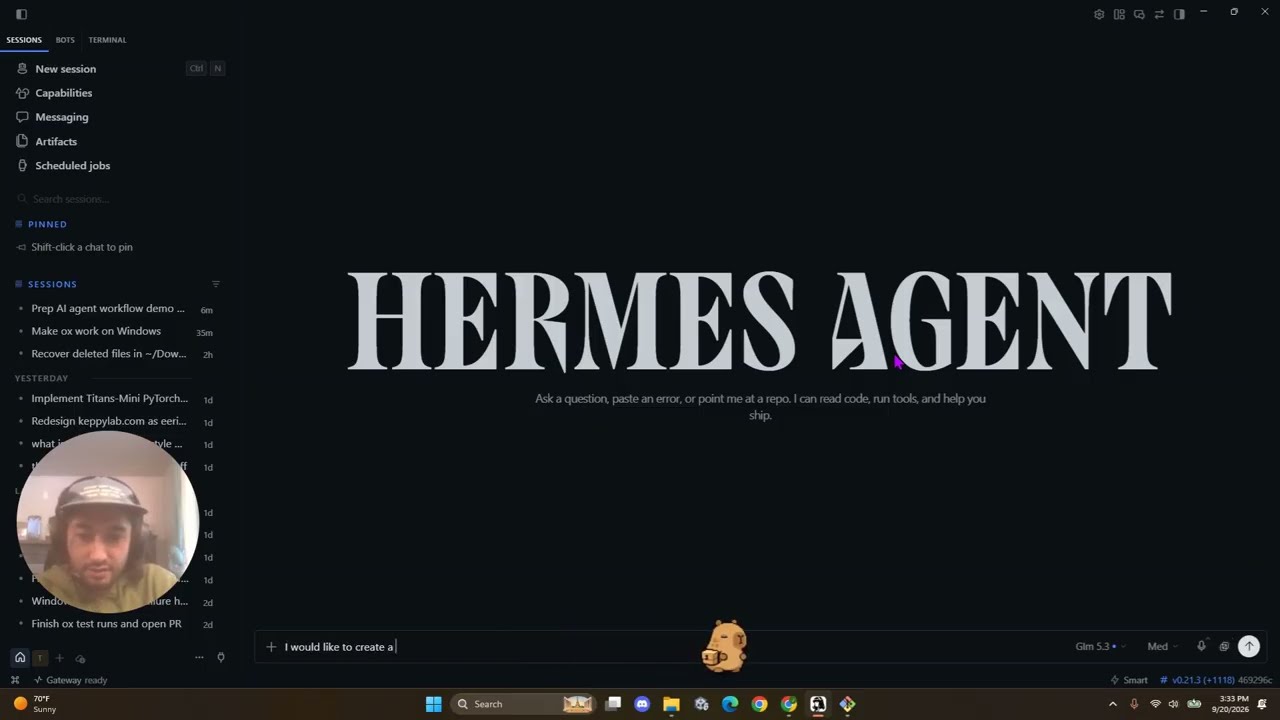
Video (40:33): the whole pipeline worked live: plan, contract, a subagent building the thomas training path, two dead runs and one false alarm, and the Modal fine-tune of ModernBERT-small-v2 on an L4 for under $1, scored on the gonogo Banking77 canary. Writeup.
- 87.2% [82.5%, 90.8%] pass rate against a 95% target → AUTOMATE WITH REVIEW
- at confidence ≥ 0.91: 98.3% precision [95.2%, 99.4%] on 71% of cases, the rest routed to a human
- calibration error 0.03 after temperature scaling; +10.0 points over the TF-IDF baseline on the same 250 cases (p < 0.001)
Artifact availability: the trained 146 MB Banking77 model and test-case
JSONL are local-only, ignored files; neither is in this repository or available
at an advertised download URL. No model has been published by this change.
The checked-in 250-case prediction receipt
contains only case id, expected label, predicted label and calibrated confidence
(no customer text). examples/banking77_receipt.py replays the gonogo decision
from it; with your own original artifact and cases, it checks every CPU prediction
against the receipt. The provenance manifest
identifies the locally checked model files, source CSVs, cases JSONL and receipt
by SHA-256; the script enforces those hashes when the local sources are present.
Hashes identify checked bytes, not independent attestation of a training run.
The receipt verifies the reported decision, not inference from a
public checkpoint. The dataset fetch/split logic is in
examples/banking77_encoder.py; Modal training costs money, and replay does not.
The operating threshold was selected on this same 250-case set and needs a
fresh holdout before deployment.
Install
pip install thomas-train                 # core + gonogo
pip install "thomas-train[encoder]"      # + encoder fine-tune on Modal (torch, transformers, modal)
pip install "thomas-train[post_train]"   # + Tinker RL
Installs as thomas-train (the plain thomas name on PyPI belongs to an unrelated
project); imports as thomas. The examples live in the repo, so clone it to run them
(pip install -e ".[encoder]" from the clone).
Try it
python examples/banking77_encoder.py --dry-run     # free: prints the config and the split, spends nothing
python examples/banking77_receipt.py             # replay the 250-case prediction receipt, CPU
# If you have the original local model and derived cases (not shipped):
python examples/banking77_receipt.py --model-dir examples/artifacts/banking77-enc \
    --cases-path examples/banking77_cases.jsonl   # verify all 250 predictions
python examples/banking77_predict.py --model-dir YOUR_LOCAL_ARTIFACT \
    "I lost my card"                              # CPU inference
Encoder fine-tune (Modal)
The cheapest path, and the one behind the Banking77 result above: a small encoder with a classification head, temperature-scaled on a held-out split so its confidences mean something to gonogo.
# (text, label) JSONL in, artifact dir out
modal run -m thomas.encoder_train --model johnnyboycurtis/ModernBERT-small-v2 --data cases.jsonl

# the Banking77 canary end to end (dry run first, it's free)
python examples/banking77_encoder.py --dry-run
python examples/banking77_encoder.py
The artifact is a HuggingFace save_pretrained dir plus label2id.json,
temperature.json and metrics.json (see CONTRACT.md §4).
examples/banking77_predict.py runs it interactively on CPU.
RL on a domain
import thomas
from dataclasses import replace
from thomas.domains import tutor, tutor_scenarios

task = thomas.Task(
    name="tutor",
    cases=tutor_scenarios.CASES,
    score_text=tutor.score,           # (case, text) -> (reward, detail)
    oracle_reply=tutor.oracle,        # a reply that scores 1.0
    system_prompt=tutor.TUTOR_SYSTEM_PROMPT,
    render_messages=tutor.render,
    case_id=tutor.case_id,
)
assert task.oracle_check()            # the env is winnable by construction
# Illustrative only: for a real interval use substantially more untouched cases.
train_task = replace(task, cases=task.cases[:-2])
eval_task = replace(task, cases=task.cases[-2:])
# Costs Tinker credits; get operator approval before invoking.
run = thomas.post_train(train_task, eval_task=eval_task, max_steps=5,
                        score_text_fn="thomas.domains.tutor.score",
                        oracle_reply_fn="thomas.domains.tutor.oracle",
                        render_messages_fn="thomas.domains.tutor.render",
                        case_id_fn="thomas.domains.tutor.case_id",
                        from_json_fn="thomas.domains.tutor.cases_from_json")
print(thomas.compare(run.before, run.after).summary())
post_train and every Modal entry point spend money. Inspect the config and
approve before invoking these APIs; printing a config is not an approval
gate. post_train requires a disjoint eval_task and rejects overlapping
case ids or rendered prompts. It also requires score_text_fn to resolve to
the exact Task.score_text callable used for the baseline. The before/after
cards are measured on that untouched eval set, not training cases.
Example domains
thomas.domains.tutor: a tutoring trace scored by deterministic hard checks. The tutor must not assert unverified correctness or leak the answer, must keep the problem's conditions visible, and gets no reward for solving it for the student. Ten single-turn math scenarios intutor_scenarios.thomas.domains.skill_classify: label a problem with a skill id, exact match.thomas.domains.eerie: literary continuation scored by n-gram overlap (the pretrain-path eval).
Modal GRPO (custom checkpoints)
modal run -m thomas.trl_grpo --domain tutor \
    --model-path Qwen/Qwen3-4B --max-steps 5 \
    --wandb-name my-run
Saves a LoRA adapter to a Modal volume; metrics go to the
W&B project thomas (Modal secret wandb). The programmatic
run_grpo_modal(gpu=...) path is fixed to A100-40GB and rejects other GPU
names; it does not dynamically change Modal's allocation.
Known constraints (each cost a run to learn):
- Colocate memory: vLLM's budget is
total_gpu × vllm_gpu_memory_utilizationminus everything already resident in the process (the trainer model). The utilization must cover trainer weights + vLLM weights + KV cache. 0.75 on an A100-40GB works for 4B models; setvllm_max_model_length(TRL 1.13 kwarg — notmax_model_len) to something small, or vLLM sizes KV for the model's native context. - Load in bf16 (
torch_dtype="auto"): a silent fp32 load doubles the resident model and breaks the budget. - Reward functions receive chat format: conversational completions arrive
as a list of
{"role", "content"}messages, not a string.trl_grpoextracts visible assistant text (strips<think>) on both local and Modal paths, then scores using the dataset's stablecase_id. Matching the first case with the same prompt is wrong when distinct cases share wording. - VLM-class models (e.g. Qwen3.5) are broken upstream in TRL colocate —
weight-sync name remapping for
*ForConditionalGenerationarchitectures (huggingface/trl#5269). thomas ships a monkeypatch prefix remap, but prefer text-onlyForCausalLMcheckpoints on this path. - Server mode (
vllm_mode="server") hangs on Modal's kernel 4.19; colocate is the supported mode.
The contract with gonogo
thomas and gonogo agree on six things: case ids, reward → passed / score,
the confidence definition (max(softmax(logits / T)) over the full label set),
the artifact a training run leaves on disk, eval splits, and the gonogo calls
thomas depends on. They're written down and versioned in docs/CONTRACT.md. It's contract version 1,
tested against gonogo-eval >=0.3,<0.4.
from thomas.contract import read_artifact   # stdlib only, no torch needed
art = read_artifact("examples/artifacts/banking77-enc")
art["temperature"], len(art["label2id"])    # 0.78, 77
Works with
| gonogo | Turns a score into a ship / don't-ship decision, with intervals |
| thomas | Trains the model: encoder fine-tune on Modal, or RL on Tinker / Modal |
| hermes-plugin-gonogo | gonogo as Hermes agent tools |
| hermes-plugin-thomas | thomas's encoder path as Hermes agent tools, GPU launches behind the approval gate |
The thomas ↔ gonogo contract is above.
What thomas is not
- Not gonogo (that's the scoring/decision layer; thomas imports it)
- Not a model (that's Tinker, Modal or nanogpt; thomas drives them)
- Not a case format (that's the domain)
- Not an eval framework (that's gonogo + the domain's checks)
Changelog
License
MIT
1 maintainer

Metadata
1 maintainer
Release files for thomas-train 0.2.4
For a detailed explanation of source distributions (sdists) and built distributions (wheels), please see the package formats documentation.
Source distribution (sdist)
| File | Size | Uploaded | Provenance | |
|---|---|---|---|---|
| thomas_train-0.2.4.tar.gz | 98.2 kB | With provenance | Details |
Built distribution (wheel)
| File | Interpreter | ABI | Platform | Reset |
|---|---|---|---|---|
| thomas_train-0.2.4-py3-none-any.whl | Python 3 | none | any | Details |
Total release size: 152.5 kB
Release files / thomas_train-0.2.4.tar.gz
| Download URL | thomas_train-0.2.4.tar.gz |
|---|---|
| Size | 98.2 kB |
| Tags | Source |
|
SHA-256 checksum How to use checksums |
008c6eda5b6848fb8a4cd0848a472ddc240523c557a0e9f1c8c4a3332aec160d
|
|
BLAKE2b-256 checksum How to use checksums |
fab778dfd4b644ae2ca57abccef065ec58b073a37d2a710729fdf195da14fff8
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
Yes |
| Uploaded via |
twine/7.0.0 CPython/3.13.16
|
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.


PyPI Publish Attestation
PyPI verified that this artifact, at this checksum, originated from the publisher listed below.
Signed by GitHub Actions, verified by PyPI on Oct 23, 2026.
Transparency logRelease files / thomas_train-0.2.4-py3-none-any.whl
| Download URL | thomas_train-0.2.4-py3-none-any.whl |
|---|---|
| Size | 54.3 kB |
| Tags | Python 3 |
|
SHA-256 checksum How to use checksums |
44734426ac8b5429772fabb9ddfb477bdc2362ad460c58c552a29fd55d7ac6a2
|
|
BLAKE2b-256 checksum How to use checksums |
61d808059ddf393009e9b01771b4ea1cdd3486cf727b48a9cf8020e1a3c9c7c7
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
Yes |
| Uploaded via |
twine/7.0.0 CPython/3.13.16
|
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.
PyPI Publish Attestation
PyPI verified that this artifact, at this checksum, originated from the publisher listed below.
Signed by GitHub Actions, verified by PyPI on Oct 23, 2026.
Transparency logSecurity for thomas-train 0.2.4
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.
Full provenance
All 2 files in this release have been uploaded with provenance metadata.
Attestation for thomas_train-0.2.4.tar.gz
PyPI Publish Attestation
PyPI verified that this artifact, at this checksum, originated from the publisher listed below.
Signed by GitHub Actions, verified by PyPI on Oct 23, 2026.
Transparency logA note on package security
PyPI is a repository for distributing packages, not a service for auditing them. While third-party security researchers and our staff do their best to detect and remove malicious packages, PyPI cannot guarantee the quality, security or suitability of any given package.
To learn more about protecting yourself from malicious actors, visit our package security documentation.













