
THX-01
THX-01 is a non-autoregressive, multilingual decision model developed by HAL-X AI. Given a state (a message, ticket, e-mail, document, JSON record or agent trace) and one or more typed questions written in natural language, it returns a calibrated answer to every question in a single forward pass of about 10 ms on one GPU.
THX-01 is trained with large-scale Reinforcement Learning for Calibrated Decisions (RLCD): the reward is a strictly proper scoring rule, so reporting honest probabilities is the only way to maximise it. Beyond choosing among options, THX-01 can return numbers stated in a document, verbatim excerpts and supporting citations, through the same interface.
| Parameters | 322M (307M encoder, 15M decision head) |
| Encoder | mmBERT-base, 22 layers, 256k vocabulary |
| Input | up to 1,024 tokens per question (question, options and state); longer states are truncated |
| Post-training | eight large-scale RLCD stages, about 2.1 million training decisions |
| Languages | post-trained in 18 languages with emphasis on Azerbaijani; 100+ supported |
| Latency | about 10 ms per request, about 1 ms per decision when batched |
| License | Apache 2.0 |
Contents
Question types
| type | returns | criteria |
|---|---|---|
choice |
one of N options with a probability for each | {"key": "description", ...} or a list |
noul |
P(yes) | optional |
score |
an ordinal level and its distribution | ordered list of levels |
number |
a numeric value stated in the document, or null if it is not stated |
optional min, max, precision |
excerpt |
a verbatim span of the document with its character offsets | none |
"cite": true (any question) |
the parts of the document that support the answer, with probabilities | none |
number, excerpt and citations are native THX-01 capabilities. They are not part of the TypeSafe question types
(choice, noul, score), where they have to be emulated in the service layer with repeated choice calls.
THX-01 also answers such emulation calls (value-range buckets and document chunks) through its native lookup, so existing
service layers work unchanged.
number returns values exactly as written in the document, normalised (1,2 mln becomes 1200000). It performs no unit
or currency conversion: a question about kilometres when the document states miles, or about euros when it states US
dollars, is answered with null. excerpt cuts its answer out of the document, so it cannot contain invented text.
Quickstart
import thx01

agent = thx01.load("doofz/THX-01")              # GPU if available

doc = ("Northwind Corp. reported Q3 2026 results. Revenue for the quarter was $48.3 million, up 14%. "
       "Net income was $6.2 million, compared with $4.1 million a year ago. "
       '"We will open two offices in Baku," said CEO Laura Chen.')

result = agent.decide(doc, {
    "kind":    {"type": "choice", "question": "What is this document?",
                "criteria": {"earnings": "earnings report", "complaint": "customer complaint", "invoice": "invoice"}},
    "revenue": {"type": "number", "question": "What was the revenue, in US dollars?", "cite": True},
    "quote":   {"type": "excerpt", "question": "What did the CEO say?"},
})
# kind -> earnings, revenue -> 48300000 (+ the supporting sentence),
# quote -> verbatim span starting "We will open two offices in Baku"
Install from PyPI (the weights download from this repository on first use):
pip install thx01                 # library
pip install "thx01[server]"       # plus the REST server
Benchmarks
Support-ticket classification
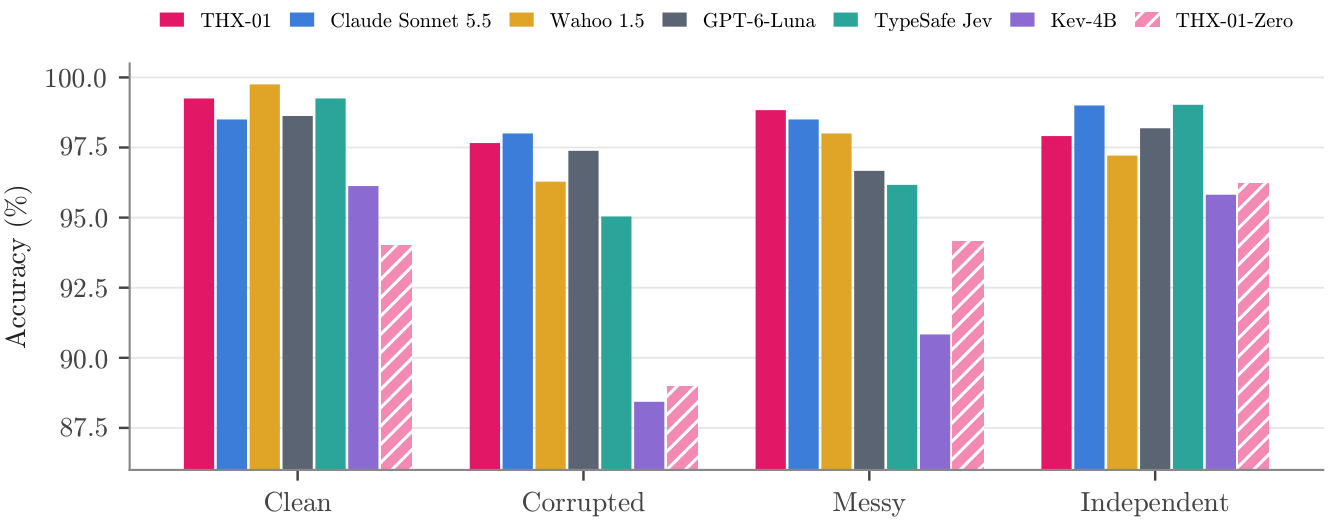
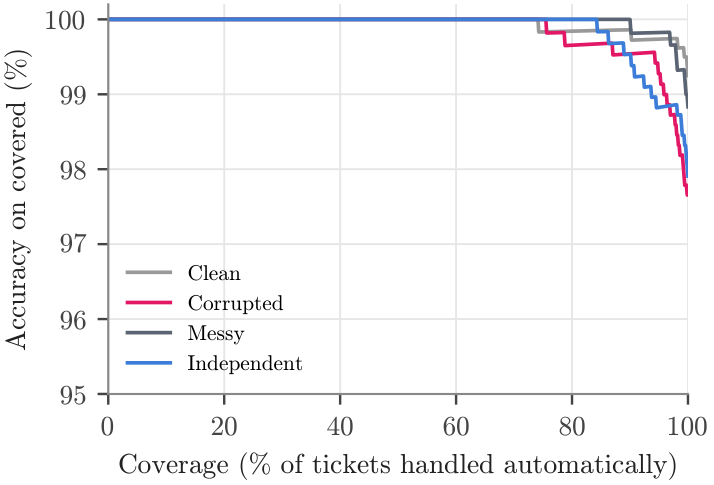
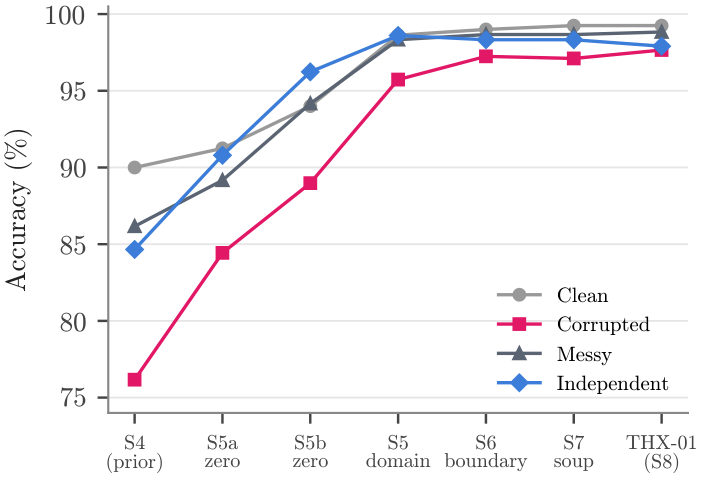
Fifteen categories (billing, refund, login, technical bug, outage, delivery, order change, product question, account change, security and fraud, data privacy, complaint, feature request, integration and API, contract and legal), four test sets with 2,843 tickets in Azerbaijani, Russian, English and Turkish: Clean, Corrupted (transliteration, removed diacritics, typos, noise), Messy (written messy on purpose) and Independent (written by GPT-6-Luna, never used for training).
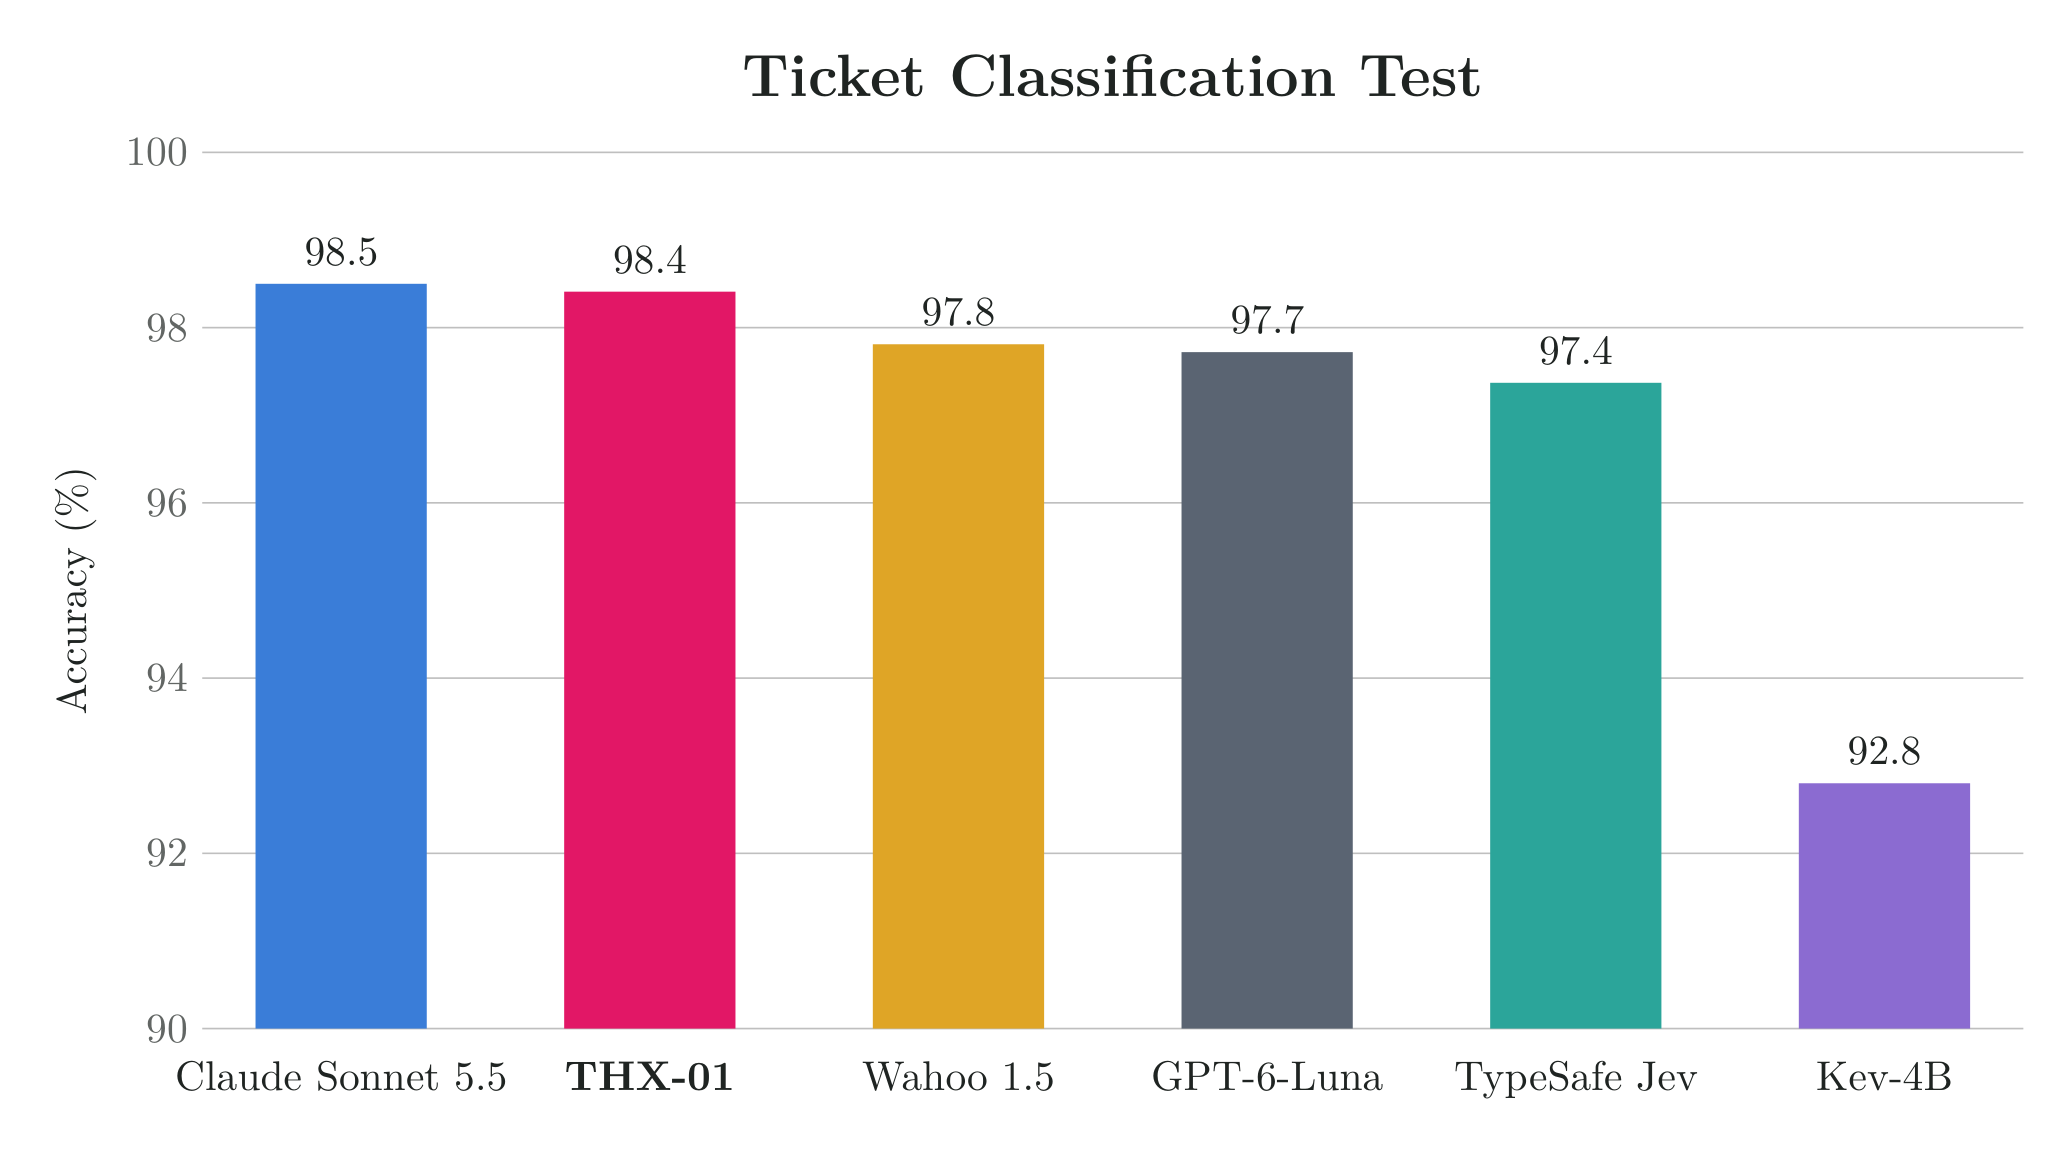
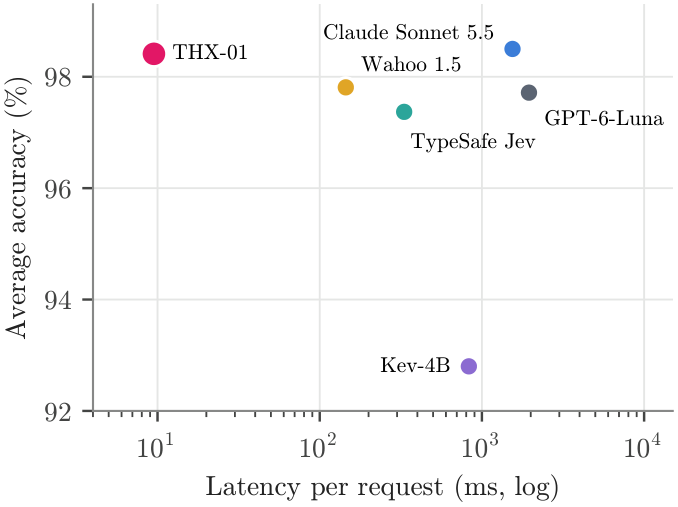
| model | Clean | Corrupted | Messy | Independent | Avg | ECE | latency |
|---|---|---|---|---|---|---|---|
| THX-01 | 99.2 | 97.7 | 98.8 | 97.9 | 98.4 | 0.003 | ~10 ms |
| Claude Sonnet 5.5 † | 98.5 | 98.0 | 98.5 | 99.0 | 98.5 | – | 1.5 s |
| Wahoo 1.5 | 99.8 | 96.3 | 98.0 | 97.2 | 97.8 | – | 145 ms |
| GPT-6-Luna | 98.6 | 97.4 | 96.7 | 98.2 | 97.7 | – | 1.9 s |
| TypeSafe Jev 1.13 | 99.2 | 95.0 | 96.2 | 99.0 | 97.4 | 0.007 | 331 ms |
| Kev-4B | 96.1 | 88.4 | 90.8 | 95.8 | 92.8 | 0.202 | 830 ms |
† Evaluated on a stratified subset of 200 tickets per set. ECE is measured on the Independent set; LLMs return no probabilities. THX-01 latency on one GPU; other models through their APIs.
Extraction and citation
Held-out multilingual documents (earnings reports, invoices, customs declarations, contracts, news, e-mails): 1,824 number questions and 1,357 excerpt questions. Number tasks report exact-value accuracy, excerpt tasks token F1, citation the accuracy of the top supporting part.
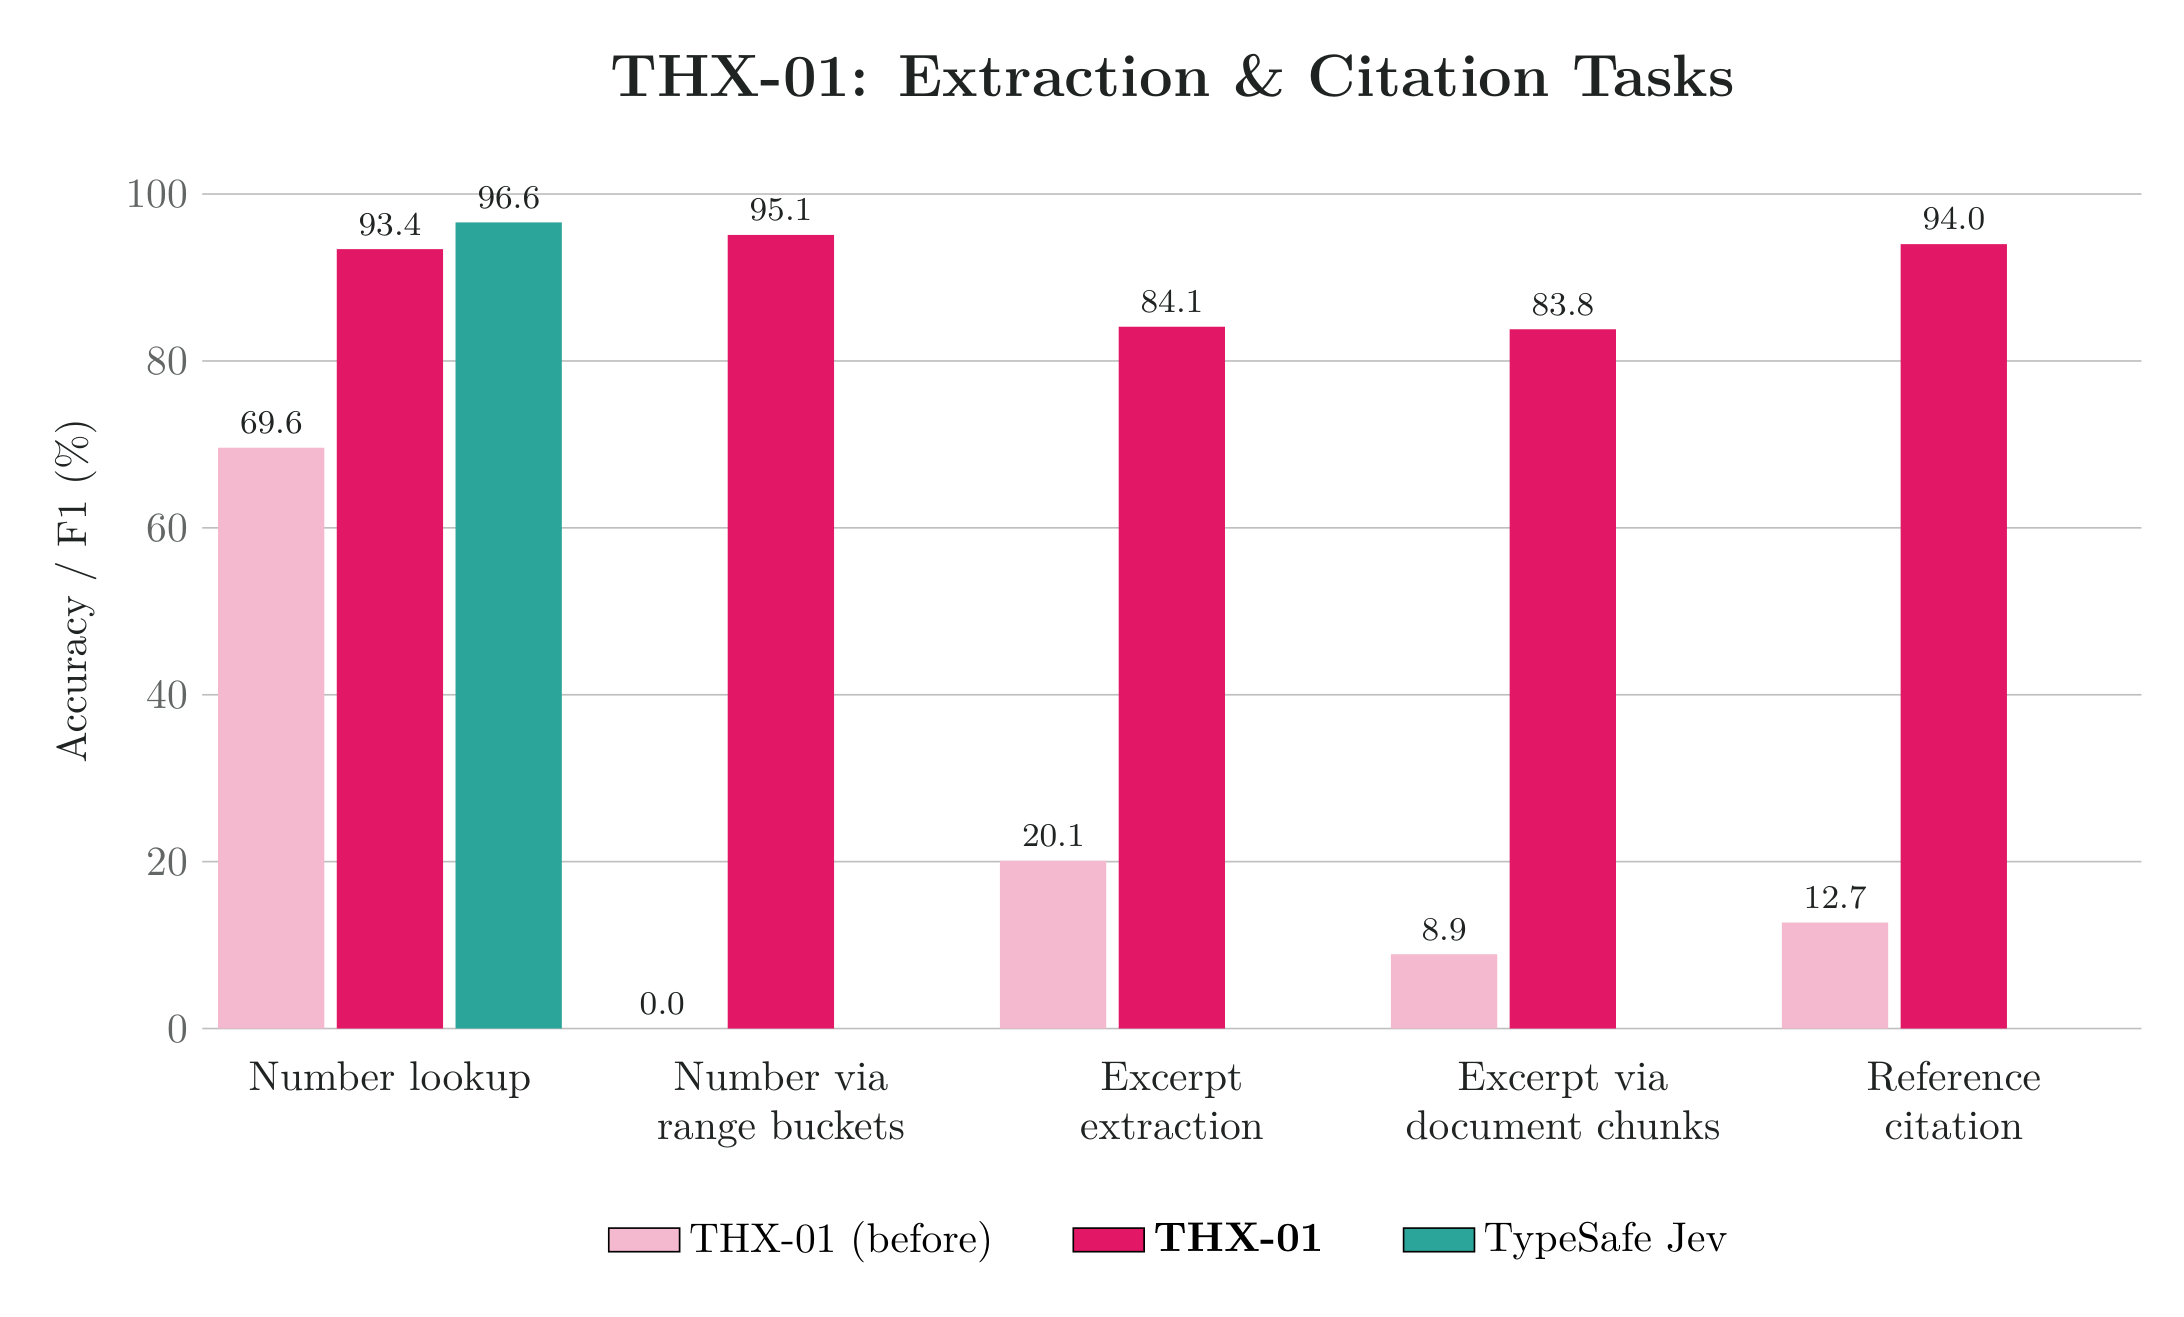
| task | previous checkpoint | THX-01 |
|---|---|---|
| Number lookup | 69.6 | 93.4 |
| Number via range buckets (service-layer emulation) | 0.0 | 95.1 |
| Excerpt extraction (F1) | 20.1 | 84.1 |
| Excerpt via document chunks (F1) | 8.9 | 83.8 |
| Reference citation | 12.7 | 94.0 |
On number lookup over the same documents, TypeSafe Jev 1.13 reaches 96.6%.
Calibration and selective automation
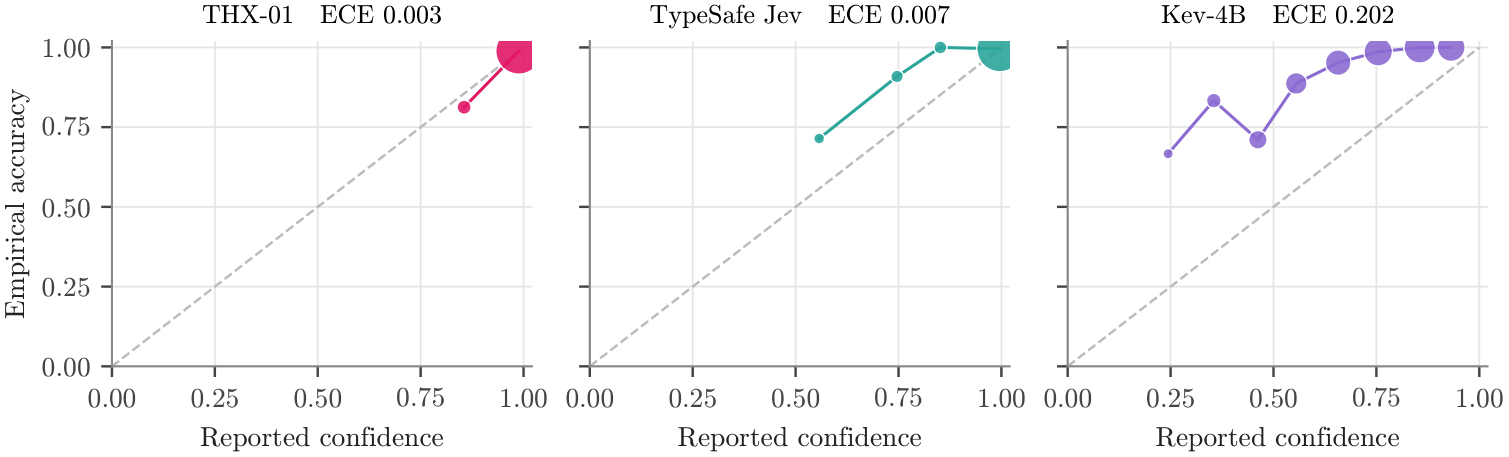
Because confidence is calibrated, a threshold turns it into an operating policy: THX-01 handles about three quarters of all tickets automatically without a single error on any of the four sets, and 90% of tickets at an accuracy of at least 99.5%.
Multilingual decision suite
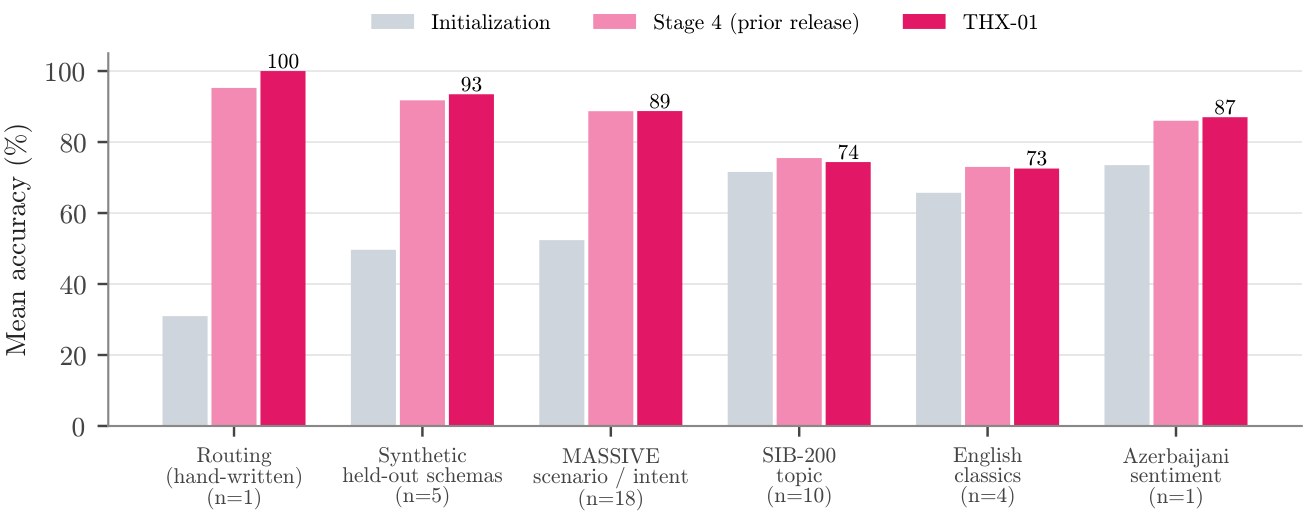
Thirty-nine held-out tasks: LLM routing, held-out synthetic schemas in 16 languages, MASSIVE scenarios and intents, SIB-200 topic classification in ten languages, AG News, Banking77, SMS spam, DAIR Emotion and Azerbaijani app reviews. Mean accuracy rises from 58.3% at initialisation to 84.2%, and mean ECE falls from 0.204 to 0.066. Hand-written LLM routing reaches 100%.
All 39 tasks
| task | initialisation | THX-01 | ECE |
|---|---|---|---|
| LLM routing (hand-written) | 30.9 | 100.0 | 0.060 |
| Synthetic routing (held-out schemas) | 33.2 | 95.6 | 0.020 |
| Synthetic decisions (held-out schemas) | 53.4 | 87.8 | 0.025 |
| Synthetic guard (held-out schemas) | 66.9 | 96.8 | 0.024 |
| Synthetic taxonomy (held-out schemas) | 36.0 | 90.6 | 0.035 |
| Synthetic emotion (held-out schemas) | 58.6 | 96.4 | 0.051 |
| AG News (4) | 94.1 | 92.3 | 0.018 |
| DAIR Emotion (6) | 43.4 | 44.6 | 0.284 |
| Banking77 (77) | 51.7 | 65.9 | 0.087 |
| SMS spam (yes/no) | 73.5 | 87.3 | 0.048 |
| AZ app-review sentiment | 73.5 | 87.0 | 0.072 |
| MASSIVE-intent@20 (az) | 36.3 | 89.7 | 0.038 |
| Intent yes/no (az) | 65.2 | 95.2 | 0.017 |
| MASSIVE-intent@20 (en) | 61.9 | 93.5 | 0.041 |
| Intent yes/no (en) | 66.7 | 95.3 | 0.017 |
| MASSIVE-scenario (en) | 69.4 | 90.8 | 0.049 |
| MASSIVE-scenario (az) | 41.6 | 88.8 | 0.052 |
| MASSIVE-scenario (ru) | 57.6 | 89.8 | 0.039 |
| MASSIVE-scenario (tr) | 50.2 | 87.4 | 0.055 |
| MASSIVE-scenario (de) | 56.4 | 88.2 | 0.050 |
| MASSIVE-scenario (fr) | 59.8 | 90.4 | 0.044 |
| MASSIVE-scenario (es) | 55.0 | 87.8 | 0.040 |
| MASSIVE-scenario (ar) | 43.8 | 82.2 | 0.050 |
| MASSIVE-scenario (hi) | 46.2 | 85.4 | 0.037 |
| MASSIVE-scenario (zh-CN) | 61.0 | 87.2 | 0.060 |
| MASSIVE-scenario (fa) | 46.6 | 89.0 | 0.052 |
| MASSIVE-scenario (ka) | 16.8 | 78.0 | 0.060 |
| MASSIVE-scenario (ja) | 59.2 | 91.8 | 0.043 |
| MASSIVE-scenario (ko) | 48.8 | 86.4 | 0.039 |
| SIB-200 (az) | 67.2 | 73.5 | 0.111 |
| SIB-200 (en) | 78.4 | 78.4 | 0.068 |
| SIB-200 (ru) | 75.5 | 76.0 | 0.082 |
| SIB-200 (tr) | 74.0 | 73.5 | 0.126 |
| SIB-200 (de) | 75.5 | 79.9 | 0.080 |
| SIB-200 (ar) | 73.0 | 76.5 | 0.076 |
| SIB-200 (hi) | 67.2 | 69.6 | 0.132 |
| SIB-200 (zh) | 77.9 | 77.9 | 0.082 |
| SIB-200 (kk) | 68.6 | 68.1 | 0.158 |
| SIB-200 (uz) | 58.3 | 70.1 | 0.145 |
Speed
| workload | time on one GPU |
|---|---|
| one question | about 9 ms |
| three questions about the same state | about 10 ms |
| 150 requests batched | about 156 ms |
| peak throughput | about 3,000 decisions per second |
Method
Every question is serialised as [CLS] question [MASK] option 1 [MASK] option 2 ... [SEP] state. The encoder reads the
whole sequence at once; a two-layer decision head scores each option at its own [MASK] position, and a softmax with a
temperature fitted per question type and option count gives calibrated probabilities. All questions of a request are
scored in one batched pass. Questions with more than 24 options are decided by a two-round tournament.
Reinforcement Learning for Calibrated Decisions
Each question is a one-step game: the policy reports a distribution q over the options, the outcome y is revealed, and the reward is
R(q, t) = sum_k t_k log q_k + 0.5 * (sum_k t_k q_k) / ||q||_2 - 1[ordinal] * RPS(q, t)
a combination of the logarithmic, spherical and ranked-probability scores. Because the reward is strictly proper, its expectation is maximised only when the reported distribution equals the true one. THX-01 optimises the expected reward with an exact, zero-variance gradient. Soft targets teach two further behaviours: a uniform target when no option applies (so the model reports uncertainty instead of a confident wrong answer) and near-miss credit on ordinal scales.
Training
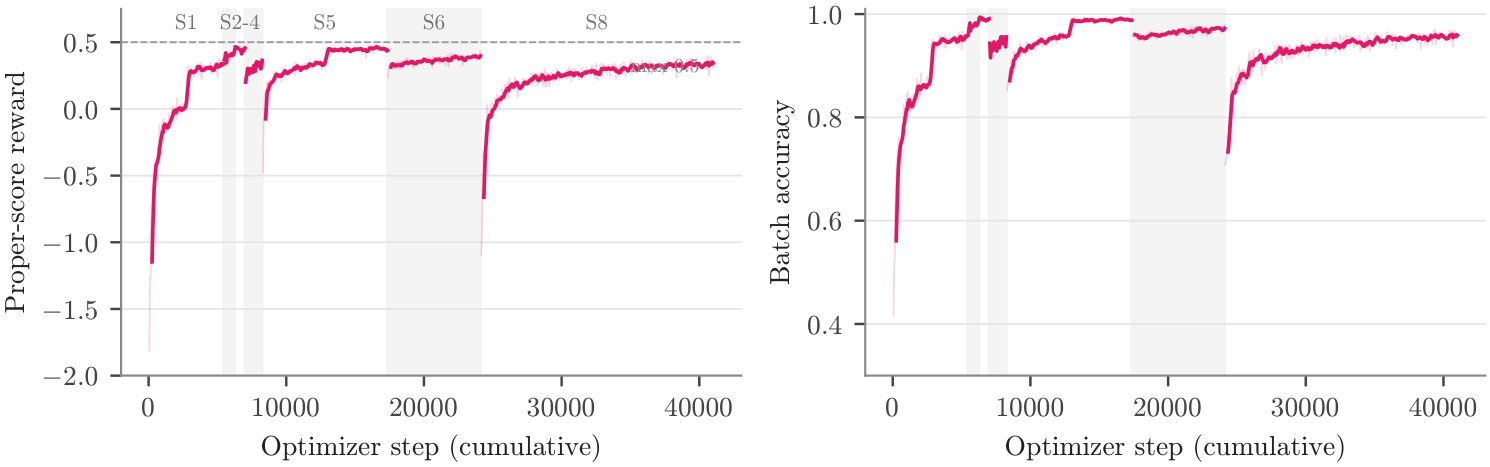
| stage | focus | decisions per epoch |
|---|---|---|
| S1 | broad multilingual RLCD: synthetic decisions in 16 languages, MASSIVE in 14 languages, Azerbaijani sentiment | 157,912 (x2) |
| S2 | spatial and control decisions | 53,040 |
| S3 | LLM and agent routing | 48,000 |
| S4 | generic skills: bare-key options, identifier lookup, no-good-option honesty | 77,000 |
| S5 | robustness and domain: 600 new business taxonomies, confusable pairs, transliteration and noise, support tickets | 213,961 (x2) |
| S6 | boundary cases between confusable categories, three teacher models | 284,207 |
| S7 | weight interpolation and temperature refit | – |
| S8 | extraction and citation: numbers, excerpts, supporting parts, currency equivalence, new hard decisions, full replay | 493,442 |
Training data combines curated data from the HAL-X data team, public benchmarks' training splits and verified synthetic data. Synthetic items are generated label-first by teacher models (Wahoo 1.5, GPT-6-Luna, Claude Sonnet 5.5) and kept only when a blind second pass agrees; test items and their near-duplicates are excluded from training. Optimisation uses 8-bit AdamW, bf16, length-bucketed batches, random option order and option subsets, and a frozen token-embedding matrix that preserves the encoder's coverage of more than 1,800 pretraining languages.
Languages
Post-training covers Azerbaijani, English, Russian, Turkish, German, French, Spanish, Arabic, Hindi, Chinese, Persian, Georgian, Japanese, Korean, Ukrainian, Kazakh, Uzbek and Italian, with Azerbaijani the largest language in every synthetic component. A dedicated curriculum covers the way text is actually typed in the region: Azerbaijani without its letters (e for the schwa, s for s-cedilla, c for c-cedilla), Russian in Latin transliteration, and code-mixing of Azerbaijani, Russian and English. Through its encoder THX-01 supports more than 100 languages.
| model | Independent az | ru | en | Corrupted az | ru | en |
|---|---|---|---|---|---|---|
| THX-01 | 97.1 | 98.3 | 98.3 | 97.9 | 96.6 | 97.9 |
| Claude Sonnet 5.5 † | 98.5 | 100.0 | 98.5 | 97.6 | 100.0 | 97.5 |
| Wahoo 1.5 | 96.2 | 95.8 | 99.6 | 94.5 | 95.0 | 98.9 |
| GPT-6-Luna | 97.9 | 97.5 | 99.2 | 97.2 | 95.0 | 98.6 |
| TypeSafe Jev 1.13 | 98.8 | 98.3 | 100.0 | 92.9 | 93.3 | 98.2 |
| Kev-4B | 94.2 | 95.4 | 97.9 | 83.1 | 89.1 | 94.3 |
REST API
pip install "thx01[server]"
THX01_MODEL=doofz/THX-01 THX01_API_KEY=your-key python -m thx01.server --port 8095
POST /v1/decide (alias POST /v1/systemone, TypeSafe-compatible) takes {"state": ..., "questions": {...}} and returns
{"answers": {...}, "latency_ms": ...}; POST /v1/decide/batch (alias /v1/systemone/batch) takes {"items": [...]}.
The state may be a string or an object with a document field; the question text may be given as instructions or
question. Requests are micro-batched on the GPU.
Limitations
- Fine-grained intent sets with many near-synonymous labels remain hard: Banking77 (77 intents) reaches 65.9%.
- Emotion with six overlapping classes (DAIR Emotion) reaches 44.6%; the model reports correspondingly low confidence.
numberandexcerptlocate text that is present in the document; they do not perform arithmetic, unit conversion or paraphrase.
Citation
@techreport{thx01_2026,
  title       = {THX-01: Large-Scale Reinforcement Learning for Calibrated Decisions in 100+ Languages},
  author      = {Aghayev, Farid and Ahmadbayli, Elturan},
  institution = {HAL-X AI},
  year        = {2026}
}
License
1 maintainer

Metadata
1 maintainer
Release files for thx01 1.0.0
For a detailed explanation of source distributions (sdists) and built distributions (wheels), please see the package formats documentation.
Source distribution (sdist)
| File | Size | Uploaded | |
|---|---|---|---|
| thx01-1.0.0.tar.gz | 51.7 kB | Details |
Built distribution (wheel)
| File | Interpreter | ABI | Platform | Reset |
|---|---|---|---|---|
| thx01-1.0.0-py3-none-any.whl | Python 3 | none | any | Details |
Total release size: 100.9 kB
Release files / thx01-1.0.0.tar.gz
| Download URL | thx01-1.0.0.tar.gz |
|---|---|
| Size | 51.7 kB |
| Tags | Source |
|
SHA-256 checksum How to use checksums |
6d1013b900ab30d4b8848b9c57e03e54e389e25c5f797df2aea9c6a69b18c8c3
|
|
BLAKE2b-256 checksum How to use checksums |
7d7cb1e5490b672c60037804de4b3709d42d8af3e82299205e781048a0e37674
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
No |
| Uploaded via |
twine/7.0.0 CPython/3.12.14
|
Release files / thx01-1.0.0-py3-none-any.whl
| Download URL | thx01-1.0.0-py3-none-any.whl |
|---|---|
| Size | 49.2 kB |
| Tags | Python 3 |
|
SHA-256 checksum How to use checksums |
090b8ec4b67b2271b7d228c9a99e0b79537cb652ff5b4b3c59ae7b154f660bf9
|
|
BLAKE2b-256 checksum How to use checksums |
ca9b85c98b4a19a0ccbc3e10f91f6e6bfd9b91ec19bb07fb8be5160bc7bd135a
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
No |
| Uploaded via |
twine/7.0.0 CPython/3.12.14
|













