
tipeft
Tabular-infused Parameter Efficient Finetuning (tipeft) is a novel PEFT method designed to infuse tabular features into the initialization process of re-parameterization parameter efficient finetuning (PEFT) methods. This provides an element of well-informed and representational capacity towards the newly introduced PEFT parameters, which are usually introduced and initialized independently
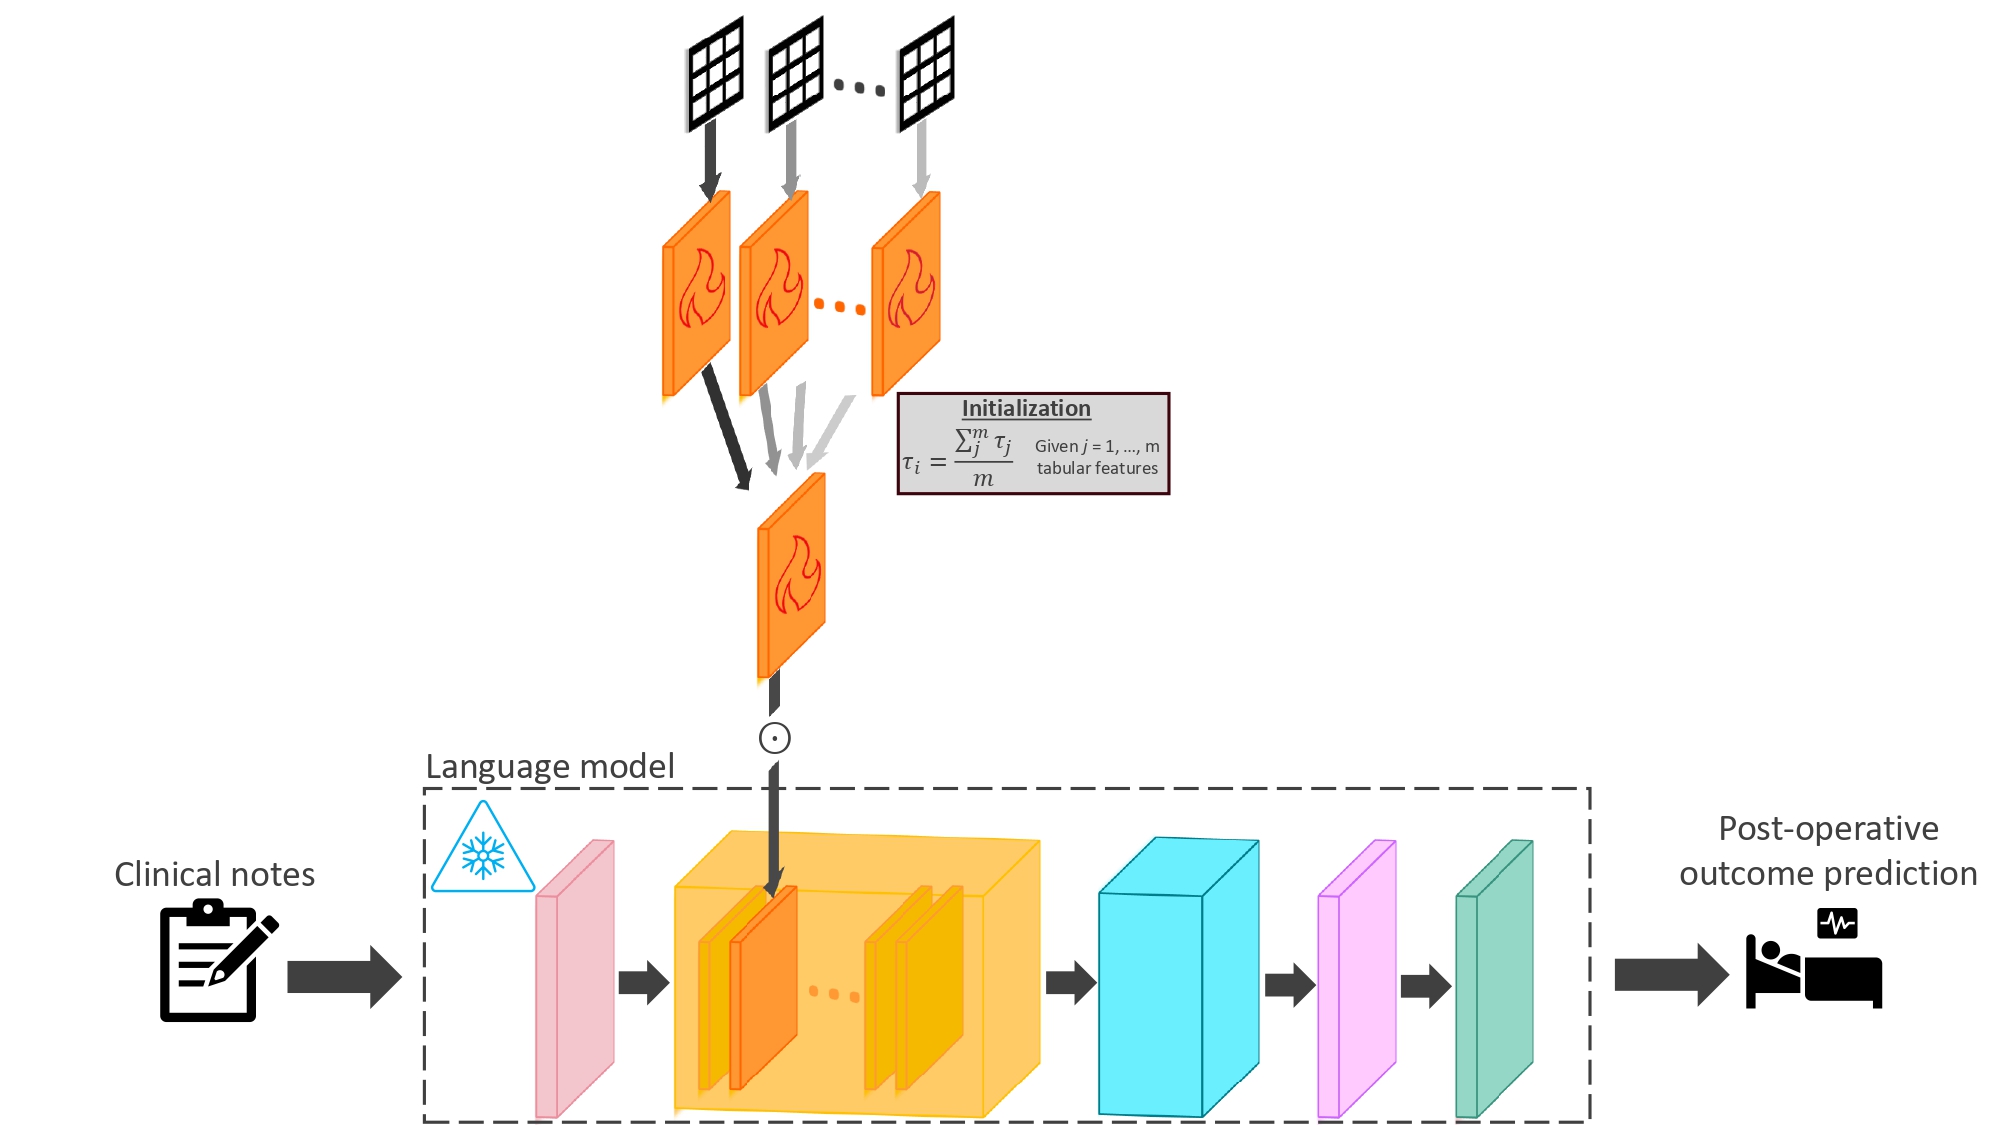
It is specifically designed for postoperative predictions in clinical care, where predictive and valuable pre-operative tabular features are often under-utilized in language model finetuning. For now, it supports both LoRA and IA3
Requirements
Dependencies
The following Python packages are required for tipeft:
-
torch -
transformers -
peft -
accelerate -
numpy -
pandas -
scikit-learn -
tqdm
Install dependencies with:
pip install torch transformers peft accelerate numpy pandas scikit-learn tqdm
Note on Pytorch installation
Because PyTorch wheels vary by CUDA version and hardware, it is recommended to install PyTorch manually following the instructions at https://pytorch.org/
System Requirements
tipeft has been tested and verified on the following configuration:
-
OS: Windows 10
-
Python: 3.9.19
-
CUDA: 12.6
Important Notes
-
Environment: Must be run in a Jupyter notebook. Running as a standalone Python script may cause multiprocessing issues.
-
CPU cores: At least 10 CPU cores recommended (uses
Pool(processes=10)internally). -
GPU: CUDA-compatible GPU required.
-
OS: Tested on Windows. Linux/Mac compatibility not yet verified.
Known Compatibility Limitations
-
Jupyter only - Uses
tqdm.notebookwhich may not display correctly outside Jupyter. -
Multiprocessing - May behave differently on Linux/Mac due to different multiprocessing backends.
If you encounter issues on a different setup, please open an issue with your system info.
GPU requirements
tipeft is designed for GPU acceleration.
-
At least 1 GPU is recommended
-
Suggested minimum: 16GB VRAM
-
Memory usage depends on:
-
sequence length
-
model size
-
batch size
-
peft configuration
-
Installation
To install in python, simply do the following:
pip install tipeft
Usage
train_tabular_infused_IA3
Parameters
-
train(pandas.DataFrame): Training dataframe containing text, label, and tabular feature columns (required) -
val(pandas.DataFrame): Validation dataframe with same structure as train (required) -
pretrained_model_name(str): Base model to fine-tune. Supports"emilyalsentzer/Bio_ClinicalBERT"or"microsoft/biogpt"(required) -
label_col(str): Column name of the binary outcome label. Must containTrue/Falsevalues. (required) -
text_col(str): Column name containing the clinical text (required) -
columns_unique_labels_of_tabular_features(dict): Map feature names to unique values. Use1for continuous,>1for categorical. (required) -
lr(float): Learning rate for final model training (default:0.001) -
num_epochs(int): Number of training epochs (default:5) -
lr_of_tabular_infused_features(float): Learning rate for tabular pre-training (default:0.0001)
Returns
-
model(PeftModel): The trained IA3 model -
tokenizer(AutoTokenizer): The tokenizer for the model
Example use case
from tipeft import train_tabular_infused_IA3


model, tokenizer = train_tabular_infused_IA3(

    train=train_df,

    val=val_df,

    pretrained_model_name="emilyalsentzer/Bio_ClinicalBERT",

    label_col="in_hospital_mortality",

    text_col="clinical_notes",

    columns_unique_labels_of_tabular_features={

        "gender": 2,

        "insurance": 3,

        "marital_status": 4,

        "anchor_age": 1,

        "anchor_year": 1

    },

    lr=0.001,

    num_epochs=5,

    lr_of_tabular_infused_features=0.0001

)
Notes
-
The
label_colmust contain boolean values (True/False) -
Categorical features should have
>1unique labels incolumns_unique_labels_of_tabular_features -
Continuous/numerical features should have
1as their value incolumns_unique_labels_of_tabular_features -
Ensure all unique values in categorical columns appear in both train and val sets
-
The trained model is saved to
trained_models/IA3_{pretrained_model_name}_{label_col}
train_tabular_infused_lora
Parameters
-
train(pandas.DataFrame): Training dataframe containing text, label, and tabular feature columns (required) -
val(pandas.DataFrame): Validation dataframe with same structure as train (required) -
pretrained_model_name(str): Base model to fine-tune. Supports"emilyalsentzer/Bio_ClinicalBERT"or"microsoft/biogpt"(required) -
label_col(str): Column name of the binary outcome label. Must containTrue/Falsevalues. (required) -
text_col(str): Column name containing the clinical text (required) -
columns_unique_labels_of_tabular_features(dict): Map feature names to unique values. Use1for continuous,>1for categorical. (required) -
lr(float): Learning rate for final model training (default:0.001) -
num_epochs(int): Number of training epochs (default:5) -
lr_of_tabular_infused_features(float): Learning rate for tabular pre-training (default:0.0001)
Returns
-
model(PeftModel): The trained IA3 model -
tokenizer(AutoTokenizer): The tokenizer for the model
Example use case
from tipeft import train_tabular_infused_lora


model, tokenizer = train_tabular_infused_lora(

    train=train_df,

    val=val_df,

    pretrained_model_name="emilyalsentzer/Bio_ClinicalBERT",

    label_col="in_hospital_mortality",

    text_col="clinical_notes",

    columns_unique_labels_of_tabular_features={

        "gender": 2,

        "insurance": 3,

        "marital_status": 4,

        "anchor_age": 1,

        "anchor_year": 1

    },

    lr=0.001,

    num_epochs=5,

    lr_of_tabular_infused_features=0.0001

)
Notes
-
The
label_colmust contain boolean values (True/False) -
Categorical features should have
>1unique labels incolumns_unique_labels_of_tabular_features -
Continuous/numerical features should have
1as their value incolumns_unique_labels_of_tabular_features -
Ensure all unique values in categorical columns appear in both train and val sets
-
The trained model is saved to
trained_models/lora_{pretrained_model_name}_{label_col}
Questions?
Contact me at alba@wustl.edu
1 maintainer

Metadata
1 maintainer
Release files for tipeft 0.1.3
For a detailed explanation of source distributions (sdists) and built distributions (wheels), please see the package formats documentation.
Source distribution (sdist)
| File | Size | Uploaded | Provenance | |
|---|---|---|---|---|
| tipeft-0.1.3.tar.gz | 237.0 kB | Without provenance | Details |
Built distribution (wheel)
| File | Interpreter | ABI | Platform | Reset |
|---|---|---|---|---|
| tipeft-0.1.3-py3-none-any.whl | Python 3 | none | any | Details |
Total release size: 250.2 kB
Release files / tipeft-0.1.3.tar.gz
| Download URL | tipeft-0.1.3.tar.gz |
|---|---|
| Size | 237.0 kB |
| Tags | Source |
|
SHA-256 checksum How to use checksums |
08320824d32260c726e01fb341e10903548c2496cbca38c323e47391c77dca10
|
|
BLAKE2b-256 checksum How to use checksums |
18468c03f07624a249772a951922f4ee3d5419cefe435311f826bc1920a5ac6d
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
No |
| Uploaded via |
twine/6.2.0 CPython/3.12.0
|
Release files / tipeft-0.1.3-py3-none-any.whl
| Download URL | tipeft-0.1.3-py3-none-any.whl |
|---|---|
| Size | 13.2 kB |
| Tags | Python 3 |
|
SHA-256 checksum How to use checksums |
1b51a85122b73a69bc3eb1d6fcb4c39d682a969fbf0d4c0394923d2dbd9e3501
|
|
BLAKE2b-256 checksum How to use checksums |
3621bd5bad99c5892095ecde3e7fc6cf038293c9d00d7f701e9cd03a6d927112
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
No |
| Uploaded via |
twine/6.2.0 CPython/3.12.0
|
Security for tipeft 0.1.3
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.
No provenance found
None of the files in this release were uploaded with provenance metadata.
A note on package security
PyPI is a repository for distributing packages, not a service for auditing them. While third-party security researchers and our staff do their best to detect and remove malicious packages, PyPI cannot guarantee the quality, security or suitability of any given package.
To learn more about protecting yourself from malicious actors, visit our package security documentation.














