
token-save-mcp
Your coding agent burns its context reading files. This stops it — and shows you the receipt.


An MCP server that sends big files to a cheap worker model and returns only the answer. The file bytes are paid for once, in the worker's context — not permanently in your agent's.
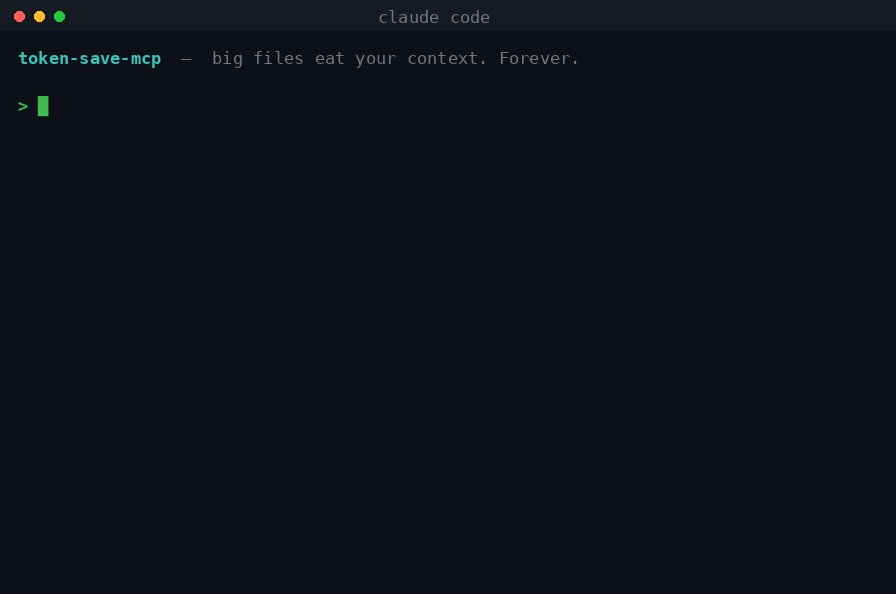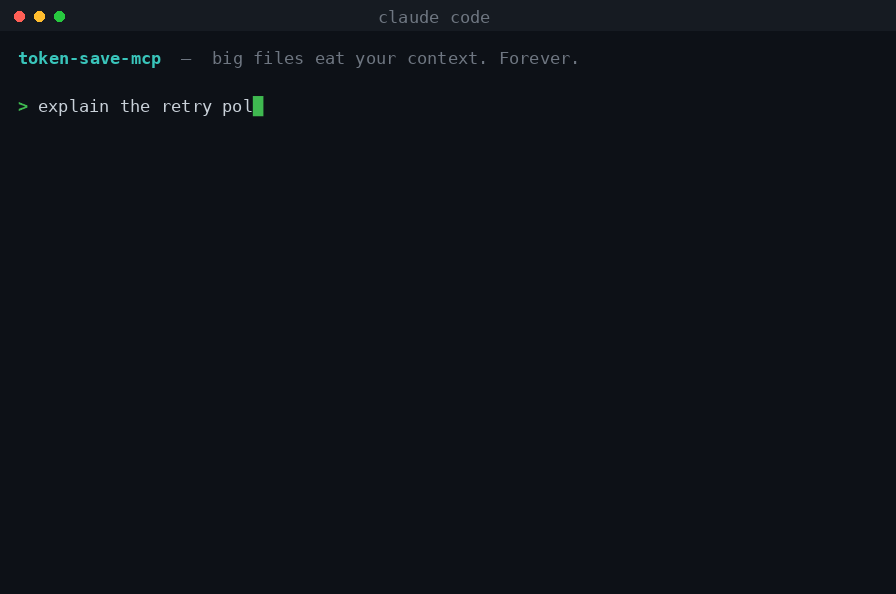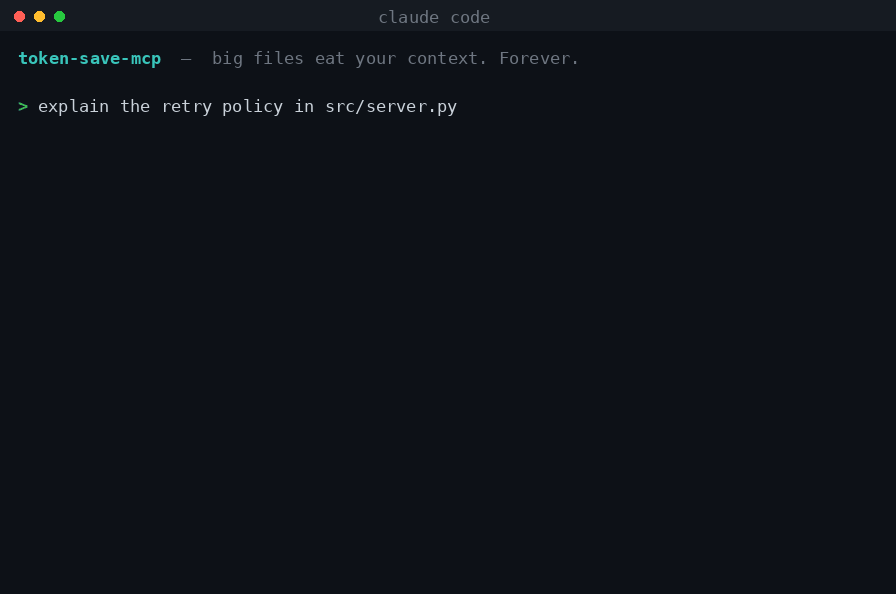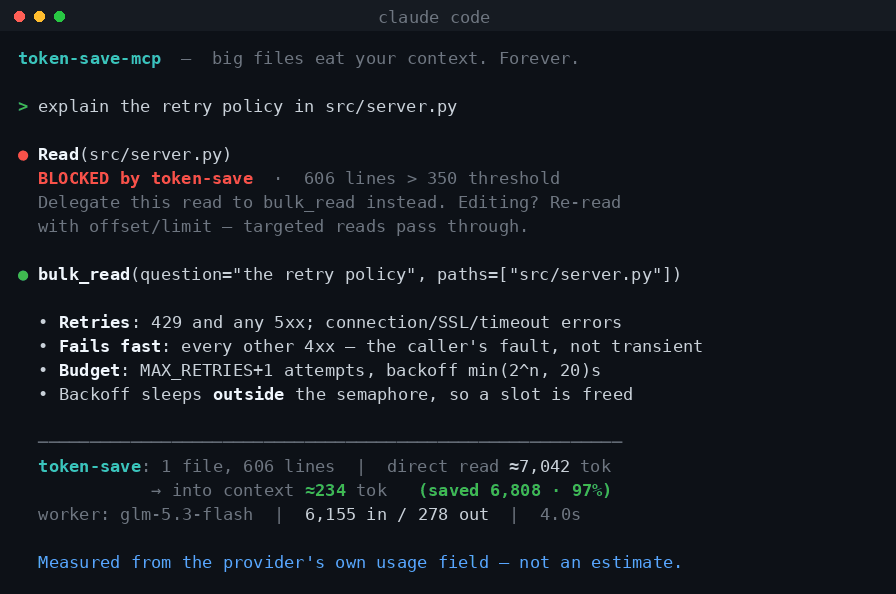
The hook blocks the expensive read and redirects it. The answer comes back with the worker's real token usage from the API response — not an estimate, a receipt:
─────────────────────────────────────────────────────────────
token-save: 1 file, 606 lines | direct read ≈7,042 tok →
into context ≈234 tok (saved 6,808 · 97%)
worker: glm-5.3-flash | 6,155 in / 278 out | 4.0s
Install
pip install token-save-mcp
token-save-mcp init
init finds a provider key you already have and sets everything up. If you
have none, it prints the options and where to get one — nothing is connected
automatically, and no key ships with the tool. The worker is yours: your
key, your provider, your bill.
A full run looks like this:
export OPENROUTER_API_KEY=sk-or-...        # your key, from your provider
token-save-mcp init --provider openrouter --hook
Verify with token-save-mcp doctor, which checks the config and makes one
live call to prove the worker answers:
✓ provider: openrouter -> https://openrouter.ai/api/v1
✓ worker model: deepseek/deepseek-chat
✓ MCP server registered and connected
✓ enforcement hook installed
✓ worker replied in 2.0s (21 in / 13 out)
Don't want to send code anywhere? Point it at a model on your own machine — no key, no network:
token-save-mcp init --provider local # Ollama on localhost:11434
Providers
Any OpenAI-compatible endpoint works. Presets:
--provider |
Endpoint | Key variable |
|---|---|---|
ollama (default) |
ollama.com | OLLAMA_API_KEY |
openrouter |
openrouter.ai | OPENROUTER_API_KEY |
deepseek |
api.deepseek.com | DEEPSEEK_API_KEY |
groq |
api.groq.com | GROQ_API_KEY |
local |
localhost:11434 | (none) |
Anything else: set TOKENSAVE_BASE_URL and TOKENSAVE_API_KEY directly.
With local your code never leaves the machine.
The transport is the plain OpenAI SDK pointed at a base_url, so any
OpenAI-compatible endpoint works. The measurements below were taken against
Ollama Cloud; the other presets are configured and exercised by the test suite
but their numbers will differ with the model you pick.
The part nobody else does: enforcement
Every token-saving tool has the same failure mode — the agent forgets to use it. A tool the model may ignore gets ignored, and your savings are whatever the model felt like that day.
token-save-mcp install-hook registers a PreToolUse hook that blocks
Read on files over the threshold and redirects the agent to bulk_read:
Read("src/server.py")
→ BLOCKED: This file is 606 lines (threshold: 350).
  Use bulk_read to delegate this read instead.
  Need exact content to EDIT? Re-read with offset/limit — that passes through.
What still passes through, by design:
- Targeted reads (
offset/limit) — editing needs exact text - Small files — under the threshold, delegating costs more than it saves
- Binaries and missing files — nothing to summarise
Not ready to be told no? Install it in warn mode instead — the read goes through, but you see what it cost:
token-save-mcp install-hook --hook-mode warn
Enforcement is opt-in and reversible: token-save-mcp uninstall-hook.
The hook is Claude Code only. The
bulk_read/code_writetools are plain MCP and work in any client — Cursor, Cline, Windsurf, Codex — just without the enforcement layer.
Tools
bulk_read(question, paths, model?, effort?)
Read files without pulling them into context.
bulk_read(
  question="Which methods touch the database, and where is auth enforced?",
  paths=["src/service.py", "src/handlers.py"]
)
Use for: surveying unfamiliar code, "what does this do", tracing a flow across files, finding where something is handled.
Don't use for: editing (you need exact text — use a targeted read), debugging that needs your own reasoning over raw code, or files under ~350 lines where delegation overhead exceeds the saving. The tool tells you when you've crossed that line rather than silently burning a call.
code_write(spec, reference, target?, model?, effort?)
Generate boilerplate matching an existing file's style. With target, the code
is written straight to disk and only a confirmation returns — the generated
code never enters your context at all.
code_write(
  spec="pytest suite for clamp(value, lo, hi), covering both bounds and lo>hi",
  reference=["tests/test_total.py"],
  target="tests/test_clamp.py"
)
→ Wrote tests/test_clamp.py (32 lines). Not read into your context.
Never overwrites: the target is created with O_EXCL, which also refuses to
follow a dangling symlink.
status()
Prints the live configuration and makes one tiny call to prove the worker is actually reachable.
token-save-mcp stats
Every call appends one line to a local ledger, so you can see what the tool has actually saved you. Example output after a few weeks of use:
$ token-save-mcp stats --badge
token-save-mcp — all time
148 calls · 71,204 lines of code read by a worker
context saved: 812,455 tokens (94%)
worker time: 612s total
Markdown badge:
The ledger is a plain JSONL file in ~/.token-save/ and never leaves your
machine. --since 7 limits the window; TOKENSAVE_NO_LEDGER=1 turns recording
off entirely.
Measured savings
Real runs, not projections. Each number is the footer from an actual call:
| What | Size | Direct read | Via token-save | Saved |
|---|---|---|---|---|
| This project's own server.py | 606 lines | ≈7,042 tok | ≈234 tok | 97% |
| A large TypeScript handler | 602 lines | ≈13,340 tok | ≈689 tok | 95% |
| Production Python service | 443 lines | ≈5,788 tok | ≈684 tok | 88% |
| 4 files across a codebase | 1,910 lines | ≈28,379 tok | ≈304 tok | 99% |
| Code generation to disk | 58 lines written | — | 0 tok | 100% |
Method: "direct read" is the file's own size at ~3.6 chars/token (source
code is denser than prose); "via token-save" is the returned answer measured the
same way. The worker's in/out numbers come from the provider's usage field.
Reproduce any row by running the same call — the footer prints on every one.
Where it's weaker, honestly: on a 281-line diff the saving was 67%, because a short input with a long answer is the worst case. The tool says so in its own output. Savings are best where the file is big and the question is narrow.
How it compares
Different tools solve "too many tokens" in genuinely different ways:
| Approach | Enforced? | Savings figure | |
|---|---|---|---|
| token-save-mcp | LLM worker reads, returns an answer | Yes — hook blocks Read | Measured per call |
| Static AST tools | Parse the tree, return exact symbols | No | Deterministic |
| Other delegation MCPs | LLM worker, single provider | No | Usually estimated |
Static AST tools are better than this one at "give me the exact body of
handleRequest" — they're free, instant, and can't hallucinate. Reach for them
for symbol lookup.
This tool is for semantic questions over large files — "what does this service do", "where does auth happen", "which of these files handle retries" — where you want an answer, not an extract. That costs a worker call and a few seconds, and a worker can be wrong. Use both.
Configuration
| Variable | Default | Purpose |
|---|---|---|
TOKENSAVE_PROVIDER |
ollama |
Preset: ollama, openrouter, deepseek, groq, local |
TOKENSAVE_API_KEY |
— | Overrides the preset's key variable |
TOKENSAVE_BASE_URL |
preset | Any OpenAI-compatible endpoint |
TOKENSAVE_MODEL |
preset | Worker model id |
TOKENSAVE_MIN_LINES |
350 |
Hook threshold, and the "too small" warning |
TOKENSAVE_HOOK_MODE |
block |
warn allows the read but flags the cost |
TOKENSAVE_HOOK_MAX_BYTES |
100000 |
Also block on size — catches minified files |
TOKENSAVE_MAX_CORPUS_BYTES |
2000000 |
Ceiling on one request |
TOKENSAVE_TIMEOUT |
600 |
Seconds per call |
TOKENSAVE_MAX_RETRIES |
4 |
Retries on transient failures |
TOKENSAVE_MAX_CONCURRENCY |
3 |
Match your provider's limit |
TOKENSAVE_LEDGER |
~/.token-save/ledger.jsonl |
Where stats reads from |
TOKENSAVE_NO_LEDGER |
unset | Set to disable local recording |
When not to use this
Being clear about this is the point, not a disclaimer:
- You need exact text to edit. Use a targeted read. The hook lets those through.
- You're debugging subtle behaviour. Summaries lose the detail that matters.
- The file is small. Under ~350 lines, reading directly is cheaper and faster.
- The worker can be wrong. It's an LLM. For anything you'll act on blindly, verify against the source. Static tools don't have this failure mode.
Development
git clone https://github.com/Habartru/token_save_mcp
cd token_save_mcp
pip install -e ".[dev]"

python tests/test_server.py    # 95 server tests — no API calls
python tests/test_cli.py       # 24 CLI / onboarding tests
bash tests/test_hook.sh        # 19 hook routing tests
The test suite stubs the transport, so it costs nothing to run and is safe in CI. It covers the retry loop, corpus assembly, fence stripping, the disk-write guards, and every hook routing decision.
Credits
The delegation-plus-hook pattern is adapted from the shunt plugin in
spotify/portal-ai-plugins
(Apache-2.0), which routes the same kind of work through Spotify's internal
Portal CLI. This project keeps the idea and swaps the transport for any
OpenAI-compatible provider, so no corporate Portal instance is required. Files
also travel in-process rather than through argv, which removes the 128 KiB
per-argument limit on Linux.
MIT licensed.
1 maintainer

Download files
Download the file for your platform. If you're not sure which to choose, learn more about installing packages.
Source Distribution
Built Distribution
Filter files by name, interpreter, ABI, and platform.
If you're not sure about the file name format, learn more about wheel file names.
Copy a direct link to the current filters
File details
Details for the file token_save_mcp-0.1.1.tar.gz.
File metadata
- Download URL: token_save_mcp-0.1.1.tar.gz
- Upload date:
- Size: 159.4 kB
- Tags: Source
- Uploaded using Trusted Publishing? No
- Uploaded via:
twine/7.0.0 CPython/3.14.6
File hashes
| Algorithm | Hash digest | |
|---|---|---|
| SHA256 |
e1adc95ec900cf481cf432640b02126ee1041db1d2182c080f58e8983e13e355
|
|
| MD5 |
e12603be4c91a9158279df001352c318
|
|
| BLAKE2b-256 |
2d01531a78239db244b1b564880125f09a70b17e78c4b8171cbb72fa608108ef
|
File details
Details for the file token_save_mcp-0.1.1-py3-none-any.whl.
File metadata
- Download URL: token_save_mcp-0.1.1-py3-none-any.whl
- Upload date:
- Size: 26.1 kB
- Tags: Python 3
- Uploaded using Trusted Publishing? No
- Uploaded via:
twine/7.0.0 CPython/3.14.6
File hashes
| Algorithm | Hash digest | |
|---|---|---|
| SHA256 |
954ba8d5293e9039b5c695bf55f49f0994ee83636eaef21f4b31613655236ca4
|
|
| MD5 |
59e0400af82a879c62dfda12096e3da0
|
|
| BLAKE2b-256 |
66261dd29f04ba2295b6c2ca3d4bc78d9aba46f96f570da4d168894f7adbf8ac
|














