
TokenSpeed-MLA
Speed-of-light TokenSpeed MLA kernels for Blackwell (SM100/SM103) with:
MLA prefill:- CuTe DSL JIT backend for ragged varlen FMHA (no padding)
- BF16 output, optional LSE output, causal/non-causal modes, PDL support
MLA decode:- CuTe DSL decode kernels for FP16/BF16/FP8 input paths
- FP8 decode writes BF16 output for better downstream stability
- Split-KV + workspace path with runtime auto-sizing and compile caching
MLA K/V pack + FP8 quantize:- Fused Triton kernel replacing
cat + cast + castin chunked prefill - Supports strided views and optional pre-allocated output buffers
- Fused Triton kernel replacing
This package includes performance-oriented optimizations for latency-sensitive
serving workloads, especially coding agent style use cases with high request
concurrency, short decode steps, and strict time-to-first-token/next-token
requirements. For MLA decode kernel, small q_len * num_heads
configurations can fold a query-token group (fold_sq_factor) into heads for
better tile utilization; remaining query groups are scheduled across the query
sequence dimension.
Performance Numbers
Prefill Performance
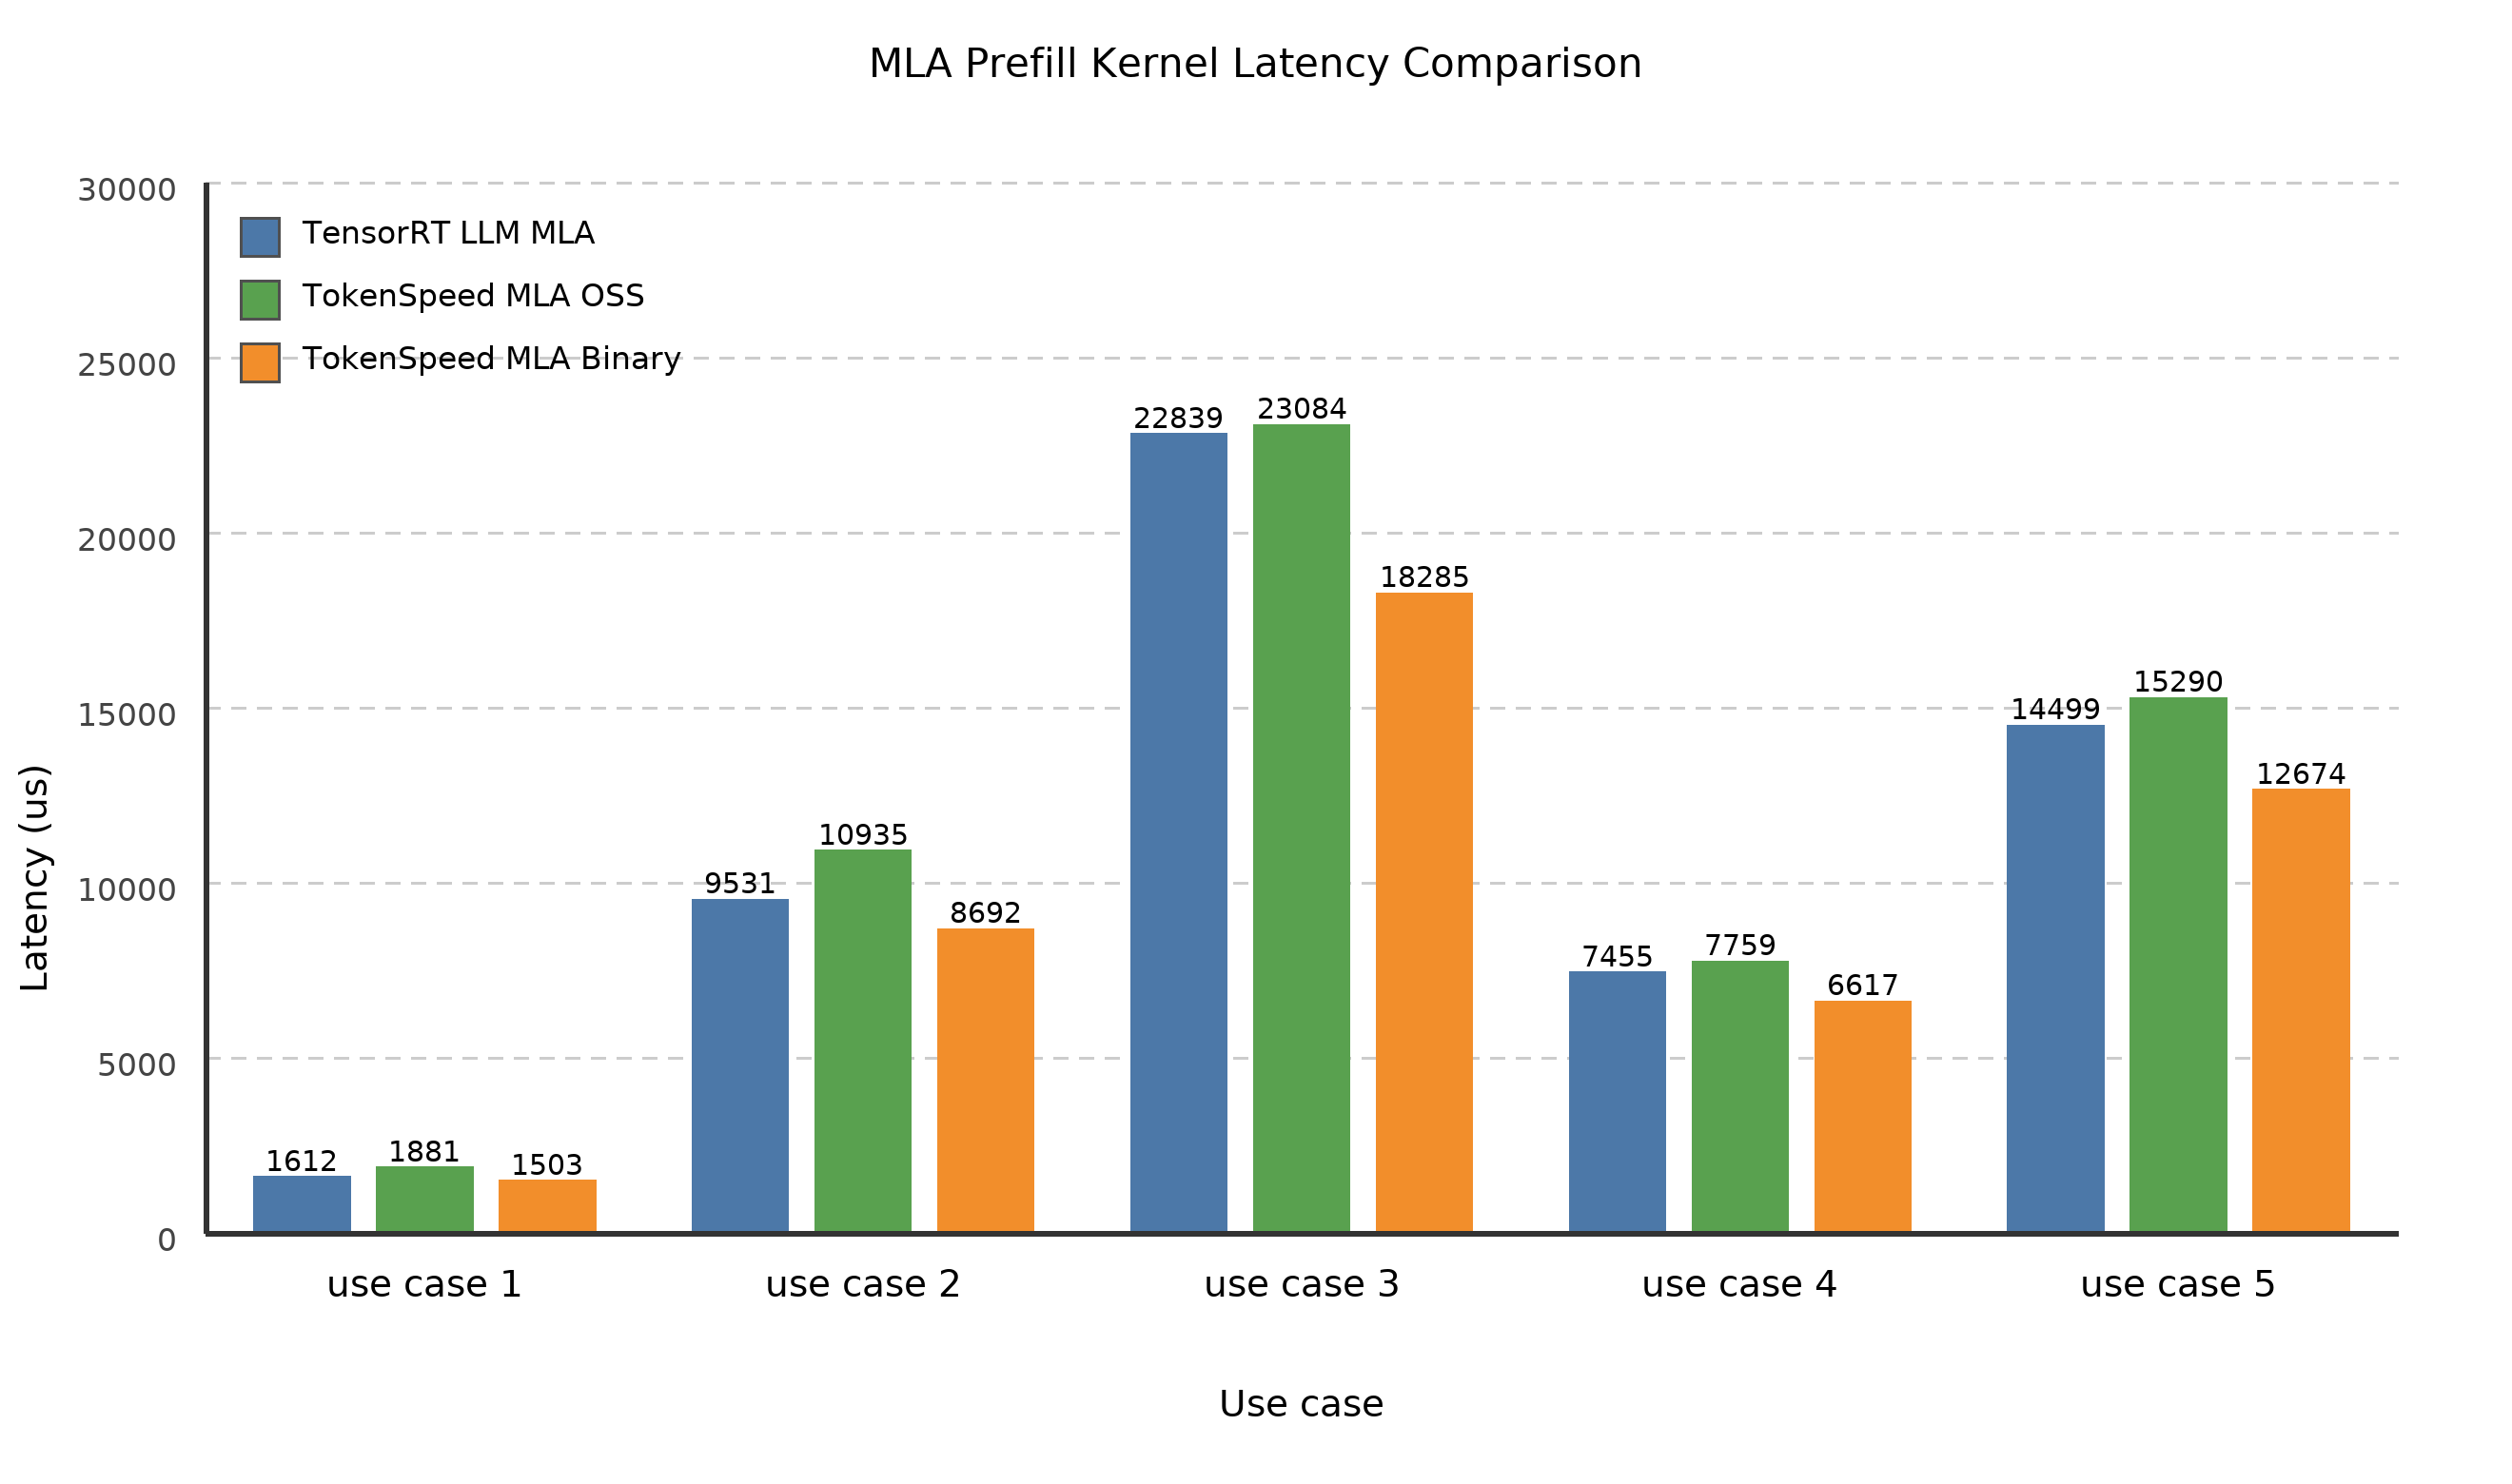
Where:
use case 1: batch_size = 1, seqlen_qo = 8 * 1024, seqlen_kv = 8 * 1024
use case 2: batch_size = 1, seqlen_qo = 8 * 1024, seqlen_kv = 32 * 1024
use case 3: batch_size = 1, seqlen_qo = 8 * 1024, seqlen_kv = 64 * 1024
use case 4: batch_size = 4, seqlen_qo = 512,      seqlen_kv = 80 * 1024
use case 5: batch_size = 4, seqlen_qo = 1024,     seqlen_kv = 80 * 1024
The prefill comparison above includes historical results from an AOT implementation. Current releases ship the public CuTe DSL JIT implementation; the historical AOT backend is not included in the package.
The performance numbers can be collected using the following command line:
python ./tokenspeed-mla/python/tokenspeed_mla/fmha.py \
  --is_causal \
  --bottom_right_align \
  --in_dtype Float8E4M3FN \
  --out_dtype Float8E4M3FN \
  --q_shape 1,8192,128,192 \
  --k_shape 1,8192,128,192 \
  --warmup_iterations 10 \
  --iterations 10 \
  --skip_ref_check
Decode Performance
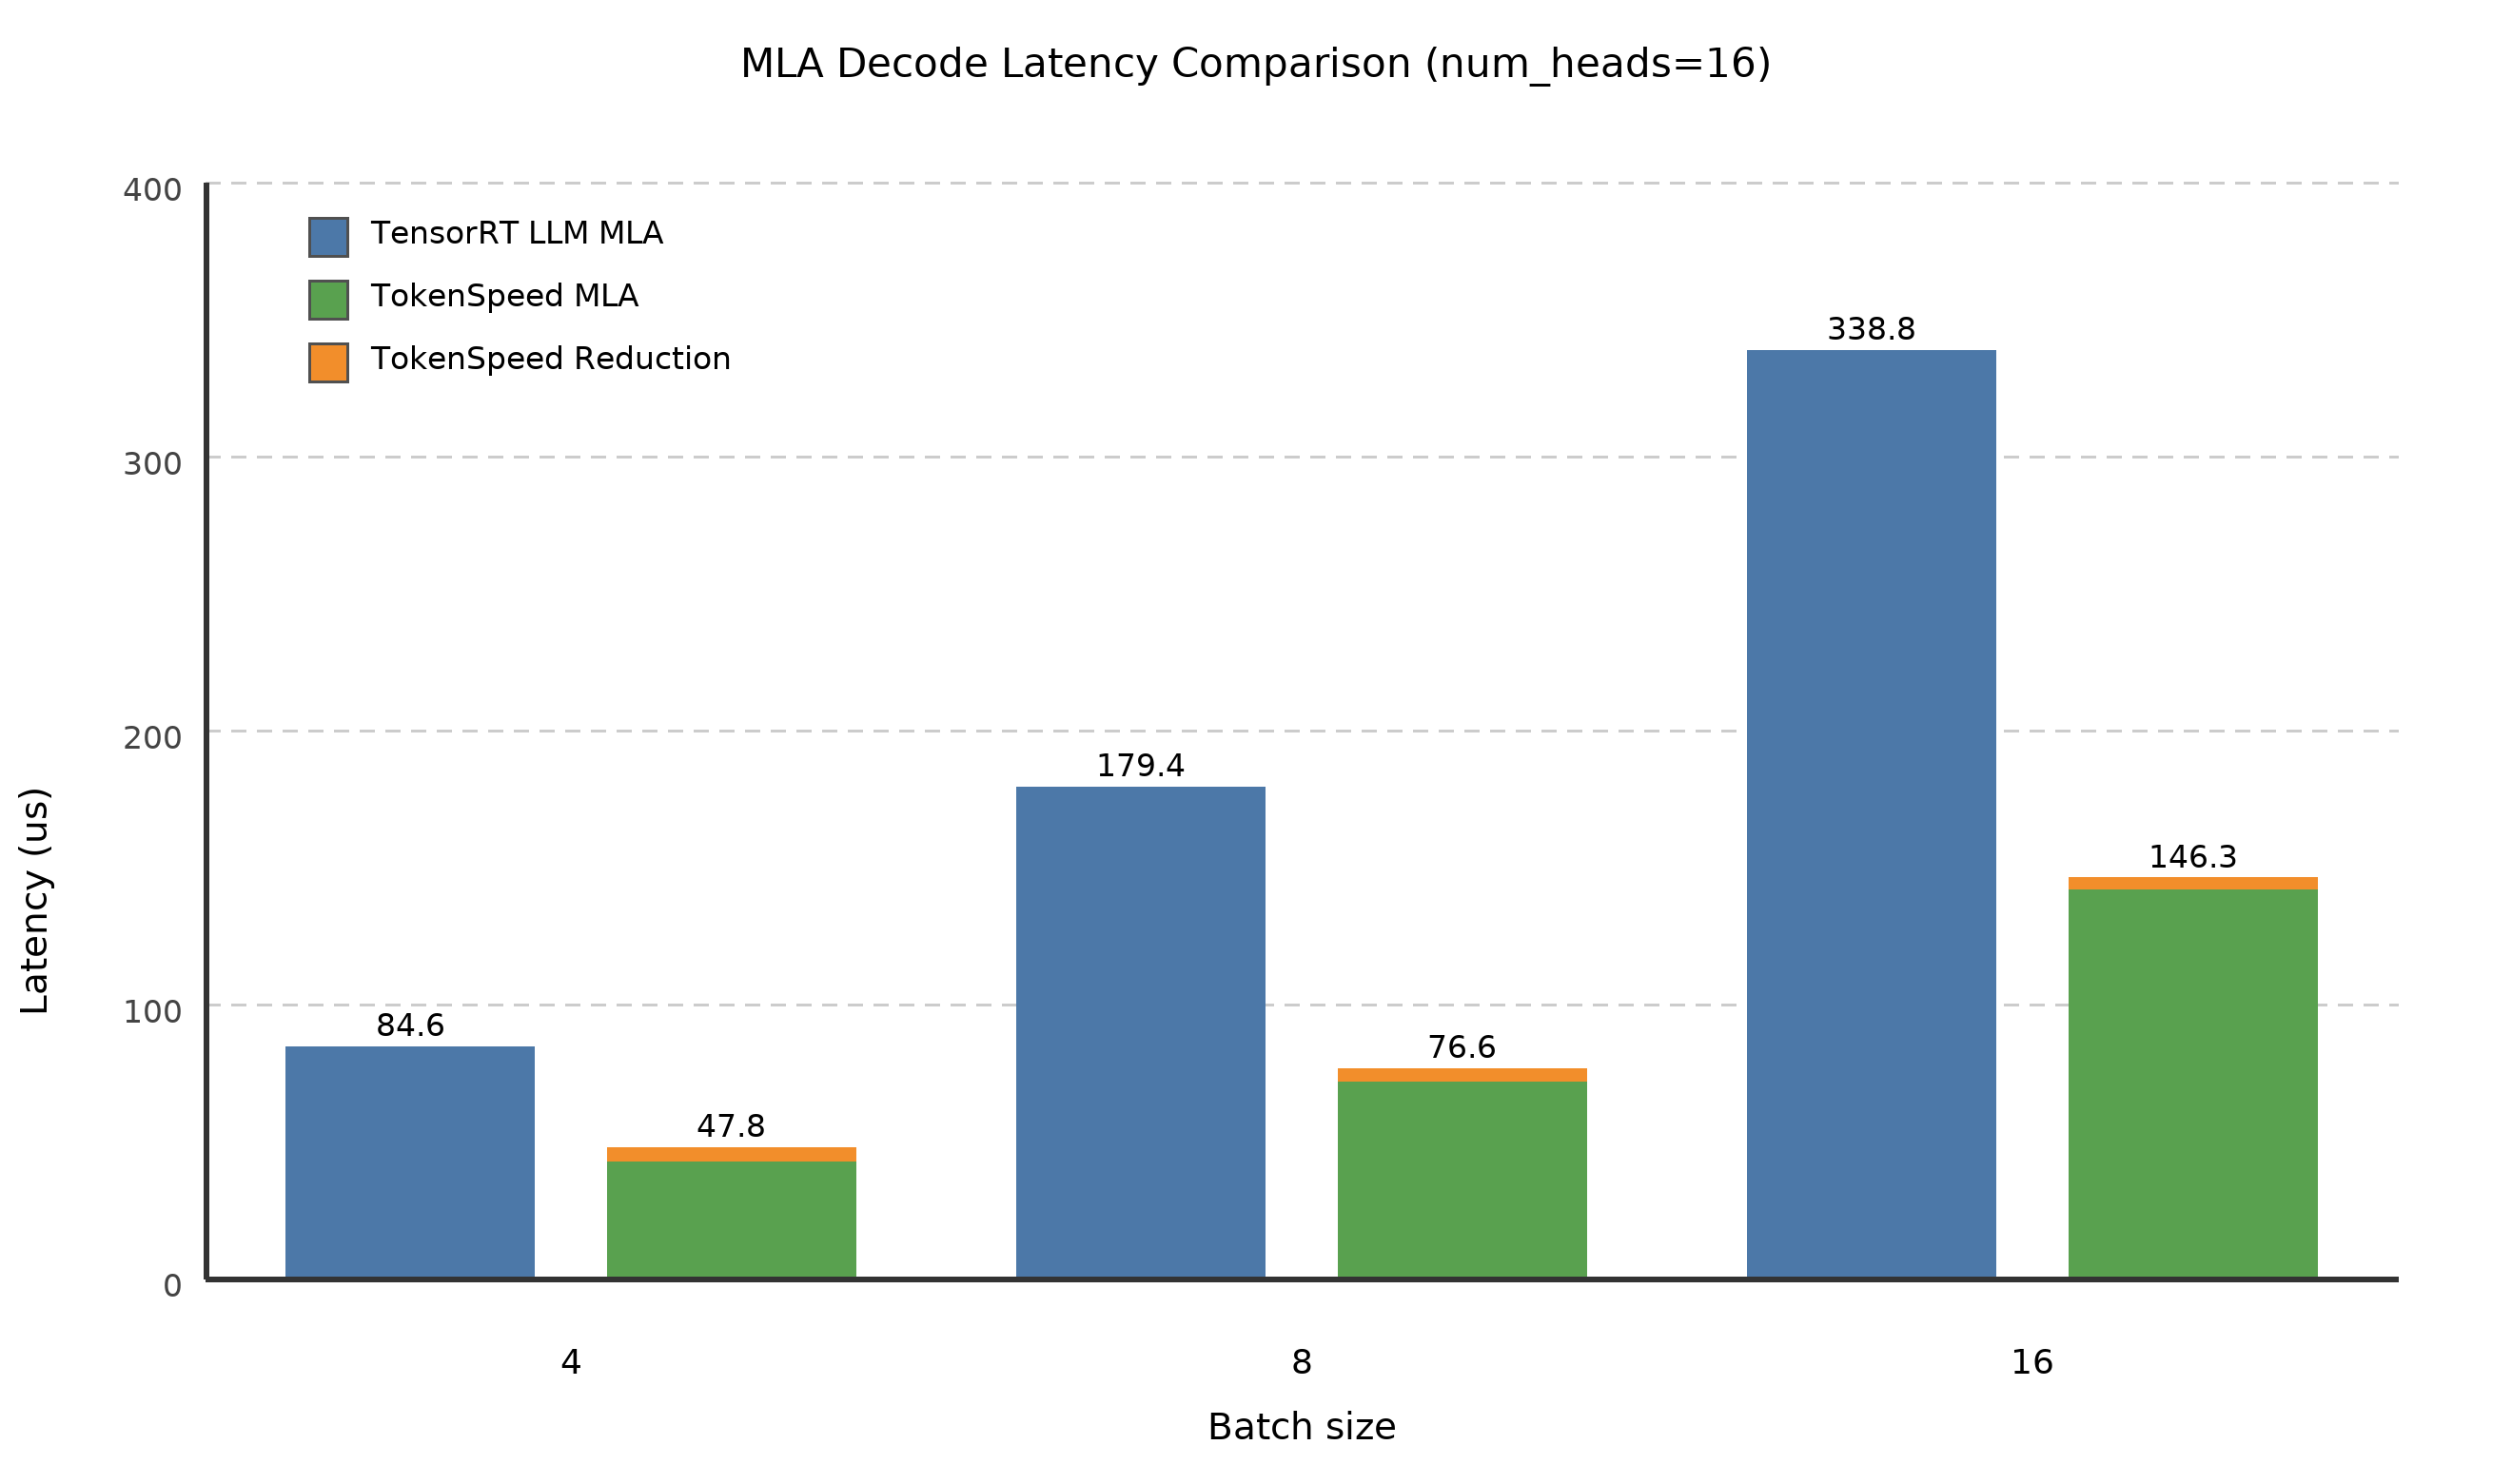
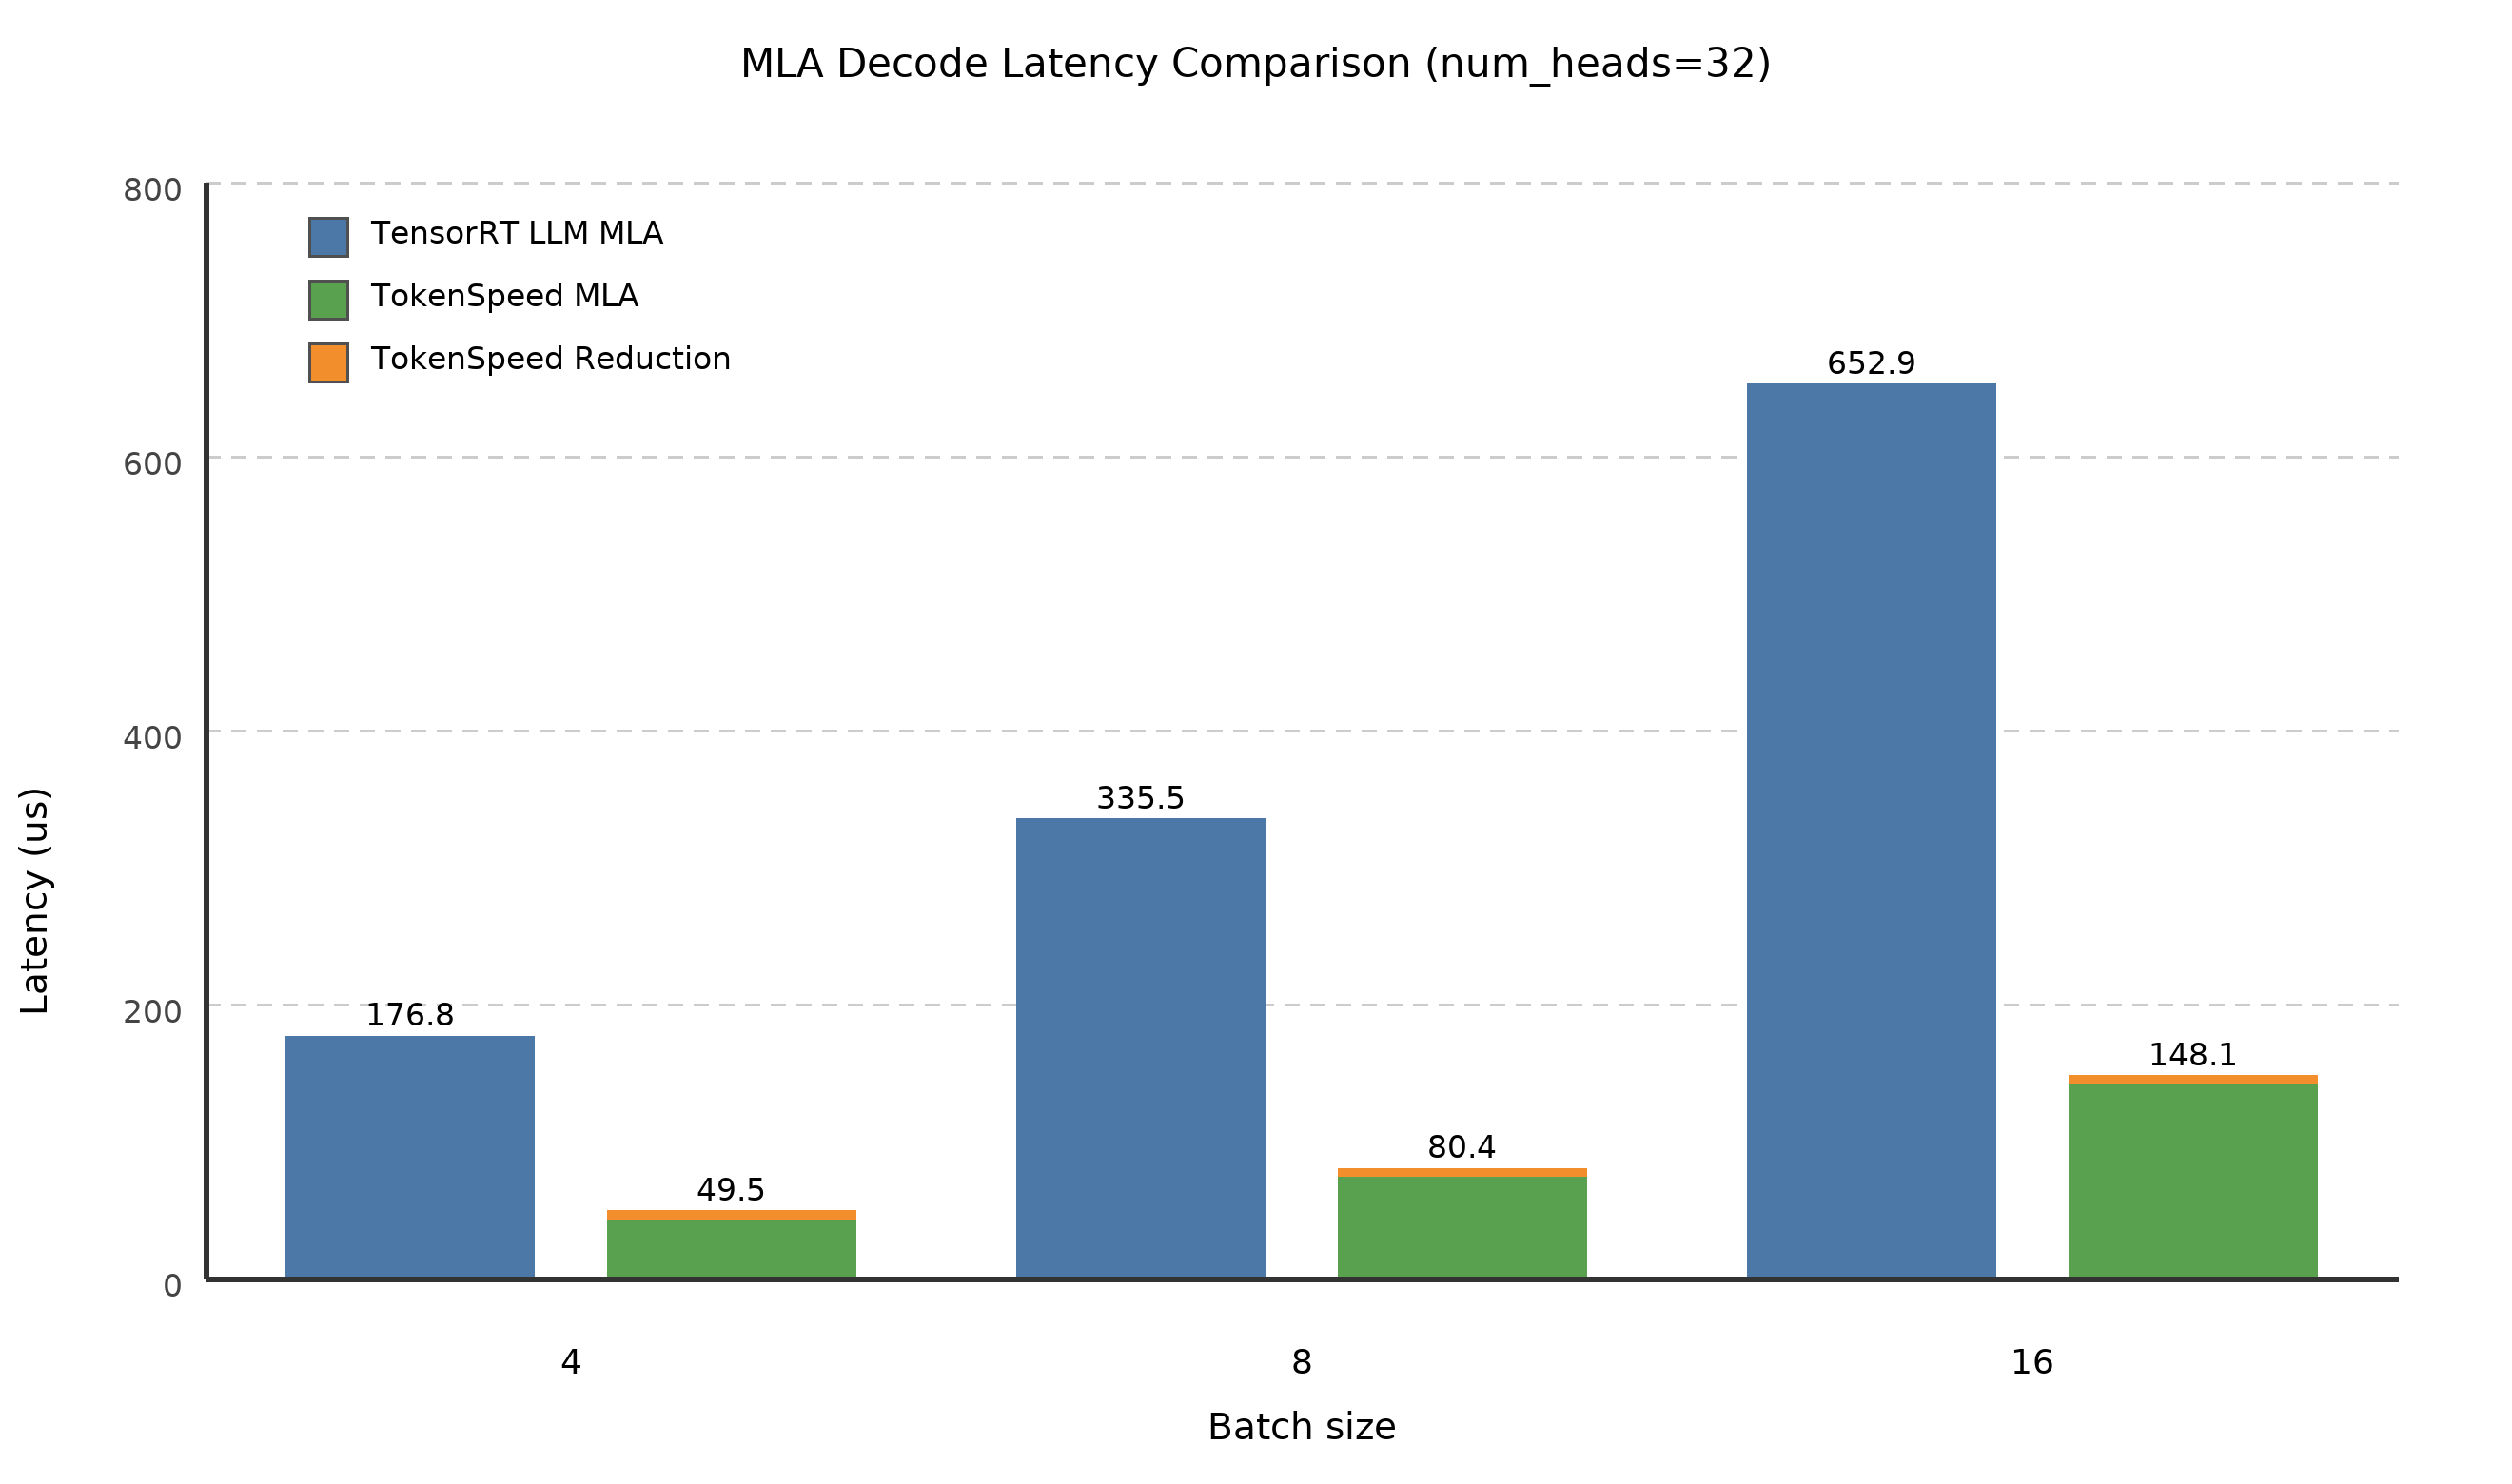
In the above test cases, q_seqlen = 4 and kv_seqlen = 80K.
TensorRT-LLM uses a single kernel for MLA decode, which appears to adopt a swap-AB strategy in the tested cases. In contrast, TokenSpeed’s MLA decode kernel uses a two-kernel implementation: one kernel computes the MLA decode with split-KV, and a second kernel performs the reduction of the split-KV partial results.
Key Optimization of TokenSpeed MLA decode kernel: Group q_seqlen and num_heads into BMM1 M
In mla_decode.py, mla_decode_fp16.py, and mla_decode_fp8.py, decode uses
fold_sq_factor to partially fold query tokens into the head axis when
num_heads < 128. q_seqlen can be any positive length; the runtime chooses
the largest factor F such that: q_seqlen % F == 0 and
num_heads * F <= 128. If no factor greater than one divides q_seqlen, the
kernel does not fold and schedules the full query sequence dimension directly.
The folded execution shape becomes:
H_eff = num_heads * Fq_seqlen_eff = q_seqlen / F
This improves BMM1 M-dimension utilization and reduces tile waste in small-head
decode scenarios, especially token-by-token agent traffic. Example:
num_heads=64, q_seqlen=4 chooses F=2, so two query tokens are folded into
M (H_eff=128) and the remaining two query groups are scheduled on the
scheduler second dimension (q_seqlen_eff=2).
The public tokenspeed_mla_decode also accepts enable_packed_q=True to
opt into continuous query/head packing on the FP8 and FP16/BF16 M128 paths, adapted from
FlashInfer PR #4178. The default is False, preserving the folded-query
implementation. M64 and token-gapped Q/output views continue to
use that implementation even when the option is enabled.
Packed rows are ordered as query_token * num_heads + head. Each 2-CTA
group owns 128 consecutive rows, including across query boundaries. Thus
H96/Sq4 uses three query tiles instead of four, and H96/Sq8 uses six
instead of eight. Only the final tile may contain padding. This is a tensor
view transformation, with no additional packing kernel. The kernel uses
per-row causal positions and predicates partial output/LSE rows.
For packed queries, auto split-KV uses ceil(H * q_len / 128) query tiles,
and workspace needs B * 128 * ceil(H * q_len / 128) * split_kv * 513 * 4
bytes for D512/FP32 partials, or zero when split-KV is one. Callers enabling
this option must provide sufficient workspace. Output shape, output dtype
(BF16 for FP8; input dtype for FP16/BF16), and base-2 LSE semantics are unchanged.
The FP16/BF16 implementation retains its existing split-KV heuristic, reducer
capacity and PDL waits. The option is part of the
compile cache key. Existing direct kernel callers retain the old layout;
opting in through the public wrapper keeps tiling and workspace consistent.
Sliding-window and DCP masking remain supported; window boundaries use the packed row's original query-token position.
Regression coverage is in tests/test_mla_decode.py. It checks packed-query geometry, split-KV workspace sizing, FP8/FP16/BF16 outputs and LSE, reducer variants, CUDA-graph replay, sliding windows and DCP. From the repository root, select this checkout's sources explicitly:
PYTHONPATH=tokenspeed-mla/python python -m pytest -q tokenspeed-mla/tests/test_mla_decode.py
GPU cases require Blackwell SM100/SM103 and are skipped on other devices.
Add -k 'not TestGPU' to run only CPU checks, or -k TestGPU for GPU checks.
Other optimizations include:
- FP8 split-KV candidates are normalized to nonempty K partitions before workspace allocation and kernel launch. The reducer uses a 32/64-split capacity for the M128/M64 paths and selects 1/2/4 disjoint D512 output bands when the real output rows do not fill the GPU. These changes adapt the split-KV and reducer optimizations from FlashInfer PR #4178 to TokenSpeed's folded-query layout; both reducer settings are included in the compile cache.
- Using 2CTA UTCMMA instruction to reduce shared memory usage.
- Try to use as less mbarrier as possible.
- Split kv loading warp to get more latency hiding ability. After loading K, V is already in the L2 cache. Loading K of next tile will not have to wait for the completion of V loading.
- Using multiple stage (sub-tiling) for STG in epilogue.
The performance numbers can be collected using the following command line:
python ./tokenspeed-mla/python/tokenspeed_mla/mla_decode_fp8.py \
  --batch_size 4 \
  --softmax_scale 0.07216882 \
  --page_size 64 \
  --seq_len_k 81920 \
  --in_dtype Float8E4M3FN \
  --out_dtype Float8E4M3FN \
  --seq_len_q 4 \
  --warmup_iterations 1 \
  --iterations 10 \
  --num_heads 16 \
  --skip_ref_check
Kernel Capability Summary
MLA Prefill (tokenspeed_mla_prefill)
What it supports:
- Ragged varlen prefill without padding:
Q: [sum(q_lens), h_q, d_qk]K: [sum(kv_lens), h_k, d_qk]V: [sum(kv_lens), h_k, d_v]
- Different Q/KV sequence packs (
cum_seq_lens_qandcum_seq_lens_kvcan differ) - Causal and non-causal execution
- Optional LSE return (
return_lse=True) - PDL enable/disable (
enable_pdl) - Kernel compile cache keyed by static config (
dtype,d_qk,d_v, causal, LSE, PDL, etc.) - Skip-correction is enabled in the wrapped FMHA path.
- ex2-emulation (disabled by default on B200, and not supported on B300)
- CuTe DSL JIT backend
Input/output dtype behavior:
- CuTe DSL backend accepts input dtypes supported :
torch.float16,torch.bfloat16,torch.float8_e4m3fn,torch.float8_e5m2- MLA Prefill only support
torch.float8_e4m3fn
- Prefill output tensor is BF16 (
torch.bfloat16) - Optional LSE output is FP32
MLA Decode (tokenspeed_mla_decode)
What it supports:
- Query shape:
[B, q_len, H, kv_lora_rank + qk_rope_head_dim] - KV cache shape:
- 3D:
[num_pages, page_size, D_total] - 4D accepted and normalized internally
- 3D:
- Auto
split_kv+ workspace sizing and caching - Supports FP16/BF16/FP8; FP8 path writes BF16 output.
- Supports
H <= 128and1 <= q_len <= 4; for example,H=64, q_len=4is supported. split_kvandworkspace_sizeare computed and cached from runtime shape/device info.is_var_seq,is_persistent, andenable_pdlaffect scheduling/compile variants.causal_masksupports causal and non-causal execution on FP16/BF16/FP8 paths.window_leftbounds each block row's history: rowisees keys[max(0, K - q_len - window_left + i), k_bound), the wholeq_lenblock pluswindow_lefttokens of context. The kernel starts its KV walk at the window rather than at key 0, so cost tracks the window, not the cache.-1(the default) is full history and compiles the same kernel it always did.- Optional
outtensor reuse is_var_seqandenable_pdlcontrols
Minimal Usage
1) Decode
import torch
from tokenspeed_mla import tokenspeed_mla_decode

# query: [B, q_len, H, D_qk]
# kv_cache: [num_pages, page_size, D_total]
out = tokenspeed_mla_decode(
    query=query,
    kv_cache=kv_cache,
    workspace_buffer=workspace_buffer,  # torch.int8, 1D
    kv_lora_rank=kv_lora_rank,
    qk_rope_head_dim=qk_rope_head_dim,
    block_tables=block_tables,          # [B, max_pages]
    seq_lens=seq_lens,                  # [B]
    max_seq_len=max_seq_len,
    softmax_scale=softmax_scale,
    enable_pdl=False,
)
2) Prefill
import torch
from tokenspeed_mla import tokenspeed_mla_prefill

# query: [sum(q_lens), h_q, d_qk]
# key:   [sum(kv_lens), h_k, d_qk]
# value: [sum(kv_lens), h_k, d_v]
out, lse = tokenspeed_mla_prefill(
    query=query,
    key=key,
    value=value,
    seq_lens=seq_lens,
    cum_seq_lens=cum_seq_lens_kv,
    max_seq_len=max_kv_len,
    batch_size=batch_size,
    softmax_scale=softmax_scale,
    is_causal=True,
    return_lse=True,
    cum_seq_lens_q=cum_seq_lens_q,  # optional, when Q/KV lengths differ
    max_seq_len_q=max_q_len,        # optional
    enable_pdl=False,
)
Releases
The release-tokenspeed-mla workflow
builds a source-only py3-none-any wheel from this repository and publishes it to
PyPI. Packaging does not require a GPU or CUDA compiler; the kernels compile with
CuTe DSL and Triton at runtime.
Before the first release through this workflow, configure a
PyPI Trusted Publisher
for the existing tokenspeed-mla project:
- Owner:
lightseekorg - Repository:
tokenspeed - Workflow filename:
release-tokenspeed-mla.yml - Environment:
pypi
Release steps:
- Merge kernel changes, then update
[project].versionintokenspeed-mla/pyproject.tomlwhen a release is needed. Prefer a separate version-bump PR; multiple code changes can share one release. - After merging the version bump, dispatch from
main:gh workflow run release-tokenspeed-mla.yml -R lightseekorg/tokenspeed --ref main. The workflow refuses versions already present on PyPI and checks the wheel's metadata, JIT sources, and license notices before publishing. - Wait for PyPI publication, then use
update-tokenspeed-kernel-mla.ymlwithmla_version=<version>to open the dependency-update PR.
For local packaging checks, use Python 3.12 and install build, packaging,
pytest, and twine in a virtual environment. From the repository root:
(cd tokenspeed-mla && python -m pytest tests/test_release.py -q)
python -m build tokenspeed-mla --wheel --outdir dist
python -m twine check --strict dist/*
python tokenspeed-mla/scripts/check_release.py --package-dir tokenspeed-mla --dist-dir dist
1 maintainer

Release files for tokenspeed-mla 0.2.10
For a detailed explanation of source distributions (sdists) and built distributions (wheels), please see the package formats documentation.
Built distribution (wheel)
| File | Interpreter | ABI | Platform | Reset |
|---|---|---|---|---|
| tokenspeed_mla-0.2.10-py3-none-any.whl | Python 3 | none | any | Details |
Release files / tokenspeed_mla-0.2.10-py3-none-any.whl
| Download URL | tokenspeed_mla-0.2.10-py3-none-any.whl |
|---|---|
| Size | 149.1 kB |
| Tags | Python 3 |
|
SHA-256 checksum How to use checksums |
a39770b718682e23551743b68a2ce36f5140ac2351fe86412343cc4b42aa57d1
|
|
BLAKE2b-256 checksum How to use checksums |
69d0e86381eb77de469597da14c81c994d6b894aeed3213439ccf4dd4ca4918b
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
Yes |
| Uploaded via |
twine/7.0.0 CPython/3.13.14
|
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.


PyPI Publish Attestation
PyPI verified that this artifact, at this checksum, originated from the publisher listed below.
Signed by GitHub Actions, verified by PyPI on Sep 20, 2026.
Transparency log













