
TokenSpeed is a speed-of-light LLM inference engine designed for agentic workloads, with TensorRT-LLM-level performance and vLLM-level usability. Our goal is to be the most performant inference engine for production agentic workloads.
Core components:
- Scheduler: C++ control plane and Python execution plane. Request lifecycle, KV cache ownership, and overlap timing are encoded as a finite-state machine, with safe KV resource reuse enforced by the type system at compile time.
- Kernels: pluggable, layered kernel system with a portable public API and a centralized registry including one of the fastest MLA (Multi-head Latent Attention) implementations on Blackwell for agentic workloads.
- Entrypoint: SMG-integrated AsyncLLM for low-overhead CPU-side request handling.
Differentiation
TokenSpeed takes a fundamentally different architectural approach from existing LLM inference engines. The PyTorch Foundation highlighted these architectural differentiators when welcoming TokenSpeed to the PyTorch Ecosystem Landscape:
TokenSpeed is an open source LLM inference engine and the first to separate the control plane from the execution plane. The control plane is implemented in C++ as a finite-state machine, using the type system to enforce safe resource management, including request lifecycles and KV cache state, at compile time rather than runtime. The execution plane is implemented in Python, enabling fast iteration and lowering the cognitive load for researchers and engineers. This architecture combines strong correctness guarantees in the core scheduling system with the development velocity of a high-level execution layer.
TokenSpeed also treats kernels as a first-class, modular subsystem, separating them from the core engine through a portable public API, centralized registry and selection model, and an extensible plugin mechanism for heterogeneous accelerators.
More importantly, TokenSpeed is the Switzerland of open-source LLM inference engines: neutral because it's backed by the non-profit LightSeek Foundation rather than a commercial company, with serious hardware and engineering support from vendors like NVIDIA and AMD.
News
- [2026/09] Kimi K3 Optimization on GB300 — Part I. [blog]
- [2026/08] Qwen3.8 Flash Next at Day 0 and GLM 5.3 Flash at Day 0.
- [2026/08] Qwen3.8 at Day 0: 2.4T-Scale Inference with TokenSpeed. [blog]
- [2026/08] TokenSpeed joins the PyTorch Ecosystem.
- [2026/07] Kimi K3 at Day 0: Frontier Model Enablement on Leading Platforms with TokenSpeed. [blog]
- [2026/07] TML Inkling at Day 0: FP4 Inference on NVIDIA and AMD with TokenSpeed. [blog]
- [2026/06] Deep dive into the design and optimization of TokenSpeed-Kernel. [PyTorch blog]
- [2026/05] 🚀 TokenSpeed hits 580 TPS on Qwen3.5-397B-A17B for agentic workloads. [PyTorch blog]
- [2026/05] TokenSpeed announced — a speed-of-light LLM inference engine for agentic workloads. [blog]
Blogs and Talks
For technical blogs, conference talks, and engineering articles from LightSeek Foundation, visit the LightSeek Blog.
Sponsors and Partners
LightSeek's work is advanced by the support of sponsors and partners across the AI ecosystem.
Performance Comparison
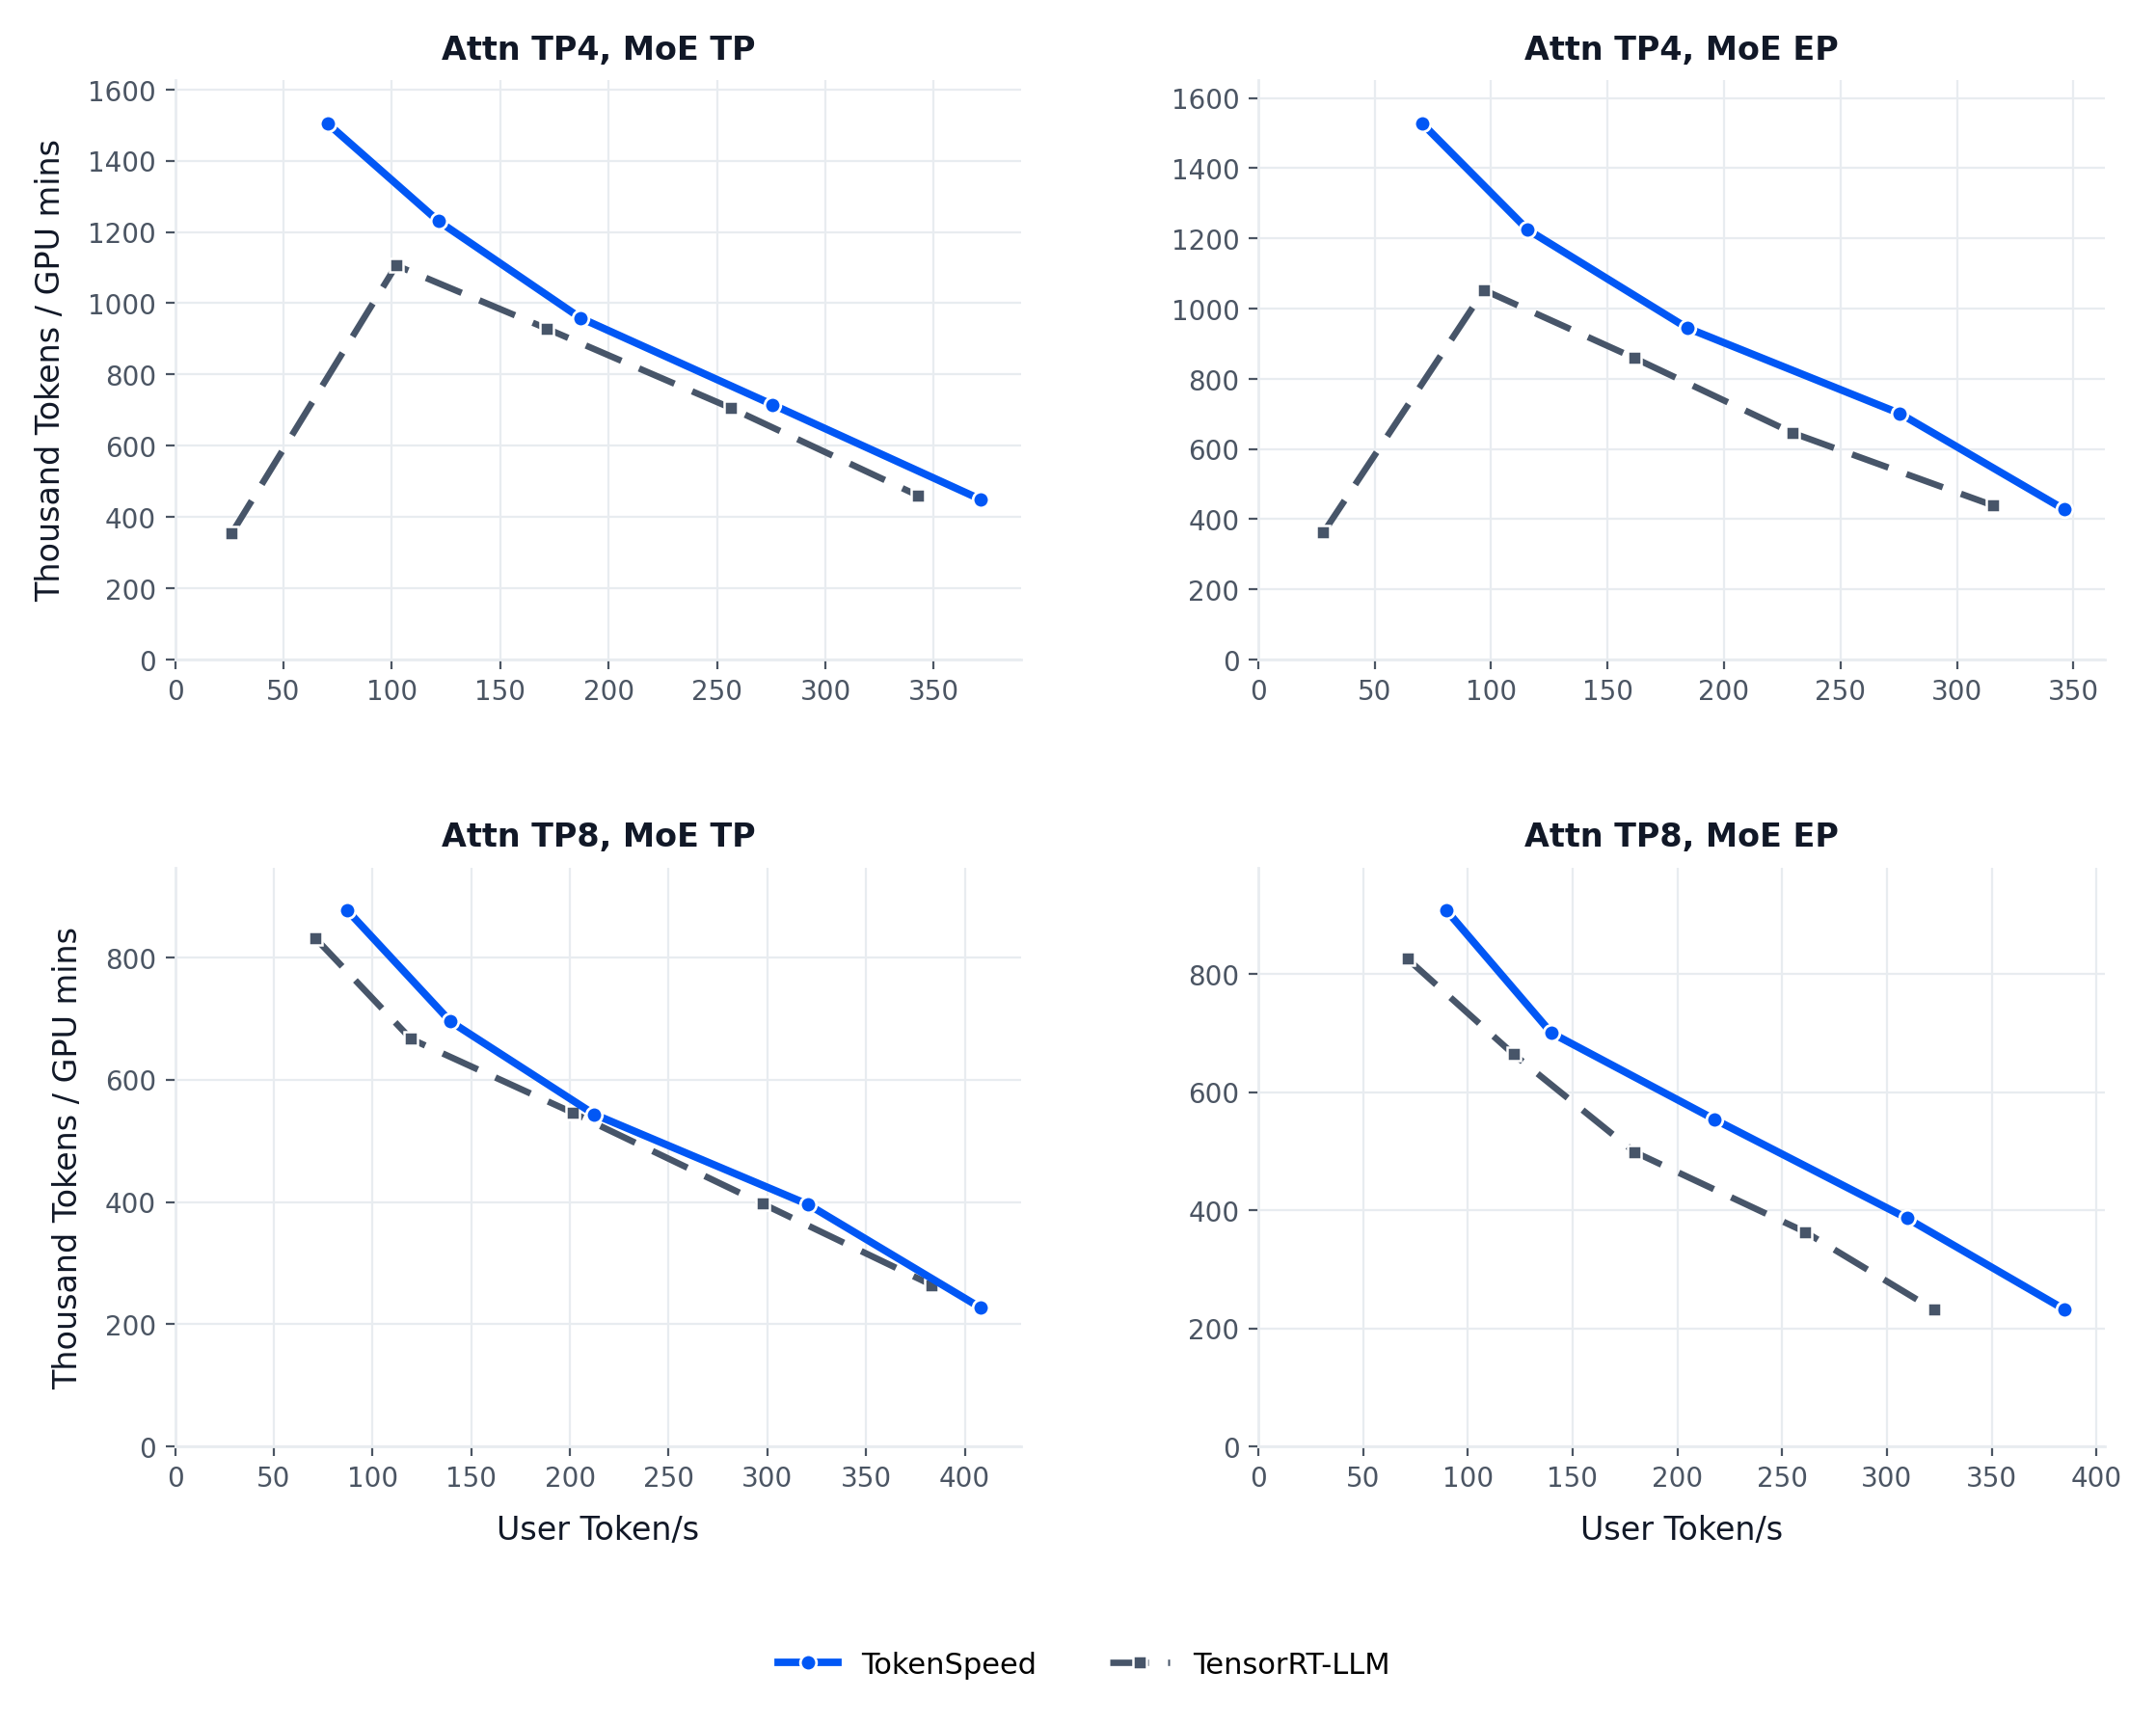
TokenSpeed vs. TensorRT-LLM Pareto curves on agentic workloads (Kimi K2.5, B200)
Documentation
Start here:
- Docs Index
- Getting Started
- Launching a Server
- Model Recipes
- Server Parameters
- Compatible Parameters
- Parallelism
Citation
@misc{tokenspeed2026,
  author       = {{TokenSpeed Team}},
  title        = {{TokenSpeed}: A Speed-of-Light {LLM} Inference Engine},
  year         = {2026},
  howpublished = {\url{https://github.com/lightseekorg/tokenspeed}}
}
1 maintainer

Metadata
1 maintainer
Release files for tokenspeed 0.1.1
For a detailed explanation of source distributions (sdists) and built distributions (wheels), please see the package formats documentation.
Source distribution (sdist)
| File | Size | Uploaded | |
|---|---|---|---|
| tokenspeed-0.1.1.tar.gz | 1.7 MB | Details |
Built distribution (wheel)
| File | Interpreter | ABI | Platform | Reset |
|---|---|---|---|---|
| tokenspeed-0.1.1-py3-none-any.whl | Python 3 | none | any | Details |
Total release size: 4.0 MB
Release files / tokenspeed-0.1.1.tar.gz
| Download URL | tokenspeed-0.1.1.tar.gz |
|---|---|
| Size | 1.7 MB |
| Tags | Source |
|
SHA-256 checksum How to use checksums |
0eb2805de8d2512d78e83240605bc1129e24677e9c932d42e513071982606461
|
|
BLAKE2b-256 checksum How to use checksums |
ef8ab1d75e5a757ae0a5a28fc472327ac8f4b389c540b40332cde84bb7057a6a
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
Yes |
| Uploaded via |
twine/7.0.0 CPython/3.13.14
|
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.


PyPI Publish Attestation
PyPI verified that this artifact, at this checksum, originated from the publisher listed below.
Signed by GitHub Actions, verified by PyPI on Oct 6, 2026.
Transparency logRelease files / tokenspeed-0.1.1-py3-none-any.whl
| Download URL | tokenspeed-0.1.1-py3-none-any.whl |
|---|---|
| Size | 2.3 MB |
| Tags | Python 3 |
|
SHA-256 checksum How to use checksums |
c20d4e87830c821f0b36f665baff999c4d08603b38becc6be33dc2636b97fb19
|
|
BLAKE2b-256 checksum How to use checksums |
3e0367fd749bd05d25de4499f3e0472797f8b48681a86df7f2152416e4ef8221
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
Yes |
| Uploaded via |
twine/7.0.0 CPython/3.13.14
|
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.
PyPI Publish Attestation
PyPI verified that this artifact, at this checksum, originated from the publisher listed below.
Signed by GitHub Actions, verified by PyPI on Oct 6, 2026.
Transparency log













