
Your agent has too many tools and calls the wrong one.
toolhunch searches them, lets a fast decision model pick, and can say “none”.



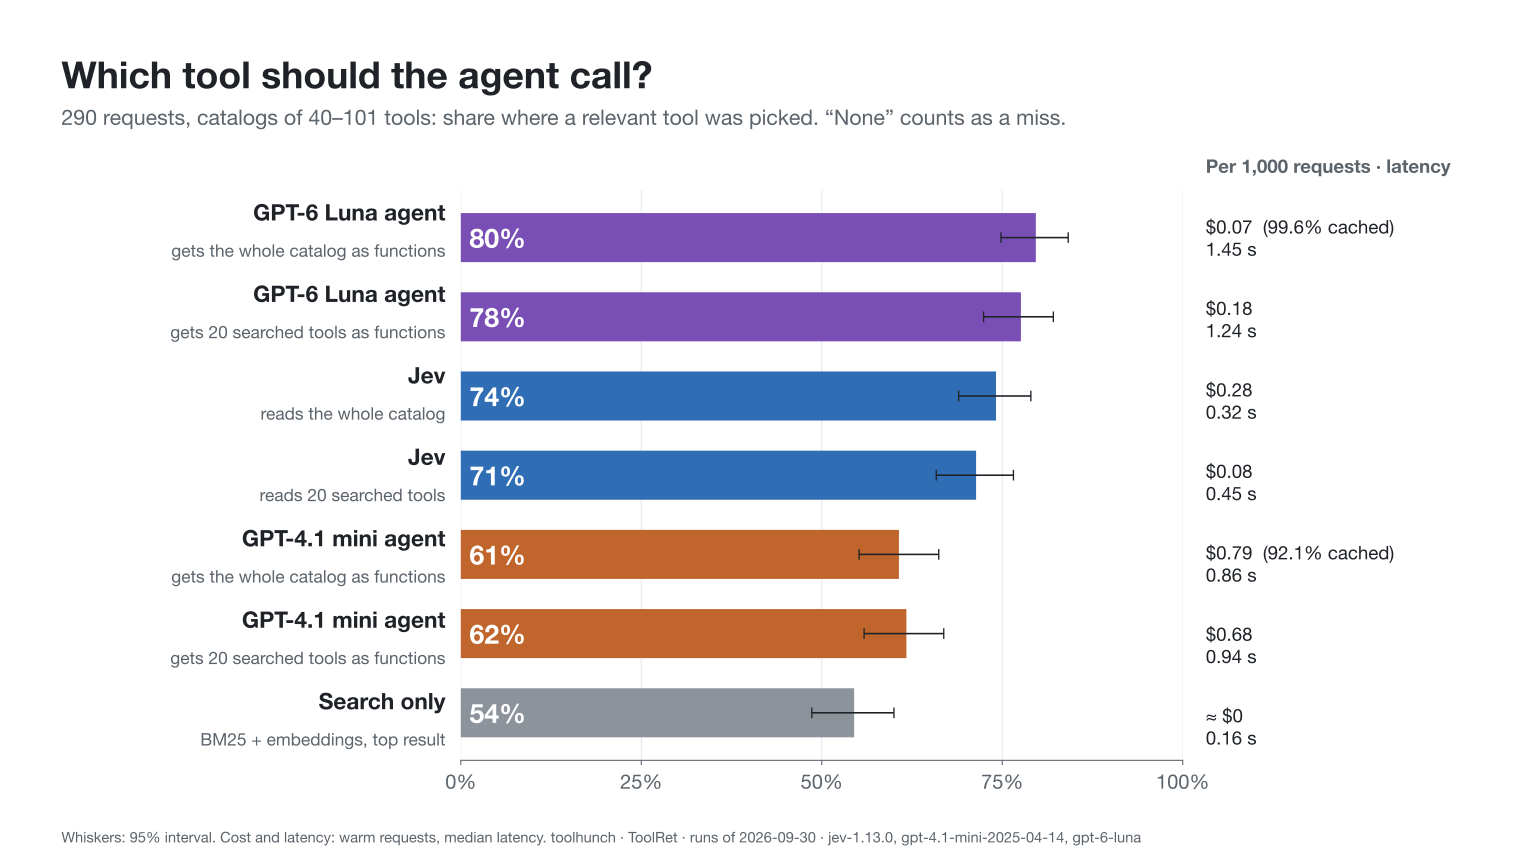
On catalogs of 40–101 tools, a GPT-6 Luna agent given every tool as a function picked a relevant tool for 80% of 290 requests, and so did Cloudflare's Clef reading the whole catalog. Jev reached 74%, rizzo-flow running on a Mac 70% and a GPT-4.1 mini agent 61%. Jev decided in 0.32 s against 1.43–1.45 s for Clef and Luna, and Luna never answered “none”. Results and limits below.
Why search tools at all?
An agent usually receives every tool definition on every call. That is fine for a handful of tools, but:
- Context and cost. Every definition takes context-window space and input tokens on every call.
- Hard limits. OpenAI rejected our request with 200 functions (
array_above_max_length). - Caching helps, within limits. Prompt caching makes a fixed tool list cheaper, but the list still fills the context, and changing it breaks the cache.
What we measured: at 40–101 tools, both GPT agents did about as well with every tool as with 20 searched ones, and caching made the whole catalog cheap (GPT-6 Luna: $0.07 against $0.18 per 1,000 requests). Search earns its place as catalogs grow: hundreds of MCP tools, or ToolRet's 44,453.
How it works
request ──► search (BM25 + embeddings) ──► 20 candidates ──► decider ──► one tool, or “none”
- Search ranks tools by keywords (BM25) and by meaning (embeddings), merged with reciprocal rank fusion.
- A decider reads the request and the candidates, then picks one or answers “none”. It can be a System-1 decision model such as TypeSafe's Jev or Cloudflare's Clef, a Jev-compatible server you run yourself (Strands Decider, rizzo-flow, Laya), or an LLM that ranks the options with its token probabilities (logprobs) or names one as structured output.
- Two ways to use a decider: after search, on the 20 candidates, at any catalog size; or instead of search, reading the whole catalog, when it is small.
The pipeline ranks tools; an integration decides how they reach the agent. The core is framework-free.
Results
The data is ToolRet (Shi et al., Findings of ACL 2025): requests labelled with the tools that solve them, over a 44,453-tool corpus. “Relevant” means one of the labelled tools. These tests measure tool selection on single-turn requests, not task completion. Intervals are 95% bootstrap intervals over tasks; every figure is generated from a published summary.
1. Small catalogs: read everything, or search first?
Four ToolRet catalogs of 40–101 tools, with the same 290 requests for every strategy (chart above):
| Strategy | Relevant tool picked (95% CI) | Cost / 1,000 requests | Median decision latency |
|---|---|---|---|
| GPT-6 Luna agent, whole catalog | 79.7% (74.8–84.1) | $0.07 (99.6% cached) | 1.45 s |
| Clef reads the whole catalog | 79.7% (75.2–84.1) | $1.63 | 1.43 s |
| Clef-flash reads the whole catalog | 78.6% (73.8–83.1) | $0.61 | 0.69 s |
| GPT-6 Luna agent, 20 searched tools | 77.6% (72.4–82.1) | $0.18 | 1.28 s |
| Search, then Clef picks among 20 | 76.9% (72.1–81.7) | $0.44 | 0.61 s |
| Search, then Clef-flash picks among 20 | 76.9% (72.1–81.7) | $0.17 | 0.46 s |
| Jev reads the whole catalog | 74.1% (69.0–79.0) | $0.28 | 0.32 s |
| Search, then Jev picks among 20 | 71.4% (65.9–76.6) | $0.08 | 0.28 s |
| Search, then rizzo-flow picks among 20 | 69.7% (64.5–74.5) | local | 0.57 s |
| rizzo-flow reads the whole catalog | 69.0% (63.4–74.1) | local | 2.95 s |
| Strands Decider 2B reads the whole catalog | 62.1% (56.2–67.6) | local | 0.12 s |
| GPT-4.1 mini agent, 20 searched tools | 61.7% (55.9–66.9) | $0.68 | 0.76 s |
| Search, then Strands Decider 2B picks among 20 | 61.4% (55.9–66.9) | local | 0.16 s |
| GPT-4.1 mini agent, whole catalog | 60.7% (55.2–66.2) | $0.79 (92% cached) | 0.86 s |
| Search only, top result | 54.5% (48.6–60.0) | ≈ $0 | 0.16 s (search) |
| Search, then Laya wide picks among 20 | 40.7% (34.8–46.2) | local | 0.11 s |
| Laya wide reads the whole catalog | 34.8% (29.3–40.3) | local | 0.30 s |
The agent makes one function-calling request; its first call is scored, never executed. GPT-6 Luna runs with reasoning off. Later runs, on the same requests, added the other deciders. Costs and latency are for warm requests, after the first of each catalog; latency is the decision's alone, since some runs searched with query embeddings an earlier run had cached. “Local” deciders ran on one Mac (Apple M5 Max, 128 GB): no money cost, and that machine's latency. rizzo-flow and Laya answer one request at a time, so their latency adds every call of a request: rizzo-flow asks about six questions when it reads a whole catalog. Clef and Clef-flash have no pinned version (runs of 2026-10-04). Limits of these runs has more.
2. 44,453 tools: search, then decide
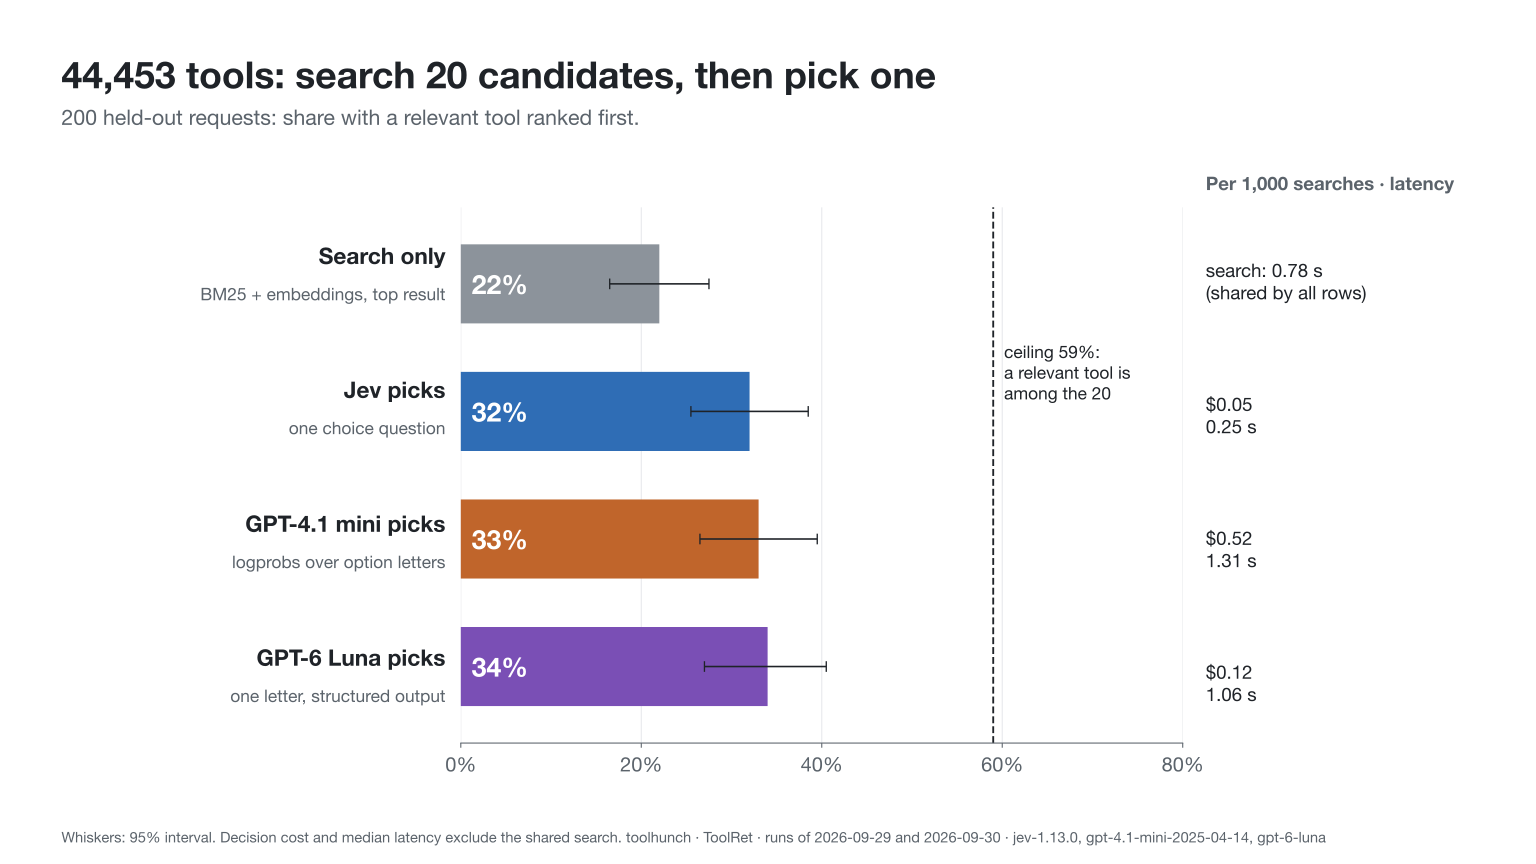
On 200 held-out requests, search alone puts a relevant tool first 22% of the time. A decider over the 20 candidates raises that to 34% (GPT-6 Luna), 33% (GPT-4.1 mini logprobs), 32% (Jev), 31% (Clef) or 30.5% (rizzo-flow, on a Mac): the same precision within the intervals. Jev is the cheapest and fastest hosted decider ($0.05 per 1,000 searches and 0.25 s, against $0.27 and 0.52 s for Clef, $0.12 and 1.06 s for Luna, $0.52 and 1.31 s for GPT-4.1 mini). Strands Decider 2B reaches 28.5% in 0.08 s on the Mac, Clef-flash 24%, and Laya wide, used zero-shot, 20%: no gain over search. Search is the limit: a relevant tool is among the 20 candidates only 59% of the time. With 50 candidates the ceiling is 71.5%, and Jev reaches 37.0%, Clef 36.5% and rizzo-flow 33.5%.
Why GPT-4.1 mini for logprobs? The decider reads the probability of every option letter, and GPT-4.1 mini is the newest OpenAI model we found that returns 20 of them: GPT-5-mini refuses logprobs, GPT-5.4-mini returns at most 5, and GPT-6 Luna at most 5, only with reasoning off. So Luna answers the same prompt with one letter as structured output: no probabilities, hence no confidence threshold and no averaging below.
3. When no tool fits
To test “none”, we remove the labelled tools from some requests and check who notices. The same answer can be read in three ways:
| Reading | The decider… |
|---|---|
| Answer always | must pick a tool |
| Allow “none” | may answer “none of these” |
| Confidence threshold | answers only when its probability is at least 0.95 (chosen on dev data), otherwise “none” |
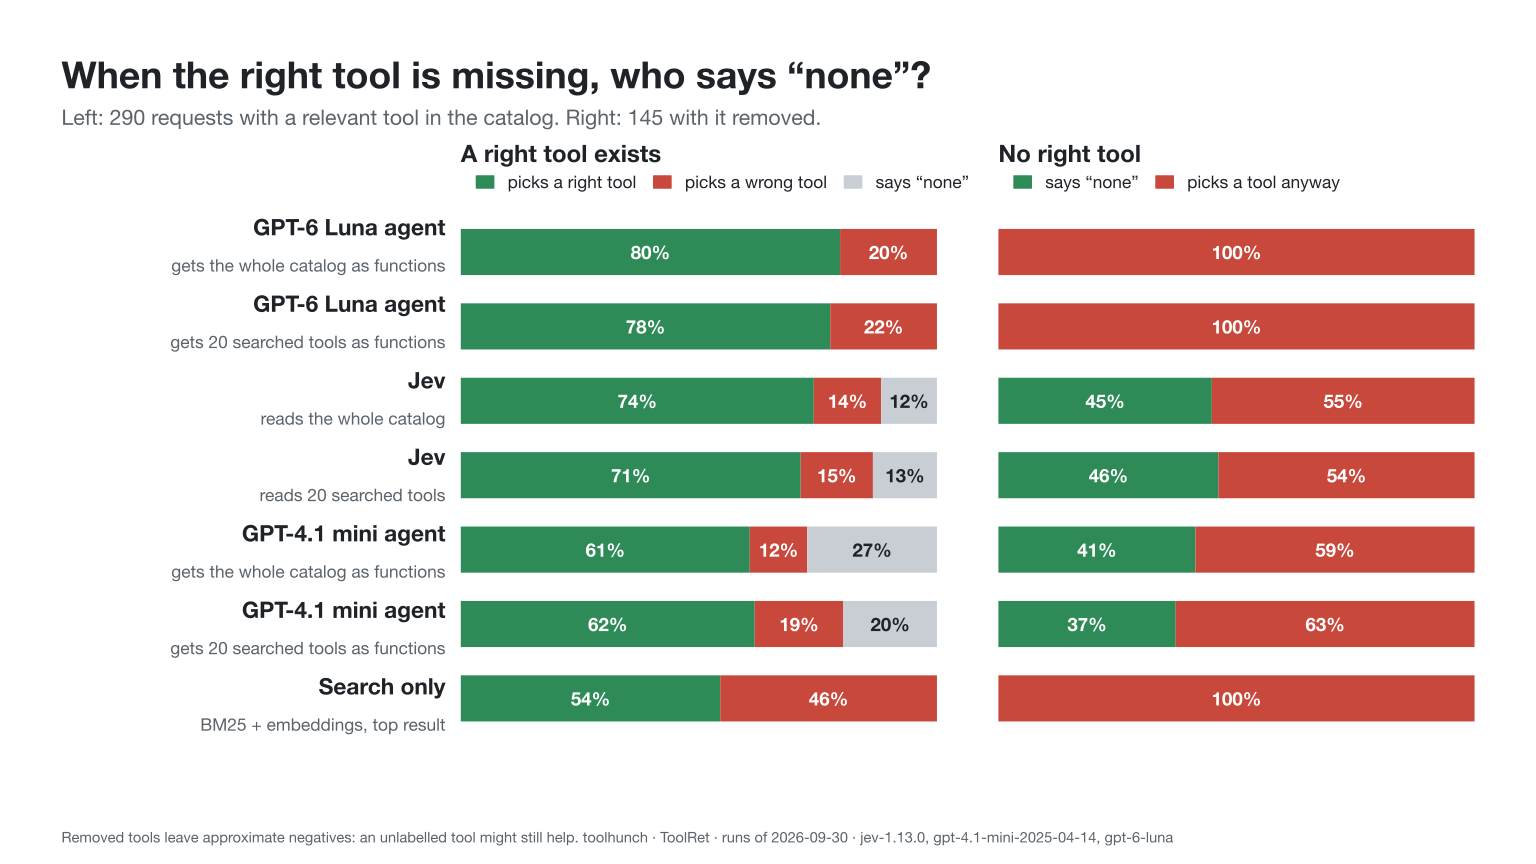
On small catalogs, with “none” allowed: when no right tool existed, Jev said “none” 45% of the time and the GPT-4.1 mini agent 41%, so both usually picked something anyway. The GPT-6 Luna agent never said it: it called a tool for all 145 requests without a right one. When a right tool existed, the GPT-4.1 mini agent said “none” to 27% of requests, Jev to 12%. Among the later deciders, Clef said “none” to 26–31% of the requests without a right tool, Clef-flash 16–25%, Strands Decider 2B 26–37% and rizzo-flow 28–29% (whole catalog and 20 searched tools). Laya wide said it most, 43–58%, but also to 37–40% of the requests that had one.
A threshold is no cure either. At 44,453 tools, on 200 requests with a relevant tool and 200 without:
| Jev, 20 candidates | Right | Wrong | “None” |
|---|---|---|---|
| Answer always | 64 | 336 | 0 |
| Allow “none” | 64 | 265 | 71 |
| Threshold 0.95 | 20 | 29 | 351 |
Without a relevant tool any pick is wrong, so “answer always” is wrong at least 200 times by design. The threshold removed about 9 in 10 wrong picks, and 2 in 3 right ones. GPT-4.1 mini gives 66/334/0, 61/272/67 and 52/215/133 for the same readings; GPT-6 Luna, allowed “none”, gives 60/257/83. For the later deciders a threshold chosen on dev answers even less: at 0.95, Clef answers 12 of 400 requests and rizzo-flow 52.
4. Does the order of the candidates matter?
A common criticism of decision models is that shuffling the options changes the answer. We asked the same 200 questions with the 20 candidates in five orders: search order and four shuffles.
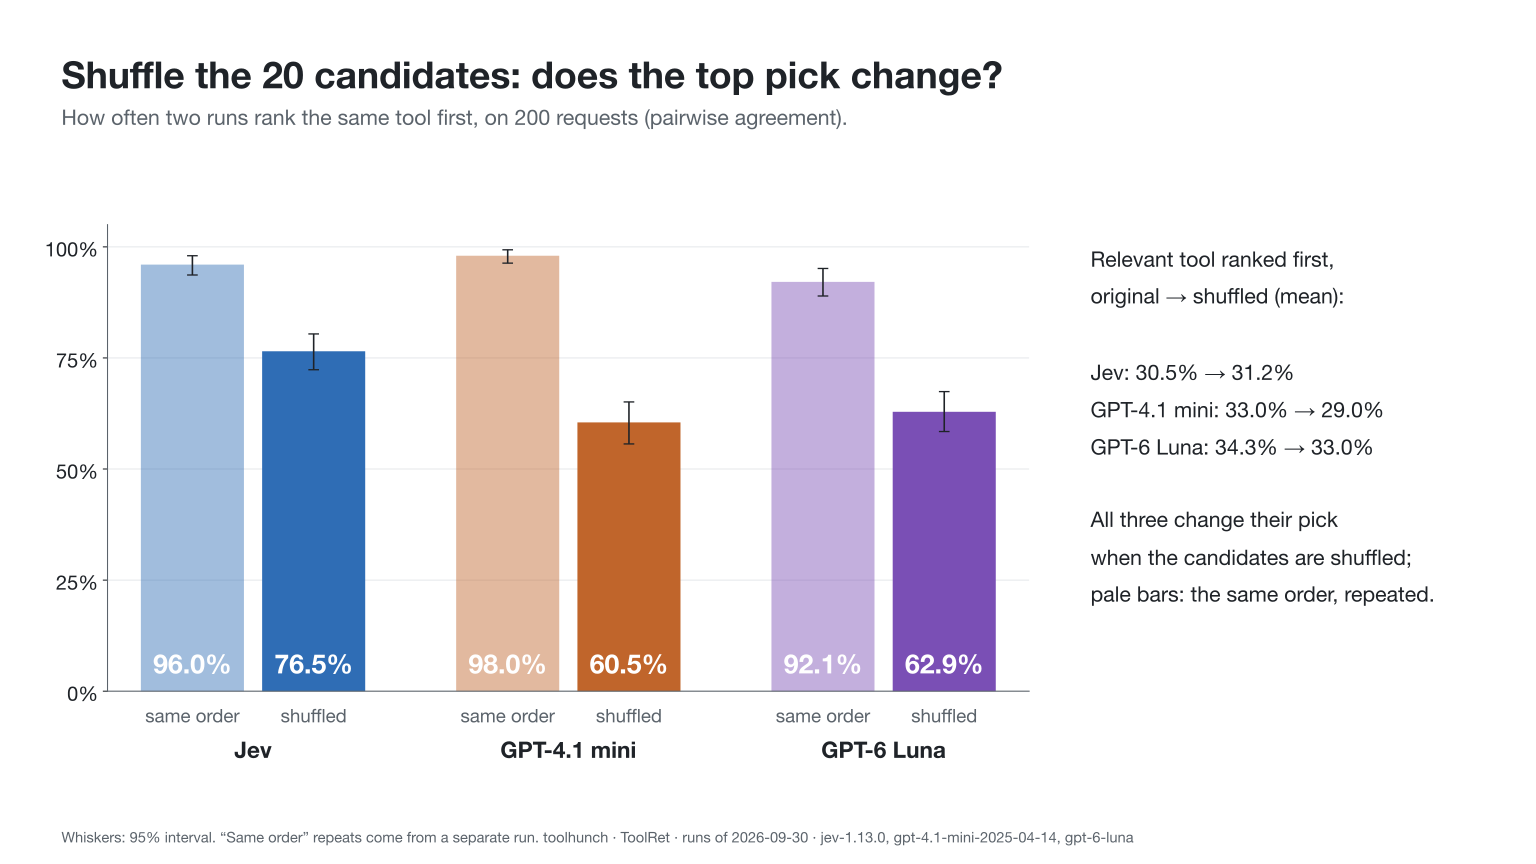
- Most change their pick. Two orders agree on the top tool 76.5% of the time for Jev, 62.9% for GPT-6 Luna and 60.5% for GPT-4.1 mini logprobs, against 92–98% when the same order is repeated; the models run on the Mac agree only 47–52% of the time (rizzo-flow, Strands Decider 2B, Laya wide). Clef and Clef-flash are the exception: 98.5% and 98.0%.
- Precision moved little, except for two. A relevant tool came first 30.5% → 31.2% (mean of the shuffles) for Jev, 34.3% → 33.0% for Luna and 31.0% → 30.9% for Clef; it fell for GPT-4.1 mini (33.0% → 29.0%) and rizzo-flow (30.5% → 26.5%), which do best in search order.
- Position bias. GPT-4.1 mini and Luna picked one of the first three slots 23% of the time, Jev 18.2%; a uniform pick gives 15%.
- Averaging five orders did not help (31.5% Jev, 31.0% GPT-4.1 mini) and costs five decisions per search.
The same-order repeats come from a separate run, so this is an observational comparison; the later deciders gave identical probabilities when a search was repeated, so they have none. Luna's figures use the 198 tasks it answered in every order (it returned an empty answer on 3 of 1,000 asks).
5. Cost and latency
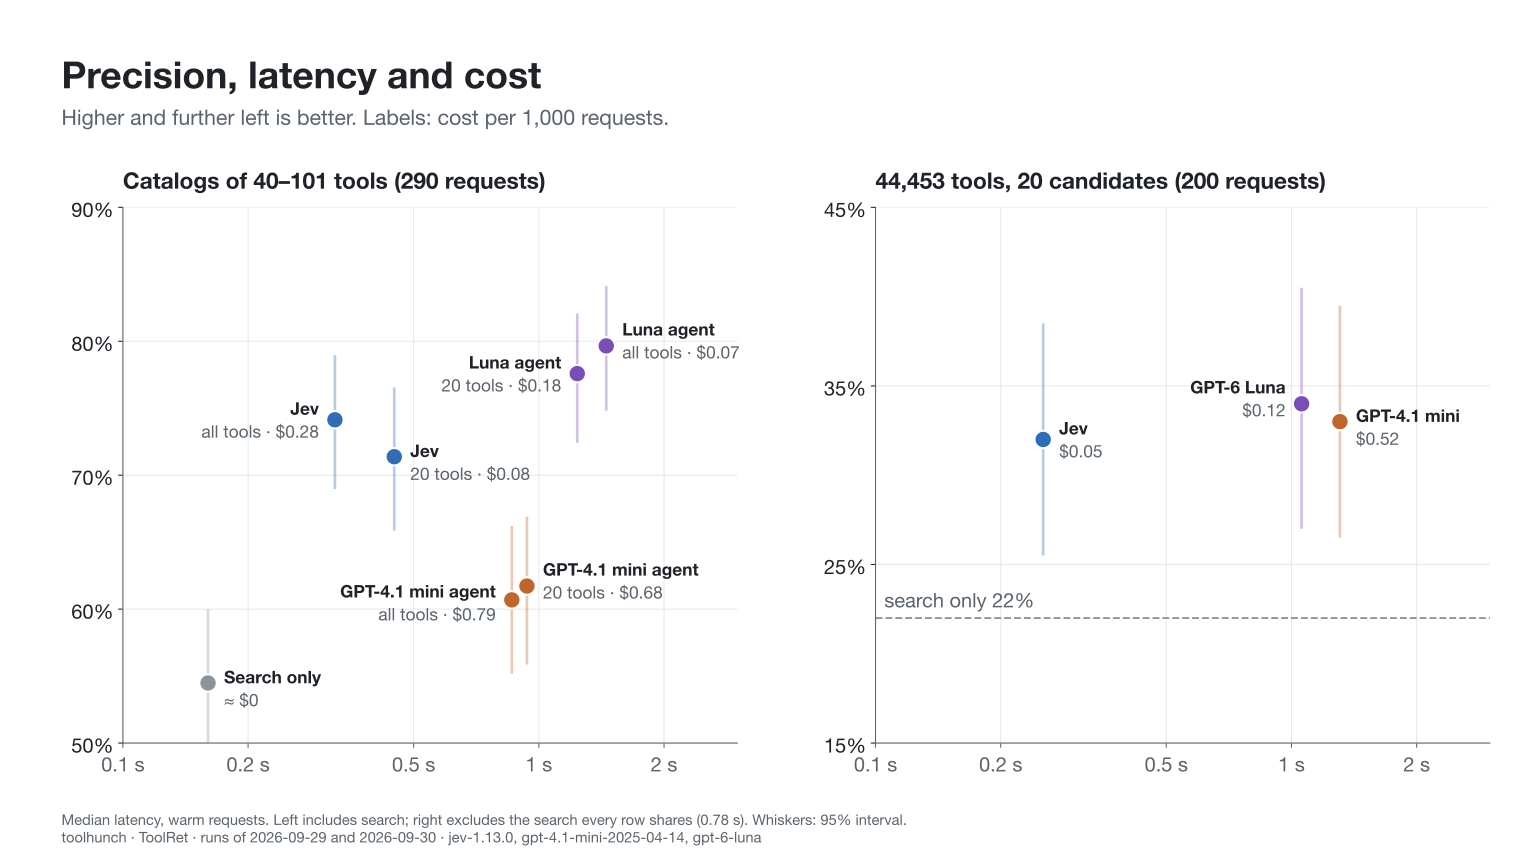
On small catalogs Clef and the GPT-6 Luna agent were the most precise, Luna cheap with its prompt cache and Clef the most expensive, both taking about 1.4 s against Jev's 0.32 s. Clef-flash after search is the compromise: 76.9% at $0.17 per 1,000 and 0.46 s. rizzo-flow, free on a Mac, comes close to Jev after search (69.7%, 0.57 s), and Strands Decider 2B answers in 0.12–0.16 s at 61–62%. At 44,453 tools most deciders tie on precision, and Jev is the fastest and cheapest hosted one.
For the agents given the whole catalog, OpenAI served most input tokens from its prompt cache on warm requests: 92% for GPT-4.1 mini ($0.79 per 1,000 instead of $2.43 at list price) and 99.6% for GPT-6 Luna ($0.07 instead of $0.62). With 20 searched tools the list changes on every request, and nothing was cached ($0.68 and $0.18). Jev's provider-side caching was not measured. Multi-turn agent loops, where caching and tool reveal interact, come next.
Limits of these runs
- Local models ran on one Mac (Apple M5 Max, 128 GB, macOS 26.6.2); their latency is that machine's, and rizzo-flow's speed varied between runs.
- Laya ran zero-shot, with wider budgets than its English checkpoint ships (512/1,024 tokens instead of 192/512, which cannot hold 50 candidates); its authors present it as a base to specialise. About a quarter of its options were shown by name only, because their description was over its 48-token option cap, and 1.6–2.1% by their key alone; 10 of 1,600 searches failed on a tool name over that cap and are left out of its precision; reading the whole catalog, one MetaTool list of 198 tools did not fit two rounds, so MetaTool is left out for it (outside the four catalogs above anyway). Its checkpoint ships an uncalibrated temperature for questions of 11 or more options, which half of its searches asked.
- rizzo-flow refuses an option over 8,000 characters: one 9,700-character tool was shown by its first sentence instead.
- Clef and Clef-flash have no pinned version: Cloudflare may change them under the same name.
The technical page has the protocol, every table, per-catalog results, latency, thresholds and limitations.
Quickstart
pip install toolhunch                  # or: uv add toolhunch
pip install "toolhunch[pydantic-ai]"   # with the Pydantic AI integration
Set TYPESAFE_API_KEY for Jev (and OPENAI_API_KEY for the agent below) in your environment:
import anyio

from toolhunch import Abstention, BM25Retriever, ChoiceDecider, ToolCard, ToolCatalog, ToolSearchPipeline, jev

catalog = ToolCatalog(
    [
        ToolCard(name="get_weather", description="Get the current weather in a city."),
        ToolCard(name="send_email", description="Send an e-mail message to a recipient."),
        # ... the rest of your tools
    ]
)
pipeline = ToolSearchPipeline(
    BM25Retriever(),  # 1. search: keep 20 candidates
    decider=ChoiceDecider(jev("jev-1.13.0"), abstention=Abstention()),  # 2. pick one, or "none"
    k=20,
    top_n=1,
)
result = anyio.run(pipeline.search, ["What's the weather in Milan?"], catalog)
print("none" if result.abstained else result.names[0])
BM25 needs no key; the benchmark uses HybridRetriever with BM25 and OpenAI embeddings. Abstention() adds
“none” without a probability threshold: a threshold belongs to one model, prompt and payload shape, so
calibrate your own.
With Pydantic AI
The same pipeline plugs into Pydantic AI's tool search: deferred tools stay hidden until the decider picks one.
from pydantic_ai import Agent
from pydantic_ai.capabilities import ToolSearch

from toolhunch.integrations.pydantic_ai import reveal_strategy

agent = Agent("openai:gpt-4.1-mini", capabilities=[ToolSearch(strategy=reveal_strategy(pipeline))])


@agent.tool_plain(defer_loading=True)  # hidden until the search reveals it
def get_weather(city: str) -> str:
    """Get the current weather in a city."""
    return f"{city}: sunny, 18 °C (demo)"


print(agent.run_sync("What's the weather in Milan?").output)
A complete script, run offline by the tests, is in examples/pydantic_ai_tool_search.py.
With a Jev-compatible server
Swap the decision model; everything else stays. Each factory declares its server's limits (options, token windows, a source and a date), so the planner fits every question before anything is sent:
from toolhunch.decision import clef, laya, rizzo_flow, strands_decider

decider = ChoiceDecider(rizzo_flow(), abstention=Abstention())  # `rizzo serve` on http://127.0.0.1:8017
# clef("clef-flash")    Cloudflare Workers AI; CLOUDFLARE_ACCOUNT_ID and CLOUDFLARE_API_KEY in the environment
# strands_decider()     `strands-decider serve --strict-window` on http://127.0.0.1:8000
# laya()                `laya-serve`, English checkpoint, on http://127.0.0.1:8010
pipeline = ToolSearchPipeline(BM25Retriever(), decider=decider, k=20, top_n=1)
Small windows make the planner lower card detail or split a choice into rounds; Laya's 48-token option cap is
counted with the planner's tokenizer, so pass one that reads Laya's own tokenizer.json for an exact fit.
JevWireModel covers any other Jev-shaped endpoint, and OpenAILogprobModel OpenAI-compatible endpoints that
return top_logprobs.
Status and roadmap
Alpha: search, deciders and the Pydantic AI integration work; the API may change.
- Multi-turn agents: measure whole agent loops, where prompt caching and tool reveal interact.
- OpenAI Decisions API: announced at DevDay 2026 in limited preview, it answers questions with predefined answers in about 150 ms and is built on GPT-6 Luna. It is the same kind of model as Jev, and the next decider to benchmark against the Luna numbers above once it is available.
Reproduce
The benchmark is not on PyPI. Clone the repository, run the offline checks and regenerate the figures from the published summaries, without API calls:
git clone https://github.com/dfm88/toolhunch && cd toolhunch && uv sync --all-packages
uv run pytest -q
uv run toolhunch-bench readme-charts
The technical page gives report regeneration and paid rerun commands: about $2 for the main 44,453-tool decision calls, $1 for the small-catalog run, under $1 for the GPT-6 Luna runs and about $4 for Clef and Clef-flash; the local deciders cost nothing but time. Every paid command prints an estimate first. See AGENTS.md for development conventions.
License
MIT.
1 maintainer

Metadata
1 maintainer
Release files for toolhunch 0.2.0
For a detailed explanation of source distributions (sdists) and built distributions (wheels), please see the package formats documentation.
Source distribution (sdist)
| File | Size | Uploaded | |
|---|---|---|---|
| toolhunch-0.2.0.tar.gz | 58.0 kB | Details |
Built distribution (wheel)
| File | Interpreter | ABI | Platform | Reset |
|---|---|---|---|---|
| toolhunch-0.2.0-py3-none-any.whl | Python 3 | none | any | Details |
Total release size: 128.4 kB
Release files / toolhunch-0.2.0.tar.gz
| Download URL | toolhunch-0.2.0.tar.gz |
|---|---|
| Size | 58.0 kB |
| Tags | Source |
|
SHA-256 checksum How to use checksums |
f113db92efeadbf60bb3560d7c8df2403eb7afbe3d517cfddce148e653f1e645
|
|
BLAKE2b-256 checksum How to use checksums |
abfb076507f2ac45f2393ee8a3fa1b7ba677637918f0c0bb3a96ff6c71a4d442
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
No |
| Uploaded via |
uv/0.12.4 {"installer":{"name":"uv","version":"0.12.4","subcommand":["publish"]},"python":null,"implementation":{"name":null,"version":null},"distro":{"name":"macOS","version":null,"id":null,"libc":null},"system":{"name":null,"release":null},"cpu":null,"openssl_version":null,"setuptools_version":null,"rustc_version":null,"ci":null}
|
Release files / toolhunch-0.2.0-py3-none-any.whl
| Download URL | toolhunch-0.2.0-py3-none-any.whl |
|---|---|
| Size | 70.4 kB |
| Tags | Python 3 |
|
SHA-256 checksum How to use checksums |
ce1310d54386c402655766a7e6fd8f7d7f006b8482ba46a3649e6e1603b3319d
|
|
BLAKE2b-256 checksum How to use checksums |
921c3badf1b6e307eecc45821ace80ff0aa6c364feebb96d5d36ecec56e71244
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
No |
| Uploaded via |
uv/0.12.4 {"installer":{"name":"uv","version":"0.12.4","subcommand":["publish"]},"python":null,"implementation":{"name":null,"version":null},"distro":{"name":"macOS","version":null,"id":null,"libc":null},"system":{"name":null,"release":null},"cpu":null,"openssl_version":null,"setuptools_version":null,"rustc_version":null,"ci":null}
|














