
traceburn
Find expensive patterns in your AI agent, inspect the calls, and test a change.
Try it in one command
uvx --from git+https://github.com/TommyTranX/traceburn.git traceburn demo
Opens a standalone HTML report. No account, API key, or model call. The bundled
example is explicitly synthetic. Expand a finding and follow its call links.
Use --no-browser on a headless machine; --force replaces a previous demo.
The GitHub command installs the current source. PyPI may still have an older version.
Already installed from current source? Run traceburn demo.
Export a real run for a teammate with traceburn report -o report.html. It uses
the latest trace by default and omits payloads, names, models, raw IDs, and paths.
Review the remaining numeric metadata before sharing. Export details.
The finding that made me build this
I wrote a small support ticket triage agent: five tickets, one tool call each, a roughly 4,700 token static policy prompt sent fresh on every call, model claude-haiku-4-5. Running it uncached cost $0.0539. traceburn's waste report looked at the trace, noticed that same 4,700 token prefix going out uncached on all 10 calls, and estimated that about 82 percent of that spend was avoidable. So I added exactly the one cache_control block it suggested and reran the same five tickets: $0.0167.
That's a 69 percent saving in that run, compared with an estimated 82 percent: about 13 percentage points higher than the observed saving. This small synthetic example illustrates the workflow; it does not establish typical savings or estimator accuracy. The figures and screenshot below describe the original run, not a benchmark of each release.
Prices and model behavior change. You can rerun the paid example at examples/cache_before_after.py. Measured 2026-07-05. The example now stops after at most three API requests per ticket and disables SDK retries. This limits requests, not the dollar charge.
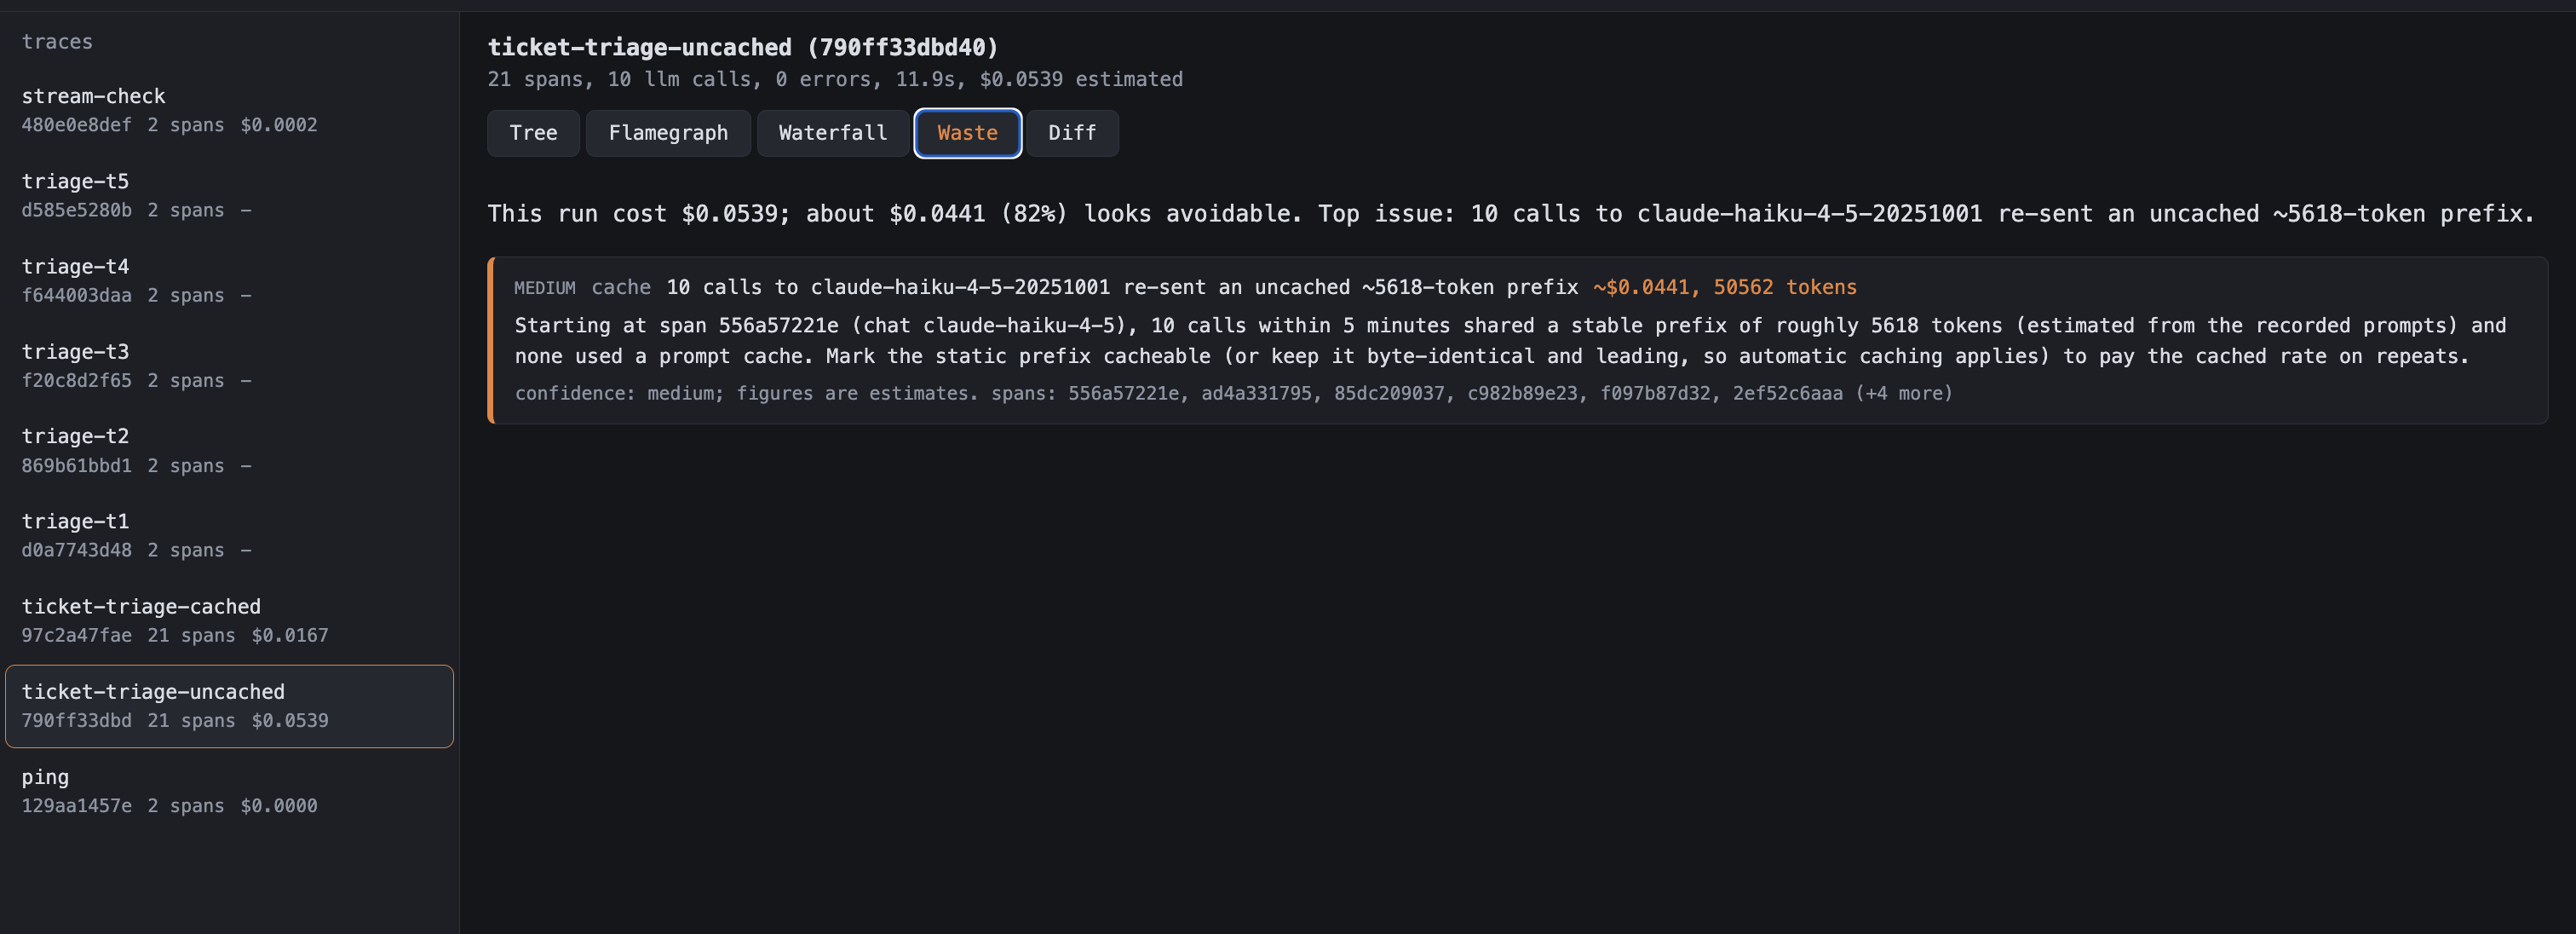
TraceBurn identifies patterns worth investigating: repeated requests, prompt-cache opportunities, growing context, retry loops, and candidates for smaller-model tests. Its findings are heuristics. Inspect the evidence and evaluate task outcomes before changing a workflow. Cost and latency flamegraphs, replay, and run diffs are backed by a local SQLite file. No telemetry leaves your machine.
Install
Core tracer, stdlib only, zero dependencies:
pip install traceburn
Tracer plus the local web viewer (adds starlette and uvicorn):
pip install "traceburn[ui]"
Requires Python 3.10 or later.
Quickstart
Patch the SDKs at the top of your agent:
import traceburn
traceburn.install()

# your existing openai / anthropic code, unchanged
Supported synchronous, asynchronous, and streaming model calls are recorded as spans,
including reported token and cache usage. Wrap your own tool functions with traceburn.span
to record their execution. Traces live in one SQLite file, ./.traceburn/traces.db by default; set
the TRACEBURN_DB environment variable if you want it somewhere else. If you'd rather not touch
the source at all, wrap the run instead:
TRACEBURN=1 python your_agent.py
Then look at what happened:
traceburn ui             # opens the web viewer at 127.0.0.1:8765
traceburn ls              # list recorded traces
traceburn show <id>       # inspect one trace
traceburn waste <id>      # run the waste report on one trace
traceburn fix <id>        # print the literal patch, where one is derivable
traceburn check           # CI cost-regression gate, exits nonzero over budget
traceburn diff <a> <b>    # compare two traces span by span
With the current source installed, try a synthetic run or export a real one:
traceburn demo                         # synthetic report, opens your browser
traceburn show                         # latest trace, no ID to copy
traceburn waste                        # findings for latest trace
traceburn report -o report.html        # standalone export, payloads omitted
traceburn report <id> -o earlier.html  # choose another trace
The demo does not modify your trace database. All of its usage, timing and cost values are invented to demonstrate a repeated request.
What it actually does
Waste report. Heuristics look for duplicate calls, unused cache opportunities, bloated prompts, model overkill, and retry loops. Each finding ships with a confidence level and, where the numbers support it, a dollar figure, so you're looking at "$0.037/run avoidable" instead of a generic warning. More on this below.
Fix. traceburn fix <id> goes one step past the report: for the two waste patterns where a
mechanical patch is derivable from the recorded call alone (a missed Anthropic cache_control block,
a model swap to something cheaper), it prints the literal change instead of leaving you to work it
out.
Check. traceburn check is a threshold gate for CI: fail the build if a traced run costs more
than a dollar limit, if too much of its spend looks avoidable, or if it regressed against a named
baseline trace. A linter for what your agent's calls actually cost.
Trace. traceburn.install() patches the supported OpenAI, Anthropic and LiteLLM
entry points so calls become spans with tokens, latency and estimated cost attached.
Want manual control instead, or you're using a framework outside those adapters? The explicit API, @trace,
span(), and session(), works by hand with anything.
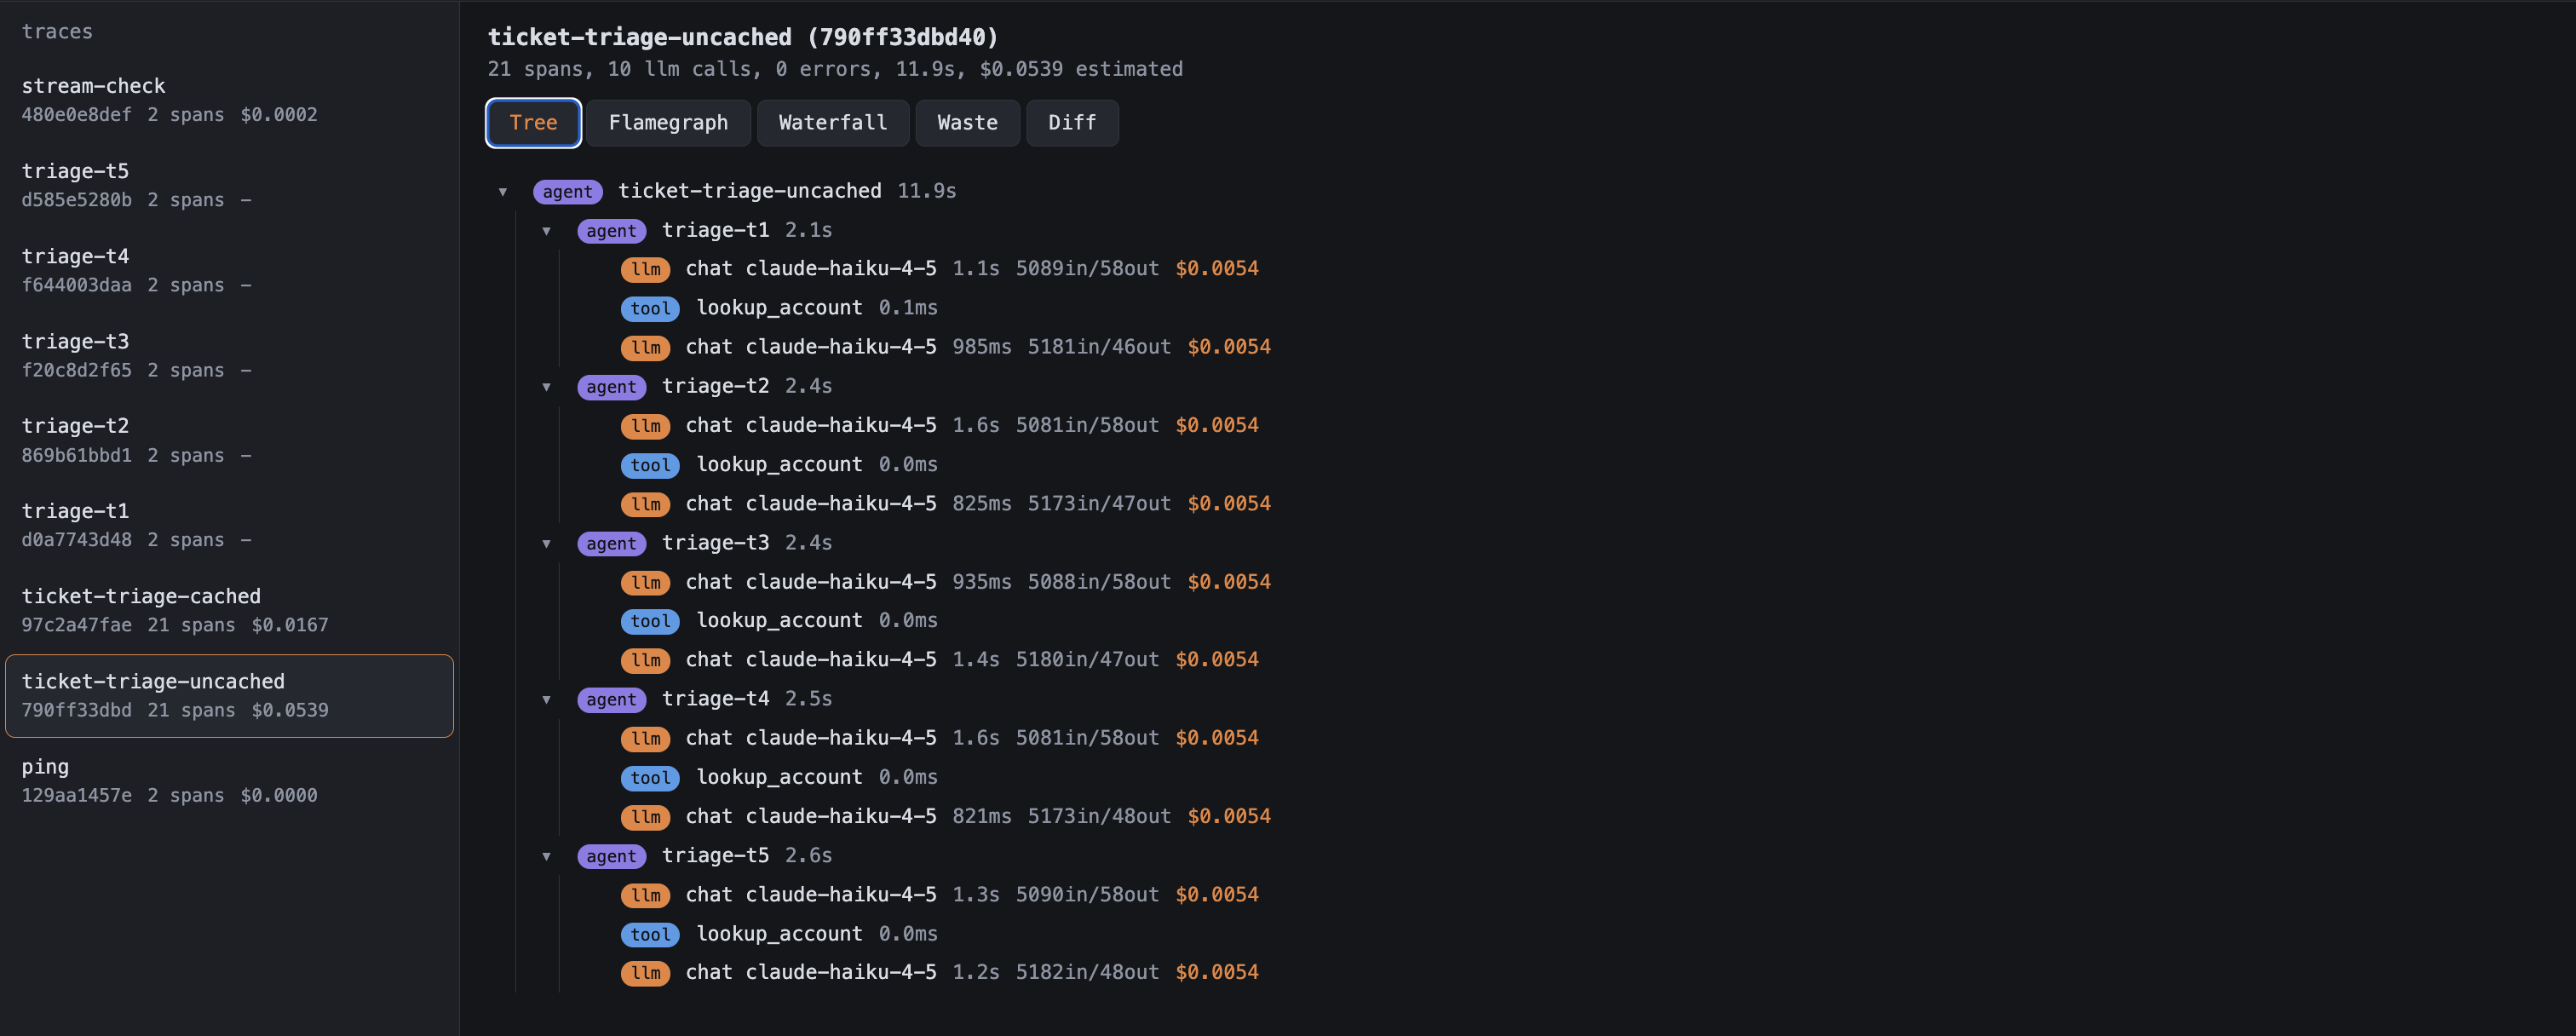
Flamegraph. Spans render as a flamegraph you can size two ways: by wall-clock time or by dollars spent, with self-time kept separate from time spent in children, so a slow parent span doesn't hide which child call actually burned the seconds or the money.
Replay. traceburn.analyze.replay.replay() plays recorded provider responses back through the
real SDK types, so your agent code runs again exactly as before with zero tokens spent. That's
useful for tests and for debugging without burning a budget. Streaming calls aren't replayable
yet; replay currently only serves non-streaming recordings.
Diff. traceburn diff <a> <b> lines up two traces span by span and reports the delta in
tokens, cost, and latency, alongside text diffs of the prompts and responses that changed between
the runs. Good for answering "did that prompt tweak actually help."
The web viewer
traceburn ui starts a small, read-only Starlette API in front of a vendored single-page app: no
build step, no CDN, everything ships in the package. It gives you the trace tree, the flamegraph,
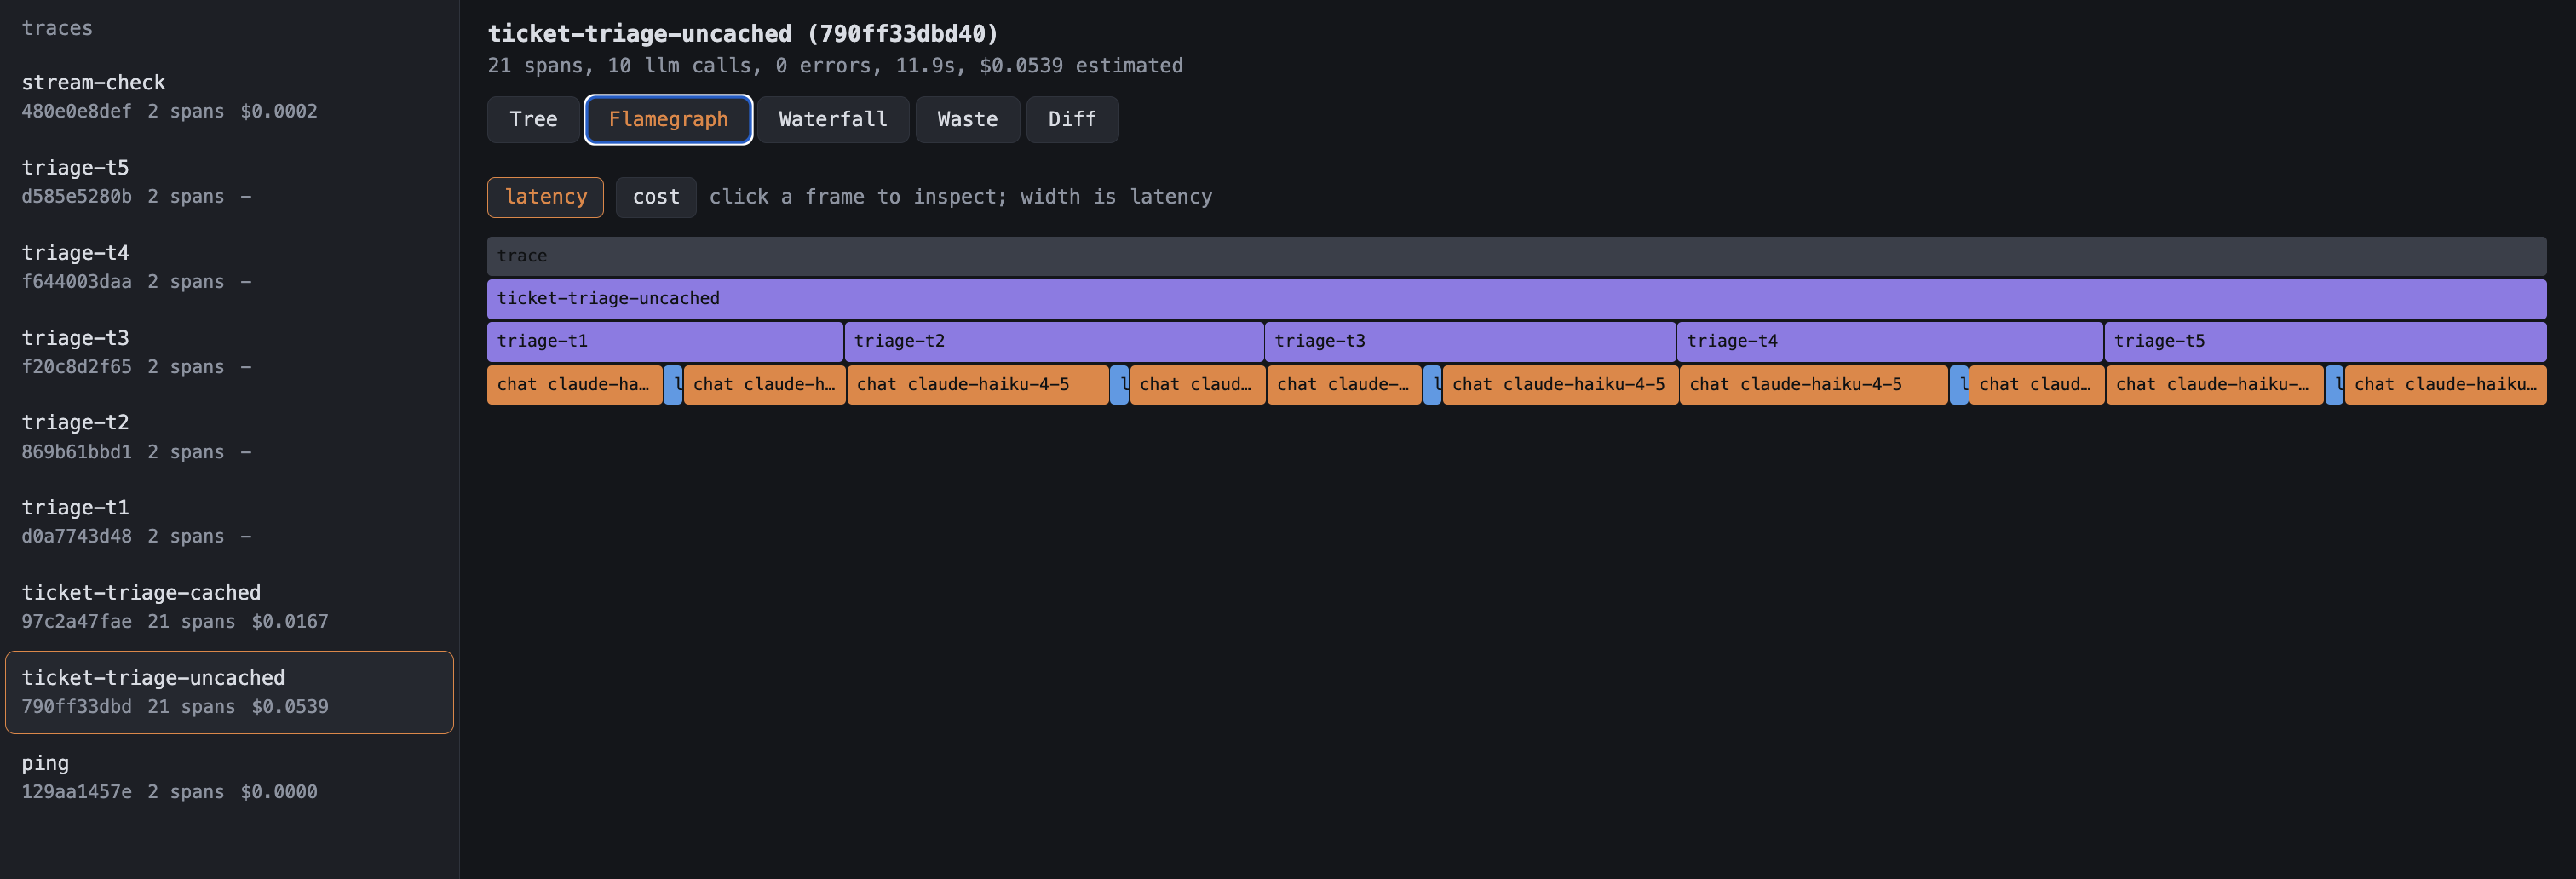
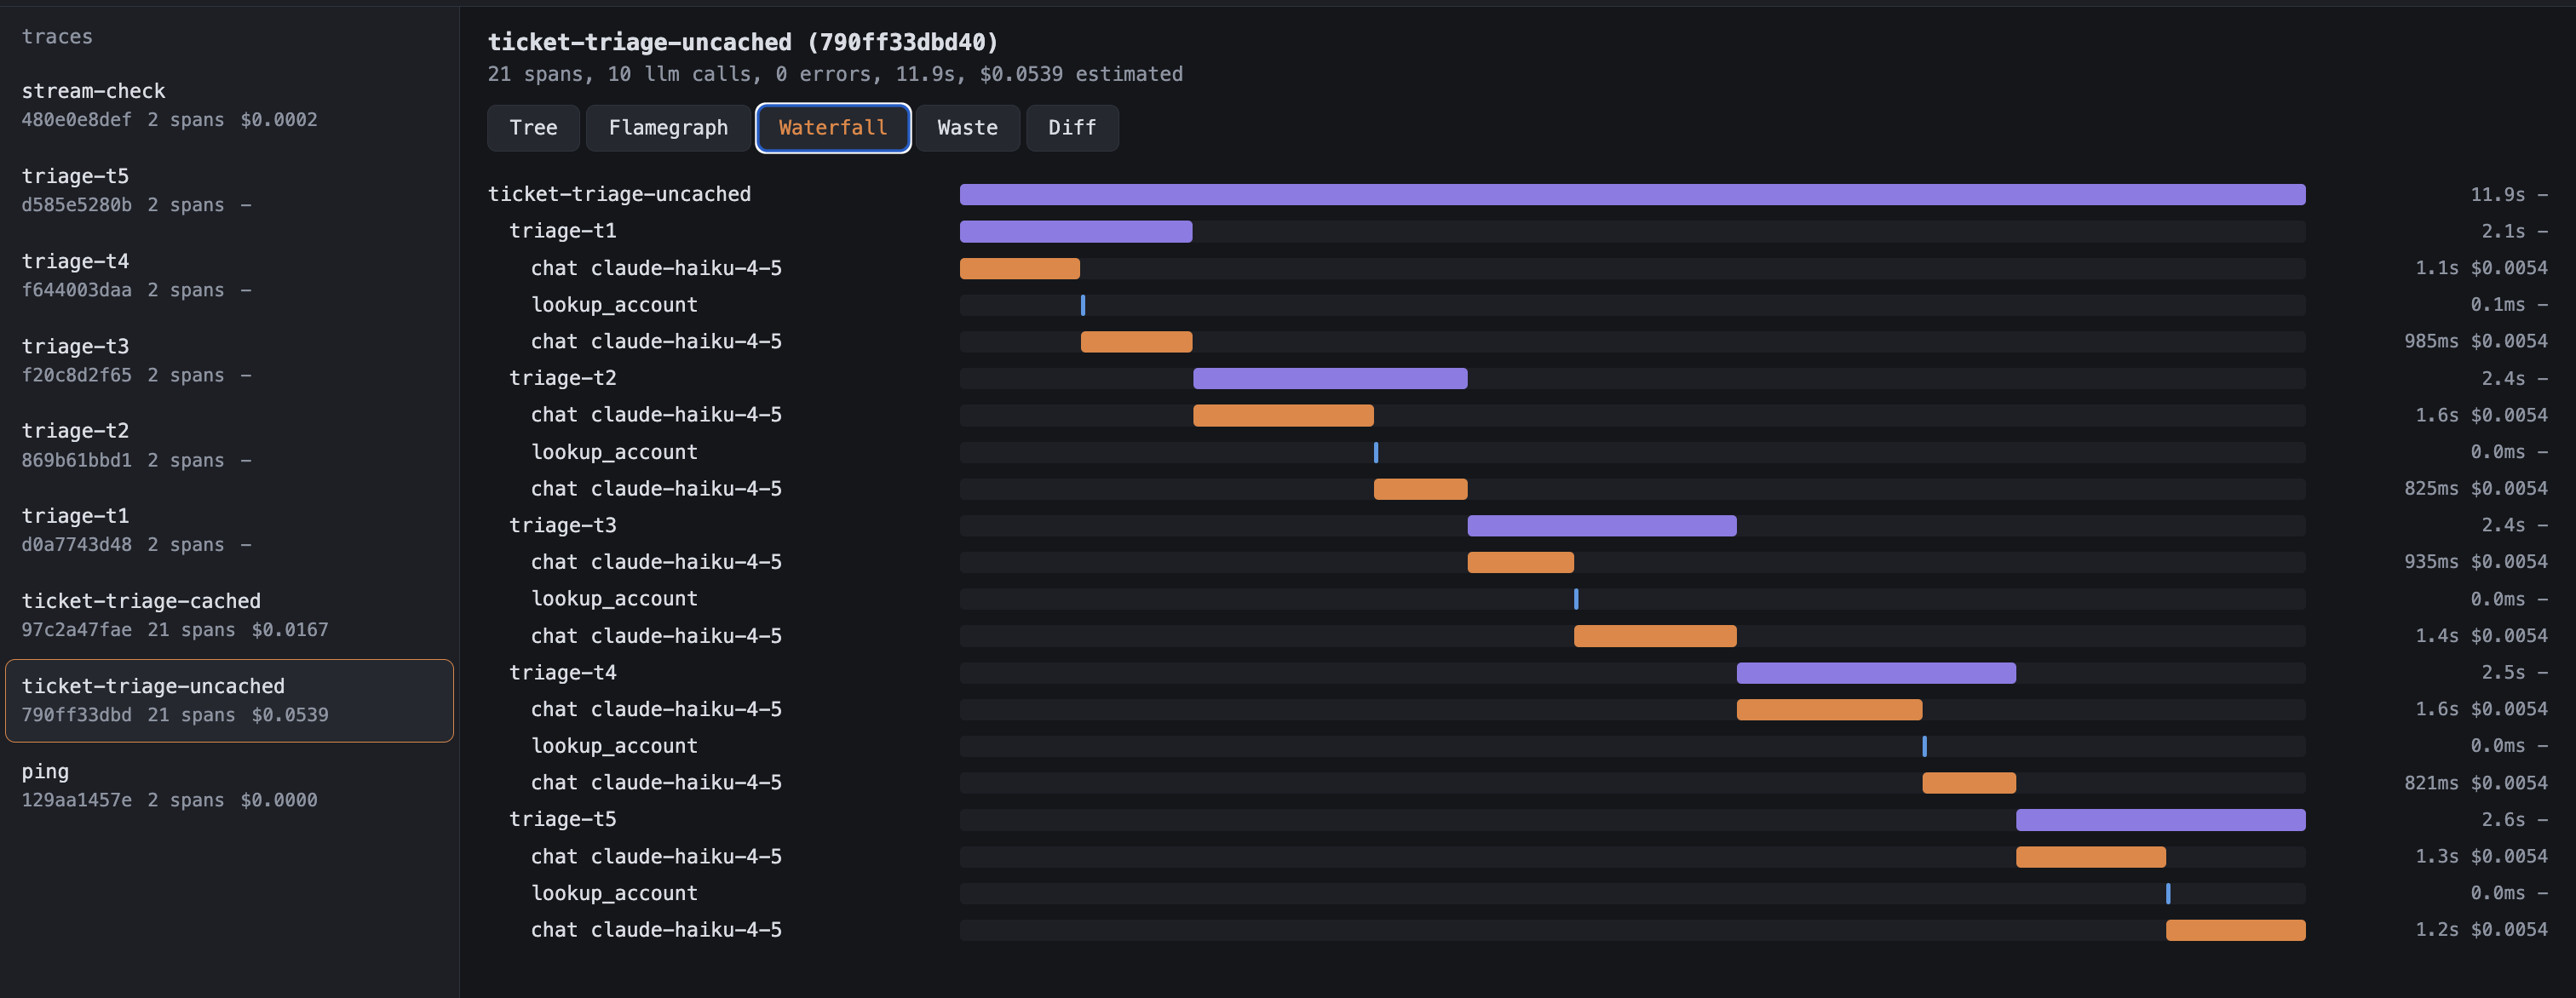
a waterfall timeline, the waste report, and the run diff view.
It binds to 127.0.0.1 only and checks the request's host header against DNS rebinding, but it has no authentication of any kind. That's a deliberate tradeoff: the viewer isn't meant to be reachable from anywhere but your own machine.
Framework support
Today, that means the raw openai and anthropic Python SDKs, plus litellm.completion() /
litellm.acompletion(), all patched automatically by traceburn.install(). The litellm adapter
records whichever provider litellm actually routed the call to, so a trace made through litellm
looks the same as one made by calling the SDK directly. If you're on something else, the explicit
span() / trace() / session() API works with any framework right now, by hand, since it
doesn't care what's making the call. LangChain, LlamaIndex, and anything already emitting
OpenTelemetry GenAI spans aren't instrumented automatically yet. That's real, planned work, not
something already built and just undocumented, and it's covered in the roadmap below.
How the waste rules work
The rules live in traceburn/analyze/waste/ and are documented in full at
docs/waste-rules.md. Five
kinds of waste get checked for: duplicates (exact and near-duplicate repeated calls), cache (a
stable prompt prefix resent without ever hitting a provider cache), context_bloat (duplicate
blocks inside one prompt, or a huge prompt for a tiny output), model_overkill (a frontier-priced
model spent on trivial short calls, phrased as a suggestion and kept at low confidence on purpose),
and loops (retry storms, repeated identical tool calls, or a runaway step count). Every finding
also carries a confidence level: high, medium, low, or info.
Two principles govern all of them. A wrong finding does more damage than a missed one, so the rules are tuned for precision over recall and would rather stay quiet than guess. And no dollar figure is ever printed without observed tokens behind it and a price in the pricing table to multiply against; everything the tool prints is labeled an estimate, because it is one.
Two of the five, cache and model_overkill, sometimes carry enough information to fix
mechanically rather than just flag; traceburn fix renders those. The other three need a decision
only visible in your own source code, so they stay a diagnosis rather than a patch. Full writeup at
docs/fix-and-check.md.
Privacy
TraceBurn sends no telemetry and makes no outbound network requests of its own. The optional viewer serves data on localhost. The offline tests exercise recording and analysis with socket access blocked, including token estimation. Token estimates use a local character-count heuristic without downloading tokenizer data.
The SDK adapters omit authentication headers, but capture prompts, responses and tool arguments. Those payloads, custom span attributes and error messages can contain secrets or personal data. There is currently no built-in redaction or payload opt-out. Review what your application records, protect the database and its SQLite journal files, and do not share a trace database without inspecting its contents.
Limitations
Instrumentation covers the openai and anthropic Python SDKs plus LiteLLM's
completion() and acompletion(). SDK parse() convenience methods and
with_raw_response calls pass through untraced. Multi-choice requests (n > 1)
record text and tool calls from the first choice.
Cost figures come from a dated public pricing table (pricing.json) and don't model long-context pricing tiers or regional surcharges. Token counts prefer whatever the provider itself reports as usage; anything estimated is flagged as estimated rather than presented as measured. Fallback token counts use roughly four characters per token; accuracy varies with language and content. Cache savings estimates are capped by recorded input usage when available, and no cache dollar estimate is shown when input usage is missing.
The waste rules are heuristics tuned for precision over recall, which means they'll miss real waste sooner than they'll invent fake waste, and every finding states its own confidence so you can judge it accordingly. Streaming calls aren't replayable yet; only non-streaming recordings are.
The web viewer is read-only, bound to 127.0.0.1 only, and has no authentication.
Roadmap: v0.2
- A pytest plugin built on replay, for deterministic, token-free agent tests that feed straight
into
traceburn checkin CI. - OpenTelemetry GenAI span ingest plus OTLP export. This is also the path for capturing LangChain and LlamaIndex traces, since it rides on their existing OTel instrumentation rather than requiring bespoke adapters for each.
- More waste rules.
Related work
Langfuse is a full open-source LLM platform: tracing, evals, and prompt management, backed by Postgres and ClickHouse and meant to run as a server.
Arize Phoenix is the closest neighbor here. It runs locally against SQLite with no account needed, and it's strong on tracing and evals, but it runs as a server process with a fairly large dependency set, and it doesn't focus on waste detection, a cost-weighted flamegraph, deterministic replay, or run diffs.
MLflow has been adding GenAI tracing, trace comparison, and efficiency scoring to its tracking server; see mlflow/mlflow.
LangSmith is LangChain's hosted, proprietary platform. OpenLLMetry takes a different approach: it instruments your code and exports OpenTelemetry spans to whatever backend you choose to point it at, rather than shipping a backend of its own.
AgentSight renders token flamegraphs of coding agents from the system side using eBPF, a genuinely different vantage point, though it's Linux only.
Helicone (Helicone/helicone), OpenLIT (openlit/openlit), Braintrust (braintrust.dev), and Logfire (pydantic.dev/logfire) each pair instrumentation with a server or a cloud backend of their own.
traceburn's own position is narrower than most of the above: strictly local, one file, no account and no server needed for basic use, framework-agnostic at the SDK level, and built around efficiency first, meaning the waste report, the dollar-weighted flamegraph, replay, and diff all live together in one small package. It's meant to sit next to whatever observability stack you already run, not replace it.
Contributing
There are two extension points, each documented and each meant to be roughly an afternoon of work: an instrumentation adapter for a new SDK or framework, and a waste rule for a new pattern of avoidable spend. The full guide is at CONTRIBUTING.md.
For AI agents
A machine-readable summary lives at llms.txt: what the tool does, how to install and invoke it, and links to every doc, without needing to parse this whole page.
Citation
A citation file is included at CITATION.cff.
License
MIT. Full text at LICENSE.
Written by Tommy Tran.
1 maintainer

Metadata
1 maintainer
Release files for traceburn 0.2.0
For a detailed explanation of source distributions (sdists) and built distributions (wheels), please see the package formats documentation.
Source distribution (sdist)
| File | Size | Uploaded | |
|---|---|---|---|
| traceburn-0.2.0.tar.gz | 1.2 MB | Details |
Built distribution (wheel)
| File | Interpreter | ABI | Platform | Reset |
|---|---|---|---|---|
| traceburn-0.2.0-py3-none-any.whl | Python 3 | none | any | Details |
Total release size: 1.3 MB
Release files / traceburn-0.2.0.tar.gz
| Download URL | traceburn-0.2.0.tar.gz |
|---|---|
| Size | 1.2 MB |
| Tags | Source |
|
SHA-256 checksum How to use checksums |
e0738231adbbd2b81cd66e6850a9cf8690dbc59a6777a6fe10e0be9a0ce8a604
|
|
BLAKE2b-256 checksum How to use checksums |
0abae253b3aed677a7bdcdac1f697b6f737c577e21337dd34e0048cecfa3c69d
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
No |
| Uploaded via |
twine/7.0.0 CPython/3.11.15
|
Release files / traceburn-0.2.0-py3-none-any.whl
| Download URL | traceburn-0.2.0-py3-none-any.whl |
|---|---|
| Size | 82.9 kB |
| Tags | Python 3 |
|
SHA-256 checksum How to use checksums |
d9e641c5e2f3782ee0543463766f0d48c2aad5f8908d7caa3850108fb823cc65
|
|
BLAKE2b-256 checksum How to use checksums |
6ecd2d8550b01a69ad3fcea8c5d536d306211210406fe1b3c8f229e5d1783080
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
No |
| Uploaded via |
twine/7.0.0 CPython/3.11.15
|














