
tracecraft


The black box for AI agents — records everything your agents do, and referees what they do next.
Every coding session, every task claim, every handoff lands as plain JSON in a bucket you own — any S3-compatible or HuggingFace bucket. Replay any run from any machine, months later. Audit any incident. No server. No database. No SDK lock-in.
- Record — your coding agent stores sessions as local JSONL and, in Claude Code's case, deletes them after 30 days by default.
tracecraft session mirror -fstreams the transcript to your bucket live: private by default, redacted by default, immune to purges, crashes, and laptop swaps. - Referee — run a fleet and two agents can never grab the same work: task claims are decided atomically by S3
If-None-Matchconditional writes — 1,200/1,200 contested races, exactly one winner (benchmarks) — plus shared memory, mailboxes, handoffs, and artifacts through the same bucket.
Who is this for: anyone running Claude Code / Codex / OpenClaw / Hermes who wants an indelible record of what their agents did — and fleets of agents that need coordination without new infrastructure.
Record: your sessions, backed up in 60 seconds
Fastest path is a HuggingFace bucket (any S3 endpoint works too — see Backends):
pip install 'tracecraft-ai[huggingface]'    # or: uvx --from 'tracecraft-ai[huggingface]' tracecraft
export HF_TOKEN=hf_...                      # write token from huggingface.co/settings/tokens

tracecraft init --backend hf --bucket <you>/agent-sessions
tracecraft session mirror -f       # -f = follow: mirror live until Ctrl-C
That's the whole setup — init defaults the project to your directory name and the agent id to your username, and mirror defaults to the claude-code harness (--harness codex|openclaw|hermes for the others).
init creates the bucket private by default and prints the actual visibility read back from the Hub. From then on, every new byte of your session lands in your bucket within seconds — and stays there:
tracecraft session list                    # browse mirrored sessions
tracecraft session show <id> --tail 50     # replay: meta + last N transcript lines, from any machine
tracecraft session compact <id>            # merge a session's many parts into one
- Survives what local storage doesn't — the 30-day purge, crashes, compaction,
rm -rf, switching machines. - Incremental cursor uploads — only new bytes upload, as numbered parts; re-running from a cron or hook is safe and cheap, and the part sequence survives losing local state.
- Near-real-time
--follow— re-flushes every--intervalseconds (default 5), so a crash loses at most one interval. One batched flush per interval keeps request costs flat.--allfollows every session in a folder from one terminal. - Redaction on by default — AWS / Anthropic / OpenAI / HF / GitHub / Slack token shapes are scrubbed before upload, with per-pattern match counts recorded in
meta.json(--no-redactto opt out). Source transcripts are never modified. - Four harnesses —
claude-code,codex,openclaw,hermes; anything else can mirror by writing JSONL to the same layout.
Anthropic's own Agent SDK added pluggable session storage for the same reason — transcripts belong in storage you govern. That covers SDK apps; tracecraft covers the interactive CLIs you actually code with.
Harness matrix, storage formats, and redaction details → docs/session-mirror.md
Referee: coordination for agent fleets
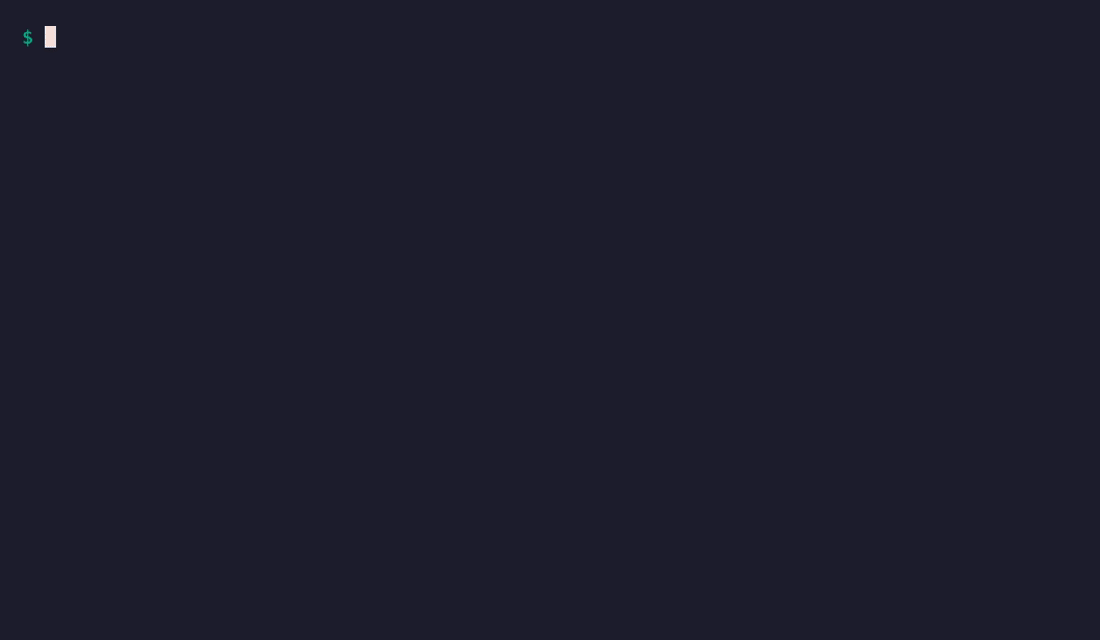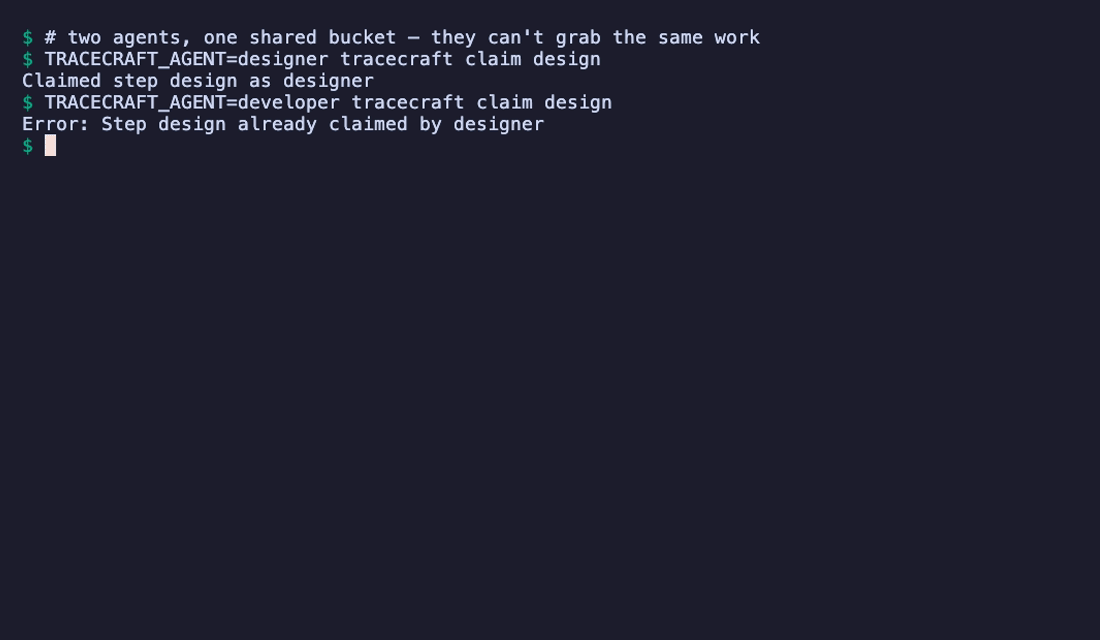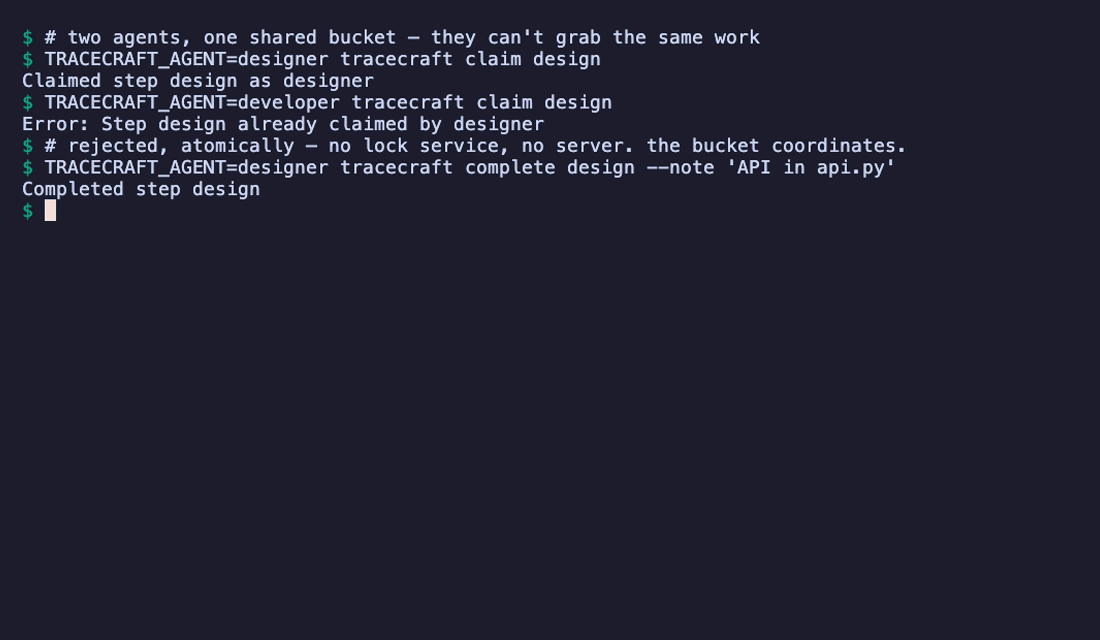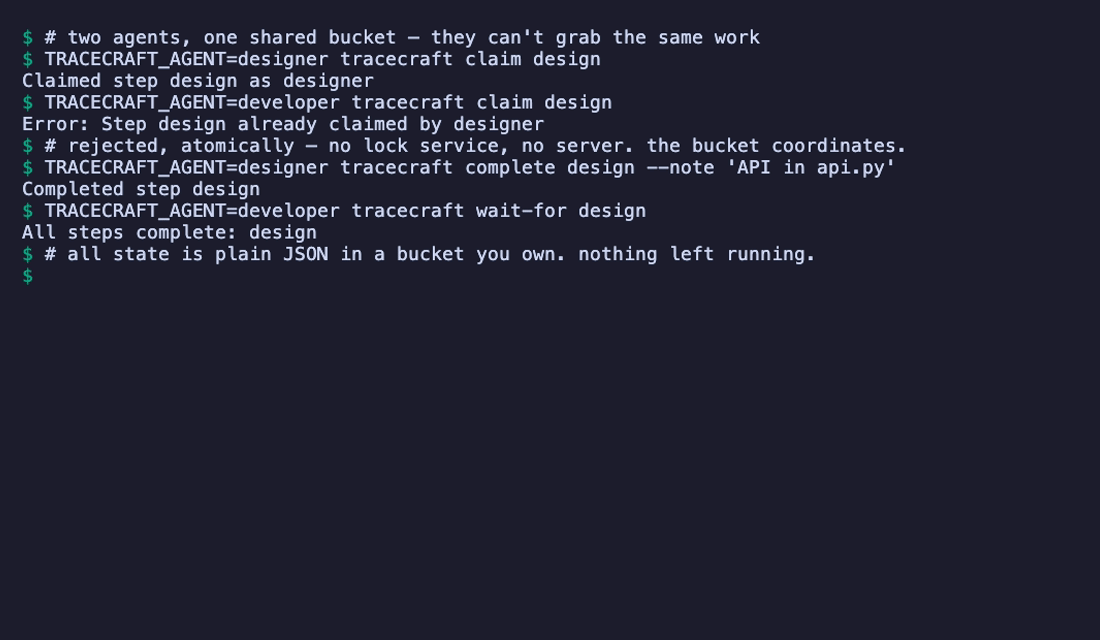
The bucket that holds the record is the bucket that coordinates the fleet. Two agents cannot grab the same work — enforced by an S3 If-None-Match conditional write, with no lock service and no server:
# Local dev: any S3 endpoint works; MinIO in Docker is the quickest sandbox
docker run -d -p 9000:9000 \
  -e MINIO_ROOT_USER=admin -e MINIO_ROOT_PASSWORD=admin123456 \
  minio/minio server /data

export AWS_ACCESS_KEY_ID=admin
export AWS_SECRET_ACCESS_KEY=admin123456

# Terminal 1                                      # Terminal 2 — same flags, --agent developer
tracecraft init --project demo --agent designer \
  --endpoint http://localhost:9000 --bucket tracecraft
# Terminal 1 — designer claims the task
$ tracecraft claim design
Claimed step design as designer

# Terminal 2 — developer tries the SAME task, atomically rejected (S3 If-None-Match)
$ tracecraft claim design
Error: Step design already claimed by designer

# designer finishes and leaves a handoff note for whoever picks up next
$ tracecraft complete design --note "API in api.py, see memory key design.contract"
Completed step design

# developer was blocked on it — now it unblocks
$ tracecraft wait-for design
All steps complete: design
Agents also message through the bucket — direct and broadcast, each message a JSON file in a per-agent mailbox:
tracecraft send developer "contract is in memory key design.contract"
tracecraft inbox                       # read your direct + broadcast messages
tracecraft send _broadcast "v1 cut at 3pm, wrap your tasks"
Why this design:
- Atomic task claims — two agents never grab the same work, enforced by S3 conditional puts, no central coordinator.
- Coordinate across hosts — the bucket is the coordinator; agents on different machines or clouds work together by default.
- No server, no database — every CLI call is stateless; all state is JSON in a bucket you already own.
- Harness-agnostic — Claude Code, Codex, OpenClaw, Hermes, bash, Python, or anything that can run a shell command.
- Coordination + reasoning together — the events and each agent's full session transcript live in one bucket, not two systems.
Frameworks like CrewAI and LangGraph own the agent loop; memory layers like Mem0 store one agent's recall; A2A/MCP are live wire protocols between running agents. Tracecraft owns neither the loop nor the model — just the durable state agents coordinate through — so it works across hosts, across clouds, with agents that aren't even running at the same time.
Benchmarks
Reproducible, against real backends, published with the raw data in benchmarks/:
- 1,200 / 1,200 claim races produced exactly one winner (zero duplicate wins) across 2–50 simultaneous agents.
- Median winning-claim latency 6.5 ms (2 agents) → 41 ms (50 agents), p95 at 50 agents: 74 ms (local MinIO; per-backend results in the report).
- Honest failure disclosure: our old whole-second message keys silently dropped 928 of 960 messages under concurrent send; the nanosecond+uuid scheme shipped in 0.2.2 delivers 960/960. The regression test is in the suite and the bug writeup is in the report.
One command reruns everything: see benchmarks/README.md.
Status & limitations
Honest sharp edges, as of now:
- No TTL on claims — a crashed claim-holder keeps the lock until someone runs
complete --force. - Heartbeat isn't refreshed —
agentsshows who registered, not who's alive right now. - HF claims are best-effort — HuggingFace Buckets have no conditional write, so atomic claims need an S3-compatible backend.
Open issues and roadmap → github.com/Arrmlet/tracecraft/issues
How it works
Every agent action is a JSON file under <bucket>/<project>/:
s3://bucket/demo/
  agents/designer.json                       ← who's alive, what they're doing
  memory/design/contract.json                ← shared key-value state
  messages/developer/1738f3_designer.json    ← per-agent mailbox
  steps/design/claim.json                    ← who claimed what (atomic)
  steps/design/status.json                   ← pending → in_progress → complete
  steps/design/handoff.json                  ← note for the next agent
  artifacts/design/mockup.html               ← shared files
  sessions/claude-code/<id>/part-00000-….jsonl  ← mirrored agent transcript
  sessions/claude-code/<id>/meta.json            ← cumulative session metadata
Any process that can call tracecraft participates. Any S3 browser (MinIO console, AWS console, HuggingFace Hub) lets you watch agents coordinate in real time. Atomicity details and the HuggingFace fallback are in docs/s3-architecture.md.
Backends
Bring your own bucket — no vendor lock-in:
| Backend | init flag |
Notes |
|---|---|---|
| HuggingFace Buckets | --backend hf --bucket user/name |
browsable on the Hub; pip install tracecraft-ai[huggingface] |
| MinIO | --endpoint http://localhost:9000 |
recommended for local dev |
| AWS S3 | --endpoint https://s3.amazonaws.com |
|
| Cloudflare R2 | --endpoint https://<acct>.r2.cloudflarestorage.com |
zero egress fees |
| Backblaze B2 / Wasabi | S3-compatible endpoint | |
| SeaweedFS | --endpoint http://localhost:8333 |
self-hosted |
HuggingFace privacy: init creates the bucket private by default (pass --public to opt out) and prints the bucket's actual visibility, read back from the Hub — e.g. Backend: HuggingFace Buckets Bucket: user/x (private). If the bucket already exists as public and you didn't ask for that, init warns loudly: coordination data and mirrored transcripts would be publicly visible. Visibility can't be flipped after creation (huggingface_hub has no update_bucket) — the only way to change it is delete + recreate.
Use cases
- Session backup & replay — every Claude Code / Codex session mirrored to your own bucket as it happens; replay any session from any machine, months later.
- Multi-agent coding — run several agents in parallel; they claim modules, share artifacts, wait at barriers, and hand off context instead of stepping on each other.
- Autonomous research — agents claim experiments, share results via memory, and avoid duplicating work across a fleet.
- Pipelines — lint → test → build → deploy as claimed steps; each stage waits for its dependencies.
Full CLI reference
tracecraft init                           # Configure backend + project + agent

tracecraft session mirror                        # Mirror a session into the bucket (add -f to follow; --harness defaults to claude-code)
tracecraft session list                          # Browse mirrored sessions
tracecraft session show <id> [--tail N]          # Inspect meta + transcript tail
tracecraft session compact <id>                  # Merge parts into one
tracecraft session stop <id>                     # Clear local state, mark ended

tracecraft agents                         # Who's online?

tracecraft memory set <key> <value>       # Write (dots become path separators)
tracecraft memory get <key>               # Read
tracecraft memory list [prefix]           # List keys

tracecraft send <agent-id> <message>      # Direct message
tracecraft send _broadcast <message>      # Broadcast to all
tracecraft inbox                          # Read messages
tracecraft inbox --delete                 # Read and clear

tracecraft claim <step-id>                # Claim a step (atomic)
tracecraft complete <step-id> [--note X] [--to AGENT] [--next-action X]
                                          [--blocked|--needs-review]
                                          [--changed-files-from-git]  # Structured handoff record
tracecraft step-status <step-id>          # Check status
tracecraft wait-for <step-ids...>         # Block until complete (default 300s timeout)

tracecraft artifact upload <path> [--step id]    # Share a file
tracecraft artifact download <name> [--step id]  # Get a file
tracecraft artifact list [--step id]             # List files
Run multiple agents from one directory by overriding identity per call:
TRACECRAFT_AGENT=designer  tracecraft inbox
TRACECRAFT_AGENT=developer tracecraft inbox
Python API
The CLI is the stable interface; for code that wants direct bucket access, the store factory is the escape hatch:
from tracecraft.store import get_store

store, cfg = get_store()  # reads .tracecraft.json like the CLI does
store.put_json("memory/build/status.json", {"value": "passing", "set_by": cfg["agent_id"]})
More
- docs/session-mirror.md — session mirroring: harnesses, formats, redaction
- docs/s3-architecture.md — atomicity, key layout, HuggingFace fallback
- benchmarks/ — contention + messaging benchmarks, raw results, repro commands
- plans/ — roadmap, research, and known gaps
License
MIT
tracecraft is tracecraft-ai on PyPI — not affiliated with similarly named observability SDKs.
1 maintainer

Download files
Download the file for your platform. If you're not sure which to choose, learn more about installing packages.
Source Distribution
Built Distribution
Filter files by name, interpreter, ABI, and platform.
If you're not sure about the file name format, learn more about wheel file names.
Copy a direct link to the current filters
File details
Details for the file tracecraft_ai-0.2.4.tar.gz.
File metadata
- Download URL: tracecraft_ai-0.2.4.tar.gz
- Upload date:
- Size: 57.7 kB
- Tags: Source
- Uploaded using Trusted Publishing? Yes
- Uploaded via:
twine/7.0.0 CPython/3.13.14
File hashes
| Algorithm | Hash digest | |
|---|---|---|
| SHA256 |
aa6e458a209de66de5ccdbd3014fa0aa4dcd86de907d40ce992cfd2a7681fd21
|
|
| MD5 |
e7629fdf706c4b936eec6e11d1fb46cd
|
|
| BLAKE2b-256 |
f93cb2a30c482a9af966adfb0d322bff6f3aebf39840f62fc3bbf2aa68818213
|
Provenance
The following attestation bundles were made for tracecraft_ai-0.2.4.tar.gz:
Publisher:
release.yml on Arrmlet/tracecraft
-
Statement:
-
Statement type:
https://in-toto.io/Statement/v1 -
Predicate type:
https://docs.pypi.org/attestations/publish/v1 -
Subject name:
tracecraft_ai-0.2.4.tar.gz -
Subject digest:
aa6e458a209de66de5ccdbd3014fa0aa4dcd86de907d40ce992cfd2a7681fd21 - Sigstore transparency entry: 2426569341
- Sigstore integration time:
-
Permalink:
Arrmlet/tracecraft@f7b07f766e924388dbabc4a973afc47038cbb604 -
Branch / Tag:
refs/tags/v0.2.4 - Owner: https://github.com/Arrmlet
-
Access:
public
-
Token Issuer:
https://token.actions.githubusercontent.com -
Runner Environment:
github-hosted -
Publication workflow:
release.yml@f7b07f766e924388dbabc4a973afc47038cbb604 -
Trigger Event:
release
-
Statement type:
File details
Details for the file tracecraft_ai-0.2.4-py3-none-any.whl.
File metadata
- Download URL: tracecraft_ai-0.2.4-py3-none-any.whl
- Upload date:
- Size: 40.2 kB
- Tags: Python 3
- Uploaded using Trusted Publishing? Yes
- Uploaded via:
twine/7.0.0 CPython/3.13.14
File hashes
| Algorithm | Hash digest | |
|---|---|---|
| SHA256 |
47b9191a3b2348ec92ad24652c322c11288d268d8c7b2ff7cf14a7340058708f
|
|
| MD5 |
c5f6601dbb35636842cbb656187dbcde
|
|
| BLAKE2b-256 |
40beb33e78fb745876672204a10722fce5ec0ff2ae0f7b477cd57735c64b5a88
|
Provenance
The following attestation bundles were made for tracecraft_ai-0.2.4-py3-none-any.whl:
Publisher:
release.yml on Arrmlet/tracecraft
-
Statement:
-
Statement type:
https://in-toto.io/Statement/v1 -
Predicate type:
https://docs.pypi.org/attestations/publish/v1 -
Subject name:
tracecraft_ai-0.2.4-py3-none-any.whl -
Subject digest:
47b9191a3b2348ec92ad24652c322c11288d268d8c7b2ff7cf14a7340058708f - Sigstore transparency entry: 2426569440
- Sigstore integration time:
-
Permalink:
Arrmlet/tracecraft@f7b07f766e924388dbabc4a973afc47038cbb604 -
Branch / Tag:
refs/tags/v0.2.4 - Owner: https://github.com/Arrmlet
-
Access:
public
-
Token Issuer:
https://token.actions.githubusercontent.com -
Runner Environment:
github-hosted -
Publication workflow:
release.yml@f7b07f766e924388dbabc4a973afc47038cbb604 -
Trigger Event:
release
-
Statement type:














