
DeepSeek MLA Triton Kernel
A fused decode kernel for Multi-head Latent Attention (MLA), the attention mechanism behind DeepSeek-V2, V3 and R1. MLA compresses the KV cache into one small latent vector per token, so long contexts take far less GPU memory.
The kernel is written in Triton, OpenAI's Python-embedded DSL for writing GPU kernels.
Why use it: torch.compile still runs MLA decode as several separate GPU
operations and writes the full attention-score matrix to memory between them.
This kernel does the whole step in one pass over the compressed cache, so it
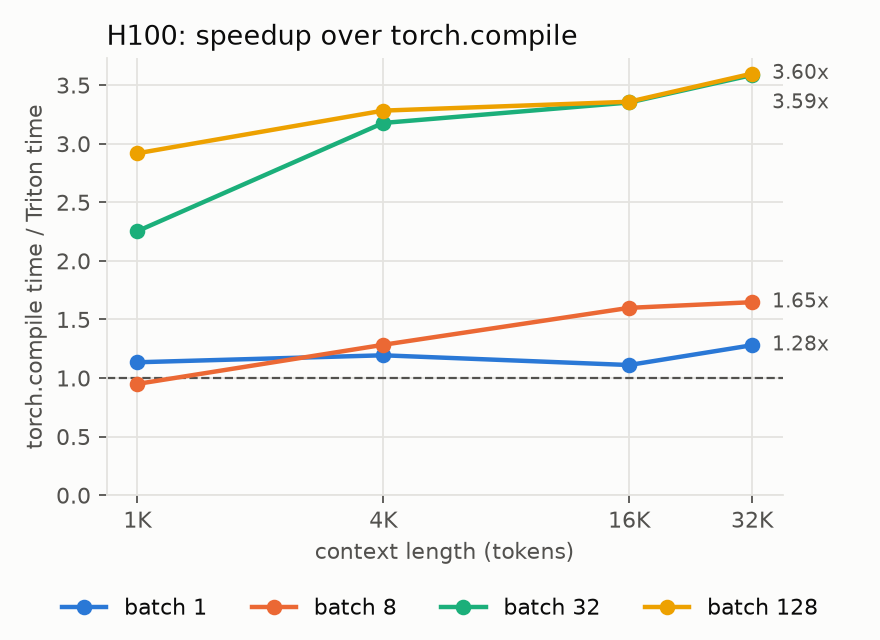
runs up to 3.6x faster on an H100 at long contexts.
Details
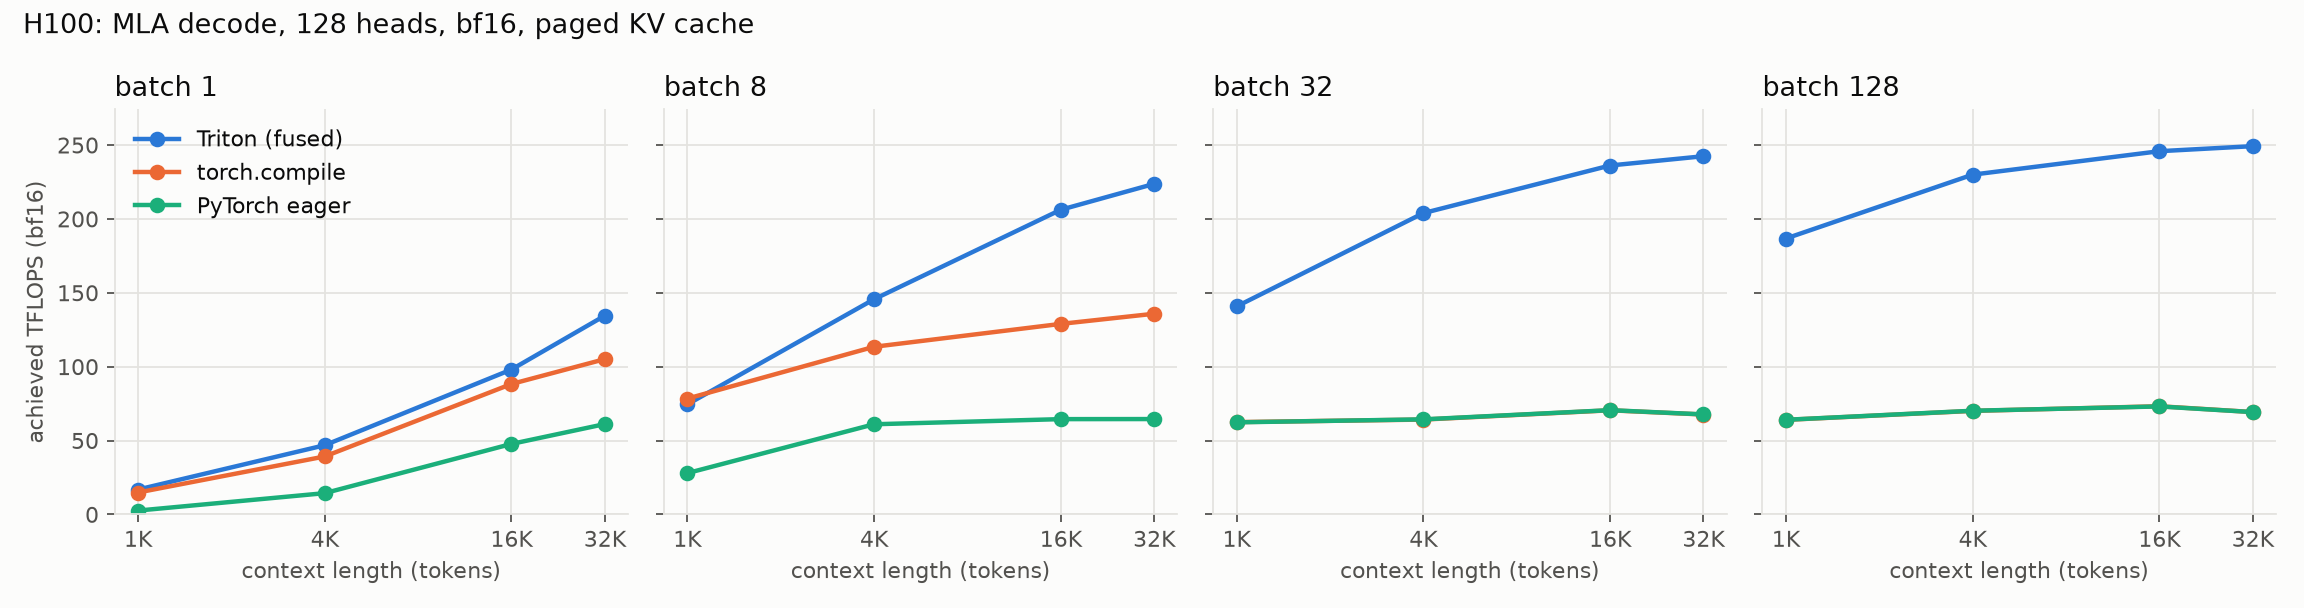
- Setup: H100 80GB SXM, 128 heads (DeepSeek-V3 on one GPU), bf16, paged
KV cache.
torch.compileruns inmax-autotunemode. Every case is checked against a reference before it is timed. - Results: faster than
torch.compilein 15 of 16 shapes, peaking at 249 TFLOPS. The one loss is batch 8 at 1K tokens, where launch overhead dominates. At batch 32 and above,torch.compilewas no faster than plain PyTorch. Full numbers are inresults/bench_h100.csv. - Install:
pip install triton-mla(PyPI). The package providesmla_decode, a fullMLAlayer and thetriton-mla-benchcommand. - Limitations: single-token decode only, no FP8 cache, and no Blackwell (B200) support yet.
1 maintainer

Metadata
1 maintainer
Release files for triton-mla 0.1.1
For a detailed explanation of source distributions (sdists) and built distributions (wheels), please see the package formats documentation.
Source distribution (sdist)
| File | Size | Uploaded | Provenance | Actions |
|---|---|---|---|---|
| triton_mla-0.1.1.tar.gz | 13.2 kB | Without provenance | Details for triton_mla-0.1.1.tar.gz |
Built distribution (wheel)
| File | Interpreter | ABI | Platform | Actions Reset |
|---|---|---|---|---|
| triton_mla-0.1.1-py3-none-any.whl | Python 3 | none | any | Details for triton_mla-0.1.1-py3-none-any.whl |
Total release size: 25.5 kB
Release files / triton_mla-0.1.1.tar.gz
| Download URL | triton_mla-0.1.1.tar.gz |
|---|---|
| Size | 13.2 kB |
| Tags | Source |
|
SHA-256 checksum How to use checksums |
40d988ebf7c02ef1bc73714704284f301e566b28f99571de3ec9d808c4a490d7
|
|
BLAKE2b-256 checksum How to use checksums |
21965d00a9ebc4f086c441c96e163ed64b82ef68e34a918d3d1409d1060b2701
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
No |
| Uploaded via |
twine/7.0.0 CPython/3.12.1
|
Release files / triton_mla-0.1.1-py3-none-any.whl
| Download URL | triton_mla-0.1.1-py3-none-any.whl |
|---|---|
| Size | 12.3 kB |
| Tags | Python 3 |
|
SHA-256 checksum How to use checksums |
1e4686cc3b7b3a3b014e6a4de63cb77841793574c7852bec2079636d9e6cb568
|
|
BLAKE2b-256 checksum How to use checksums |
4739d99893e414db3790aea850afdfdacbfc07c126a7814b800d8aec575c157a
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
No |
| Uploaded via |
twine/7.0.0 CPython/3.12.1
|
Security for triton-mla 0.1.1
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.
No provenance found
None of the files in this release were uploaded with provenance metadata.
A note on package security
PyPI is a repository for distributing packages, not a service for auditing them. While third-party security researchers and our staff do their best to detect and remove malicious packages, PyPI cannot guarantee the quality, security or suitability of any given package.
To learn more about protecting yourself from malicious actors, visit our package security documentation.














