
turing-bf16
Run bf16 models at fp16 tensor-core speed on GPUs that have no bf16 tensor cores (Turing: RTX 2060–2080 Ti, TITAN RTX, Quadro RTX, Tesla T4). One line, no calibration, same accuracy as native bf16. Inference and training.
import tbf16
tbf16.convert(model)               # inference (transformers models, any nn.Module)
tbf16.convert(pipe)                # diffusers pipelines
tbf16.convert(model, train=True)   # training / LoRA fine-tuning
Compared with running the same bf16 model in plain PyTorch:
| RTX 2080 Ti: torch bf16 → tbf16 | Tesla T4: torch bf16 → tbf16 | |
|---|---|---|
| Large matmuls | 8 → 50–53 TFLOPS | 2.9 → 24–30 TFLOPS |
| Attention, 4–16k tokens | 4–5 → 28–33 TFLOPS, 4–7 GB → <1 GB | → 12.6–14.5 TFLOPS (fp16 speed) |
Gemma 3 4B prompt, 2048 tokens (.half() gives NaN) |
2084 → 484 ms (4.3x) | 5286 → 874 ms (6.0x) |
| Qwen3-1.7B prompt, 4096 tokens | 2455 → 423 ms (5.8x) | 6319 → 852 ms (7.4x) |
| Wan2.1 1.3B video, s/step | 3.72 → 0.74 s (5.0x) at 17x320x512 | 27.2 → 4.45 s (6.1x) at 17x480x832; the default 81x480x832 video runs where native OOMs |
| Sana 1600M image, s/step at 1024² | 2.24 → 0.40 s (5.6x); native bf16 VAE cannot decode at all | |
| UMT5-XXL text encoder (Wan's), 8 x 512 tokens | 14.8 → 2.8 s (5.3x) | |
| Training, matching loss curves | 1.5–2.6x | linear/attention fwd+bwd 5.4–9.2x |
Full numbers, methods and negative results: RESULTS.md.
Status: research code. Benchmarked on RTX 2080 Ti and Tesla T4 (sm_75) with torch 2.15 / CUDA 13.2. The test suite also passes on an RTX A5000 and an A10G (Ampere,
force=True), whereconvert()is a no-op by default. Not yet tested on other Turing cards or V100. Linux only.
Why this exists
Turing tensor cores do fp16, int8 and int4, but not bf16. Most current models ship in bf16, and on Turing they hit three bad options:
- Run bf16 as-is. PyTorch falls back to a path that is slower than fp32 (7.6 vs 56 TFLOPS fp16 on a 2080 Ti), and bf16 attention has no fused kernel, so it builds the full S x S matrix (slow, and out of memory at long contexts).
- Cast to fp16 (
model.half()). Fast, but fp16 tops out at 65504. Many bf16 models (Gemma 2/3, T5, video DiTs) overflow and produce NaN or black frames. - Run in fp32. Correct, 2x the memory, and still only ~13 TFLOPS. This is what vLLM (Gemma) and ComfyUI ("manual cast: float32") do on these cards.
tbf16 is a fourth option: keep everything in bf16 and do the math on fp16 tensor cores, without overflow.
How it works
bf16 has an 8-bit significand and fp16 has 11, so every bf16 value converts to fp16 exactly
as long as it is inside fp16's range. tbf16 moves each row of activations and each row of
weights into that range with a power-of-two scale (exact: it only changes the exponent),
runs fp16 tensor-core GEMMs with fp32 accumulation (a fused mma.sync kernel for M ≥ 256,
cuBLAS below that), and undoes the scales in the epilogue.
- Linear layers: one scale per activation row and per weight row. The scale target is
chosen so the fp16 GEMM output provably cannot overflow (
|C| < K * 4^t <= 65504). - Attention: Q is multiplied by 2^a and K by 2^-a, which leaves every logit unchanged; V gets one scale per head, undone on the output. Torch's fp16 memory-efficient kernel does the work. No host sync.
- Training: dX and dW are fp16 GEMMs too, with column scales where the contraction changes. The attention backward scales dO by a power of two per call, like per-op loss scaling decided on the spot, so no step is ever skipped.
Precision: the result matches torch's own bf16 computation to within the bf16 rounding of the output (relative error ~1.7e-3 against an fp64 reference in both cases). Two caveats:
- Very small elements: values more than ~2^16 smaller than their row's maximum land in fp16's subnormal range and keep fewer bits. Their contribution to the result is far below bf16 rounding.
- Double rounding (small batches only): for fewer than 256 rows the cuBLAS path rounds the GEMM output to fp16 (11 bits) before bf16 (8 bits). From 256 rows up, a fused sm_75 kernel converts bf16 to fp16 on the fly and writes bf16 straight from the fp32 accumulators.
Install
Requirements:
- Linux and an NVIDIA Turing GPU.
- PyTorch with CUDA.
- An
nvccwhose major CUDA version matches PyTorch's, to build the small CUDA kernels on first use. Without it, tbf16 still works through Triton/torch fallbacks: correct, but slower for small batches.
pip install turing-bf16

# nvcc matching your torch build, if you don't have a CUDA toolkit. For CUDA 13 builds of torch
# (the PyPI default), pip wheels work; pin all three to torch's CUDA version:
python -c "import torch; print(torch.version.cuda)"              # e.g. 13.2
pip install "nvidia-cuda-nvcc==13.2.*" "nvidia-nvvm==13.2.*" "nvidia-cuda-crt==13.2.*" ninja
#   For CUDA 12 builds of torch, the pip nvcc wheel ships only ptxas: install a CUDA 12 toolkit
#   (system package, or `conda install -c nvidia cuda-nvcc`) and set CUDA_HOME if it isn't found.

python -m tbf16    # checks the GPU, builds the kernels, verifies accuracy, prints a speedup
Expected output on a 2080 Ti:
GPU: NVIDIA GeForce RTX 2080 Ti (sm_75)
tbf16 applies to this GPU: True
CUDA kernels: built/loaded in 0.2 s
linear rel err 1.70e-03, attention rel err 1.71e-03 (bf16 rounding is ~1.7e-3): OK
4096^3 GEMM: torch bf16 6.6 TFLOPS, tbf16 41.9 TFLOPS (6.4x)
The first run compiles the kernels, which takes about 1–2 minutes. They are cached under
~/.cache/torch_extensions.
Usage
Inference with Hugging Face transformers
import torch, tbf16
from transformers import AutoModelForCausalLM, AutoTokenizer

name = "google/gemma-3-4b-it"
tok = AutoTokenizer.from_pretrained(name)
model = AutoModelForCausalLM.from_pretrained(name, dtype=torch.bfloat16, attn_implementation="sdpa").cuda().eval()
tbf16.convert(model)    # in place; weights become fp16 + power-of-two scales (same memory)
out = model.generate(**tok("Explain bf16 vs fp16.", return_tensors="pt").to("cuda"), max_new_tokens=200)
- Load the model in bf16 and use
attn_implementation="sdpa". convertreplaces every bf16nn.Linearand routesF.scaled_dot_product_attention. Do it after loading and moving the model to the GPU.- Weights tied to the embedding (e.g.
lm_head) are left as they are.
Training and LoRA
model = AutoModelForCausalLM.from_pretrained(name, dtype=torch.bfloat16, attn_implementation="sdpa").cuda()
model = get_peft_model(model, LoraConfig(r=16, target_modules="all-linear"))  # optional
tbf16.convert(model, train=True)      # after PEFT wrapping; parameters are untouched
model.train()

with torch.autocast("cuda", dtype=torch.bfloat16):   # usual bf16 mixed precision, no GradScaler
    loss = model(**batch).loss
loss.backward(); optimizer.step()
Works with fp32 master weights under autocast(bf16), with pure bf16 weights, with
gradient checkpointing, and with PEFT/LoRA.
Diffusion models (diffusers)
pipe = DiffusionPipeline.from_pretrained(name, torch_dtype=torch.bfloat16).to("cuda")
tbf16.convert(pipe)   # every bf16 Linear and Conv on the GPU (transformer, VAE, ...), plus SDPA
video = pipe(prompt, num_frames=81, height=480, width=832).frames[0]
Measured results:
- Wan2.1 T2V 1.3B: 5–5.6x faster per step than native bf16 and within 8% of fp16. It generates the default 81x480x832 video, where native bf16 runs out of memory.
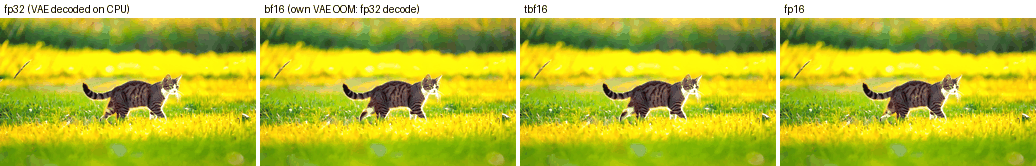
- VAEs: they decode at fp16 speed. Wan's native bf16 VAE is 4.5x slower or runs out of memory; Sana's does not run in native bf16 on Turing at all, since cuDNN has no bf16 kernel for one of its convolutions.
- Output: it matches native bf16 (same error against fp32).
Neither Wan2.1 nor Sana overflowed in fp16, so for those two .half() is also fine, and
slightly faster.
Not supported yet: enable_model_cpu_offload(), because convert only touches modules that
are already on the GPU.
Lower-level API
| Function | What it does |
|---|---|
tbf16.convert(model_or_pipeline, train=False, sdpa=True, force=False, conv=True) |
In-place conversion: Linear, Conv1d/2d/3d and SDPA. A no-op with a warning on GPUs that already have bf16 (Ampere and newer) unless force=True. |
tbf16.is_supported_gpu() |
True on sm_70/72/75 (fp16 tensor cores, no bf16). |
tbf16.prepare_weight(w) |
bf16 (N, K) → (fp16 (N, K), fp32 (N,) inverse scales). |
tbf16.scaled_linear(x, w16, w_scale, bias=None) |
x @ W^T + b for bf16 x, inference. |
tbf16.sdpa(q, k, v, attn_mask=None, is_causal=False, scale=None, enable_gqa=False) |
bf16 attention, inference. |
tbf16.autograd.linear(x, w, b), tbf16.autograd.sdpa(...) |
Differentiable versions. |
tbf16.patch() |
Context manager that intercepts F.linear/SDPA without converting the model. Convenient, but caches an extra fp16 copy of the weights. |
python -m tbf16 |
Self-check. |
Environment variables:
TBF16_BACKEND=tritonforces the Triton kernels.TBF16_ATTN_CHECK=0skips the attention-backward overflow check, which is the only host sync.TBF16_MIN_DIM(default 128): in train mode, linear layers smaller than this in either dimension run as fp32.
When to use it (and when not)
| Situation | Recommendation |
|---|---|
| Turing GPU, bf16 model, prompt processing / batch inference / diffusion | Use tbf16. This is where the 3–8x is. |
| Turing GPU, model known to be fp16-safe (e.g. Wan2.1, Sana, Qwen3) | .half() works and is 0–15% faster; tbf16 is the safe default when you don't know. |
| Turing GPU, T5/UMT5 text encoders | fp16 is the most accurate there (Hugging Face clamps T5's huge activations, and fp16 keeps 3 more bits between layers). tbf16 is 5x faster than native bf16, with the same accuracy as native bf16. |
| Turing GPU, bf16 model that overflows in fp16 (Gemma 3, many DiTs) | Use tbf16. .half() breaks; fp32 is 2x memory and slow. |
| Turing GPU, single-stream token-by-token decoding | Same speed as native; it is memory bound either way. |
| Turing GPU, training a model that is known to be fp16-safe | fp16 AMP + GradScaler is still 1.4–1.6x faster than tbf16 at small batch. tbf16 gives bf16 semantics (no loss scaling, no skipped steps) at 1.5–2.6x native bf16. |
| Ampere, Ada, Hopper, Blackwell (RTX 30xx+, A100, H100, ...) | Not needed. convert is a no-op there. |
| GTX 16xx (Turing without tensor cores), Pascal or older | Not useful; untested. |
| V100 (Volta, fp16 tensor cores) | Probably works; untested. |
For AI coding agents
If a user asks you to run a bf16 model on a Turing GPU (RTX 20xx, T4, Quadro RTX, TITAN RTX):
- Check the GPU:
python -c "import torch; print(torch.cuda.get_device_capability())"should print(7, 5). Anything>= (8, 0)already has bf16; don't use tbf16 there. - Install as in Install and run
python -m tbf16. It must printOK. - Load the model in
torch.bfloat16withattn_implementation="sdpa", move it to CUDA, then calltbf16.convert(model)(ortrain=Truefor training). Change nothing else. - Verify on the user's own model: compare a few logits or outputs against the unconverted bf16 model (expect a relative difference around 1e-3, and the same greedy tokens for most prompts).
- Things that are not handled, and just run natively: non-SDPA attention implementations
(eager attention with manual matmuls),
torch.compile/CUDA graphs (untested), and head dims above 256. Callconvertafter moving the model or pipeline to CUDA; CPU offloading is not supported.
To change the library itself, read AGENTS.md.
Limitations
- Tested on one GPU model. Only an RTX 2080 Ti, with torch 2.15 / CUDA 13.2, has been tested.
- Linear, Conv and SDPA only. Eager-mode attention and custom matmuls
(
torch.matmul/einsumin model code) run natively. Convs are inference only, and depthwise convs are slightly slower than native (still converted, because native can fail outright). - Attention needs 4D inputs (B, H, S, D) with head dim ≤ 256. Single-query decode steps run natively because they are just as fast.
- Training has more launch overhead than fp16 AMP. The gap is largest at small batches on slow host CPUs.
patch()doubles weight memory. Preferconvert().- The GeForce ceiling is half rate. GeForce Turing runs fp16 with fp32 accumulation at half rate (~57 TFLOPS on a 2080 Ti). Data-center Turing (T4, Quadro) does not have this limit.
Related work
The exactness of bf16 → fp16 inside fp16's range, and power-of-two scaling, are not new.
- WanGP uses the same argument for bf16 convolutions on Turing (Oct 2026).
- Strata PR #593 runs bf16 GEMMs as fp16 on Volta/Turing, without scaling.
- fp16-fixer and others make specific models fp16-safe with static rescaling.
- DeepSeek-V3, OCP MX and Transformer Engine use power-of-two block scales for low-precision formats.
What tbf16 adds is a general, calibration-free drop-in for linear layers, convolutions and SDPA, for inference and training, with end-to-end measurements. See docs/RELATED_WORK.md for the full survey.
Maintenance
Research code, provided as is. It is not actively maintained: issues and pull requests are welcome but may not get a response. Fork freely.
License
MIT. See LICENSE.
1 maintainer

Metadata
1 maintainer
Release files for turing-bf16 0.1.0
For a detailed explanation of source distributions (sdists) and built distributions (wheels), please see the package formats documentation.
Source distribution (sdist)
| File | Size | Uploaded | Provenance | Actions |
|---|---|---|---|---|
| turing_bf16-0.1.0.tar.gz | 45.9 kB | With provenance | Details for turing_bf16-0.1.0.tar.gz |
Built distribution (wheel)
| File | Interpreter | ABI | Platform | Actions Reset |
|---|---|---|---|---|
| turing_bf16-0.1.0-py3-none-any.whl | Python 3 | none | any | Details for turing_bf16-0.1.0-py3-none-any.whl |
Total release size: 82.8 kB
Release files / turing_bf16-0.1.0.tar.gz
| Download URL | turing_bf16-0.1.0.tar.gz |
|---|---|
| Size | 45.9 kB |
| Tags | Source |
|
SHA-256 checksum How to use checksums |
30dc07ddc3b5ea12bbefe75371a8d391f924c400b419f959040b514e72b22a10
|
|
BLAKE2b-256 checksum How to use checksums |
99c22144e9301a227c1f0e790704ecf4d0446c8eb815821b5f59a923f9a90cad
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
Yes |
| Uploaded via |
twine/7.0.0 CPython/3.13.16
|
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.


PyPI Publish Attestation
PyPI verified that this artifact, at this checksum, originated from the publisher listed below.
Signed by GitHub Actions, verified by PyPI on Nov 3, 2026.
Transparency logRelease files / turing_bf16-0.1.0-py3-none-any.whl
| Download URL | turing_bf16-0.1.0-py3-none-any.whl |
|---|---|
| Size | 37.0 kB |
| Tags | Python 3 |
|
SHA-256 checksum How to use checksums |
c24b7efe783851438d12db163fbac6adacddbed388ca891843cd41d657d4479f
|
|
BLAKE2b-256 checksum How to use checksums |
d490e96be0deb9a9198760dd04b822853d7eaf3b852bcebe6a7a50998a4e7d84
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
Yes |
| Uploaded via |
twine/7.0.0 CPython/3.13.16
|
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.
PyPI Publish Attestation
PyPI verified that this artifact, at this checksum, originated from the publisher listed below.
Signed by GitHub Actions, verified by PyPI on Nov 3, 2026.
Transparency logSecurity for turing-bf16 0.1.0
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.
Full provenance
All 2 files in this release have been uploaded with provenance metadata.
Attestation for turing_bf16-0.1.0.tar.gz
PyPI Publish Attestation
PyPI verified that this artifact, at this checksum, originated from the publisher listed below.
Signed by GitHub Actions, verified by PyPI on Nov 3, 2026.
Transparency logA note on package security
PyPI is a repository for distributing packages, not a service for auditing them. While third-party security researchers and our staff do their best to detect and remove malicious packages, PyPI cannot guarantee the quality, security or suitability of any given package.
To learn more about protecting yourself from malicious actors, visit our package security documentation.













