
Turnbook
Your AI forgets everything when the session ends. This one remembers, and it never calls an LLM to do it.
91.8% on LongMemEval from 3.1k tokens of memory per question (0.10.0). Zero model tokens spent saving memory. Runs on your own PC.





Decide something with one agent on Monday. Ask another on Wednesday. It knows.
| tokens spent saving memory | text the answer model reads per question | LongMemEval | |
|---|---|---|---|
| Turnbook 0.10 | 0 | 3.1k tokens | 91.8% |
| Turnbook, previous search model | 0 | 26.3k tokens | 91.8% |
| agentmemory | — | ~16.5k tokens | 80.4% |
All 500 LongMemEval_S questions (agentmemory: 499), same answer model (gpt-5-mini), prompt and official gpt-4o judge; only the memory differs. Tools like claude-mem and Mem0 run an LLM over your conversations to save them; Turnbook stores them word for word. Details
English · 한국어
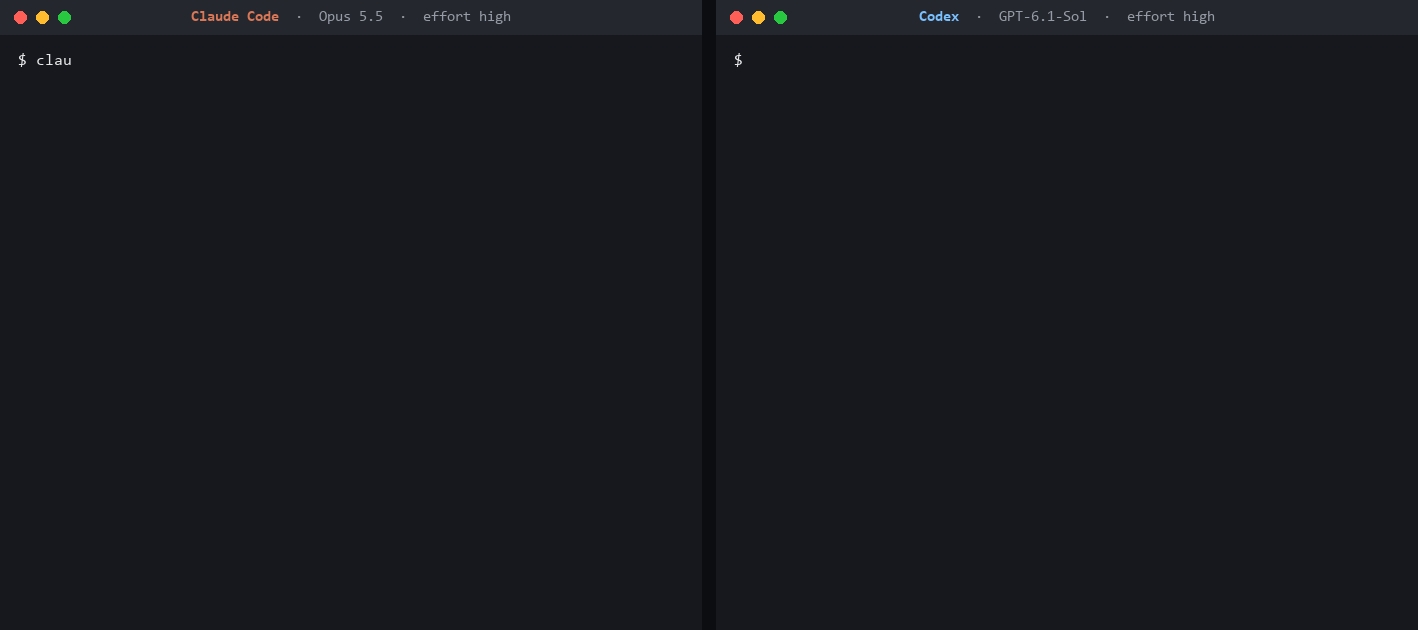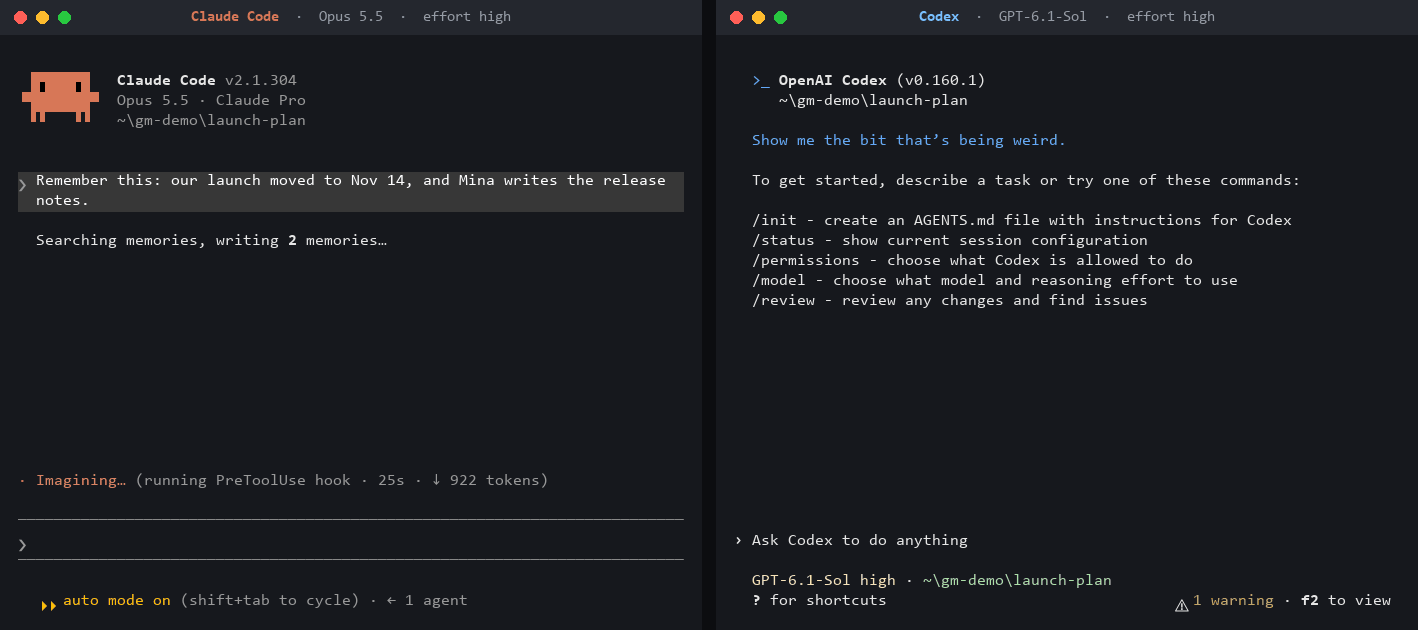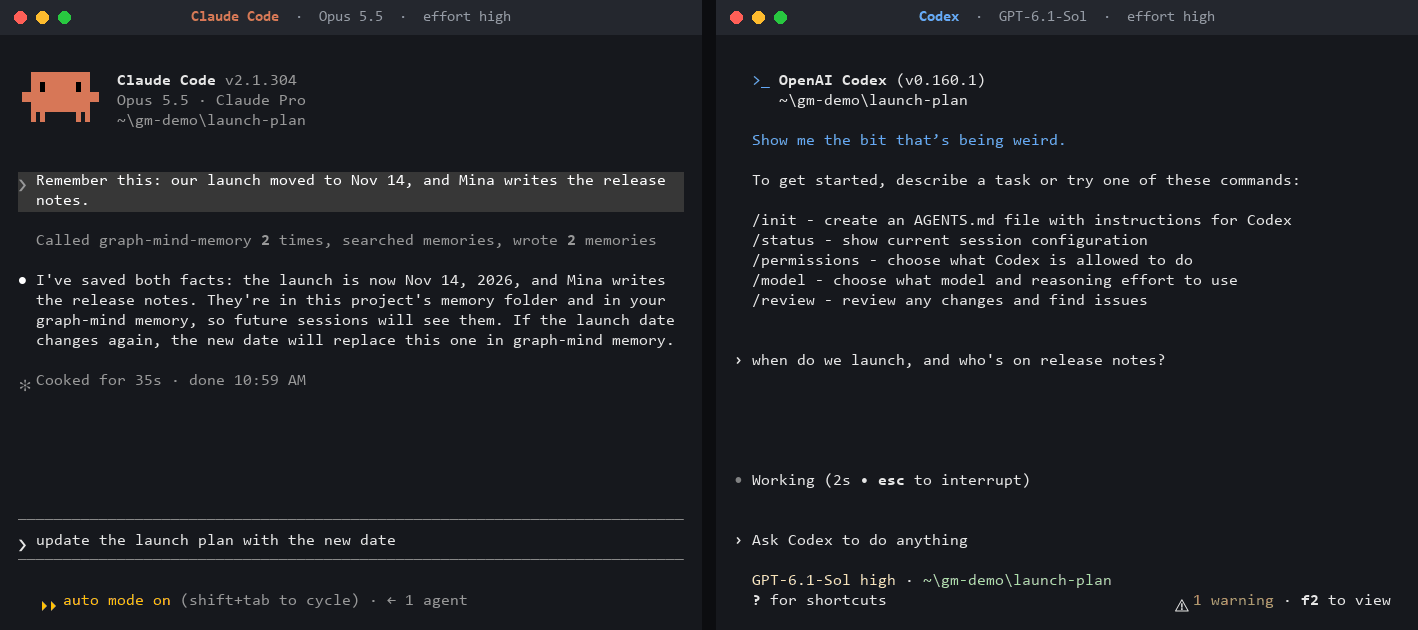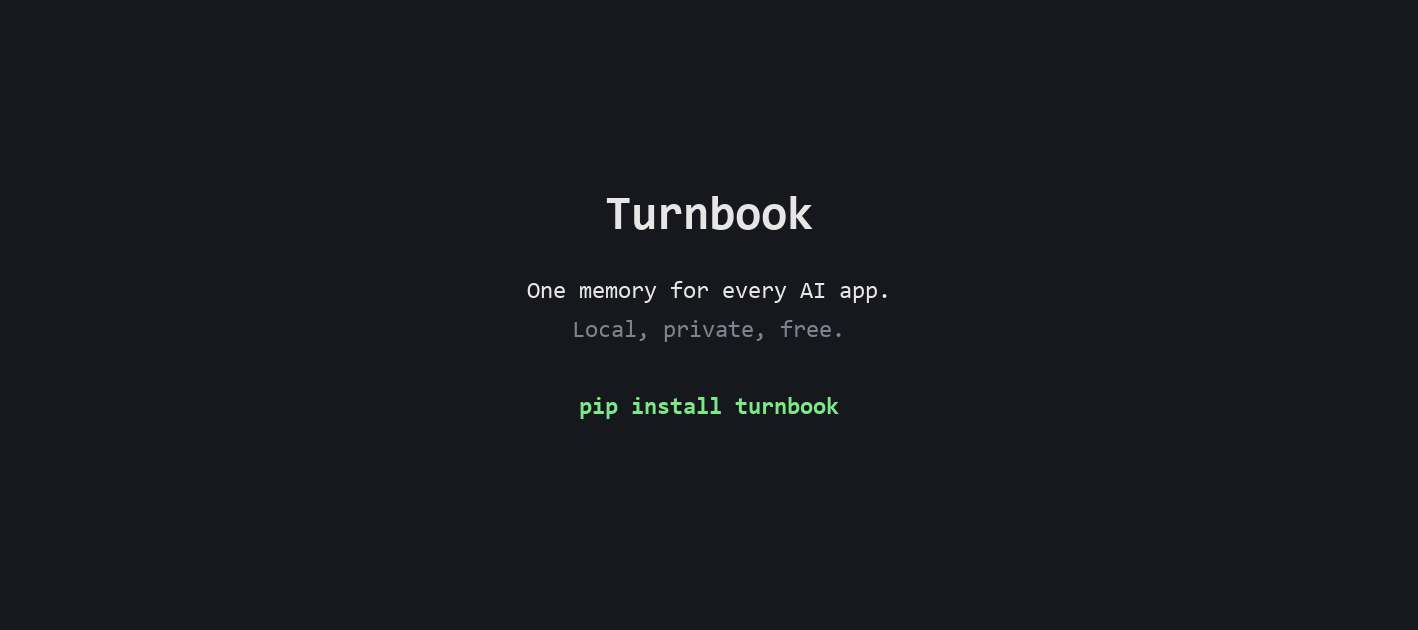
Recorded live on one PC: Claude Code (Opus 5.5, effort high) and Codex (GPT-6.1-Sol, effort high) sharing one Turnbook memory. Model thinking time is fast-forwarded.
If Turnbook saves you tokens or repeated explanations, a ⭐ helps other people find it.
Install
Windows: download Turnbook-Setup.cmd and double-click it, or in PowerShell:
irm https://raw.githubusercontent.com/goyohan0611-png/turnbook/main/scripts/install.ps1 | iex
macOS / Linux:
curl -LsSf https://raw.githubusercontent.com/goyohan0611-png/turnbook/main/scripts/install.sh | sh
No Python needed; nothing else to set up. Restart your AI apps afterwards. Already have Python?
pip install turnbook && turnbook-install. More: docs/install.md.
Connecting an MCP client by hand
After pip install turnbook:
{
  "mcpServers": {
    "turnbook": {
      "command": "python",
      "args": ["-m", "graph_mind.mcp_server"]
    }
  }
}
Claude Code: claude mcp add turnbook -- python -m graph_mind.mcp_server. This gives the
tools only; turnbook-install also saves every conversation automatically.
Try it
Work as usual for a while, then open a new session, another app, or another model and ask:
- "Where did we leave off yesterday?"
- "Which database did we pick for the billing service, and why?"
- "What did you change in the auth middleware last week?"
- "What's my dog's name?" (any fact you mentioned once, in passing)
Nothing to tag or save by hand: every turn is already stored, and the agent pulls back the few that answer the question.
What it does
- Every agent, one memory. Claude Code, Codex, Cursor, Copilot CLI, Gemini CLI, OpenCode and any MCP app read and write the same memory. Decide with one, ask another; switch models, the memory stays.
- The right memory in every message. In Claude Code, Codex, Copilot CLI, Gemini CLI and OpenCode, Turnbook looks up what your message needs from the past and adds it before the model answers. Nothing to ask for.
- Free to save, on your PC. Every turn is stored word for word in one SQLite file: no model call, no tokens, no account, no cloud.
Everything else
- Made for orchestration. When an orchestrator runs several agents at once, they all write to the same memory as they work, so what one agent decided is there for the next. Every memory keeps which app and session it came from.
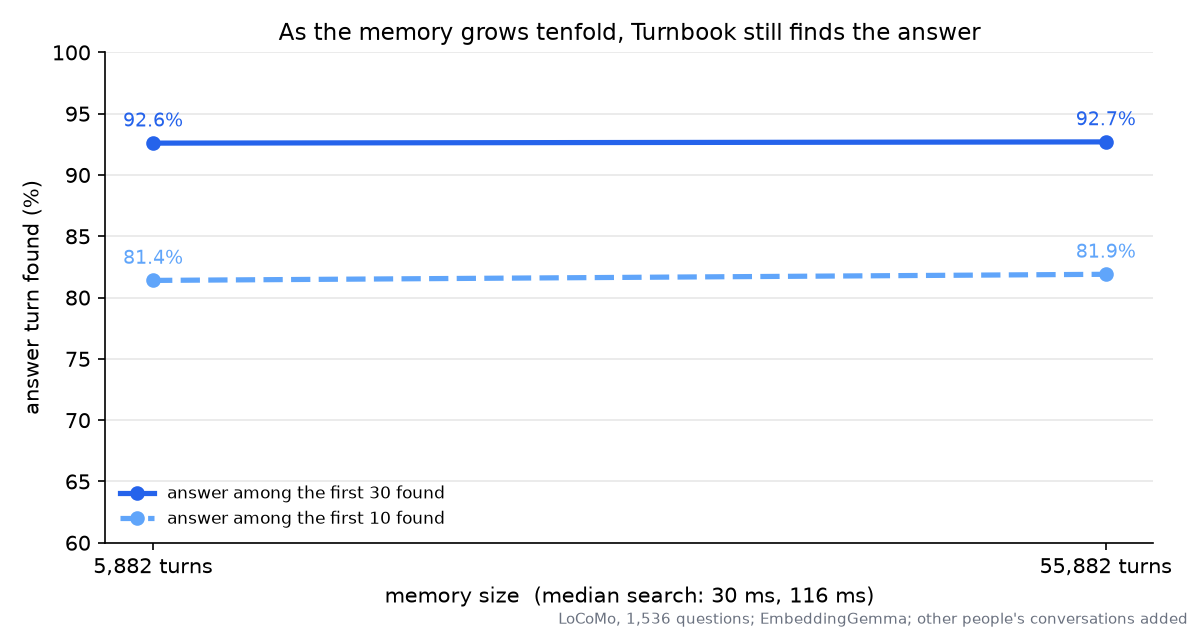
- Holds up as memory piles up. With 0.9.47's search model, in a memory of 205,000 turns the answer is still among the first 30 found for 79.7% of questions (82.8% at 6,000), and a search takes about 0.4 s. As the memory grows
- Any language, across languages. The search model reads Korean almost as well as English: ask in Korean about something said in English, or the other way round. In Korean
- Your project's documents too.
turnbook docs add FOLDERkeeps its Markdown and text files searchable beside the conversations, section by section, and up to date as they change. - One memory across your PCs. Run
turnbook folder share, thenturnbook folder <code>on the other PC (the AI tells you the command; it never moves your memory by itself, so a web page cannot either). Office network or Tailscale, over TLS, every line encrypted before it leaves a PC. - Hand a memory to someone else as a file.
turnbook export FILEwrites all of it;--project FOLDERwrites only the conversations held in that folder. They runturnbook import FILE. - Yours. No account, no cloud of its own, no telemetry. Secrets are masked before anything is stored, and "delete the password I typed earlier" deletes it everywhere. docs/privacy.md
- Teams, if you want them. Share a project's decisions and progress with teammates' AIs, never your personal memory; files stay in Slack and GitHub. docs/teams.md
Works with
The installer finds these and connects them; run it again after installing a new one.
| app | conversations saved | how |
|---|---|---|
| Claude Code | every turn | reads its transcripts; a hook adds relevant memory to each message |
| Codex CLI | every turn | reads its transcripts; a hook adds relevant memory to each message (trust it once in /hooks) |
| Cursor | every turn | reads its transcripts |
| Copilot CLI | every turn | reads its transcripts; a hook adds relevant memory to each message |
| Claude Desktop (Cowork) | every turn | reads its session files |
| Gemini CLI | every turn | hooks; also adds relevant memory before each answer |
| OpenCode | every turn | plugin; also adds relevant memory before each answer, for any model |
| Claude Desktop chat, Windsurf, VS Code Copilot, Cline, LM Studio | what the model saves | MCP tools |
Any other MCP client works through the tools: see the hand-written config above.
How it works
flowchart LR
    A["Claude Code · Codex · Cursor<br/>Gemini CLI · OpenCode · ..."] -- "transcripts, hooks, plugin" --> C["capture service<br/>(runs in the background)"]
    C -- "verbatim turns,<br/>secrets masked" --> S[("your memory<br/>on this PC")]
    S --> I["local search<br/>words + meaning + time"]
    A -- "a question that needs the past" --> I
    I -- "the few turns that answer it<br/>(a few thousand tokens)" --> A
- Saving costs nothing. Turns are stored as they were said. No model summarises or extracts anything at write time, so nothing is lost or invented on the way in, and no tokens are spent.
- Search runs on your PC. Word search, a local embedding model (Google's EmbeddingGemma, 4-bit; ONNX, no GPU) and when things were said are combined, then ordered by a small learned score; the agent gets a short packet with the source turns, not a dump of history.
- The model you already use does the thinking. Turnbook hands it evidence; it answers. When models get better, the answers get better without changing the memory.
Beyond agent memory
Underneath, Turnbook is RAG over chat history with everything before the answer built in. A typical RAG stack is assembled from parts; Turnbook runs every step up to the answer on its own and leaves only the answer to the model you already use:
| Step | Typical RAG stack | Turnbook |
|---|---|---|
| Collect | an ingestion script you write | every turn saved automatically from your agents |
| Chunk | splitting rules to tune | one turn per entry, word for word |
| Embed | an embedding API, paid per token | a local model, free |
| Store | a vector database to run | one SQLite file |
| Retrieve | search code to write | words, meaning and time, re-ranked by a small learned score |
| Hand over | prompt-assembly code | a bounded evidence packet over MCP |
| Answer | your LLM | your LLM (Claude, Codex, ...) |
The same engine could serve a chatbot that remembers each of its users, a support bot that recalls past tickets, or a team's searchable decision log. Today it ships as a personal, local memory; a Python API and multi-user server mode are not built yet. Interested? Open an issue.
Does it work?
LongMemEval is the public benchmark for long-term chat memory: 500 questions over about 50 past sessions each. Every system below got the same answer model (gpt-5-mini), the same prompt and the official gpt-4o judge; only the memory differs.
| accuracy | model tokens spent saving memory | text the answer model reads | |
|---|---|---|---|
| Turnbook 0.10.0 | 91.8% (all 500) | 0 | 3.1k tokens |
| Turnbook 0.9.9 | 88.8% (all 500) | 0 | 3.4k tokens |
| agentmemory | 80.4% (same 499) | — | ~16.5k tokens |
agentmemory was measured against 0.9.9, which scored 89.0% on agentmemory's 499. Retrieval alone, on agentmemory's own measure (an answer session among the first 5 retrieved): Turnbook 0.9.9 98.5%, agentmemory 95.2%. A question the answer model leaves unanswered (it spends its whole output limit thinking) counts as wrong, as in every Turnbook score here.
Fewer tokens for the same accuracy
0.10.0 changes the search model for new installs from mpnet to EmbeddingGemma. The same 500 questions, the same reader and judge; only the search model and the packet size differ:
| search model | text the answer model reads (median) | accuracy |
|---|---|---|
| mpnet | 3.4k tokens | 86.6% |
| mpnet | 6.7k tokens | 89.6% |
| mpnet | 13.2k tokens | 90.4% |
| mpnet | 26.3k tokens | 91.8% |
| EmbeddingGemma | 3.1k tokens | 91.8% |
Against mpnet at the same size, EmbeddingGemma answers 33 questions mpnet misses and misses 7 it
answers (p = 0.00004). Questions that need several past sessions gain most: 73.6% → 88.4%. The
re-ranker weights for each model were trained on LoCoMo and LongMemEval together. These packets
held up to 15,000 characters; since 0.10.0 brain_context sends up to 30,000 by default
(max_chars sets it). Its retrieval on LoCoMo, scored on conversations its weights never saw
(answer turn among the first 10 found): 83.7%, mpnet 70.2%.
research/runs/graph-v9.14-full500-mpnet8-gemma
As the memory grows
The charts below were measured with 0.9.47 and its search model (mpnet). With 0.10's model, at 6,000 turns the answer turn is among the first 30 found for 92.5% of questions (0.9.47: 82.8%); the larger memories are still being measured.
Recall gets harder as memory piles up: more past conversations look like the one you mean. Since 0.9.46 Turnbook orders what it finds with a small learned score instead of a fixed blend. On LoCoMo (1,536 questions), with each person's memory grown to 10× by storing other conversations beside it, the share of questions whose answer reaches the model fell 5.6 points before (82.5% → 76.9%) and 3.1 points now (83.5% → 80.4%). Each conversation was scored with weights learned on the other nine; the added conversations are other people's, likely easier to tell apart than one person's own history. On LongMemEval the same change took the answer reaching the model from 97.5% to 98.3%.
0.9.47 adds more to that score (how rare the shared words are, how much of one past conversation was found) and looks at 100 candidates per search instead of 50. With LoCoMo inside a memory grown to 205,000 turns, the answer turn is among the first 30 found for 79.7% of questions, against 73.0% with the fixed blend of 0.9.45; a search takes about 0.4 s there.

In Korean
Four LoCoMo conversations translated into Korean (582 questions). Search by meaning alone, share of questions whose answer turn is among the first 30 found:
| search model | English | Korean | Korean question, English memory |
|---|---|---|---|
| mpnet | 75.6% | 67.5% | 70.6% |
| EmbeddingGemma (0.10.0 default) | 90.2% | 86.9% | 87.8% |
With all of search (words, meaning, re-ranker) on mpnet, 0.9.47 found the answer turn among the first 30 for 77.5% of Korean questions (84.7% in English); word search finds "콩이" in "콩이를" (Korean particles). research/runs/graph-v9.21-korean
Every question, answer and verdict is in research/runs/; method, failures and
how to rerun it: docs/benchmarks.md.
FAQ
Will it slow my PC down? The background service uses about 2% of one CPU core when nothing new is coming in. An app's memory server holds about 525 MB with EmbeddingGemma (772 MB with mpnet). A memory search takes about 40 ms (46 ms at the 95th percentile on a GitHub runner; mpnet 26 ms); the first one after an app starts, about 1.4 s. Each new turn takes about 0.1 s to embed; the service runs below normal CPU priority and embeds backlogs at half pace. On a first install, the conversations already on the PC are read in the background while word search answers at once.
Which search model? EmbeddingGemma
(about 200 MB, downloaded from Hugging Face on first use). A memory from 0.9.47 or before keeps
searching with its old model (mpnet) while the background service reads it again with
EmbeddingGemma, a few pieces at a time when nothing else is due; then it moves over by itself.
turnbook model shows which model is in use; turnbook model multilingual keeps mpnet for good.
EmbeddingGemma is provided under the
Gemma Terms of Use; it is not part of Turnbook's own code
or license.
What does it cost? Nothing. No API key and no model calls of its own; your AI app reads a packet of a few thousand tokens when a question needs the past.
Does anything leave my PC? No, unless you share the memory with your own other PCs or a team. No telemetry. Secrets (API keys, passwords, card numbers...) are masked before storing.
How is this different from CLAUDE.md or an app's built-in memory? Those keep notes a model wrote, one app at a time. Turnbook keeps every turn as it was said and shares it across every app and model on the PC.
Korean? Yes: Korean and English conversations, and questions in either language. With the default model, search by meaning trails English by about 3 points in Korean, and a Korean question finds an English memory about as often: In Korean.
How do I remove it? turnbook-uninstall disconnects every app and stops the service; the
memory stays in ~/.graph-mind unless you add --purge.
More
MCP tools · See your memory in 3D
(turnbook-view) · Changelog · Security ·
Development: pip install -r requirements.txt, then python -m unittest discover -s tests
Contributions are welcome. License: Apache-2.0.
1 maintainer

Metadata
1 maintainer
Release files for turnbook 0.10.1
For a detailed explanation of source distributions (sdists) and built distributions (wheels), please see the package formats documentation.
Source distribution (sdist)
| File | Size | Uploaded | Provenance | Actions |
|---|---|---|---|---|
| turnbook-0.10.1.tar.gz | 249.2 kB | With provenance | Details for turnbook-0.10.1.tar.gz |
Built distribution (wheel)
| File | Interpreter | ABI | Platform | Actions Reset |
|---|---|---|---|---|
| turnbook-0.10.1-py3-none-any.whl | Python 3 | none | any | Details for turnbook-0.10.1-py3-none-any.whl |
Total release size: 443.9 kB
Release files / turnbook-0.10.1.tar.gz
| Download URL | turnbook-0.10.1.tar.gz |
|---|---|
| Size | 249.2 kB |
| Tags | Source |
|
SHA-256 checksum How to use checksums |
eda1e51852c220219f378b38a416280b5b878c05d190f119225c6c13e7c4413b
|
|
BLAKE2b-256 checksum How to use checksums |
28456b4f59a2f4e1437581490d94d4967f35bcf7c5d4d8e1a789562fa1dcbd97
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
Yes |
| Uploaded via |
twine/7.0.0 CPython/3.13.16
|
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.


PyPI Publish Attestation
PyPI verified that this artifact, at this checksum, originated from the publisher listed below.
Signed by GitHub Actions, verified by PyPI on Oct 30, 2026.
Transparency logRelease files / turnbook-0.10.1-py3-none-any.whl
| Download URL | turnbook-0.10.1-py3-none-any.whl |
|---|---|
| Size | 194.7 kB |
| Tags | Python 3 |
|
SHA-256 checksum How to use checksums |
d913a5a32543654f216c2fade1ea7081af272e1a1bb98da4895e846ae2978915
|
|
BLAKE2b-256 checksum How to use checksums |
dd0e49d07b712f3ab83c43a5c5064316b927fdaacb8ef43f03f1420813a7f6bd
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
Yes |
| Uploaded via |
twine/7.0.0 CPython/3.13.16
|
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.
PyPI Publish Attestation
PyPI verified that this artifact, at this checksum, originated from the publisher listed below.
Signed by GitHub Actions, verified by PyPI on Oct 30, 2026.
Transparency logSecurity for turnbook 0.10.1
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.
Full provenance
All 2 files in this release have been uploaded with provenance metadata.
Attestation for turnbook-0.10.1.tar.gz
PyPI Publish Attestation
PyPI verified that this artifact, at this checksum, originated from the publisher listed below.
Signed by GitHub Actions, verified by PyPI on Oct 30, 2026.
Transparency logA note on package security
PyPI is a repository for distributing packages, not a service for auditing them. While third-party security researchers and our staff do their best to detect and remove malicious packages, PyPI cannot guarantee the quality, security or suitability of any given package.
To learn more about protecting yourself from malicious actors, visit our package security documentation.














