
unimut
unimut (universal mutator) is a mutation testing tool that finds tests you are missing, built to scale across a project's whole lifecycle: a fast, precise gate on individual PRs (--diff), an exhaustive nightly audit of legacy code (--whole-file), and parallel execution across CI cores (--jobs) -- all from one tool, working on any language with a registered backend.
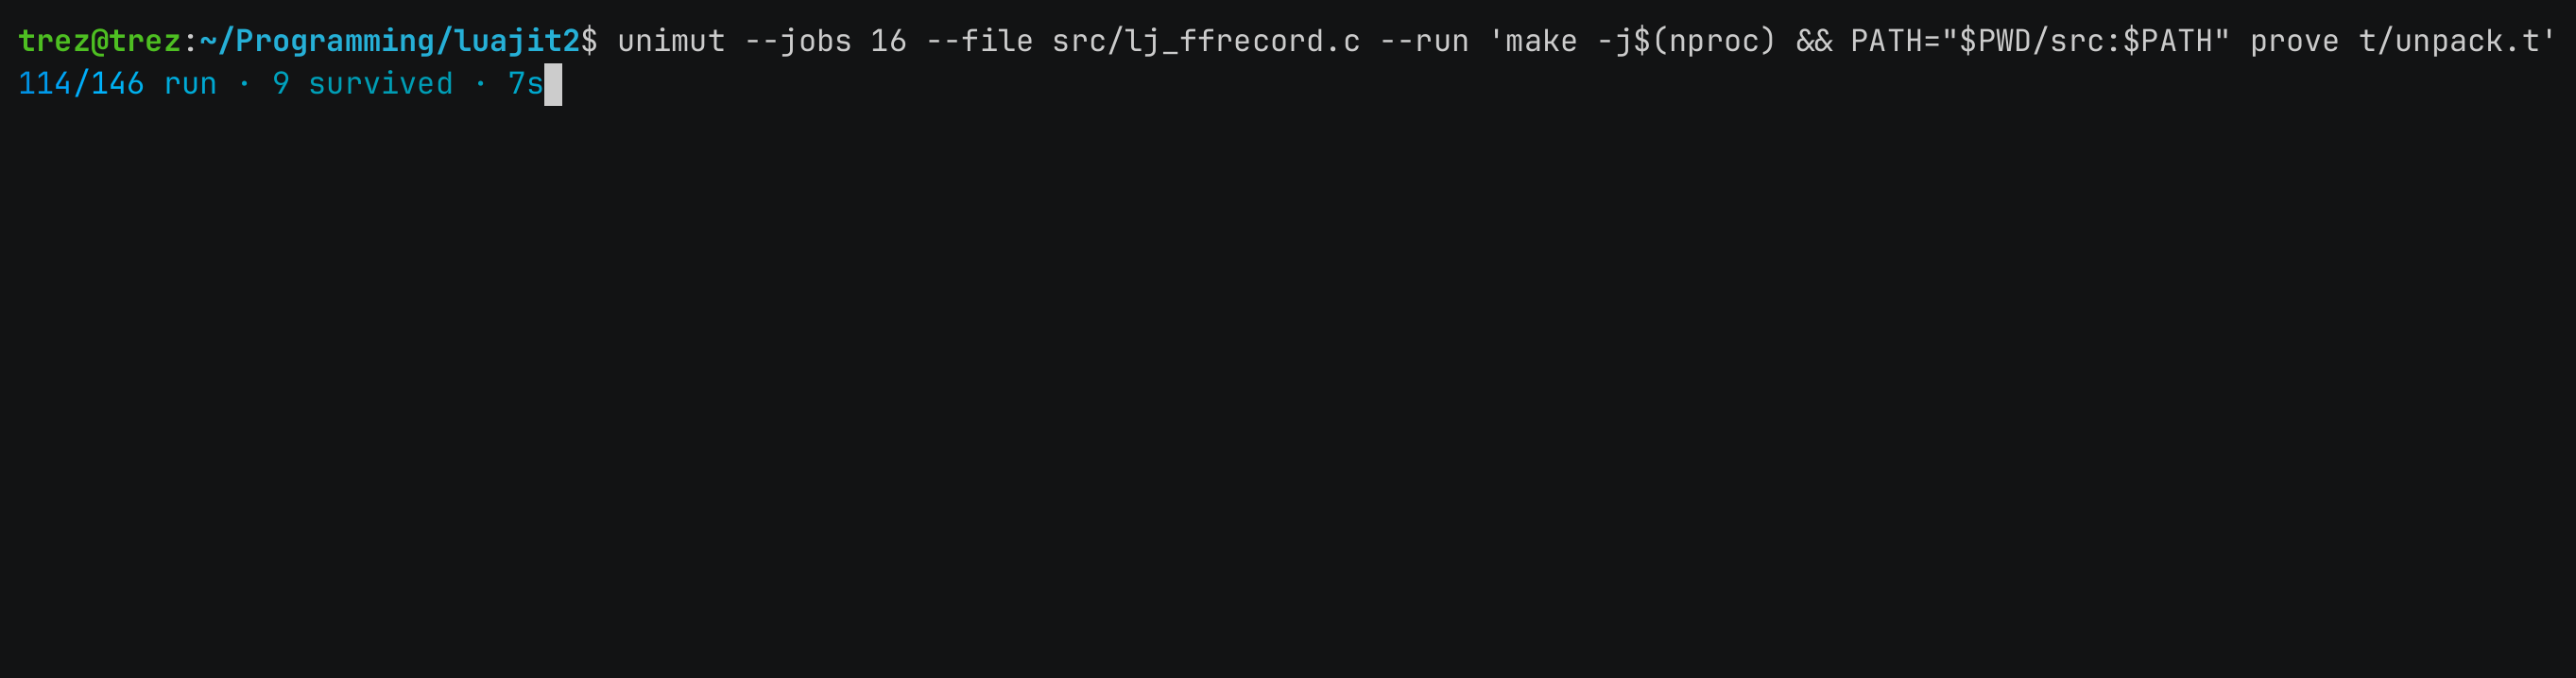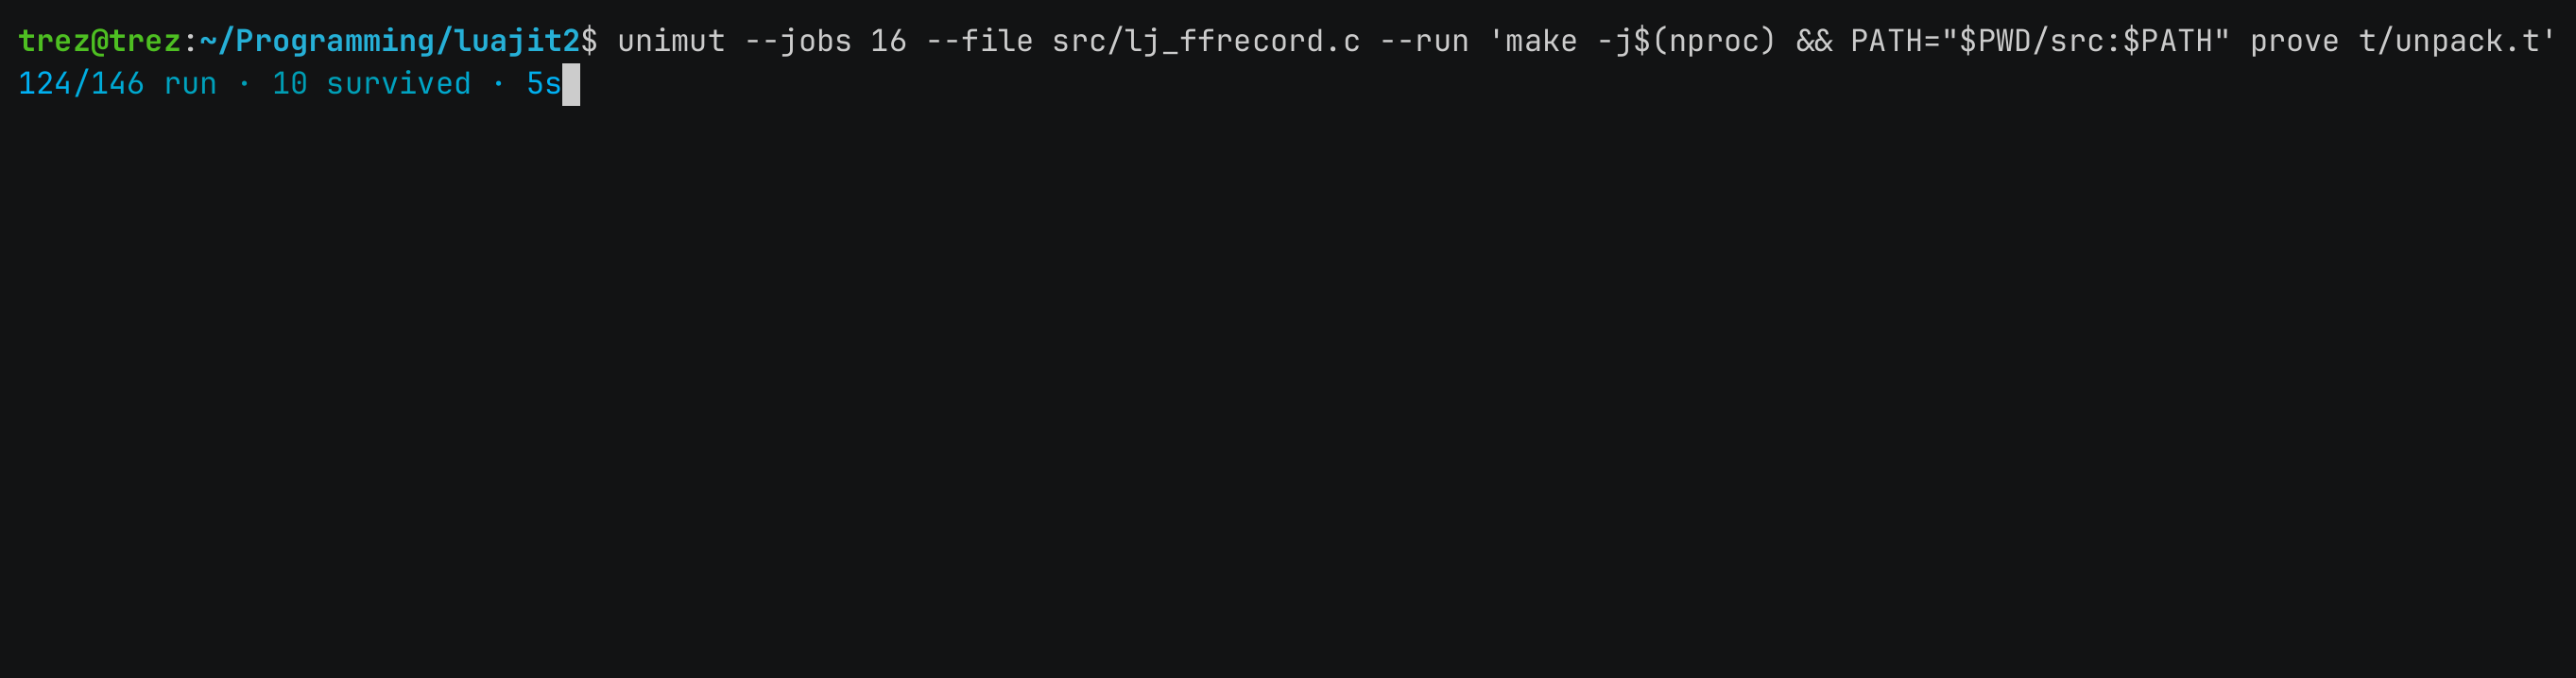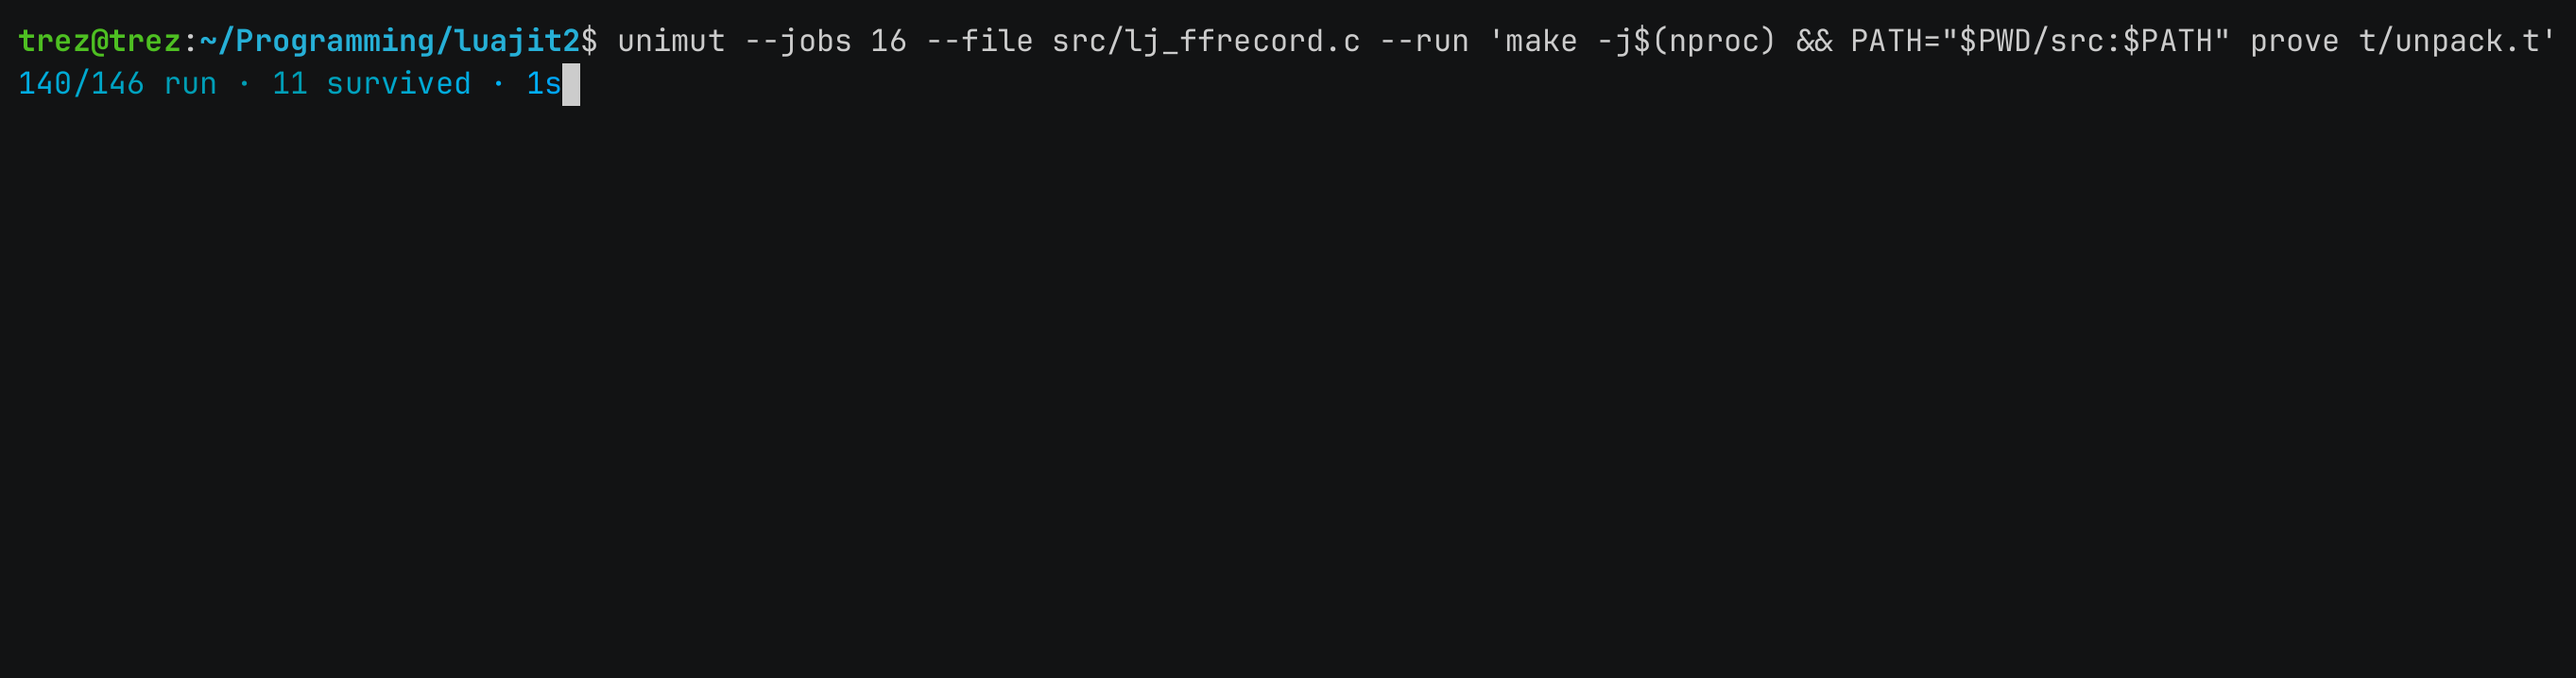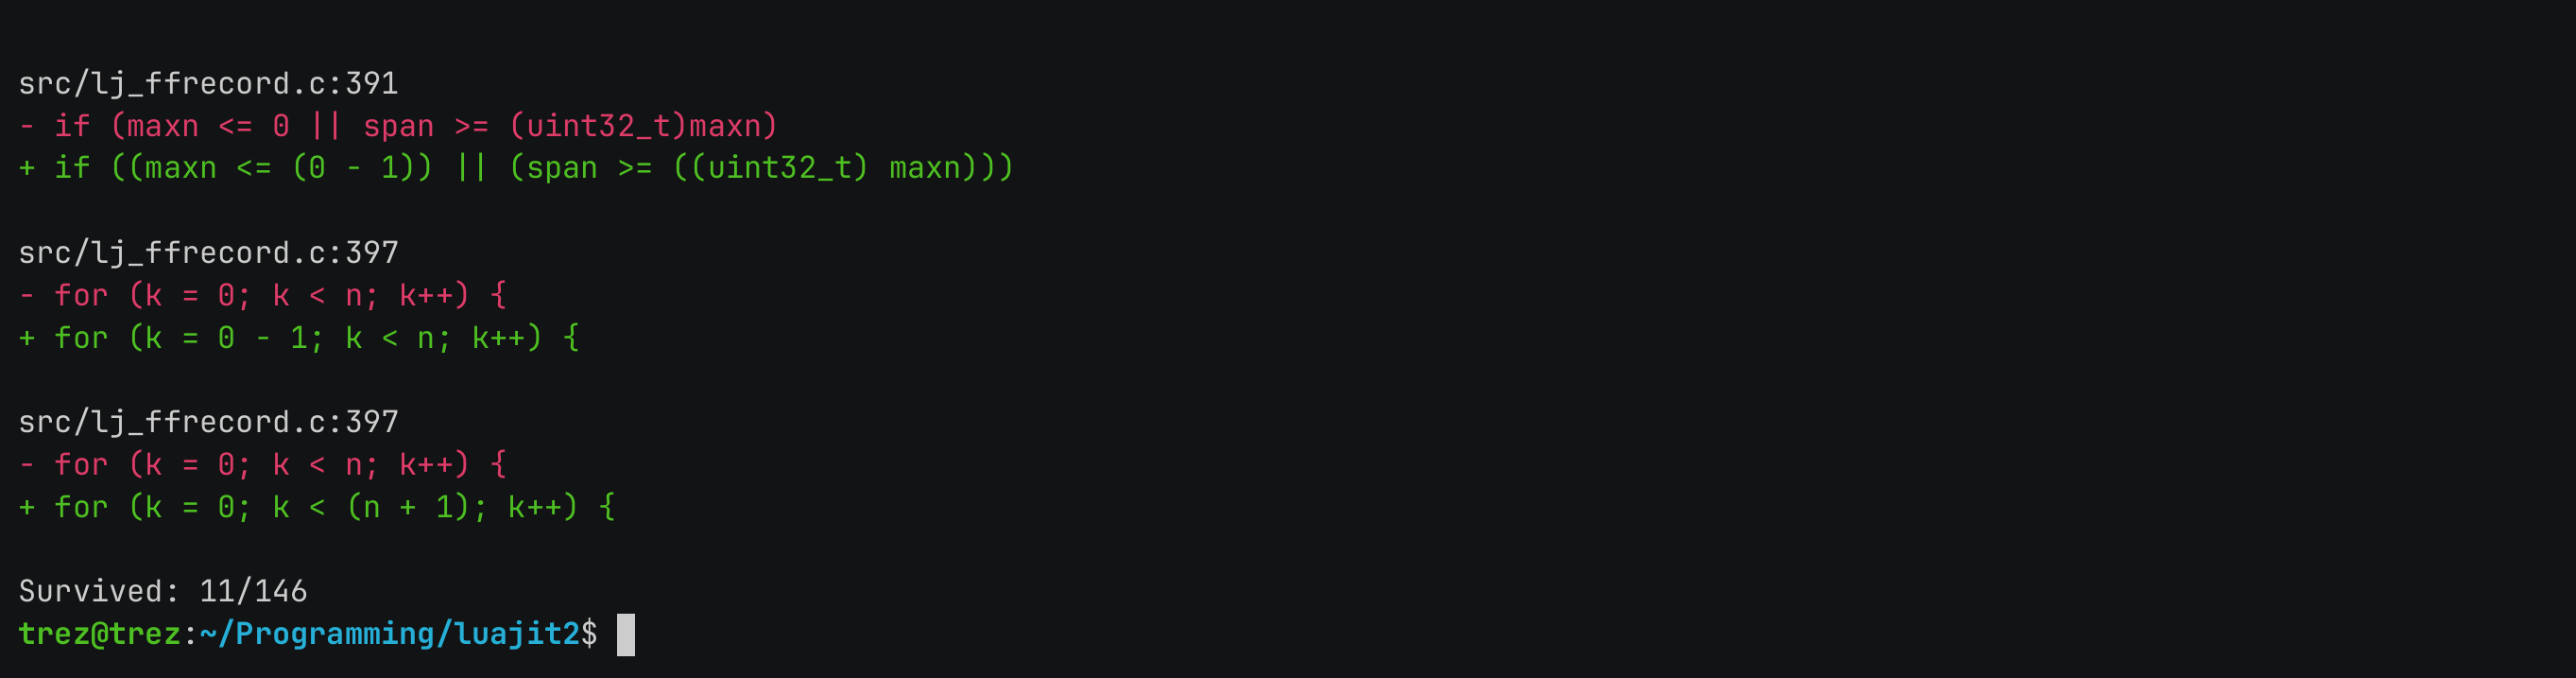
unimut tries mutations of your code and runs a --run command (typically "rebuild, then test") against each one:
- A mutant your tests catch (
--runfails) is killed -- the good outcome, and hidden by default. - A mutant your tests miss (
--runstill exits 0) survived -- a sign you're missing a test -- and gets printed.
Every mutant changes exactly one thing -- one statement removed, one operator swapped, one constant nudged -- never several at once. This is what keeps unimut computationally feasible at all: the mutant count grows linearly with the number of mutation sites, not combinatorially with every possible combination of them (which would be 2^n for n independent single-point mutants -- intractable past a handful of lines). It also keeps every survivor legible: when a mutant survives, you know precisely which one-line change your tests failed to notice, rather than being left to guess which part of a bundle of simultaneous changes was the one that mattered, or whether two changes happened to cancel each other out. The known gap this leaves is coupling failure -- two simultaneous faults that mask each other, which no single-mutation test could ever catch even with full first-order coverage -- but mutation testing's "coupling effect" hypothesis (tests that catch simple faults tend to also catch complex ones built from them) is why tools converge on first-order mutation anyway: it captures most of the signal for a small fraction of the cost.
$ unimut --file src/lj_ffrecord.c --run 'make -j$(nproc) && PATH="$PWD/src:$PATH" perl t/unpack.t'

src/lj_ffrecord.c:13
- if (tref_isnil(tri)) i = 1;

src/lj_ffrecord.c:27
- if (i > e) { rd->nres = 0; return; }

Survived: 2/44
- lines (removed code) print red; + lines (replacement code, for mutation kinds that have one) print green. unimut exits 0 if nothing survived, 1 otherwise (or on error) -- usable as a CI gate.
Installing
pip install unimut
or pip install -e . from a checkout for development. Requires Python 3.9+; the bundled C backend pulls in pycparser automatically.
Choosing what to mutate
| Mode | What it mutates |
|---|---|
| Default | Code wrapped in // unimut on / // unimut off markers |
--diff REF |
Whole file, filtered to lines that differ from REF |
--whole-file |
Whole file, exhaustively |
Default: marker-based
// unimut on
static void LJ_FASTCALL recff_unpack(jit_State *J, RecordFFData *rd)
{
  ...
}
// unimut off
Wrap a whole function, or just a run of statements as they'd appear inside one. A file can hold multiple on/off pairs; they cannot be nested.
--diff REF: a fast PR gate
unimut --file src/api.c --diff main --run 'make -j$(nproc) && make test'
Scans the whole file, but keeps only mutants on a line git diff REF...HEAD -- src/api.c reports as changed. A PR only has to prove the lines it touched are covered, not the whole file -- turning an hours-long whole-codebase run into a seconds-long diff-sized one. REF is anything git diff accepts (main, origin/main, a SHA); requires --file to be inside a git repo with REF resolvable.
--diff implies whole-file scanning, so the marker inversion below applies to it too.
--whole-file: a slow nightly audit
unimut --file src/api.c --whole-file --run 'make -j$(nproc) && make test'
Mutates every statement in the file -- the right mode for periodically auditing legacy code that never got markers. If // unimut on/off markers are still present, their meaning inverts: an off/on pair now marks a range to exclude, the same way tools like clang-format reuse on/off markers:
// unimut off
die("Out of memory"); // no test can reliably trigger this allocator failure
// unimut on
Excluded text still has to be part of a file that parses as C overall -- exclusion hides a range from mutation, not from parsing.
Running it
unimut --file <path> --run '<shell command>' [--diff REF | --whole-file] [--jobs N] [--keep-call NAME ...]
unimut never mutates your real files. It copies the whole repository (via git rev-parse --show-toplevel, or the current directory if that isn't a git checkout) into an isolated temp directory per job, and mutates and builds/tests that copy instead -- your working tree is untouched even if --run crashes or you hit Ctrl-C.
--jobs N runs N mutants at a time, each in its own worker process with its own repo copy -- not threads. Applying a mutant re-parses code with pycparser, which is CPU-bound pure Python and holds the GIL, so threads would mostly serialize on that step regardless of idle cores; separate processes don't share a GIL and actually scale with --jobs.
Every run also does one baseline check: build/test the code completely unmodified, to confirm --run actually passes before trusting any mutant result. It's not run up front and serially -- it's just one more job in the same worker pool, so it costs no extra wall time when it passes. If it fails -- including timing out, see below -- mutant results would be meaningless (a broken build "survives" every mutation), so unimut cancels whatever mutants haven't started yet and reports the baseline's own output instead of the usual survivor list.
--timeout SECONDS (default 10) bounds how long any single --run invocation gets, to catch mutations that hang -- e.g. removing a loop's increment and turning it infinite. A mutant that times out is killed (the whole process tree, not just the immediate shell) and silently treated as killed, same as any other non-surviving mutant. Raise it if your own --run legitimately takes longer than that (a slow test suite, a heavy build) -- and lower it if you want faster feedback on infinite-loop-style mutants and know your real runs are quick.
While mutants run, a live n/m survived · ETA line updates in place (spinner included) if stdout is a terminal; piping to a file or CI log disables it and prints nothing extra.
Options
| Flag | Meaning |
|---|---|
--file PATH |
source file to mutate (required) |
--run CMD |
shell command to build/test each mutant (required unless --print-mutant-counts) |
--lang NAME |
override language detection from --file's extension. Valid values come from whatever backends are discovered -- see Adding another language |
--diff REF |
PR-gate mode (see above) |
--whole-file |
nightly-audit mode (see above) |
--jobs N |
run N mutants at a time, each in its own isolated process (default: 1) |
--timeout SECONDS |
kill (and silently treat as killed) any mutant whose --run exceeds this many seconds; a baseline timeout is an error instead (default: 10) |
--keep-call NAME |
never remove a statement that's just a call to NAME (e.g. --keep-call printf --keep-call print_int), so logging calls most applications never test don't get reported as untested -- not meant for assertions, which should stay a mutation target; repeatable |
--print-mutant-counts |
print how many mutants would be tried, and exit |
--include-killed-mutants |
also print killed mutants, not just survivors |
--exit-on-first-survivor |
stop as soon as any mutant survives instead of running the rest -- for fast local iteration |
A note on "ignored" compile failures
A mutation that fails to compile just makes --run fail like any other test failure, so it's counted and treated as killed -- there's no separate "ignored" bucket. That's intentional: a mutant that doesn't compile is indistinguishable from one a test caught, and should be, since either way nothing survived.
The C backend (mutate_c)
Lives at src/unimut/langs/mutate_c.py -- see Adding another language for what "lives in langs/" buys it. It's built on pycparser, which has no preprocessor and no idea what your project's types are called. Real code (like the LuaJIT recorder functions this was built for) uses unknown types (TRef, jit_State) and calling-convention macros (LJ_FASTCALL) that won't parse as-is, so mutate_c.py does a heuristic pre-pass first: strip comments (preserving line numbers), drop bare ALL_CAPS tokens in front of name(, and synthesize fake typedef int Name; stand-ins for identifiers that look like unknown types, on top of a small <stdint.h>-style preamble.
This recovers the statement structure of typical C -- enough for statement removal -- but it's not a general C frontend, and treats every unknown type as int-sized. A region that genuinely can't be parsed this way raises a clear error rather than silently doing the wrong thing.
Because pycparser's generator doesn't preserve formatting, applying a mutant regenerates the whole marked (or whole-file) region through pycparser's CGenerator; everything outside it is left byte-for-byte identical.
Run its own test suite (hardcoded C strings, no fixture files, compiled with whatever of cc/gcc/clang is on PATH) with:
python -m unittest discover -s src -p "*.py" -v
Currently implemented: statement removal, comparison-operator swap (==, !=, <, <=, >, >=), recursive ±1 boundary mutation on RHS subexpressions, and else-unwrapping.
Mutation kinds still to add
High priority
- Boolean negation insertion (
!) -- wrap every boolean subexpression, one at a time and at every nesting depth, in!.if (foo)becomesif (!foo);if (foo && bar)becomesif (!foo && bar),if (foo && !bar), andif (!(foo && bar)). - Logical connector replacement (
&&↔||) -- same idea as the existing comparison-operator swap, one level up, for compound conditions. - Bitwise/shift operator replacement (
&,|,^,<<,>>) -- swap each bitwise op for every other one in its class (keep shifts separate from&/|/^). Untouched by any current operator, and likely the single highest-value addition for bit-twiddling-heavy code like LuaJIT's tag checks, flag masks, and shift-based encoding. - Arithmetic operator replacement (
+↔-,*↔/, plus%) -- swapping the operator between two full subexpressions (a * b→a / b), distinct from the existing±1boundary mutation on RHS values. - Cast/width mutation -- flip an explicit cast's signedness (
(uint32_t)↔(int32_t)) or widen/narrow between fixed-width types. Directly targets the class of bug that careful overflow-safe code (e.g. computing a span asuint32_tspecifically to dodge signed overflow) is meant to prevent. - Increment/decrement mutation --
i++↔i--, and separately pre ↔ post (++i↔i++). Cheap to generate, common bug class in loop counters and pointer walks.
Medium priority
- Return-value mutation -- for
return expr;, offerreturn 0;,return !expr(in boolean context), or swapexprfor another in-scope variable of compatible type. - Break/continue swap inside loops -- invisible to statement removal, since swapping the keyword rather than deleting the statement is a different failure mode.
- Array/pointer subscript off-by-one, independent of assignment RHS -- the existing
±1mutator walks RHS-of-assignment subexpressions recursively; a subscript sitting inside a function-call argument may not be reached the same way. Needs checking whether_find_rhs_targetsalready covers call arguments generally, or is scoped to assignment statements.
Low priority
- Function-call argument swap -- for a call with two-or-more arguments of the same declared type, swap an adjacent pair.
sizeofargument mutation -- swapsizeof(X)forsizeof(Y)whereYis another in-scope type/variable, particularly around allocation/copy sizes. More generally useful across other files than inlj_ffrecord.citself.
Note: logical (&&/||) and bitwise (&/|) swaps on boolean-typed (0/1) operands will often produce equivalent mutants for structural reasons (same as k != n vs k < n today) -- expect some of that noise rather than treating every survivor from these two as an actionable gap.
The Python backend (mutate_python)
Lives at src/unimut/langs/mutate_python.py, and is deliberately much smaller than mutate_c.py: Python has no preprocessor to work around (no macros, and being dynamically typed, no "unknown type" to guess the width of), so there's no equivalent of mutate_c.py's heuristic pre-pass at all. It parses the whole file with the stdlib ast module in one call, rather than slicing out just the marked region the way mutate_c.py does -- slicing wouldn't generally produce valid Python on its own, since indentation is syntax, and a marked region inside a method body carries indentation that's invalid as top-level code. Regenerating a mutant is one ast.unparse() call over the whole (modified) tree.
Currently implemented: statement removal only -- the same starting point mutate_c.py had. Nothing else on mutate_c.py's mutation-kind list (operator swaps, boundary mutation, etc.) is Python-specific to add, this file just hasn't grown them yet. --diff, --whole-file, and --keep-call also aren't implemented yet (generate_mutants here takes no extra keyword arguments), so unimut correctly refuses those flags for .py files rather than silently ignoring them.
One difference worth knowing, not a bug: since mutants are produced by re-serializing the whole file via ast.unparse(), the copy of the file actually handed to --run has no comments in it at all (ast doesn't retain them) -- harmless for running the code, but unlike mutate_c.py, which leaves everything outside the mutated statement byte-for-byte untouched. What unimut's own report shows is unaffected either way: the - ... line always comes from the real source text, never from ast.unparse()'s output.
Adding another language
Language backends are plain modules exposing:
EXTENSIONS: set[str]  # e.g. {".c"}

def generate_mutants(file_path: str, source: str) -> list[Mutant]:
    ...
Mutant and the exception type a backend raises for an unparseable region both live in unimut.langs, shared by every backend rather than defined per-backend:
from unimut.langs import Mutant, MutationError
Mutant has .file, .line, .original, .mutated (str | None), and an .apply(source: str) -> str method that must be picklable (--jobs ships mutants to worker processes -- a plain closure won't survive that; see _RemoveStatementApply in mutate_c.py or mutate_python.py for the pattern). Raise MutationError (not your own exception class) for a region that can't be turned into mutants -- that's what lets unimut's CLI catch a failure from any backend, built-in or your own, with a single except clause.
To support --diff/--whole-file, also accept whole_file: bool = False and changed_lines: set[int] | None = None; to support --keep-call, accept keep_calls: set[str] | None = None. Backends that omit any of these simply refuse the corresponding flag (see mutate_python.py, which omits all three).
Backends are found automatically -- nothing in unimut.py needs editing to add one, and nothing in unimut.py needs editing for a user to add their own, either:
-
Built-in: drop a
mutate_<lang>.pyfile directly intosrc/unimut/langs/.mutate_c.pyandmutate_python.pyare already there; a third file implementing the protocol above is a complete addition on its own. -
Your own, with zero changes to unimut at all: write
mutate_<lang>.pyanywhere, thenexport UNIMUT_LANG_PATH=/path/to/that/directory
(
os.pathsep-separated, like$PATH, so multiple directories work too). unimut scans every directory listed there formutate_*.pyfiles on every run, imports each one, and registers it under the<lang>in its filename -- somutate_rust.pybecomes available as--lang rust, and matches automatically by extension if its ownEXTENSIONSincludes.rs. This is done early enough that it works correctly with--jobs > 1: your module is imported once in the main process, and every forked worker inherits it already loaded, no re-import needed.
A backend found this way that turns out to be broken (bad syntax, missing generate_mutants, whatever) is treated exactly like a broken built-in backend: discover_languages() raises, and unimut reports it with a clean unimut: error: could not load backend '...': ... message and exits non-zero -- for every invocation, not just ones that would have used it, until the file is fixed or removed from $UNIMUT_LANG_PATH. There's no partial-success mode where the good backends keep working around a broken one.
Planned
- More C mutation kinds beyond the ones already implemented (see The C backend for the specific list) -- these will populate
Mutant.mutatedand print a+line. - More mutation kinds for the Python backend, starting from the same list -- none of it is C-specific,
mutate_python.pyjust hasn't grown past statement removal yet. --diff/--whole-file/--keep-callsupport for the Python backend.- Additional built-in language backends beyond C and Python.
Contributing
This project uses Black and Pyright. Run once to install a pre-commit hook that formats/checks staged files on every git commit:
pip install pre-commit && pre-commit install
1 maintainer

Download files
Download the file for your platform. If you're not sure which to choose, learn more about installing packages.
Source Distribution
Built Distribution
Filter files by name, interpreter, ABI, and platform.
If you're not sure about the file name format, learn more about wheel file names.
Copy a direct link to the current filters
File details
Details for the file unimut-0.1.6.tar.gz.
File metadata
- Download URL: unimut-0.1.6.tar.gz
- Upload date:
- Size: 473.3 kB
- Tags: Source
- Uploaded using Trusted Publishing? Yes
- Uploaded via:
twine/7.0.0 CPython/3.13.14
File hashes
| Algorithm | Hash digest | |
|---|---|---|
| SHA256 |
f60ac296b52849d5a080d98340c25ea9d5938689d326916328bfed6c9c59cdc3
|
|
| MD5 |
2dd72d2a15392d9a9a009af1f4c18025
|
|
| BLAKE2b-256 |
e297862371a0721a18fd7f97783a13b4f31c774197deb3eb07e1112c71bfb97d
|
Provenance
The following attestation bundles were made for unimut-0.1.6.tar.gz:
Publisher:
build.yml on MyNameIsTrez/unimut
-
Statement:
-
Statement type:
https://in-toto.io/Statement/v1 -
Predicate type:
https://docs.pypi.org/attestations/publish/v1 -
Subject name:
unimut-0.1.6.tar.gz -
Subject digest:
f60ac296b52849d5a080d98340c25ea9d5938689d326916328bfed6c9c59cdc3 - Sigstore transparency entry: 2348332827
- Sigstore integration time:
-
Permalink:
MyNameIsTrez/unimut@227a0723f9cb43f496157abc919111be69ce572a -
Branch / Tag:
refs/tags/v0.1.6 - Owner: https://github.com/MyNameIsTrez
-
Access:
public
-
Token Issuer:
https://token.actions.githubusercontent.com -
Runner Environment:
github-hosted -
Publication workflow:
build.yml@227a0723f9cb43f496157abc919111be69ce572a -
Trigger Event:
push
-
Statement type:
File details
Details for the file unimut-0.1.6-py3-none-any.whl.
File metadata
- Download URL: unimut-0.1.6-py3-none-any.whl
- Upload date:
- Size: 64.2 kB
- Tags: Python 3
- Uploaded using Trusted Publishing? Yes
- Uploaded via:
twine/7.0.0 CPython/3.13.14
File hashes
| Algorithm | Hash digest | |
|---|---|---|
| SHA256 |
dfdfa3c2105779fc1230ac1ca5fc677995579adb7789b10178208f52568abb8f
|
|
| MD5 |
71540543e6e32162c969ef302e67fe0c
|
|
| BLAKE2b-256 |
5726aa164d3da13dc07cd33a53c4ccfbe017b760f3084e9cfd460f7ba31c4f5f
|
Provenance
The following attestation bundles were made for unimut-0.1.6-py3-none-any.whl:
Publisher:
build.yml on MyNameIsTrez/unimut
-
Statement:
-
Statement type:
https://in-toto.io/Statement/v1 -
Predicate type:
https://docs.pypi.org/attestations/publish/v1 -
Subject name:
unimut-0.1.6-py3-none-any.whl -
Subject digest:
dfdfa3c2105779fc1230ac1ca5fc677995579adb7789b10178208f52568abb8f - Sigstore transparency entry: 2348332880
- Sigstore integration time:
-
Permalink:
MyNameIsTrez/unimut@227a0723f9cb43f496157abc919111be69ce572a -
Branch / Tag:
refs/tags/v0.1.6 - Owner: https://github.com/MyNameIsTrez
-
Access:
public
-
Token Issuer:
https://token.actions.githubusercontent.com -
Runner Environment:
github-hosted -
Publication workflow:
build.yml@227a0723f9cb43f496157abc919111be69ce572a -
Trigger Event:
push
-
Statement type:














