
UnlimitedPipe



Pipe the public internet.
Collect public web data, transform it, detect what changed, and send it anywhere, from the command line. Local-first, no account, no API key, no AI required. Think Yahoo Pipes, rebuilt as Unix commands.
See it running: 20 free feeds (AI releases, exploited vulnerabilities, cloud incidents, earthquakes, rocket launches…), each one a YAML file of about 15 lines, updated hourly on GitHub Actions. Fork them.
pip install unlimitedpipe

unlimited web https://example.com
unlimited web https://example.com | unlimited select title url | unlimited json
unlimited rss https://hnrss.org/frontpage | unlimited grep AI | unlimited diff --only added
What is UnlimitedPipe?
A small set of Unix-style commands that pass events to each other:
SOURCE  ->  EVENTS  ->  OPERATORS  ->  OUTPUT
web         JSONL       filter         json, jsonl, csv
rss                     select         feed (RSS / Atom / JSON Feed)
file                    diff           your terminal
...                     ...            any tool that reads JSONL
Every event is one line of JSON that records what was observed, where, when, how it was
fetched, and every step that touched it. Pipes work with jq, grep, head and friends.
The same components run from a YAML file with unlimited run.
Why?
Everyone who works with the web has written the same throwaway script: fetch a page, pull out a few values, compare with last time, send a notification. UnlimitedPipe is that script, done once and done well:
- Change detection built in.
diffremembers what it saw and emits only what was added, removed or modified, field by field. - Reads the most reliable layer first. Product data from Shopify, schema.org JSON-LD or OpenGraph before any CSS selector. Feeds before HTML.
- Provenance on every event. Source URL, observation time, fetch method, and each operator that transformed it.
- Polite by default. robots.txt (RFC 9309), one request per second per host,
ETag/If-Modified-Sincerevalidation, an honest User-Agent. - Composable. JSONL in, JSONL out. Plain JSON from other tools is accepted too.
- Extensible. A connector is one small Python class;
pip installmakes it a command.
How it compares:
- Yahoo Pipes (2007–2015) had the right idea: wire feeds and pages together, filter them,
get a feed out. It was a hosted app, and it died with its host. UnlimitedPipe is the same
idea as local commands and text files you own;
publishhosts the result for free on GitHub. - Huginn and n8n are always-on servers with a database and a web UI. UnlimitedPipe needs neither: a pipeline is a YAML file, state is a small JSON file, and a schedule is cron or GitHub Actions.
- RSS-Bridge and RSSHub turn sites into feeds with a server and one bridge per site. UnlimitedPipe reads what sites already publish (feeds, JSON APIs, product data), filters and merges it, and writes feeds as one output among several.
- changedetection.io and paid monitors are apps.
diffgives the same field-level change detection as a pipe stage you can combine with anything. curl | jqhas no memory, no politeness and no change detection. Firecrawl and similar crawlers turn pages into text for LLMs; UnlimitedPipe turns public sources into typed events with history and receipts.
Quick start
pip install unlimitedpipe # Python 3.11+
Look at a page. In a terminal you get readable output; in a pipe you get JSONL.
unlimited web https://example.com
See what a site offers and the best way to read it:
unlimited inspect https://news.ycombinator.com
Hacker News
https://news.ycombinator.com  ·  200  ·  text/html  ·  76 ms
✓ robots.txt    allowed
✗ JSON-LD       none
✗ Products      no product data
✗ OpenGraph     none
✓ Feeds         https://news.ycombinator.com/rss
✗ Sitemap       none found
✓ Readable HTML 666 words without JavaScript
Try:
  unlimited rss https://news.ycombinator.com/rss
  unlimited web https://news.ycombinator.com
  unlimited web https://news.ycombinator.com --selector 'h2'   # pick exact elements
Watch a product. The first run saves a baseline; later runs print only changes.
unlimited web https://www.allbirds.com/products/mens-strider-explore | unlimited diff
Or let UnlimitedPipe write the watch for you, then keep it running:
unlimited new https://www.allbirds.com/products/mens-strider-explore
# Wrote allbirds-com-products-mens-strider-explore.yml: price and stock changes (product data via shopify).
unlimited watch --every 1h allbirds-com-products-mens-strider-explore.yml
new picks the most reliable approach it finds: product data for store pages, the feed for
blogs and news sites, and page text otherwise, with commented hints for narrowing it down.
Sources
| Command | Emits |
|---|---|
unlimited web URL... |
A document per page (title, description, headings, text, feeds). Pages with product data become one product per variant. --selector CSS emits elements, --field NAME=CSS builds records, --emit links emits links. |
unlimited rss URL... |
One entry per item of an RSS, Atom or JSON Feed. Given a page, uses the feed it advertises. |
unlimited file PATH... |
One record per JSON item, JSONL line or CSV row. - reads stdin. |
unlimited github releases|repo|tags|commits|issues OWNER/REPO... |
Public GitHub data through the official REST API. Optional GITHUB_TOKEN for higher limits. |
unlimited bluesky [WORDS...] |
New public Bluesky posts, live, from Bluesky's Jetstream (endless; pip install "unlimitedpipe[live]") |
unlimited inspect URL... |
An inspection: robots.txt, feeds, JSON-LD, products, sitemap, JavaScript, suggested commands. |
Sources also read URLs from stdin, so crawls compose:
unlimited web https://blog.example.com --emit links | unlimited grep 2026 | unlimited web
Public GitHub data comes through the official API, no account needed:
unlimited github releases astral-sh/uv ollama/ollama --limit 3
unlimited github repo pallets/click | unlimited select title stars forks
Operators
| Command | Does |
|---|---|
select title price=offers.0.price link=link|url |
Keep, rename, or fall back between fields |
filter 'price > 100 and availability == "InStock"' |
Keep matching events (syntax) |
filter --field country --eq Thailand |
The same without expression syntax |
map 'price=number(price)' --drop junk |
Set fields from expressions, drop fields |
grep AI LLM |
Keep events mentioning any word (whole words, any case) |
dedupe --by url |
Drop repeats within the stream |
sort --by published_at -r |
Sort (reads the whole stream) |
limit 20 |
First N events, then stop upstream |
diff |
Only what changed since the last run |
extract hashtags|cashtags|domains|words|REGEX |
Pull matches out of text into a list |
count --by tags --every 10m |
Count per value, overall or per time window |
trend |
Values rising sharply compared with earlier windows |
Fields are looked up in data first, then in the envelope (source_url, metadata.status).
Outputs
| Command | Writes |
|---|---|
jsonl [PATH] |
Full events, one per line (--data for data only) |
json [PATH] |
One JSON array of data (--full for whole events) |
csv [PATH] |
Data as CSV, nested fields as dotted columns |
feed PATH |
RSS (.xml), Atom (.atom) or JSON Feed (.json), keeping earlier items |
webhook URL |
A Discord or Slack message per event (recognized from the URL), or the event as JSON |
sqlite FILE |
One row per distinct observation, with JSON columns for SQL queries |
pretty |
Readable terminal output (the default when stdout is a terminal) |
Pipelines
The same components, in one process, from a file:
# competitor-watch.yml
name: competitor-watch

sources:
  - type: web
    url: https://competitor.example/pricing
    each: .plan
    field: [name=.plan-name, price=.price]

operators:
  - type: diff
    key: name

outputs:
  - type: feed
    path: public/competitor.xml
  - type: pretty
unlimited run competitor-watch.yml
unlimited run competitor-watch.yml --validate
unlimited watch --every 1h competitor-watch.yml     # run it every hour until Ctrl+C
Short pipelines don't need a file. Separate stages with -- and they run in one process:
unlimited run web https://example.com -- select title url -- json
unlimited watch --every 30m rss https://hnrss.org/frontpage -- grep AI -- diff --only added
watch keeps going when a run fails, reloads the pipeline file when you edit it, and adds a
little random delay so many watches don't hit a site at the same second.
Mistakes are reported with file, line and a suggestion:
error: competitor-watch.yml:8: sources[0] (web): unknown option 'feild' for web
hint: did you mean 'field'?
Publish a feed for free
publish turns a pipeline into a hosted feed: GitHub Actions runs it on a schedule, keeps the
diff state in your repository, and GitHub Pages serves the result. No server, no account
beyond GitHub.
unlimited publish feeds/*.yml --every 1h
# Wrote .github/workflows/unlimitedpipe-feeds.yml (runs every 1h, cron "54 * * * *")
# Wrote public/index.html
# ...
# Index: https://fuyuki0.github.io/unlimitedpipe-feed-demo/
Live example: the feed catalog, 20 feeds published this way from one
workflow. A feed whose source is down keeps its last good state while the others update. Each
JSON Feed carries full events, so another pipeline can read it with unlimited rss and keep
the provenance chain. Details, cron and manual setups:
docs/pipelines.md.
Change detection
diff stores a small state file per watch and compares each item with the previous run:
- Items are matched by their key: product URL + SKU, feed item id, or
--key FIELD. - Changes come out as
changeevents with field-leveloldandnewvalues. - An item counts as removed only if its page or feed was fetched in this run, so a network failure never looks like everything disappeared.
--only addedturns any feed into a stream of new items; addwebhookto get each change as a Discord or Slack message.--ignore FIELDskips noisy fields.--resetstarts a new baseline.
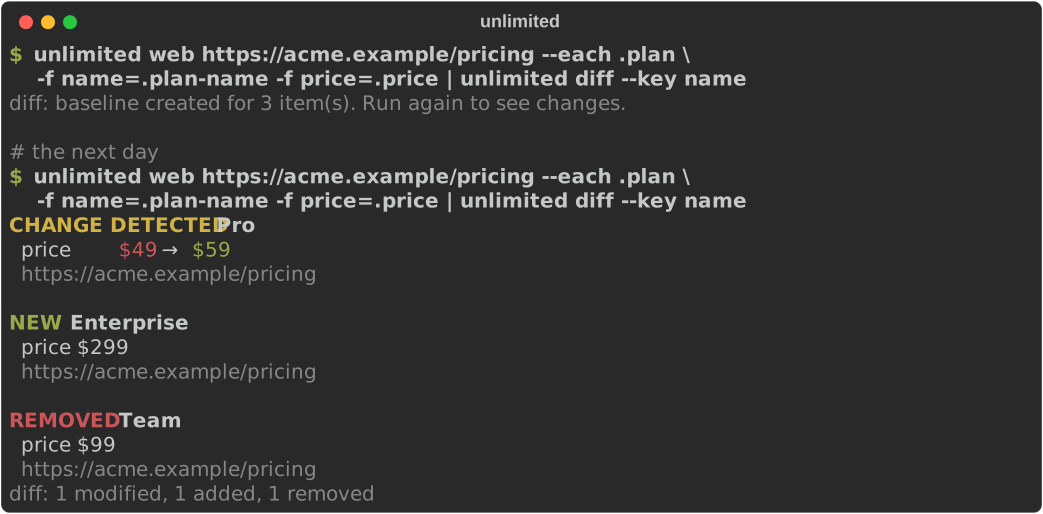
{"type": "change", "key": "https://acme.example/pricing#Pro", "source_url": "https://acme.example/pricing",
 "data": {"change": "modified", "label": "Pro", "summary": "price: $49 → $59",
          "fields": [{"path": "price", "old": "$49", "new": "$59"}], "after": {"name": "Pro", "price": "$59"}}}
State lives in your platform's user state directory; set UNLIMITEDPIPE_STATE_DIR or
diff --state FILE to keep it elsewhere (for example, in a Git repository).
AI integration
UnlimitedPipe is useful without AI and ships no AI models. Agents can use it as a tool (see
the next section). Optional AI operators
(ai extract, ai summarize, ai classify) are planned behind a provider interface with
local models (Ollama) first, and every AI result will keep the provenance of the event it came
from. Until then, pipe events into any LLM command-line tool:
unlimited web https://example.com/changelog | jq -r .data.text | llm "What changed?"
For AI agents (MCP)
unlimited mcp is a Model Context Protocol server, so Claude, Cursor and other agents can
read the public web through UnlimitedPipe and cite where every value came from:
claude mcp add unlimitedpipe -- unlimited mcp                       # Claude Code
unlimited mcp competitor-watch.yml ai-news.yml                      # your pipelines as tools
Built-in tools: fetch_page (products, documents or CSS selections), read_feed,
inspect_url and github. Each pipeline file becomes a tool too, so an agent can ask "what
changed on the competitor's pricing page?" and get the diff result. Results are events with
their source URL, observation time and provenance. Built-in tools refuse private and local
addresses, including through redirects, so a page an agent reads cannot steer it into your
network.
Creating a connector
A source is a small Python class. Its typed fields become CLI options, YAML keys and Python arguments at once:
from unlimitedpipe import Event, Source, arg, opt


class HackerNews(Source):
    """Search Hacker News stories."""

    name = "hackernews"
    query: str = arg("Search words")
    limit: int = opt("Maximum stories", default=30)

    async def collect(self, ctx):
        response = await ctx.http.get(
            "https://hn.algolia.com/api/v1/search_by_date",
            params={"query": self.query, "tags": "story", "hitsPerPage": self.limit},
        )
        for hit in response.json()["hits"]:
            yield Event(source="hackernews", type="story", key=hit["objectID"],
                        data={"title": hit["title"], "url": hit["url"], "points": hit["points"]})
Register it with one entry point, pip install it, and unlimited hackernews "local llm"
works, with rate limiting, retries, robots.txt, --help and YAML support included.
examples/plugin-hackernews is a complete package to copy, and
docs/connectors.md walks through creating, registering, testing,
documenting and submitting one.
Architecture
- Event (
unlimitedpipe.event/1):id,source,type,key,source_url,timestamp,observed_at,data,metadata,provenance. See docs/events.md. - Components are dataclasses: sources implement
collect, operatorsprocessorapply, outputsopen/write/close. The CLI and YAML loader are generated from their fields. - Engine: async generators chained source -> operators -> outputs. Streaming by default;
only
sortand whole-document outputs buffer. Stopping early (limit, Ctrl+C, a closed pipe) closes every stage, and outputs and diff state are always saved. - Network layer: one shared client per run with per-host throttling, retries honoring
Retry-After, RFC 9309 robots.txt withCrawl-delay, conditional requests, and a size cap. - Plugins: the
unlimitedpipe.pluginsentry point group. Commands load lazily, so a pipe stage starts in about 150 ms.
src/unlimitedpipe/
  event.py  component.py  engine.py  context.py  http.py  config.py  cli.py
  expr.py   watch.py  scaffold.py  publish.py  mcp.py
  sources/    web, rss, file, github, bluesky, inspect
  operators/  select, filter, map, grep, dedupe, limit, sort, diff, extract, count, trend
  outputs/    jsonl, json, csv, feed, webhook, sqlite, pretty
Examples
Runnable pipelines in examples/: website to JSON, an RSS news filter published as a feed, GitHub release watching, price monitoring with Discord alerts, competitor pricing watch, multi-source research into CSV, Bluesky trends, and a complete connector package. The feed catalog has 20 more.
Roadmap
- v0.1 Pipe: engine, CLI,
webwith product detection,rss,file,inspect, eight operators, JSON/JSONL/CSV/feed outputs, YAML pipelines, plugins. - v0.2 Feed:
watch,new,publish(free hosted feeds), thegithubconnector. - v0.3 Live (current):
webhook(Discord, Slack),sqlite, the trend engine (extract,count,trend), the liveblueskysource, and the MCP server for AI agents. - Next: optional AI operators (local models first), bot-network filtering for trends, browser fetching and screenshot evidence, more connectors (SEC filings, DexScreener), a public registry of feeds.
Responsible use
UnlimitedPipe is for public data and data you are authorized to access. It uses the front door: official APIs and feeds when they exist, polite HTML otherwise. It does not bypass logins, CAPTCHAs or blocks, and it is not for collecting data about individuals. You are responsible for complying with each site's terms and applicable law. See docs/responsible-use.md.
Contributing
Connectors, recipes and bug reports are all welcome. Start with
CONTRIBUTING.md; make test lint runs the same checks as CI.
License
1 maintainer

Release files for unlimitedpipe 0.3.2
For a detailed explanation of source distributions (sdists) and built distributions (wheels), please see the package formats documentation.
Source distribution (sdist)
| File | Size | Uploaded | |
|---|---|---|---|
| unlimitedpipe-0.3.2.tar.gz | 151.5 kB | Details |
Built distribution (wheel)
| File | Interpreter | ABI | Platform | Reset |
|---|---|---|---|---|
| unlimitedpipe-0.3.2-py3-none-any.whl | Python 3 | none | any | Details |
Total release size: 275.7 kB
Release files / unlimitedpipe-0.3.2.tar.gz
| Download URL | unlimitedpipe-0.3.2.tar.gz |
|---|---|
| Size | 151.5 kB |
| Tags | Source |
|
SHA-256 checksum How to use checksums |
f587c4d004f8eb5d0574b8e55fafc1aa2222416186cc771ef25752037f7b7581
|
|
BLAKE2b-256 checksum How to use checksums |
57be44e9b7750ea1027338a99517861b2ada4542948479ccea59aa8d996cd1b7
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
No |
| Uploaded via |
twine/7.0.0 CPython/3.12.3
|
Release files / unlimitedpipe-0.3.2-py3-none-any.whl
| Download URL | unlimitedpipe-0.3.2-py3-none-any.whl |
|---|---|
| Size | 124.2 kB |
| Tags | Python 3 |
|
SHA-256 checksum How to use checksums |
d32a00e6d83ab55e26d60780072c12fd5218e45ba69f09ba9e907919b4de73c0
|
|
BLAKE2b-256 checksum How to use checksums |
027643be3f88f69574bd205d73314a57c871b0d9326272d9be73f29275871a1d
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
No |
| Uploaded via |
twine/7.0.0 CPython/3.12.3
|














