Valen Python SDK
Fast Decisions. Continuous Evolution.
Bring Valen’s multimodal System One decisions to Python.
English · 简体中文
Valen · Try Valen · Documentation · Models
Python SDK · JavaScript SDK · C++ integration
Valen is a multimodal System One decision model that returns structured decision probabilities for your tasks. This repository provides the Python SDK for Valen.
Run text, image and video decisions inside your Python application. Get categories, yes/no probabilities and scores for ticket routing, content screening and ranking. Use local CPU inference, NVIDIA CUDA or a remote HTTP service. Local inference uses ONNX Runtime without PyTorch or Transformers. Valen.remote on the hosted API reaches Valen-Decision-1.5 0.8B, 2B and 4B through the model IDs valen-0.8b, valen-2b and valen-4b; Valen.local runs the Valen-Decision-1.5 ONNX bundles (Valen-Decision-1.5-0.8B-ONNX, 2B, 4B, 9B, 27B) with results that match the native model, answers bbox questions with them, and runs the Valen-Decision-1.0 ONNX models (Valen-0.8B-ONNX, Valen-2B-ONNX, Valen-4B-ONNX).
Reliability and integration controls
Typed methods validate returned answers against the questions you sent. Invalid or incomplete responses raise ValenResponseError with a field path; raw predict retains the compatibility interface.
from valen_sdk import Valen, Noul

with Valen.remote("https://api.valen-team.workers.dev/v1",
                  timeout=10, total_timeout=25,
                  on_event=lambda event: print(event)) as client:
    response = client.system_one("The order arrived.", {
        "arrived": Noul(instructions="The order arrived.")
    })
Durations are seconds. total_timeout includes retry waits. For cancellable concurrent LLM comparisons, use async with AsyncValen.llm(provider, model, ...); it supports the same question and response interfaces, normalization diagnostics and correction accounting as Valen.llm. normalize_probabilities=False rejects LLM distributions that need rescaling.
Pass http_client= to borrow an existing httpx.Client / httpx.AsyncClient; closing Valen leaves that client open. Pass on_event= to local clients for loading stages, inspect client.info, and use client.warmup(request) to load lazy graphs with a representative request.
See the complete behavior and timeout contract, runnable reliability example and upgrade notes. Events exclude input bodies; explicit LLM debug histories can contain them.
Complete application tutorials
Complete workflows are maintained in the official Cookbook: ticket routing, when no option fits, product-image screening and video tagging. Code, samples and measured outputs share one source. This repository retains SDK interface and installation examples. Valen.local loads ONNX; connect to GGUF services over HTTP. C++ support remains scoped by this repository's reference.
Stable version 0.5.1
Published on PyPI. Install the base package for HTTP clients, or the ONNX extra for local inference:
python -m pip install 'valen-sdk==0.5.1'
# Local CPU inference, Python 3.11+
python -m pip install 'valen-sdk[onnx]==0.5.1'
The 0.2.0 GitHub artifacts remain available. PyPI publication uses GitHub Trusted Publishing without a long-lived PyPI token; see releasing. JavaScript SDK npm availability is tracked separately.
For a first try, use the web experience or free API. See version selection.
Quick start
The repository example below needs Python 3.11+ and Git. It runs on CPU; no GPU is required. Installing the PyPI wheel itself does not require Git:
git clone --branch v0.5.1 --depth 1 https://github.com/valen-team/valen-sdk-python.git
cd valen-sdk-python
python -m pip install ".[onnx]"
python examples/local_decisions.py
A minimal protocol call with Valen-Decision-1.5 follows (the scripts in examples/ use the same 0.8B bundle); the Cookbook owns routing, thresholds and ranking:
from valen_sdk import Valen

with Valen.local("Valen-Team/Valen-Decision-1.5-0.8B-ONNX", variant="fp32") as client:
    result = client.decisions(input="A cat is on the sofa.", questions=[
        {"name": "cat", "type": "predicate", "instructions": "A cat is present."},
    ])
    print(result.by_name("cat").probability)
The first run downloads and caches the selected variant; the full 0.8B FP32 download is about 3.52 GB. Later runs reuse the cache. See the Valen-Decision-1.5 0.8B, 2B, 4B, 9B and 27B cards for model selection and downloads, and the ONNX guide for sizes and validation against the native model.
To install the SDK directly in your own project:
python -m pip install "valen-sdk[onnx]==0.5.1"
Images and video
Minimal local media interface examples remain in examples/. Complete inputs, dependencies, commands, outputs and uncertainty handling live in product screening, video tagging and direct-video basics. Shared Valen/assets/cookbook/ URLs remain stable.
Local HTTP service
Start a CPU service on your machine:
python -m pip install ".[onnx,server]"
valen serve --model Valen-Team/Valen-Decision-1.5-0.8B-ONNX --model-name valen --port 8000
In another terminal, run python examples/http_client.py, or call the service from your application:
from valen_sdk import Valen

with Valen.remote("http://127.0.0.1:8000/v1", model="valen") as client:
    result = client.decisions(
        input="Please send my order to my new address.",
        questions=[{"name": "change_address", "type": "predicate",
                    "instructions": "Is the customer requesting a delivery address change?"}],
    )
    print("Address change probability:", result.by_name("change_address").probability)
For an existing Valen service, install just the base SDK; the HTTP client does not need ONNX Runtime. The Valen.remote URL ends in /v1; pass api_key when the server uses authentication. AsyncValen provides an asynchronous HTTP client with the same api_key, timeout, max_retries and headers options. Failures raise ValenAPIError with status_code, request_id and the service's error detail.
SystemOne
Decisions uses a question list; SystemOne uses questions keyed by ID. Both formats run the same model. Run python examples/system_one.py independently:
from valen_sdk import Choice, Noul, Score, Valen

with Valen.local("Valen-Team/Valen-Decision-1.5-0.8B-ONNX", variant="fp32") as client:
    result = client.system_one(
        "I moved. Please ship my order to 12 Elm Street instead.",
        {
            "intent": Choice(instructions="What does the customer want?", criteria={
                "address": "Change the delivery address", "cancel": "Cancel the order"}),
            "change_address": Noul(instructions="The customer requests a delivery address change."),
            "explicitness": Score(instructions="How explicit is the request?", criteria=[
                "No request", "Asks whether a change is possible", "Explicitly requests a change"]),
        },
    )
    print("Intent:", result.answers["intent"].choice)
    print(f"Address change probability: {result.answers['change_address'].noul:.3f}")
    print(f"Explicitness score (0–2): {result.answers['explicitness'].score:.3f}")
Bbox questions
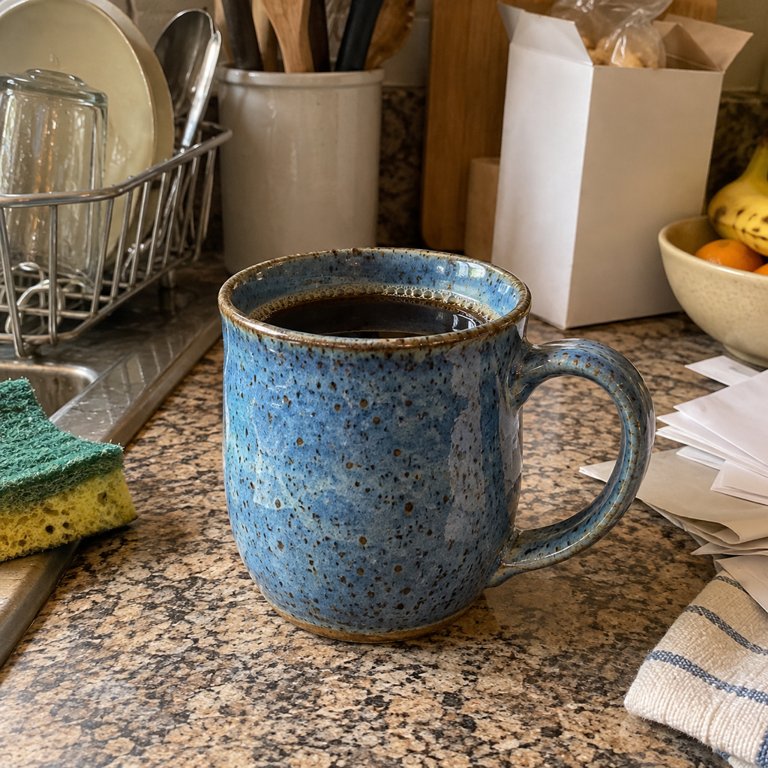
A bbox question locates something in an image and returns bbox [x1, y1, x2, y2], point [x, y] and confidence, normalized to 0–1. Local inference answers it with the grounding graph of a Valen-Decision-1.5 bundle, next to other question types in one request. Download the example image as mug-counter.jpg:
from valen_sdk import Bbox, Noul, Valen

with Valen.local("Valen-Team/Valen-Decision-1.5-0.8B-ONNX", variant="fp32") as client:
    result = client.system_one(
        {"messages": [{"role": "user", "content": [
            {"type": "image_url", "image_url": {"url": "mug-counter.jpg"}}]}]},
        {"mug": Bbox(instructions="The blue mug.", image=0),
         "full": Noul(instructions="The mug has coffee in it.")},
    )
    mug = result.bboxes["mug"]
    print(mug.bbox, mug.point, mug.confidence)
    print(result.nouls["full"].noul)
Decisions requests use {"name": "mug", "type": "bbox", "instructions": "The blue mug.", "image": 0} and return BboxAnswer through result.by_name("mug"). image is the zero-based index of the image to search. See bbox questions for measured output.
Compare with an LLM
Valen.llm sends the same system_one or decisions request to a general LLM and returns the same typed response, so routing rules, thresholds and tests run unchanged against either. Use it to measure what Valen saves on your own data. It ships in the base package; video inputs need valen-sdk[video]. Run python examples/llm_compare.py:
from valen_sdk import Choice, Valen

questions = {"queue": Choice(instructions="Which team should handle this ticket?", criteria={
    "billing": "Payments, charges and refunds", "technical": "Bugs and crashes in the app"})}
valen = Valen.remote("https://api.valen-team.workers.dev/v1", model="valen-2b")
llm = Valen.llm("openai", "gpt-4o-mini")  # reads OPENAI_API_KEY
for client in (valen, llm):
    result = client.system_one("I was charged twice.", questions)
    print(result.model, result.choices["queue"].choice, result.usage.input_tokens)
provider is openai (Chat Completions, also any OpenAI-compatible endpoint through base_url), anthropic or gemini; keys come from OPENAI_API_KEY, ANTHROPIC_API_KEY or GEMINI_API_KEY, or api_key=. Question IDs are not sent to the LLM. Images are sent inline; videos as evenly spaced frames.
| Option | Use |
|---|---|
structured |
Default True uses the provider's JSON Schema output; False asks for JSON in the prompt, for endpoints without structured output |
answer_mode |
probabilities (default): the LLM states a probability per candidate; discrete: it picks one candidate, returned as probability 1 |
n_retry_malformed |
Corrective retries when the output does not match the schema, default 2 |
max_retries |
Retries for rate limits, overload and connection failures, default 2 |
max_tokens |
Output limit; Anthropic defaults to 4096 |
video_frames |
Frames sent per video, default 8 |
extra_body |
Extra provider fields, such as {"temperature": 0} or {"reasoning_effort": "low"} |
LLM probabilities are the model's stated estimates, not Valen's candidate scores; compare decisions and accuracy on labelled cases rather than probability values. usage adds n_retries, n_retries_malformed and latency, summing tokens over every attempt (None when the endpoint omits a count). debug["llm_attempts"] records each provider request and response in order; post a request to the same endpoint to replay it. Truncated output, refusals and context overflow raise ValenAPIError without corrective retries, with the attempts in error.debug.
CUDA
In a separate environment, install python -m pip install ".[cuda]", then select the CUDA variant. Every Valen-Decision-1.5 bundle, 0.8B to 27B, includes cuda-fp16:
from valen_sdk import Valen

with Valen.local(
    "Valen-Team/Valen-Decision-1.5-0.8B-ONNX", variant="cuda-fp16",
    providers=[("CUDAExecutionProvider", {"use_tf32": "0"}), "CPUExecutionProvider"],
) as client:
    result = client.decisions(
        input="Please send my order to my new address.",
        questions=[{"name": "change_address", "type": "predicate",
                    "instructions": "Is the customer requesting a delivery address change?"}],
    )
    print(result.by_name("change_address").probability)
Cache and options
After downloading the model, run from the cache offline:
from valen_sdk import Valen

with Valen.local("Valen-Team/Valen-Decision-1.5-0.8B-ONNX", local_files_only=True) as client:
    result = client.decisions(
        input="Please send my order to my new address.",
        questions=[{"name": "change_address", "type": "predicate",
                    "instructions": "Is the customer requesting a delivery address change?"}],
    )
    print(result.by_name("change_address").probability)
You can also pass a local directory, such as Valen.local("./models/Valen-Decision-1.5-0.8B-ONNX").
| Option | Use |
|---|---|
variant |
CPU default fp32; q8-mlp for a smaller download; cuda-fp16 for CUDA |
cache_dir / revision |
Choose a cache location or HF model revision |
num_threads |
CPU inference threads, default 4 |
execution |
Default shared_state shares one forward pass within a request; question compiles each question separately |
temperature |
Request temperature, default 1 |
media_kwargs |
Set image size, video frame count or FPS |
One local client executes requests serially. predict accepts raw requests and returns dictionaries; decisions and system_one return typed results. HTTP-only clients support Python 3.10+.
More
JavaScript / browser SDK · C++ text integration · Free API documentation · Agent skill · llms.txt
Apache-2.0. See LICENSE and third-party notices.
User guides are maintained only on the website: Documentation · Fine-tuning · Probabilities · Cookbook.
1 maintainer

Metadata
1 maintainer
Release files for valen-sdk 0.5.1
For a detailed explanation of source distributions (sdists) and built distributions (wheels), please see the package formats documentation.
Source distribution (sdist)
| File | Size | Uploaded | Provenance | Actions |
|---|---|---|---|---|
| valen_sdk-0.5.1.tar.gz | 841.7 kB | With provenance | Details for valen_sdk-0.5.1.tar.gz |
Built distribution (wheel)
| File | Interpreter | ABI | Platform | Actions Reset |
|---|---|---|---|---|
| valen_sdk-0.5.1-py3-none-any.whl | Python 3 | none | any | Details for valen_sdk-0.5.1-py3-none-any.whl |
Total release size: 896.5 kB
Release files / valen_sdk-0.5.1.tar.gz
| Download URL | valen_sdk-0.5.1.tar.gz |
|---|---|
| Size | 841.7 kB |
| Tags | Source |
|
SHA-256 checksum How to use checksums |
a0925c3eb2a4c5dcd29e1abc51330a34470993e3ebe5d1d2c94c87eda0318013
|
|
BLAKE2b-256 checksum How to use checksums |
00ea35f5a6191fc7b78a59db14d54d167abb7926b4d4744f0f43cb81b7975d29
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
Yes |
| Uploaded via |
twine/7.0.0 CPython/3.13.16
|
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.


PyPI Publish Attestation
PyPI verified that this artifact, at this checksum, originated from the publisher listed below.
Signed by GitHub Actions, verified by PyPI on Nov 10, 2026.
Transparency logRelease files / valen_sdk-0.5.1-py3-none-any.whl
| Download URL | valen_sdk-0.5.1-py3-none-any.whl |
|---|---|
| Size | 54.9 kB |
| Tags | Python 3 |
|
SHA-256 checksum How to use checksums |
60008a78031d31d8c43b7e3bdeedff1fe7fa2175a841332f12ccee4ecaf73fcf
|
|
BLAKE2b-256 checksum How to use checksums |
12b50f99011bfe6261d63230957f8c15b002a203506d51129ad8057ed5ab869e
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
Yes |
| Uploaded via |
twine/7.0.0 CPython/3.13.16
|
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.
PyPI Publish Attestation
PyPI verified that this artifact, at this checksum, originated from the publisher listed below.
Signed by GitHub Actions, verified by PyPI on Nov 10, 2026.
Transparency logSecurity for valen-sdk 0.5.1
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.
Full provenance
Both files in this release have been uploaded with provenance metadata.
Attestation for valen_sdk-0.5.1.tar.gz
PyPI Publish Attestation
PyPI verified that this artifact, at this checksum, originated from the publisher listed below.
Signed by GitHub Actions, verified by PyPI on Nov 10, 2026.
Transparency logA note on package security
PyPI is a repository for distributing packages, not a service for auditing them. While third-party security researchers and our staff do their best to detect and remove malicious packages, PyPI cannot guarantee the quality, security or suitability of any given package.
To learn more about protecting yourself from malicious actors, visit our package security documentation.