
VanillaSort 🐾
English | 简体中文
📦 Python package · SpikeInterface API · Research & development
VanillaSort combines VanillaDet spike detection, HuiduRep waveform representations, and VanillaCluster clustering. Sort extracellular recordings through a Python API or the vanillasort command and obtain spike times and putative neuronal-unit assignments.
The pretrained pipeline processes multi-channel recordings. The SpikeInterface API also provides an experimental nearest-four-neighbor adapter for larger 2D probes. The main branch contains the installable package, research implementation, and development tools in a shared src/vanillasort/ layout.
📄 Paper: Zishuo Feng and Feng Cao, Spike Sorting with VanillaSort, bioRxiv, 2026. You must cite this paper when using VanillaSort. BibTeX
Meet Vanilla, our lovely Maine Coon! 🤍
📦 Install · 🚀 Quick start · 🐍 Python API · 💻 CLI · 📁 Outputs · 🧠 Architecture · 📊 Results · 🛠️ Development
Installation
Requirements: Python 3.10+, PyTorch 2.7.0+, and CUDA 12.8+ with a compatible NVIDIA driver for GPU execution. Use the latest compatible stable releases whenever possible.
Create a virtual environment:
python -m venv .venv
source .venv/bin/activate
python -m pip install --upgrade pip
On Windows PowerShell, activate the environment with .venv\Scripts\Activate.ps1.
For GPU execution, select Stable and the newest compatible CUDA version 12.8 or later in the PyTorch installation selector. Use its wheel index in the installation command. The table includes a CUDA 12.8 example:
| Platform | Command |
|---|---|
| Linux / Windows, CPU | python -m pip install --upgrade "torch>=2.7.0" --index-url https://download.pytorch.org/whl/cpu |
| Linux / Windows, NVIDIA GPU, CUDA 12.8 example | python -m pip install --upgrade "torch>=2.7.0" --index-url https://download.pytorch.org/whl/cu128 |
| macOS, Apple silicon, CPU | python -m pip install --upgrade "torch>=2.7.0" |
Install VanillaSort from PyPI:
python -m pip install --upgrade vanillasort
The package installs its runtime dependencies. Both model checkpoints (about 36 MiB total) download from Hugging Face on first use and are cached locally. The commands below work from any directory.
Quick start
Run the complete pipeline on the built-in two-second synthetic recording with four mixture components:
vanillasort --self-test --device cpu --output output/self-test
This checks detection, waveform encoding, clustering, and result export. A successful run prints Done: and saves events.npz and run.json in output/self-test/.
For your recordings, --device auto selects CUDA when available and CPU otherwise. Use a new or empty output directory for each run.
Python API
For run_sorter("vanillasort", ...), see the SpikeInterface integration guide for all 17 wrapper parameters, examples, and integration tests. Use a SpikeInterface version containing the updated wrapper; upgrading VanillaSort alone does not update it.
Pass a SpikeInterface BaseRecording with channel locations to vanillasort.sort():
import vanillasort
from spikeinterface.core import load

# recording is your SpikeInterface BaseRecording.
sorting = vanillasort.sort(
    recording,
    components=22,  # choose the GMM component count for your recording
    output_folder="output/recording",
    device="auto",
    seed=0,
)

for unit_id in sorting.unit_ids:
    samples = sorting.get_unit_spike_train(unit_id, segment_index=0)
    print(unit_id, len(samples))

restored = load("output/recording/sorting")
The result is a SpikeInterface BaseSorting. Spike trains use zero-based sample indices within each segment; main_channel_id identifies each unit's main recording channel.
Input: raw recordings with at least 100 samples per segment, and finite 2D channel locations in micrometres. Each channel group or shank must contain at least four contacts. Channel gains and offsets are applied when present; traces otherwise need a common voltage scale. Filtering is internal.
| Option | Default | Purpose |
|---|---|---|
components |
22 |
GMM component count K; choose K ≥ 2 for your recording. |
target_units |
None |
Optional fixed-K merging of local clusters, per segment. |
postprocessing |
None |
Fixed-K policies and thresholds; see below. |
neighborhood_mode |
"dense" |
Original patch selection; opt into "cover" to cover all contacts with fewer detector passes. |
output_folder |
None |
Keep results in memory, or save to a new/empty directory. |
device |
"auto" |
CUDA when available, otherwise CPU; also accepts "cpu" or "cuda:0". |
seed |
0 |
Reproducible initialization; the CLI default is 30. |
profile |
"d1" |
Select "d1" or "canonical" preprocessing. |
enable_gate |
True |
Enable built-in SNR gating, or a supplied custom gate. |
threshold |
None |
Minimum detector score; None uses the model profile (d1: 0.039). |
gate_fn |
None |
Custom gate_fn(context) returning a boolean keep mask; replaces the built-in gate. |
direct_keep |
None |
Built-in gate's direct-acceptance score; model profile default (d1: 0.045). |
primary_snr, secondary_snr |
None, None |
Built-in event-SNR minima; model defaults (3, 2). |
min_secondary_channels |
None |
Required additional channels, 1–3; model default (1). |
model, model_path |
"default", None |
Use the pretrained model or a local checkpoint. |
detector_batch, embedding_batch |
8, 128 |
Inference batch sizes. |
verbose |
True |
Print progress. |
K applies to each neighborhood and segment. A nonempty neighborhood needs at least K sortable events; empty detections produce an empty sorting.
Detection thresholds and gates: after peak selection and refractory NMS, events must have score >= threshold. With the built-in gate enabled, events with score >= direct_keep pass directly; the remaining events require the strongest-channel SNR to meet primary_snr and at least min_secondary_channels other channels to meet secondary_snr. These are per-event negative-peak SNR estimates on the canonical filtered/MAD-normalized signal, not ground-truth unit SNRs. threshold is a sigmoid score in [0, 1], not a voltage threshold. None preserves the loaded model's defaults.
Disable SNR gating while retaining a score threshold, for example:
sorting = vanillasort.sort(recording, components=10, threshold=0.139, enable_gate=False)
threshold and direct_keep are independent: raising threshold above direct_keep makes every eligible event bypass the built-in SNR gate. To keep testing SNR at higher scores, also raise direct_keep, for example threshold=0.139, direct_keep=0.2. These are example settings, not new defaults.
A custom gate replaces the built-in SNR rule, including its direct-acceptance bypass:
import numpy as np

def my_gate(events):
    ranked = np.sort(events.snrs, axis=1)
    return (events.scores >= 0.2) | ((ranked[:, -1] >= 3) & (ranked[:, -2] >= 2))

sorting = vanillasort.sort(
    recording, components=10, threshold=0.139,
    enable_gate=True, gate_fn=my_gate,
)
The callback receives a vanillasort.gating.GateContext once per segment/neighborhood with nonempty threshold-passing candidates. Its read-only CPU arrays are samples (N,), scores (N,), snrs (N, 4), channel_ids (4,), and channel_locations (4, 2). Samples are relative to the segment start; columns follow the supplied channel order. Metadata includes fs_hz, segment_index, neighborhood_index, profile, and event_snr_radius (samples). The return must be a boolean array or list of length N; integers, wrong shapes and callback errors stop the run. Empty input skips the callback. Functions, closures and callable objects are supported; enable_gate=False together with gate_fn is an error.
Neither gate mode changes subsequent main-channel ownership checks, cross-neighborhood deduplication, or waveform-boundary checks. Custom gates can reject candidates but cannot restore events removed by earlier threshold/peak/NMS selection. The resolved settings are stored in run.json under gating and in sorting.get_annotation("detection_gate"); per-neighborhood runs[].gating counts are measured before ownership. config remains the unmodified model configuration. Only the callback's name is saved, so retain its code and any captured parameters to reproduce a custom run. The updated SpikeInterface wrapper accepts all serializable gate options; custom gate_fn callbacks use the direct Python API.
Larger probes: by default the experimental adapter keeps the original nearest-four neighborhoods and ownership ("dense"). Opt into neighborhood_mode="cover" to select a deterministic covering subset, respecting group/shank boundaries. Every contact remains an input and owns exactly one selected patch; not every contact needs to be a patch center. This reduces repeated full-record detector passes. Remaining overlapping detections are still suppressed within 12 samples. A sparser set changes detector contexts and can reduce accuracy; it is therefore explicit rather than the default. Segments receive independent unit IDs. Drift correction and cross-segment unit matching remain future work.
Fixed-K postprocessing: components remains the local GMM size. Set target_units separately to merge local clusters after cross-patch event deduplication:
sorting = vanillasort.sort(
    recording, components=10, target_units=10, neighborhood_mode="cover",
    postprocessing={"on_shortfall": "return_available"},
    output_folder="output/fixed-k", device="auto",
)
The independent utility is vanillasort.postprocessing.postprocess_fixed_k(data, config), where data contains samples, labels, scores, and normalized waves of shape (N, 72, C). The recording API constructs these common-channel waveforms automatically. It ranks reliable local anchors, merges compatible fragments, and deduplicates events within each output unit. It does not fit a global GMM. Defaults preserve the tested coherence/cosine settings; fitting does not consult ground truth.
By default, insufficient reliable anchors raise InsufficientAnchorsError with an .audit diagnostic. on_shortfall="return_available" returns the available nonempty units, including zero, and records exact_k=False. anchor_policy="supplement" explicitly permits observed weak/duplicate clusters and records status="degraded"; it cannot create missing units. Degenerate templates and input noise label -1 are excluded. Invalid inputs are rejected; K=1 is supported. For multi-segment recordings, the target is per segment and output unit identities remain separate.
Results and diagnostics are saved as postprocessing_segment*.npz/json, included in run.json, and available through sorting.get_annotation("fixed_k_postprocessing"). On strict failure the JSON diagnostic is saved before raising. The updated SpikeInterface wrapper accepts target_units, neighborhood_mode, and the postprocessing dictionary through run_sorter().
Memory: traces are read in blocks of at most 300,000 samples for one four-channel neighborhood at a time. Exact filtering and median/MAD normalization require a complete segment in RAM, with an initial memory check. Waveform storage grows with the event count. CUDA memory errors trigger retries with smaller inference batches.
Runtime and progress (since 0.2.0): each selected neighborhood runs a complete detector pass, so runtime grows with the neighborhood count and recording duration. The original dense mode produces 62 neighborhoods for the standard 64-channel, two-column synthetic probe; cover mode selects only a covering subset. verbose=True reports the selected device, neighborhood count, and detection/embedding progress approximately every five seconds (after a batch completes). Per-neighborhood stage timings are saved in run.json under runs[].timings_seconds. The updated SpikeInterface wrapper echoes progress to the terminal and retains its log; spikeinterface_log.json is finalized after sorting ends.
Long rotary-detector inference uses local attention tiles with the original receptive field and checkpoints. CPU API sorting uses up to eight PyTorch threads, respecting a smaller caller limit and restoring that limit afterward. CUDA batch reductions carry over to later neighborhoods in the same sort. Larger probes can still take substantial time; GPU utilization alone does not show which stage is running. With VanillaSort and the updated SpikeInterface wrapper installed, this reproduction script runs the 64-channel, 60-second example using a fixed input seed and reusable recording cache.
Command-line usage
Prepare the input
Save a NumPy .npz archive containing:
| Key | Shape | Content |
|---|---|---|
traces |
(T, 4) |
Raw voltage samples, with time along the first axis. float32 is recommended. |
coords |
(4, 2) |
Physical channel coordinates in micrometres, in the same channel order as traces. |
fs_hz |
Scalar | Actual recording sampling frequency in Hz; defaults to 30000.0 when omitted. |
Use finite values, at least 100 time samples, and a common voltage scale across channels. Filtering and normalization are applied by the pipeline. Use the Python API for larger probes, or export a four-channel group and its matching coordinates for the CLI.
For example, package existing trace and coordinate arrays:
import numpy as np

traces = np.load("traces.npy")  # (T, 4)
coords = np.load("coords.npy")  # (4, 2), micrometres

np.savez(
    "recording.npz",
    traces=traces.astype(np.float32),
    coords=coords.astype(np.float32),
    fs_hz=30000.0,
)
Run sorting
vanillasort --input recording.npz --components 22 --output output/recording-k22
Set --components to the number of Gaussian mixture components, K, chosen for your recording. K must be at least 2, and the number of sortable events must be at least K. The bundled Hybrid Janelia settings use 22 for recordings 11/12 and 24 for 21/22/31/32.
You can also supply separate .npy files:
vanillasort --input traces.npy --coords coords.npy --fs 30000 --components 22 --output output/recording-npy
An NPZ fs_hz value takes precedence over --fs; --coords takes precedence over coordinates stored in the NPZ.
To export spike detections alone:
vanillasort --input recording.npz --detect-only --output output/detections
Outputs
Python API outputs
Passing output_folder saves the following alongside the returned BaseSorting:
| Path | Content |
|---|---|
sorting/ |
Sorting object reloadable with spikeinterface.core.load(). |
events.npz |
Aligned sample_index, unit_id, and segment_index arrays. |
segmentN_patchM.npz |
Detailed arrays for each segment and neighborhood. |
run.json |
Parameters, channel geometry, model hashes, versions, and processing diagnostics. |
Use restored.register_recording(recording) to associate a reloaded sorting with the original traces.
CLI outputs
Each run writes two files:
| File | Content |
|---|---|
events.npz |
Event times, detector scores, and, for sorting runs, labels and model outputs. |
run.json |
Configuration, sampling rate, event counts, normalization statistics, runtime, package versions, checkpoint SHA-256 hashes, and processing diagnostics. |
The following arrays are saved for a completed clustering run. Here, D is the number of accepted detections, N is the number of sortable events, and K is the requested component count.
| Array | Shape | Meaning |
|---|---|---|
detection_samples |
(D,) |
Accepted detection times as zero-based sample indices. |
detection_scores |
(D,) |
Detector sigmoid scores. |
detection_snrs |
(D, 4) |
Per-event, per-channel SNR estimates. |
samples |
(N,) |
Sample indices of events retained for sorting. |
scores |
(N,) |
Detector scores aligned with samples. |
labels, initial_labels |
(N,) each |
Final assignments and initial GMM assignments, indexed from 0 to K - 1. |
features |
(N, 32) |
HuiduRep embeddings standardized across events in the recording. |
auxiliary |
(N, 3) |
Standardized relative-amplitude contrasts. |
templates |
(2, K, 60, 4) |
Waveform templates indexed by target fold, component, sample, and channel. |
core_counts |
(2, K) |
Core-event counts used to determine template availability. |
means |
(K, 35) |
GMM component means in the combined feature space. |
covariances, weights |
(K, 35, 35), (K,) |
GMM full covariance matrices and mixture weights. |
Sorting retains detections satisfying 30 <= sample < T - 30 and extracts waveform offsets -30 through +29. This accounts for the difference between D and N. Detection-only runs save the three detection_* arrays.
Read spike times in seconds and select a unit:
import json
from pathlib import Path
import numpy as np

output = Path("output/recording-k22")
metadata = json.loads((output / "run.json").read_text(encoding="utf-8"))
with np.load(output / "events.npz") as events:
    spike_times_s = events["samples"] / metadata["fs_hz"]
    unit_ids = events["labels"]

unit_0_times_s = spike_times_s[unit_ids == 0]
units, spike_counts = np.unique(unit_ids, return_counts=True)
print(dict(zip(units.tolist(), spike_counts.tolist())))
Times are relative to the start of the supplied recording. Review putative units using their waveforms, firing rates, and inter-spike intervals. The clustering section of run.json records GMM convergence, warnings, template construction, and changes made during assignment refinement.
Models and caching
The default model is hybrid-janelia-2026.09, hosted at Kohaku2580/VanillaSort. Its immutable revision and SHA-256 hashes are recorded in default_model.json. Every load verifies the checkpoint hashes.
Download and verify the weights ahead of a run:
vanillasort --verify-only
The package uses the standard Hugging Face cache (HF_HOME / HF_HUB_CACHE). Set VANILLASORT_MODEL_CACHE to choose another Hub cache root. Once the cache is populated, HF_HUB_OFFLINE=1 enables offline operation.
For a local model:
sorting = vanillasort.sort(recording, model_path="/path/to/model.pt", components=22)
A combined .pt contains detector_state_dict, huidurep_state_dict, and optionally config. A model directory contains config.json plus the two checkpoint files named by detector_checkpoint and huidurep_checkpoint. Model loading uses weights_only=True and strict architecture matching.
Configuration
Common command-line options:
| Option | Default | Purpose |
|---|---|---|
--components K |
Required for sorting your data | Number of GMM components. |
--model-path PATH |
Hugging Face default model | Use a local checkpoint bundle or directory. |
--profile d1 |
d1 |
Select d1 or canonical preprocessing. |
--gate / --no-gate |
--gate |
Enable/disable built-in event-SNR gating; the score threshold still applies. |
--threshold VALUE |
Model profile | Minimum detector score in [0, 1]. |
--direct-keep VALUE |
Model profile | Score that bypasses the built-in SNR check. |
--primary-snr VALUE, --secondary-snr VALUE |
Model config (3, 2) | Nonnegative event-SNR minima. |
--min-secondary-channels N |
Model config (1) | Additional channels meeting secondary SNR, from 1 to 3. |
--seed 30 |
30 |
Random seed for the run and its single GMM initialization. |
--device auto |
auto |
Select auto, cpu, cuda, or a device such as cuda:0. |
--seconds 10 |
Entire recording | Process the first 10 seconds; the value must fit within the recording. |
--detector-batch 8 |
8 |
Number of 2,500-sample chunks per detector batch. |
--embedding-batch 128 |
128 |
Number of waveforms per HuiduRep batch. |
--gpu-fraction 0.4 |
0.4 |
Limit the PyTorch CUDA allocator to this fraction of device memory. |
--output PATH |
output |
New or empty result directory. |
CUDA out-of-memory handling halves the affected inference batch and retries. Filtering and normalization use the entire selected recording in host memory. Before processing, the runner checks for approximately 12 × input array bytes + 512 MiB of available RAM; waveform and feature storage also grows with the event count.
The profiles and model settings are defined in configs/default.json:
| Setting | d1 (default) |
canonical |
|---|---|---|
| Band-pass filter | 300–5,000 Hz, order 5 | 200–6,000 Hz, order 3 |
| Notch filter | 60 Hz | Off |
| Detection threshold | 0.039 | 0.038 |
| Direct-acceptance threshold | 0.045 | 0.041 |
| Waveform source | Filtered voltage | Filtered voltage with per-channel median/MAD normalization |
Both profiles use per-channel median/MAD normalization for detector input. Event-SNR gating uses the canonical 200–6,000 Hz signal. Processing a prefix with --seconds also fits normalization and clustering to that prefix. Keep run.json with your results to record these choices.
For example, vanillasort --input recording.npz --components 10 --no-gate --threshold 0.139 --output output/no-gate disables the SNR gate. Custom functions are supported through the Python API only.
Model architecture
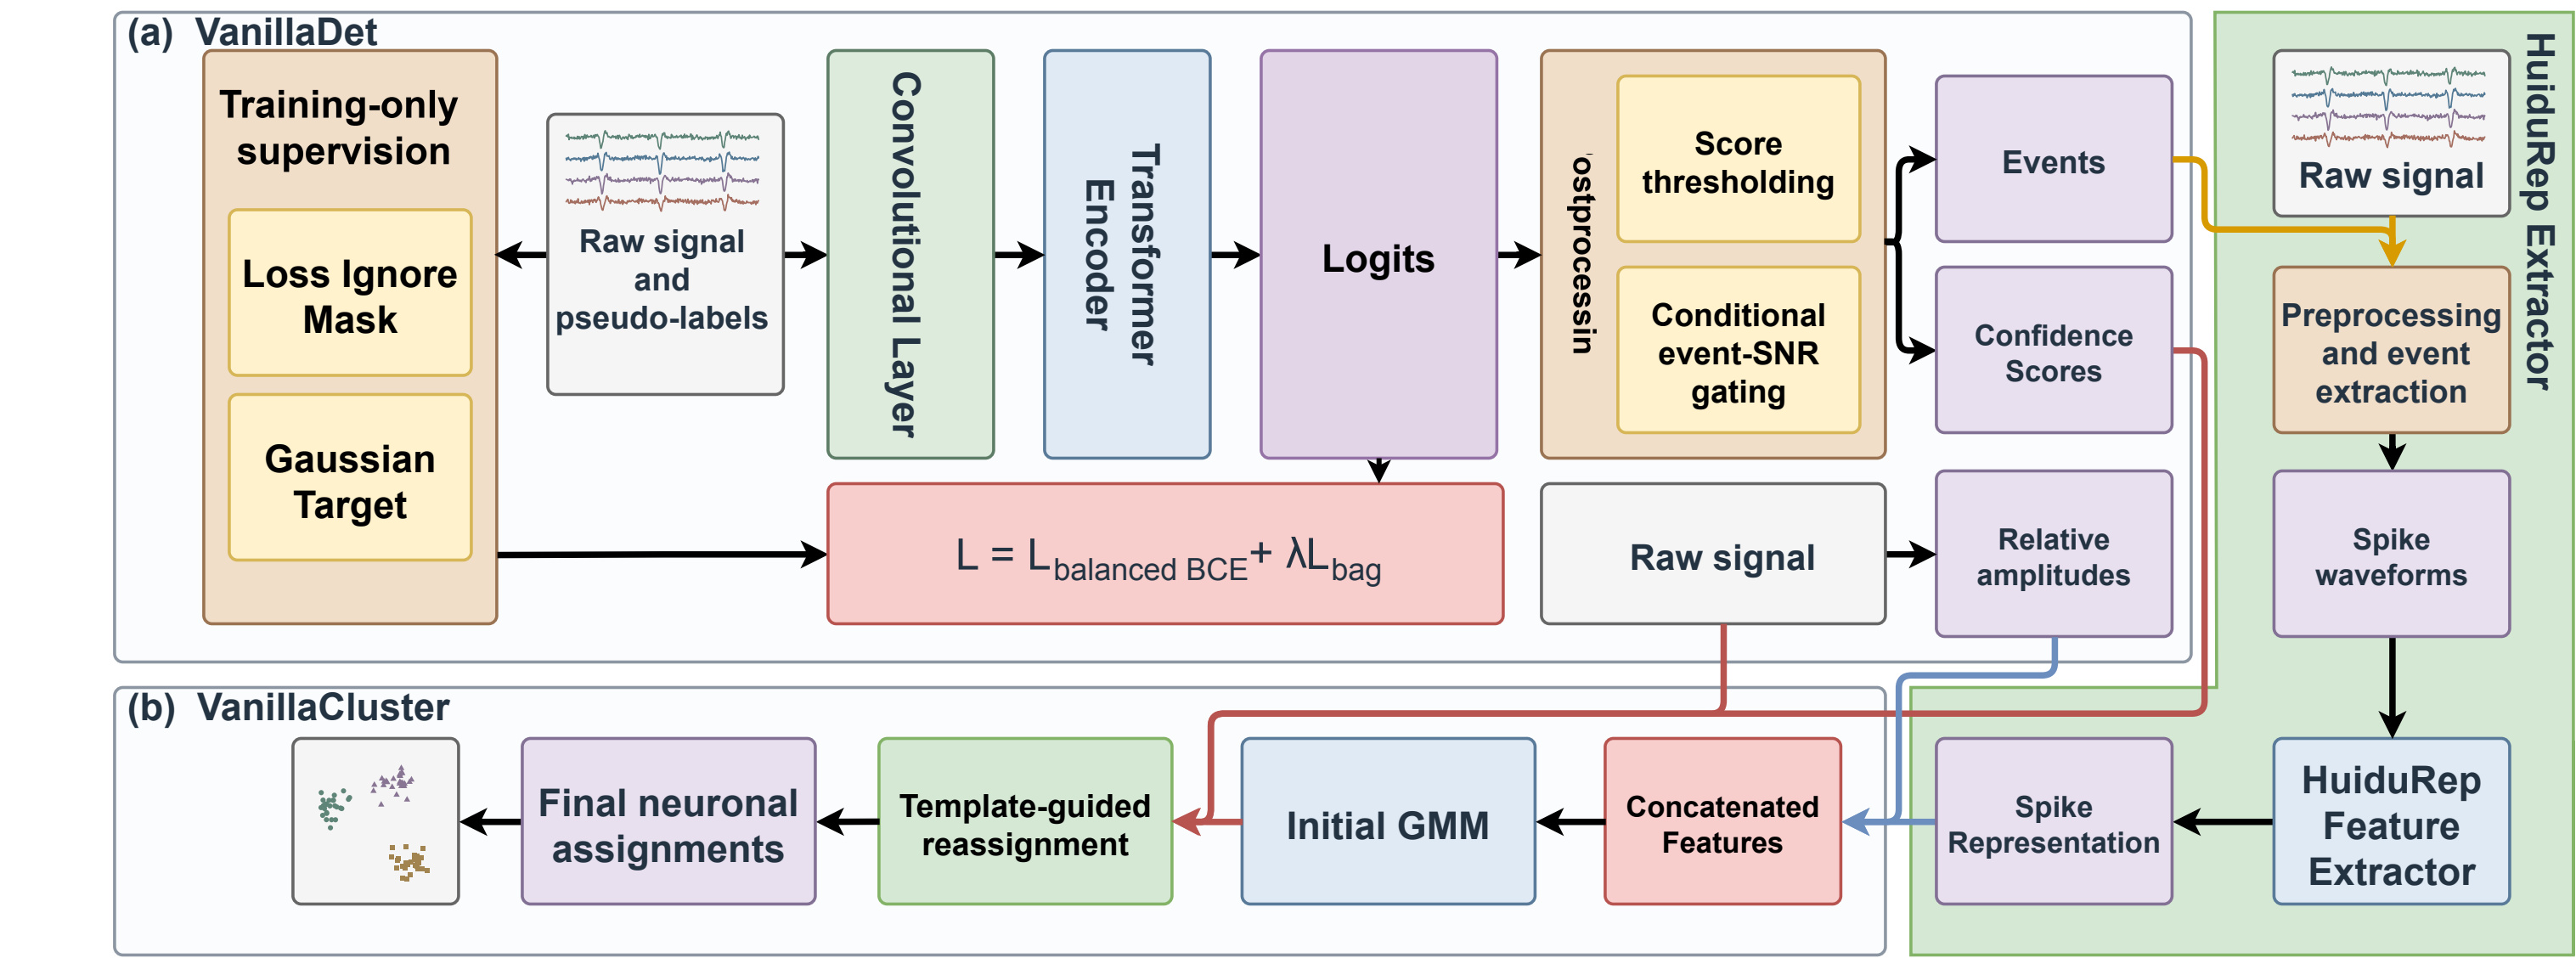
VanillaDet → HuiduRep → VanillaCluster. The diagram shows detector training and event selection, waveform representation learning, and clustering with relative-amplitude features and template-guided reassignment.
Method
- VanillaDet — detect spikes. A convolutional frontend and a six-layer local Transformer produce sample-level scores. The default model uses 256-dimensional hidden states, four attention heads, rotary positional encoding, and L2-normalized queries and keys. Peak selection applies a 12-sample exclusion radius. Events at or above the direct-acceptance threshold are retained; events between the two thresholds require a primary-channel SNR of at least 3 and an SNR of at least 2 on another channel.
- HuiduRep — encode waveforms. Each event contributes a 60-sample, four-channel waveform. Preprocessing standardizes each channel over events and time, interpolates to 90 samples, and repeats/crops channels to 11 inputs. HuiduRep applies internal denoising and produces a 32-dimensional representation, which is standardized across the recording's events.
- VanillaCluster — assign units. Three relative-amplitude features are formed from per-channel peak-to-peak amplitude fractions, projected onto a Helmert contrast basis, and standardized. A full-covariance GMM clusters the resulting 35-dimensional vectors. One template-residual refinement pass then updates assignments among the top three candidate components.
Template refinement splits events into alternating one-second blocks. For each target fold, templates are built from the opposite fold using events with GMM posterior probability of at least 0.9. Each core pool is capped at 512 events, then its lowest-scoring 25% by detector score is removed. A valid template requires at least 30 retained events and nonzero energy. Residual fitting searches shifts of ±2 samples and shared amplitude scales from 0.5 to 2.0; event timestamps are preserved. Events with insufficient template support retain their GMM assignments.
Results
The paper's Tables 1–2 report results on Hybrid Janelia Static and Drift, with nine recordings per subset and ground-truth units with SNR ≥ 3. Sorting accuracy is TP / (TP + FP + FN), with event matching within ±6 samples. Values below are mean ± SEM; higher is better.
| Spike sorter | Static accuracy | Drift accuracy |
|---|---|---|
| HerdingSpikes2 | 0.35 ± 0.01 | 0.29 ± 0.01 |
| IronClust | 0.57 ± 0.04 | 0.54 ± 0.03 |
| JRClust | 0.47 ± 0.04 | 0.35 ± 0.03 |
| KiloSort | 0.60 ± 0.02 | 0.51 ± 0.02 |
| KiloSort2 | 0.39 ± 0.03 | 0.30 ± 0.02 |
| KiloSort4 | 0.40 ± 0.03 | 0.34 ± 0.02 |
| MountainSort4 | 0.59 ± 0.02 | 0.36 ± 0.02 |
| MountainSort5 | 0.40 ± 0.06 | 0.33 ± 0.04 |
| SpykingCircus | 0.57 ± 0.01 | 0.48 ± 0.02 |
| Tridesclous | 0.54 ± 0.03 | 0.37 ± 0.02 |
| SimSort | 0.62 ± 0.04 | 0.56 ± 0.03 |
| HuiduRep (without DAE) | 0.69 ± 0.02 | 0.56 ± 0.02 |
| HuiduRep (with DAE) | 0.70 ± 0.02 | 0.60 ± 0.02 |
| VanillaSort (without DAE) | 0.73 ± 0.02 | 0.61 ± 0.02 |
| VanillaSort (with DAE) | 0.73 ± 0.01 | 0.64 ± 0.02 |
DAE denotes a denoising autoencoder. Other-tool scores are the SpikeForest or original-publication results used in the paper.
- Detection: VanillaDet achieves 0.74/0.71 accuracy on Static/Drift, compared with SimSort's 0.72/0.68 and amplitude thresholding's 0.61/0.60.
- Sorting: VanillaSort improves accuracy over the corresponding HuiduRep baselines by 3–4 percentage points on Static and 4–5 points on Drift (paired Wilcoxon test, p < 0.05).
Research and development
Develop the package and research methods on main:
git clone --branch main https://github.com/IgarashiAkatuki/VanillaSort.git
cd VanillaSort
python -m pip install -e ".[dev]"
pytest
The tests use small synthetic recordings and locally generated model weights. Numerical reference versions are recorded in requirements.txt; the package's runtime dependencies are declared in pyproject.toml.
Extend VanillaDet in src/vanillasort/models/detector.py, HuiduRep in src/vanillasort/models/huidurep/, and inference experiments in src/vanillasort/pipeline.py and src/vanillasort/configs/default.json. Use checkpoints that match the model architecture. Run the synthetic quick start after changes and keep each experiment's run.json with its outputs.
See the 0.2.2 release notes for input sampling-rate support and the relocated SpikeInterface guide and tests. The changelog also covers configurable gating, fixed-K postprocessing, and optional cover neighborhoods introduced in 0.2.1. The runtime measurements document the local-attention optimization introduced in 0.2.0 and its numerical checks.
Maintainers can follow the release process to publish a version through GitHub Actions.
Repository layout
| Path | Role |
|---|---|
pyproject.toml |
Package metadata, runtime and development dependencies, CLI. |
src/vanillasort/api.py |
Public sort() API, recording access and BaseSorting output. |
src/vanillasort/models/ |
Canonical VanillaDet and HuiduRep models, including training methods. |
src/vanillasort/pipeline.py / ops.py |
Published preprocessing, detection, embeddings, amplitude features, GMM and template refinement. |
src/vanillasort/geometry.py |
Local probe neighborhoods and overlap suppression. |
src/vanillasort/checkpoints.py |
Model resolution and strict checkpoint loading. |
src/vanillasort/configs/ |
Inference settings and pinned Hugging Face model registry; weights are cached separately. |
src/vanillasort/cli.py / run.py |
CLI and compatibility launcher. |
tests/ |
Small synthetic tests using locally generated tiny checkpoints. |
requirements.txt |
Historical numerical versions for reproduction comparisons. |
Citation
Use of VanillaSort requires citation of the following paper:
Zishuo Feng and Feng Cao. Spike Sorting with VanillaSort. bioRxiv, 2026. doi:10.64898/2026.09.18.752552.
@article{feng2026vanillasort,
  title   = {Spike Sorting with {VanillaSort}},
  author  = {Feng, Zishuo and Cao, Feng},
  journal = {bioRxiv},
  year    = {2026},
  doi     = {10.64898/2026.09.18.752552},
  url     = {https://www.biorxiv.org/content/10.64898/2026.09.18.752552}
}
License
1 maintainer

Metadata
1 maintainer
Release files for vanillasort 0.2.2
For a detailed explanation of source distributions (sdists) and built distributions (wheels), please see the package formats documentation.
Source distribution (sdist)
| File | Size | Uploaded | Provenance | |
|---|---|---|---|---|
| vanillasort-0.2.2.tar.gz | 127.3 kB | With provenance | Details |
Built distribution (wheel)
| File | Interpreter | ABI | Platform | Reset |
|---|---|---|---|---|
| vanillasort-0.2.2-py3-none-any.whl | Python 3 | none | any | Details |
Total release size: 208.0 kB
Release files / vanillasort-0.2.2.tar.gz
| Download URL | vanillasort-0.2.2.tar.gz |
|---|---|
| Size | 127.3 kB |
| Tags | Source |
|
SHA-256 checksum How to use checksums |
90b5d73e8296e8812ef0b9234fce09edd6a53bd68f163549516d3dfae79896a0
|
|
BLAKE2b-256 checksum How to use checksums |
d2b17acecdbc29ed3bb34ff6aefb425b3e6fd3137dabd089881e730ad7f5e357
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
Yes |
| Uploaded via |
twine/7.0.0 CPython/3.13.14
|
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.


PyPI Publish Attestation
PyPI verified that this artifact, at this checksum, originated from the publisher listed below.
Signed by GitHub Actions, verified by PyPI on Oct 20, 2026.
Transparency logRelease files / vanillasort-0.2.2-py3-none-any.whl
| Download URL | vanillasort-0.2.2-py3-none-any.whl |
|---|---|
| Size | 80.7 kB |
| Tags | Python 3 |
|
SHA-256 checksum How to use checksums |
d98540cecb576ced856e13621530e1f8f2a129d17db266b1ea23e8db1e802d31
|
|
BLAKE2b-256 checksum How to use checksums |
1eed8c01e8134ea72dfb35f4dcd5016872294a34d519409367d928a1e56e7b25
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
Yes |
| Uploaded via |
twine/7.0.0 CPython/3.13.14
|
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.
PyPI Publish Attestation
PyPI verified that this artifact, at this checksum, originated from the publisher listed below.
Signed by GitHub Actions, verified by PyPI on Oct 20, 2026.
Transparency logSecurity for vanillasort 0.2.2
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.
Full provenance
All 2 files in this release have been uploaded with provenance metadata.
Attestation for vanillasort-0.2.2.tar.gz
PyPI Publish Attestation
PyPI verified that this artifact, at this checksum, originated from the publisher listed below.
Signed by GitHub Actions, verified by PyPI on Oct 20, 2026.
Transparency logA note on package security
PyPI is a repository for distributing packages, not a service for auditing them. While third-party security researchers and our staff do their best to detect and remove malicious packages, PyPI cannot guarantee the quality, security or suitability of any given package.














