

Vayu - The Fastest Whisper on Apple Silicon



Vayu (وایو) is the fastest Whisper speech-to-text implementation optimized for Apple Silicon Macs. It combines MLX Whisper with Lightning Whisper MLX batched decoding to deliver 3-5x faster transcription than standard Whisper on M1/M2/M3/M4 chips.
Named after the ancient Persian god of wind - the swiftest force in nature.
Why Vayu?
- 3-5x faster than standard Whisper via batched decoding on Apple Silicon
- One-line install -
pip install vayu-whisperand you're transcribing - All Whisper models - tiny through large-v3, plus turbo and distil variants
- Multiple output formats - txt, vtt, srt, tsv, json
- Word-level timestamps - precise word timings for subtitles and alignment
- Low memory options - 4-bit and 8-bit quantization for constrained environments
- Simple Python API + CLI - use from code or the command line
Installation
pip install vayu-whisper
Or install from source:
git clone https://github.com/CodeWithBehnam/vayu.git
cd vayu
pip install -e .
Requirements
- macOS with Apple Silicon (M1/M2/M3/M4)
- Python 3.10+
- MLX 0.11+
Quick Start
Python API
from whisper_mlx import LightningWhisperMLX

# Initialize with batched decoding for maximum speed
whisper = LightningWhisperMLX(model="distil-large-v3", batch_size=12)

# Transcribe audio
result = whisper.transcribe("audio.mp3")
print(result["text"])

# With word-level timestamps
result = whisper.transcribe("audio.mp3", language="en", word_timestamps=True)
Full API
from whisper_mlx import transcribe

result = transcribe(
    "audio.mp3",
    path_or_hf_repo="mlx-community/whisper-turbo",
    batch_size=6,
    language="en",
    word_timestamps=True,
)

print(result["text"])
for segment in result["segments"]:
    print(f"[{segment['start']:.2f} -> {segment['end']:.2f}] {segment['text']}")
CLI
# Basic transcription
vayu audio.mp3

# Batched decoding (3-5x faster)
vayu audio.mp3 --batch-size 12

# Specify model and output format
vayu audio.mp3 --model mlx-community/distil-whisper-large-v3 --output-format srt

# Multiple files
vayu audio1.mp3 audio2.mp3 --output-dir ./transcripts

# Word-level timestamps
vayu audio.mp3 --word-timestamps True

# Translate to English
vayu audio.mp3 --task translate
Available Models
| Model | HuggingFace Repo | Size | Speed |
|---|---|---|---|
| tiny | mlx-community/whisper-tiny-mlx | 39M | Fastest |
| base | mlx-community/whisper-base-mlx | 74M | Fast |
| small | mlx-community/whisper-small-mlx | 244M | Medium |
| medium | mlx-community/whisper-medium-mlx | 769M | Slow |
| large-v3 | mlx-community/whisper-large-v3-mlx | 1.5B | Slowest |
| turbo | mlx-community/whisper-turbo | 809M | Fast |
| distil-large-v3 | mlx-community/distil-whisper-large-v3 | 756M | Fast |
Quantized Models
For reduced memory usage, use quantized models:
whisper = LightningWhisperMLX(model="distil-large-v3", quant="4bit")
quant accepts "4bit" or "8bit" and is available for tiny, small, medium, large-v3 and distil-large-v3. Other models raise a ValueError rather than silently loading full precision.
Batch Size Recommendations
| Model | Recommended batch_size | Memory Usage |
|---|---|---|
| tiny/base | 24-32 | Low |
| small | 16-24 | Medium |
| medium | 8-12 | High |
| large/turbo | 4-8 | High |
| distil-large-v3 | 12-16 | Medium |
Higher batch sizes improve throughput but require more memory. Start with the recommended values and adjust based on your hardware.
Measuring the speed-up
The speed-up from batching depends on the model, batch size, chip and audio. To measure it on your Mac, time sequential against batched decoding on one of your own files:
python scripts/benchmark.py audio.mp3 --model distil-large-v3 --batch-size 12
The script loads the model and warms it up first, then reports the best of --runs timings for batch_size=1 and for the batch size you chose.
Batched vs Sequential Decoding
With batch_size=1, Vayu decodes like OpenAI's Whisper. Each 30-second window starts where the previous segment ended and is conditioned on the text so far.
With batch_size > 1, fixed 30-second windows are decoded together. This is much faster, with some trade-offs:
- Every window in a batch is conditioned on the text from before the batch, so
condition_on_previous_textapplies between batches, not between windows. - Windows don't move to follow the speech. Text cut off at a window boundary is kept as a segment that ends at the boundary, so a word spanning two windows can be split.
hallucination_silence_thresholdneeds window-by-window seeking and is ignored (with a warning).best_ofis not used. Temperature fallback re-decodes only the windows that fail the quality checks.
Word-level timestamps work in both modes.
Loading Local Models
load_model and --model accept a local directory with MLX weights (config.json plus weights.safetensors, model.safetensors or weights.npz). For safety, local directories are only loaded from:
- the HuggingFace cache (
~/.cache/huggingface/hub) /usr/local/share/whisper-mlx- directories listed in
WHISPER_MLX_MODEL_DIRS(separated by:)
export WHISPER_MLX_MODEL_DIRS=~/models:/Volumes/External/whisper
vayu audio.mp3 --model ~/models/whisper-large-v3-mlx
Anything else fails with Model path '...' is not within allowed directories. HuggingFace repo names (mlx-community/whisper-turbo) are downloaded to the cache and are not affected.
API Reference
transcribe()
def transcribe(
    audio: Union[str, np.ndarray, mx.array],
    *,
    path_or_hf_repo: str = "mlx-community/whisper-turbo",
    batch_size: int = 1,
    verbose: Optional[bool] = None,
    temperature: Union[float, Tuple[float, ...]] = (0.0, 0.2, 0.4, 0.6, 0.8, 1.0),
    compression_ratio_threshold: Optional[float] = 2.4,
    logprob_threshold: Optional[float] = -1.0,
    no_speech_threshold: Optional[float] = 0.6,
    condition_on_previous_text: bool = True,
    initial_prompt: Optional[str] = None,
    word_timestamps: bool = False,
    **decode_options,
) -> dict
LightningWhisperMLX
class LightningWhisperMLX:
    def __init__(
        self,
        model: str = "distil-large-v3",
        batch_size: int = 12,
        quant: str = None,
    )

    def transcribe(
        self,
        audio_path: str,
        language: str = None,
        task: str = "transcribe",
        verbose: bool = False,
        word_timestamps: bool = False,
        **kwargs,
    ) -> dict
Contributing
Contributions are welcome! Please open an issue or submit a pull request.
# Development setup
git clone https://github.com/CodeWithBehnam/vayu.git
cd vayu
pip install -e ".[dev]"
License
MIT License - see LICENSE for details.
Acknowledgments
This project builds on the excellent work of:
| Project | Author(s) | Contribution |
|---|---|---|
| mlx-examples/whisper | Apple Inc. | MLX framework, Whisper port, CLI, output writers |
| lightning-whisper-mlx | Mustafa Aljadery, Siddharth Sharma | Batched decoding for 3-5x speedup |
| Whisper | OpenAI | Original model architecture and weights |
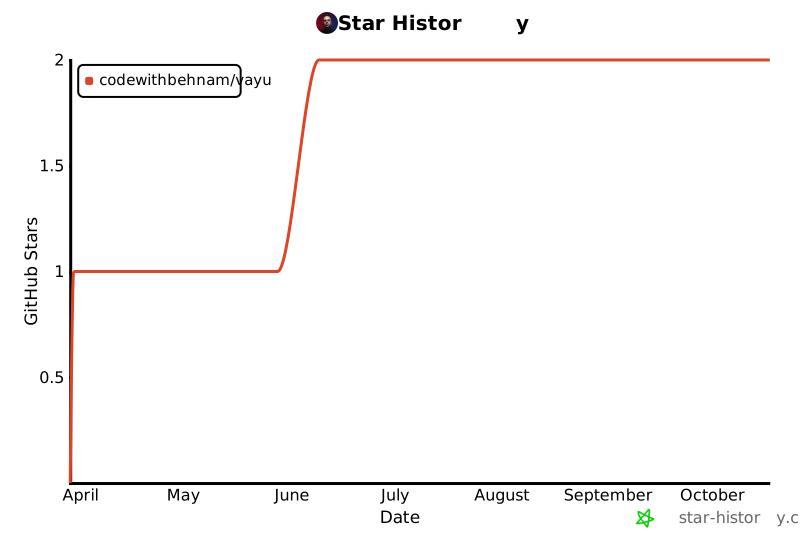
Star History
Author
Behnam Ebrahimi - Unified implementation, security improvements, and maintenance
1 maintainer

Metadata
1 maintainer
Release files for vayu-whisper 1.1.0
For a detailed explanation of source distributions (sdists) and built distributions (wheels), please see the package formats documentation.
Source distribution (sdist)
| File | Size | Uploaded | |
|---|---|---|---|
| vayu_whisper-1.1.0.tar.gz | 804.1 kB | Details |
Built distribution (wheel)
| File | Interpreter | ABI | Platform | Reset |
|---|---|---|---|---|
| vayu_whisper-1.1.0-py3-none-any.whl | Python 3 | none | any | Details |
Total release size: 1.6 MB
Release files / vayu_whisper-1.1.0.tar.gz
| Download URL | vayu_whisper-1.1.0.tar.gz |
|---|---|
| Size | 804.1 kB |
| Tags | Source |
|
SHA-256 checksum How to use checksums |
0091d55be7e2832e1e771619193a10020c373d7d6754763ca21237741f143ba3
|
|
BLAKE2b-256 checksum How to use checksums |
5b4a6fe00bbdb217bd772ba9d17a7aa85988f291aeaa5d895c9ddfefda5b177c
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
Yes |
| Uploaded via |
twine/7.0.0 CPython/3.13.14
|
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.


PyPI Publish Attestation
PyPI verified that this artifact, at this checksum, originated from the publisher listed below.
Signed by GitHub Actions, verified by PyPI on Oct 1, 2026.
Transparency logRelease files / vayu_whisper-1.1.0-py3-none-any.whl
| Download URL | vayu_whisper-1.1.0-py3-none-any.whl |
|---|---|
| Size | 799.3 kB |
| Tags | Python 3 |
|
SHA-256 checksum How to use checksums |
9766ab5b7f1f9f4bc721c076e6018a88ad061e15e09940e312cfeca97cc87cab
|
|
BLAKE2b-256 checksum How to use checksums |
9f2a96d0cbb341b9e2eb5a8ca86fb9e90682062da85e971abc5cd59904be48b3
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
Yes |
| Uploaded via |
twine/7.0.0 CPython/3.13.14
|
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.
PyPI Publish Attestation
PyPI verified that this artifact, at this checksum, originated from the publisher listed below.
Signed by GitHub Actions, verified by PyPI on Oct 1, 2026.
Transparency log













