
This release is a pre-release and may not be stable for production use.
VecAdvisor


Cost-based CLI advisor for filtered vector search in PostgreSQL and pgvector.
Read the story: Filtered vector search in pgvector can silently lose recall
VecAdvisor helps answer a question PostgreSQL does not currently cost well:
SELECT id
FROM documents
WHERE tenant_id = 42
ORDER BY embedding <-> $query_vector
LIMIT 10;
When a vector index is searched first and SQL filters are applied after the
ANN candidate set, selective filters can silently lose recall or return fewer
than k rows. Sometimes a filter-first exact scan is faster and exact.
Sometimes pgvector iterative scans are the right answer. Sometimes a partial
HNSW index or partitioning is the durable fix.
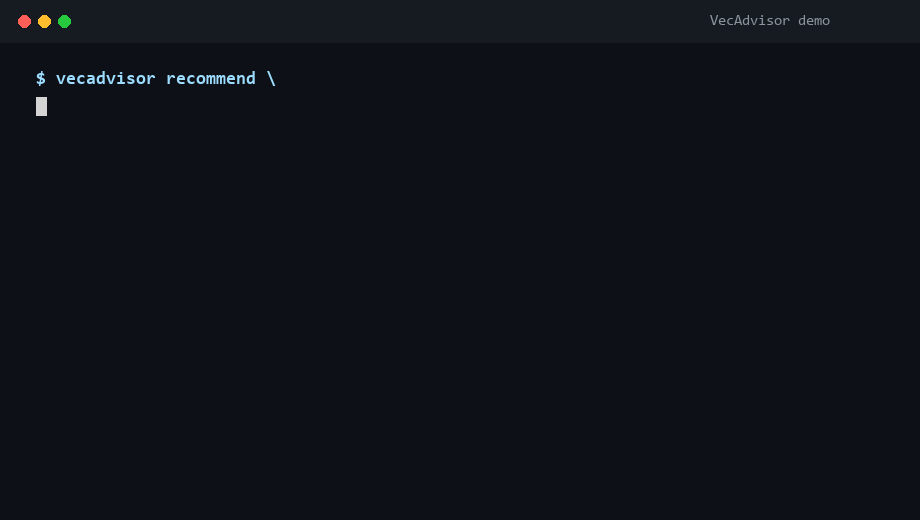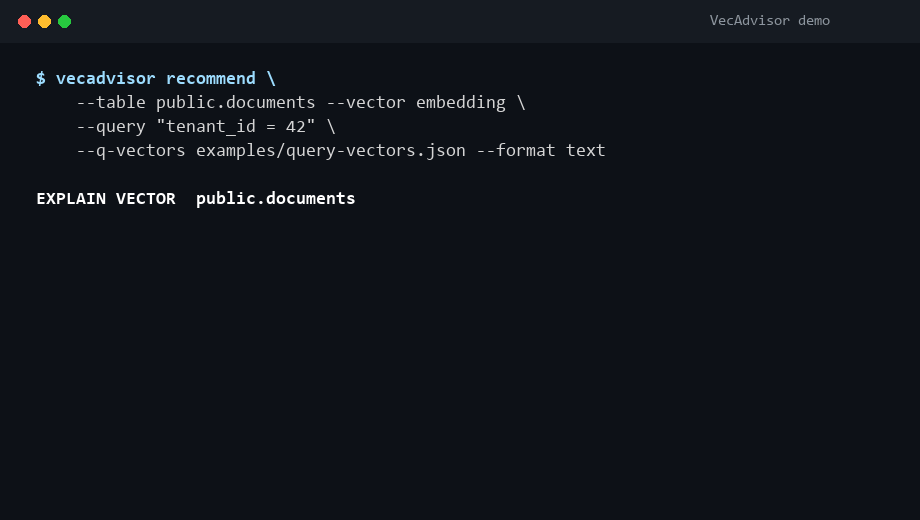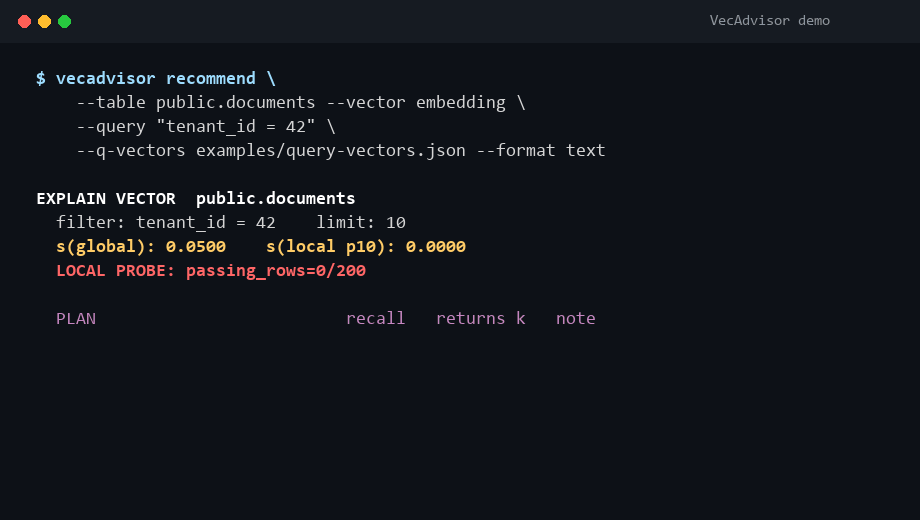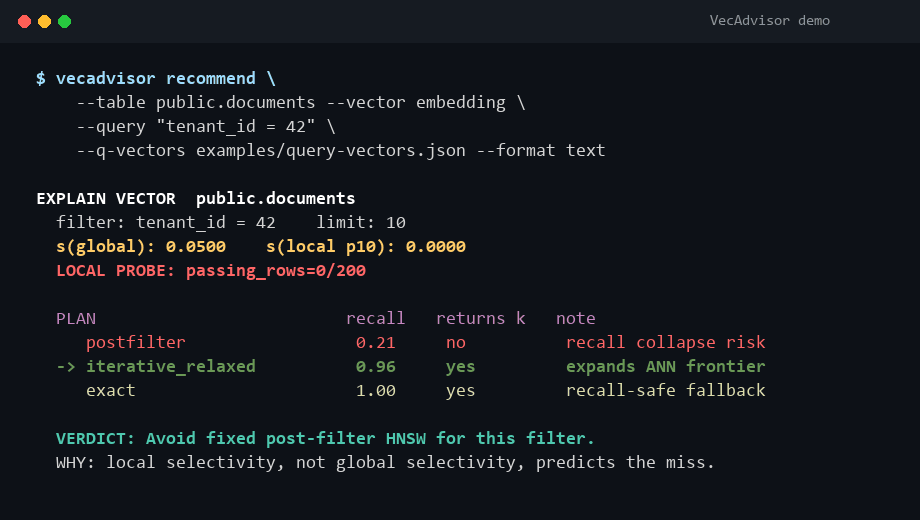
This project models that choice with:
- PostgreSQL catalog and statistics introspection.
- Global selectivity estimation and PostgreSQL plan-row cross-checks.
- Local selectivity probes over the query vector neighborhood.
- A calibrated cost model for exact, post-filter ANN, iterative ANN, partial index, and partition-pruned strategies.
- Reproducible synthetic benchmark, calibration, validation, crossover, and proof reports.
Status: alpha. The Python CLI is useful today for experimentation and design validation. It does not modify PostgreSQL's planner.
VecAdvisor is an independent third-party tool. It works with PostgreSQL and pgvector, but it is not affiliated with the official pgvector project.
Documentation
- Design
- Predicate support
- Workload collector
- Native kernels
- Rust/pgrx extension
- Benchmark artifacts
- SIFT1M scale benchmark recipe
- Release checklist
Why Local Selectivity Matters
Global selectivity is the fraction of the whole table matching a filter. Local selectivity is the fraction of near-neighbor candidates matching the filter for a query vector.
For filtered ANN, local selectivity is the important signal. A tenant may be
globally rare but locally dense near its own documents. Or it may be locally
sparse for a query outside that tenant's embedding cluster. A naive k / s
model misses this. VecAdvisor probes a bounded unfiltered top-m
neighborhood and costs durable recommendations against p10 local selectivity
across representative query vectors.
Full write-up of these results: Filtered vector search in pgvector can silently lose recall
Benchmark Evidence
The lead artifacts measure actual PostgreSQL/pgvector behavior, not a
self-contained simulator. The scale artifact uses 1,000,000 real SIFT
vectors and is the strongest first read:
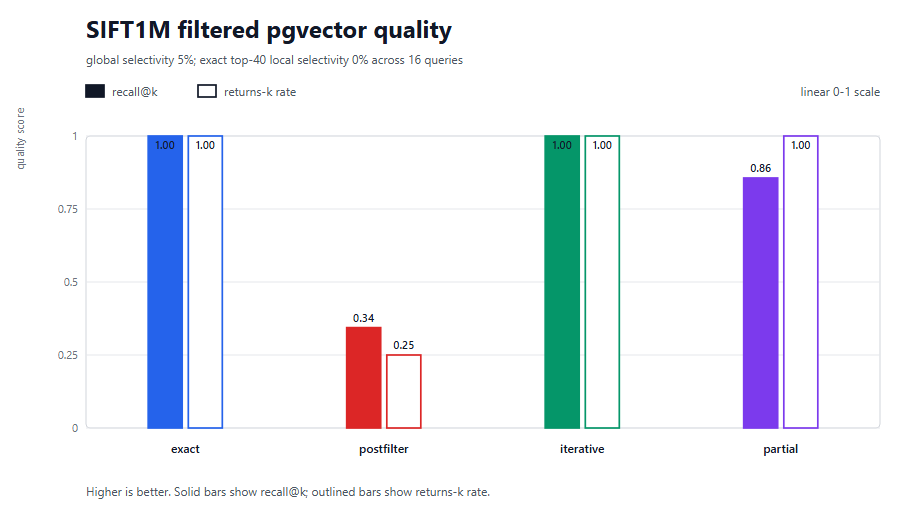
With global filter selectivity fixed at 5%, the anti-correlated SIFT1M run
has zero passing rows in every query's exact top-40 neighborhood. Fixed-frontier
postfilter reaches only 0.3438 recall@k and returns full k for 25% of
queries. Iterative HNSW recovers 1.0000 recall@k and full k, a 65.6
percentage-point recall improvement over fixed postfilter.
The companion Pareto chart is still useful for throughput/quality tradeoffs:
SIFT1M anti-correlated Pareto.
See
docs/benchmarks/sift1m-anticorrelated-pgvector-benchmark.md
for the full SIFT1M recall-collapse artifact. A companion projection-tail
SIFT1M run is also committed; it reaches 0.1750 postfilter recall@k and
0.9875 iterative recall@k:
docs/benchmarks/sift1m-pgvector-benchmark.md.
A smaller Docker-reproducible benchmark keeps the SQL strategy mechanics easy to inspect:
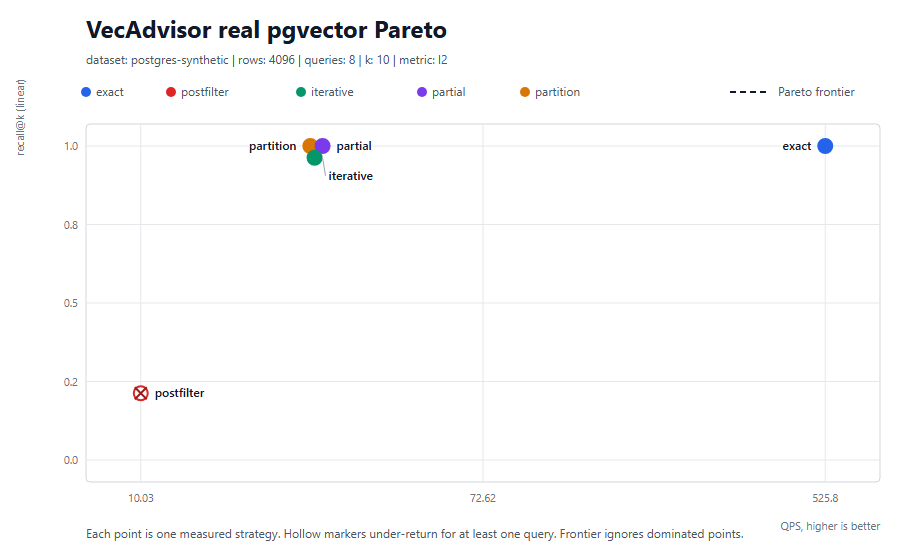
Using the bundled pgvector/pgvector:pg17 container, fixed-size HNSW
post-filtering reached only 0.2125 recall@k and returned full k for 0%
of queries on a filtered workload. Iterative, partial-index, and
partition-pruned HNSW recovered result quality. This is the failure mode
VecAdvisor is designed to catch before it becomes a production surprise.
See
docs/benchmarks/real-pgvector-benchmark.md
for the SQL strategy details, hardware notes, and reproduction commands.
On the measured PostgreSQL crossover sweep, VecAdvisor recommended a
recall-target-meeting plan in every failed-postfilter bin (9/9). It selected
the exact latency-optimal plan in 4/9 bins; in the remaining bins it chose a
recall-safe, slightly slower plan. Safety is the MVP1 claim; exact
latency-optimal ranking is a calibration roadmap item:
real-pgvector-crossover.
The repository also includes deterministic synthetic validation under
docs/benchmarks/:
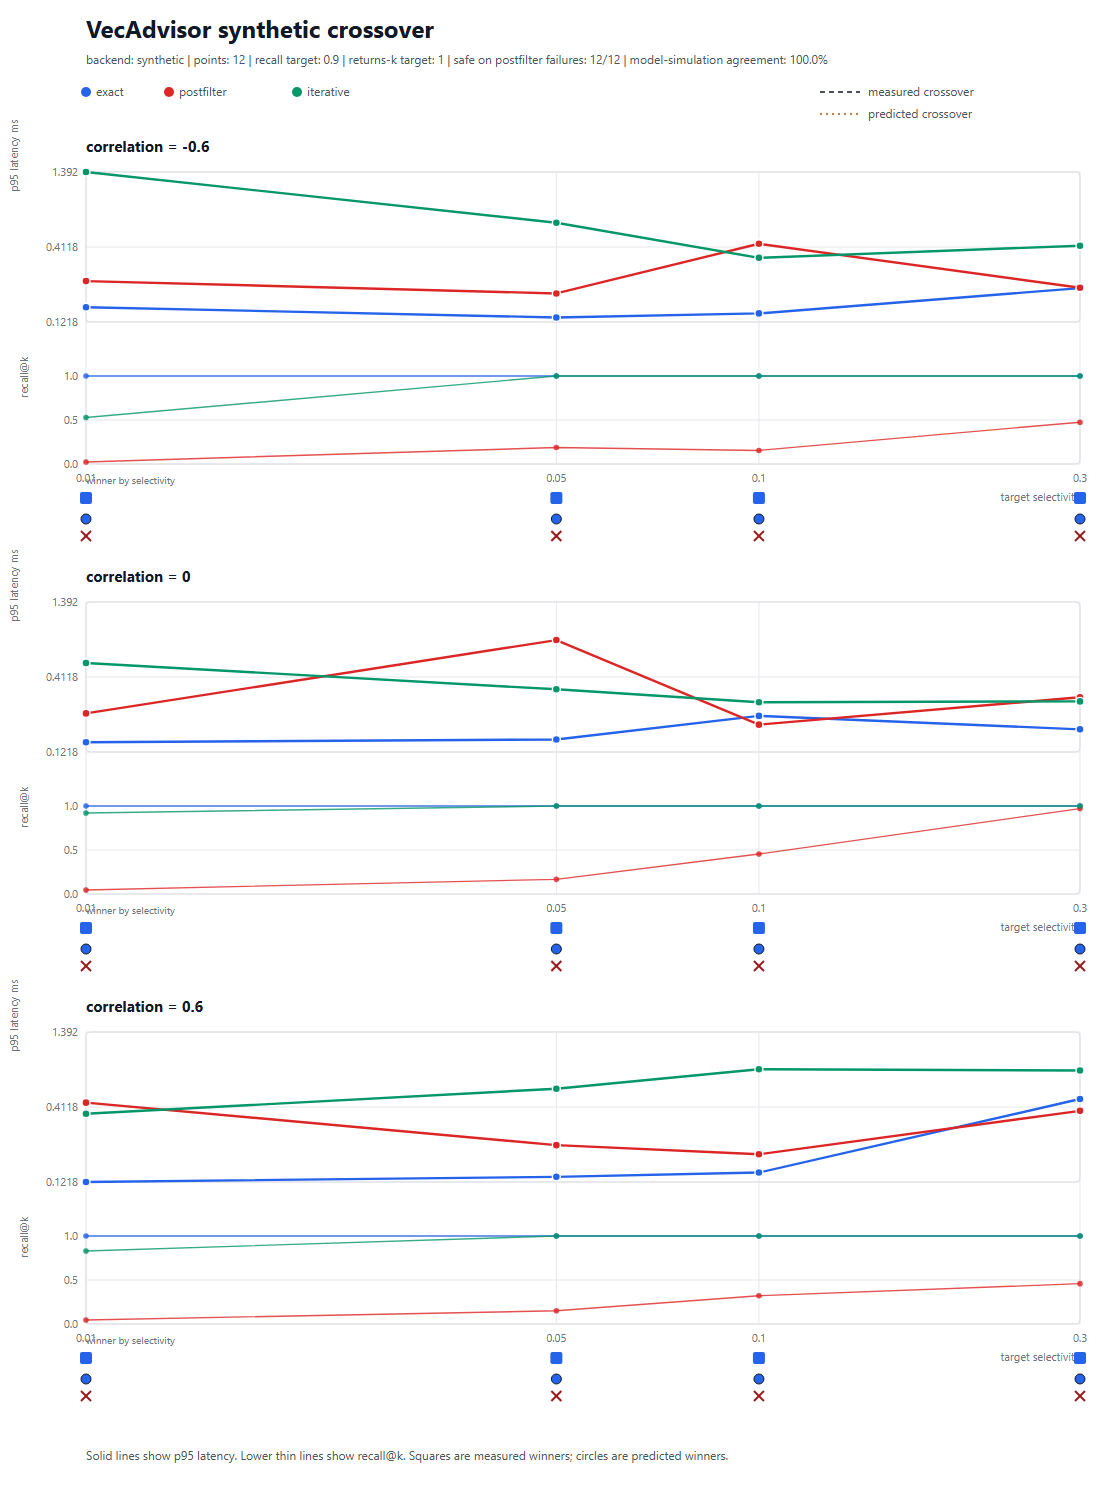
That sweep varies filter selectivity (0.01, 0.05, 0.1, 0.3) and
filter/vector correlation (-0.6, 0, 0.6) across 12 points. It is a
unit-level model-vs-simulation agreement check: the cost-model winner matched
the simulated strategy-semantics winner in all bins, and default post-filter
ANN missed recall or returns-k targets in all bins. Treat it as model
validation, not proof of production pgvector latency.
Reproduce the synthetic artifact:
vecadvisor calibrate \
  --dataset synthetic \
  --rows 2048 \
  --dim 32 \
  --queries 24 \
  --clusters 8 \
  --filter-selectivity 0.1 \
  --correlation 0.5 \
  --limit 10 \
  --ef-sweep 10,20,40,80,160 \
  --seed 410 \
  --dataset-id synthetic-readme \
  --hardware-id github-readme-synthetic \
  --out docs/benchmarks/synthetic-calibration.json

vecadvisor benchmark-sweep \
  --dataset synthetic \
  --rows 2048 \
  --dim 32 \
  --queries 24 \
  --clusters 8 \
  --filter-selectivities 0.01,0.05,0.1,0.3 \
  --correlations -0.6,0,0.6 \
  --limit 10 \
  --ef-search 40 \
  --max-scan-tuples 1000 \
  --probe-rows 200 \
  --calibration docs/benchmarks/synthetic-calibration.json \
  --seed 411 \
  --out docs/benchmarks/synthetic-sweep.json

vecadvisor proof docs/benchmarks/synthetic-sweep.json \
  --out docs/benchmarks/synthetic-proof.json

vecadvisor plot-crossover docs/benchmarks/synthetic-sweep.json \
  --out docs/assets/synthetic-crossover.svg \
  --title "VecAdvisor synthetic crossover"
Install
Install from PyPI:
python -m pip install vecadvisor
For local development:
python -m pip install -e ".[dev]"
The current alpha release is also available as wheel and source artifacts on GitHub:
python -m pip install https://github.com/vecadvisor/vecadvisor/releases/download/v0.1.0a5/vecadvisor-0.1.0a5-py3-none-any.whl
The CLI entry point is:
vecadvisor --help
30-Second Demo
From a checkout:
python -m pip install -e ".[dev]"
docker compose -f docker/docker-compose.yml up -d
docker compose -f docker/docker-compose.yml exec -T postgres \
  psql -U postgres -d vecadvisor < examples/demo.sql

vecadvisor explain \
  --dsn postgresql://postgres:postgres@localhost:5432/vecadvisor \
  --table public.documents \
  --vector embedding \
  --query "tenant_id = 1" \
  --q-vector examples/query-vector.json \
  --probe-rows 16 \
  --format text

vecadvisor recommend \
  --dsn postgresql://postgres:postgres@localhost:5432/vecadvisor \
  --table public.documents \
  --vector embedding \
  --query "tenant_id = 1" \
  --q-vectors examples/query-vectors.json \
  --probe-rows 16 \
  --max-query-vectors 3 \
  --format text
No representative query vectors yet? Use the table-sampled fallback for a 30-second first look. VecAdvisor marks this path as low confidence:
vecadvisor recommend \
  --dsn postgresql://postgres:postgres@localhost:5432/vecadvisor \
  --table public.documents \
  --vector embedding \
  --query "tenant_id = 1" \
  --allow-table-sample-vectors \
  --format text
Captured outputs:
Local PostgreSQL
Start the bundled pgvector database:
docker compose -f docker/docker-compose.yml up -d
Load the example table:
psql "postgresql://postgres:postgres@localhost:5432/vecadvisor" -f examples/demo.sql
If you do not have psql locally, use Docker:
docker compose -f docker/docker-compose.yml exec -T postgres \
  psql -U postgres -d vecadvisor < examples/demo.sql
The default test DSN is:
postgresql://postgres:postgres@localhost:5432/vecadvisor
Analyze A Table
vecadvisor analyze \
  --dsn postgresql://postgres:postgres@localhost:5432/vecadvisor \
  --table public.documents \
  --vector embedding
This reports table rows, vector dimension, indexes, extended statistics, catalog fingerprints, stats freshness, and pgvector capabilities.
Explain One Query Vector
Use explain when you have one concrete query vector and want a one-query
diagnostic:
vecadvisor explain \
  --dsn postgresql://postgres:postgres@localhost:5432/vecadvisor \
  --table public.documents \
  --vector embedding \
  --query "tenant_id = 1" \
  --q-vector examples/query-vector.json \
  --probe-rows 16 \
  --format text
explain reads --q-vector, runs one local selectivity probe, observes the
planner's vector query shape, and renders an EXPLAIN VECTOR style report.
Recommend A Durable Strategy
Use recommend when you have representative query vectors for a workload:
vecadvisor recommend \
  --dsn postgresql://postgres:postgres@localhost:5432/vecadvisor \
  --table public.documents \
  --vector embedding \
  --query "tenant_id = 1" \
  --q-vectors examples/query-vectors.json \
  --probe-rows 16 \
  --max-query-vectors 3 \
  --local-cache-dir .vecadvisor-cache
recommend uses p10 local selectivity across the vector sample. It emits:
- Ranked candidate strategies.
- Estimated latency, recall, returns-k, and confidence.
- A concise decision summary.
- PostgreSQL observed plan, when a vector sample is available.
- Statistics suggestions such as
CREATE STATISTICS. - Optional partial index or partition strategy suggestions.
If you do not have production query vectors yet, you may explicitly opt in to a low-confidence table-sample fallback:
vecadvisor recommend \
  --dsn postgresql://postgres:postgres@localhost:5432/vecadvisor \
  --table public.documents \
  --vector embedding \
  --query "tenant_id = 1" \
  --allow-table-sample-vectors
Table-sampled vectors are marked in the output and reduce confidence.
Local Selectivity Cache
Repeated multi-vector probes can be cached:
vecadvisor recommend ... --local-cache-dir .vecadvisor-cache
Cache keys include:
- table name
- filter shape
- probe rows
- query vector source
- query vector fingerprint
- table statistics fingerprint
- index fingerprint
Changing table statistics or index definitions naturally produces a different cache key. Cache entries contain only aggregate local selectivity, not raw vectors or row ids.
Use --refresh-local-cache to ignore and replace an existing cache entry.
Calibrate
Synthetic calibration fits cost constants and an unfiltered recall curve:
vecadvisor calibrate \
  --dataset synthetic \
  --rows 5000 \
  --dim 64 \
  --queries 50 \
  --clusters 16 \
  --filter-selectivity 0.1 \
  --correlation 0.5 \
  --out profiles/local.json
Load a profile during explain or recommend:
vecadvisor recommend ... --calibration profiles/local.json
Without a profile, the advisor uses conservative default constants and marks that in candidate notes.
Benchmark, Sweep, Validate, Prove
Run a small synthetic benchmark:
vecadvisor benchmark \
  --dataset synthetic \
  --strategies exact,postfilter,iterative \
  --rows 512 \
  --dim 16 \
  --queries 8 \
  --clusters 8 \
  --filter-selectivity 0.1 \
  --correlation 0.5 \
  --limit 10 \
  --ef-search 40 \
  --out benchmarks/synthetic.json
Run a selectivity and correlation sweep:
vecadvisor benchmark-sweep \
  --dataset synthetic \
  --rows 512 \
  --dim 16 \
  --queries 8 \
  --clusters 8 \
  --filter-selectivities 0.01,0.05,0.1 \
  --correlations 0,0.5 \
  --limit 10 \
  --ef-search 40 \
  --out benchmarks/sweep.json
Analyze crossover behavior:
vecadvisor crossover benchmarks/sweep.json --out benchmarks/crossover.json
Build a publishability proof report:
vecadvisor proof benchmarks/sweep.json --out benchmarks/proof.json
Render a crossover chart:
vecadvisor plot-crossover benchmarks/sweep.json --out benchmarks/crossover.svg
Output Contract Highlights
Important JSON fields:
catalog_snapshot: stats and index fingerprints for reproducibility.selectivity: advisor-vs-PostgreSQL selectivity cross-check with severity.local_selectivity: p10 and median local selectivity, confidence, and notes.local_selectivity_cache: cache hit/store metadata when enabled.recommendation.decision: winner, runner-up, viability, confidence, and why.recommendation.ranked: full candidate plan and estimate details.ground_truth.native_used: whether benchmark exact ground truth used the optional native C ABI.ground_truth.native_capabilities: native library source and runtime kernel dispatch details when native ground truth was used.
Current Limitations
- Alpha quality: APIs and output shape may change before v0.1.
- The current release is an external CLI. It does not change PostgreSQL planner behavior.
- The SIFT1M benchmark commits JSON/SVG results only; source vectors are
downloaded into ignored local
data/paths. - Calibration constants are workload and hardware dependent.
- Predicate parsing intentionally supports a restricted safe subset of filters.
- Native exact top-k ground truth is available when a locally built shared library is configured; prebuilt native wheels are deferred until the ABI and CI matrix are stable.
- Postgres integration tests require a reachable PostgreSQL database with pgvector installed. Tests skip those cases if the database is unavailable.
Development
Install dev dependencies:
python -m pip install -e ".[dev]"
Run checks:
python -m pytest
python -m ruff check .
python -m mypy src/vecadvisor
python -m build
Build the optional native distance kernels when a C++17 compiler and CMake are available:
cmake -S native -B native/build
cmake --build native/build --config Release --parallel
ctest --test-dir native/build --output-on-failure
Run the native distance benchmark wrapper to compare scalar and runtime-dispatch kernels against deterministic NumPy checksums:
python tools/native_distance_benchmark.py \
  --rows 4096 \
  --queries 16 \
  --dim 128 \
  --iterations 5
It writes a JSON artifact, Markdown report, and SVG chart under docs/.
The committed MVP2 native artifact compares AVX2 dispatch with an explicit
scalar-only fallback build and the optional SimSIMD external baseline:
docs/benchmarks/native-distance-kernels.md.
The native C ABI also includes a bounded top-k helper for exact ground-truth
search over row-major float32 blocks without materializing an N x Q
distance matrix.
Python benchmark ground-truth can use that helper when
VECADVISOR_NATIVE_DISTANCE_LIB points at the built shared library. Runs record
ground_truth.native_used, ground_truth.native_library_source, and
ground_truth.native_capabilities; if the library is missing, VecAdvisor falls
back to the NumPy path.
Inspect native availability and runtime dispatch with:
vecadvisor native-info
vecadvisor native-info --library native/build/libvecadvisor_distance.so
Verify the product path uses the native bounded top-k helper:
vecadvisor benchmark-groundtruth \
  --rows 4096 \
  --dim 32 \
  --queries 8 \
  --limit 10 \
  --native-library native/build/libvecadvisor_distance.so \
  --require-native
The smoke artifact records exact agreement with the NumPy fallback plus runtime
kernel dispatch:
docs/benchmarks/native-groundtruth-smoke.json.
Rust/pgrx Extension
MVP2 Part B has a safe pgrx extension scaffold under extension/vecadvisor.
It exposes metadata functions plus vecadvisor_postfilter_risk(...), a pure
SQL-callable estimator for post-filter candidate survival. The function accepts
LIMIT, hnsw.ef_search, global selectivity, optional local selectivity, and
optional calibrated ANN recall, then returns JSON with expected survivors,
returns-k risk, survivor-bound recall, and mitigation hints.
The extension is intentionally read-only at this stage: no planner hooks, no catalog writes, no probe execution, and no GUC mutation. The Python CLI remains the reference implementation until SQL parity tests exist.
Prior Art And Clean-Room Notes
This project builds from public PostgreSQL, pgvector, and filtered ANN literature. It does not copy source from AGPL or source-available vector extensions. Ideas such as local selectivity, filtered ANN recall risk, iterative scans, partial indexes, and calibration are implemented from public documentation, papers, and first-principles cost modeling.
License
Apache License 2.0. See LICENSE.
Built and maintained by Varun Sharma.
1 maintainer

Metadata
1 maintainer
Release files for vecadvisor 0.1.0a5
For a detailed explanation of source distributions (sdists) and built distributions (wheels), please see the package formats documentation.
Source distribution (sdist)
| File | Size | Uploaded | |
|---|---|---|---|
| vecadvisor-0.1.0a5.tar.gz | 633.9 kB | Details |
Built distribution (wheel)
| File | Interpreter | ABI | Platform | Reset |
|---|---|---|---|---|
| vecadvisor-0.1.0a5-py3-none-any.whl | Python 3 | none | any | Details |
Total release size: 748.1 kB
Release files / vecadvisor-0.1.0a5.tar.gz
| Download URL | vecadvisor-0.1.0a5.tar.gz |
|---|---|
| Size | 633.9 kB |
| Tags | Source |
|
SHA-256 checksum How to use checksums |
49b5be4f354fc1cd4226d03ec2829ba3689b4b933e4c7b846e5914bd19eaafec
|
|
BLAKE2b-256 checksum How to use checksums |
ec03130728f67f7889be6b5360bf1fb635f0cbd34da92617cb2be6f8bac36c36
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
Yes |
| Uploaded via |
twine/7.0.0 CPython/3.13.14
|
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.


PyPI Publish Attestation
PyPI verified that this artifact, at this checksum, originated from the publisher listed below.
Signed by GitHub Actions, verified by PyPI on Sep 11, 2026.
Transparency logRelease files / vecadvisor-0.1.0a5-py3-none-any.whl
| Download URL | vecadvisor-0.1.0a5-py3-none-any.whl |
|---|---|
| Size | 114.2 kB |
| Tags | Python 3 |
|
SHA-256 checksum How to use checksums |
53058a21fbf6aa7dcb1752d7ed26b4aa083a3a97cd834bdb6b24c5b2c280f920
|
|
BLAKE2b-256 checksum How to use checksums |
c477e3dfd57ab8ccd254238dd3a871461aef1ddff69459a0f03ee819876b2847
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
Yes |
| Uploaded via |
twine/7.0.0 CPython/3.13.14
|
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.
PyPI Publish Attestation
PyPI verified that this artifact, at this checksum, originated from the publisher listed below.
Signed by GitHub Actions, verified by PyPI on Sep 11, 2026.
Transparency log















