
Visual Reasoning and Understanding
VisRU (Visual Reasoning and Understanding) is an agentic harness that gives a vision-language model a workspace of images, video, and multi-view captures, plus tools to search, zoom, measure, annotate, and check its own conclusions. Every claim in its final answer links to the crop, mask, frame, or overlay that supports it.
The design borrows from coding agents. A codebase is too large to read in one pass, so a coding agent searches, opens the files it needs, edits, and runs tests. visru runs the same loop over pixels.
Status: pre-alpha.
A session
$ visru run ./rollouts/pick_place --task "Why did trial 14 fail?"

[1] list_assets(prefix="trial_14")                  -> 1 video, 1,812 frames, 30 fps
[2] sample_frames(trial_14.mp4, n=24)               -> contact sheet a_0003
[3] sample_frames(trial_14.mp4, t=37.5..40.5, n=12) -> contact sheet a_0004
[4] view(frame_1164, box=[812,402,1240,690])        -> a_0005, scale 1.00
[5] segment(a_0005, points=[[1020,560]])            -> mask a_0006 (mark 1: mug handle)
[6] overlay(a_0006 + gripper track)                 -> a_0007
[7] cross_check(c_1, via=["segment", "detect"])     -> agree, IoU 0.84
[8] coverage(trial_14.mp4)                          -> 14% of frames inspected at native scale
[9] submit_report(...)

c_1 [verified]  Gripper closed before reaching the handle at 38.8 s.
                evidence: a_0005, a_0007   checks: cross_tool
c_2 [supported] Left finger occluded the handle from 38.4 s.
                evidence: a_0004
Not inspected at native scale: frames 0 to 1100.
Architecture
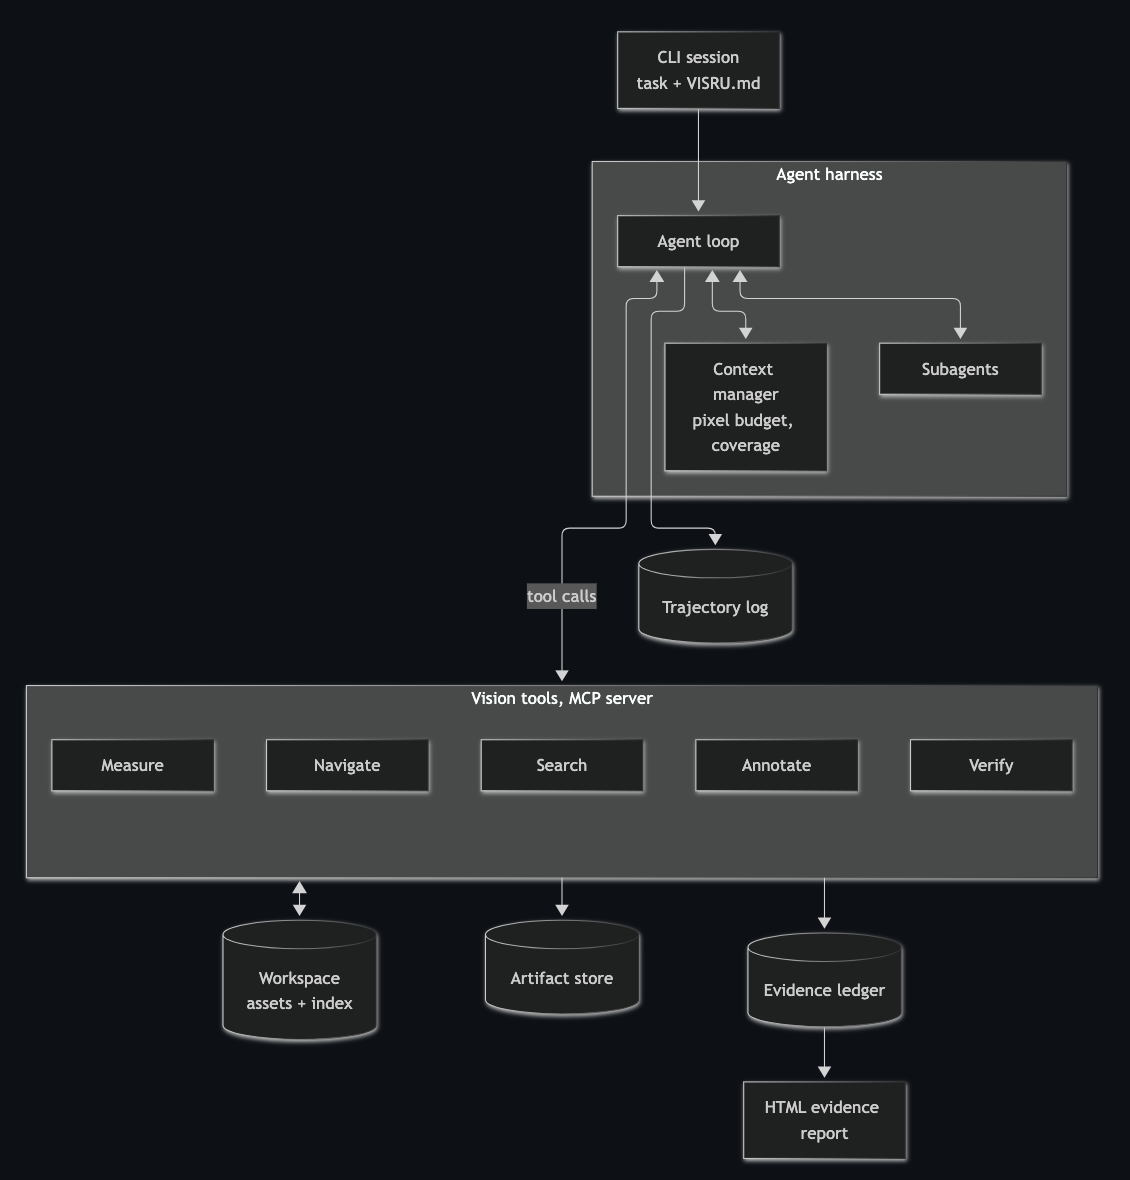
CLI and project context. A session starts in the terminal. Each workspace can carry a VISRU.md with domain context: camera intrinsics, class definitions, what counts as a defect, known failure modes, unit conventions. The harness loads it into the system prompt, the way Claude Code loads CLAUDE.md.
Agent loop. A tool-use loop. The model plans, calls tools, receives text, images, and artifact IDs, and repeats until it calls submit_report. Ending through a tool call forces the final answer into the ledger schema.
Context manager. Images dominate context cost, so the context manager keeps a fixed number of live images and replaces older ones with short text notes that carry artifact IDs. It also maintains a coverage map per asset: which regions or frames the model has viewed, and at what scale.
Workspace. An asset registry with content-hash IDs and metadata (resolution, fps, intrinsics when known), plus an embedding index built at ingest: one SigLIP embedding per image and per video keyframe, stored in FAISS.
Artifact store. Every derived image (view, mask, overlay, contact sheet, plot) is saved with its parent asset, the tool and parameters that produced it, and its coordinate transform. Any image the model saw can be regenerated from the log.
Tool layer. Tools run in an MCP server, so any MCP client can use them. Heavy models (detector, segmenter, depth, pointmaps) run in a GPU worker process that loads weights once and batches requests.
Evidence ledger. Claims with evidence IDs, the checks run against them, and a status. It renders to a static HTML report where each claim links to its artifacts.
Trajectory log. JSONL of every model turn, tool call, tool result, and artifact ID, usable as training data.
Design decisions
Tools ship as an MCP server. Claude Code or any other MCP client can drive them directly; visru's own loop uses the same server.
One coordinate frame: source-asset pixels. The API returns coordinates relative to its own resized image, and every crop adds an offset and a scale. So all tool inputs and outputs use source-asset pixels, view resizes images itself to a size the API will not resize again, and detections are drawn as numbered marks (Set-of-Mark style) so the model can say "mark 3" instead of emitting coordinates.
Images in context expire; artifacts persist. After an image ages out it becomes a note such as [a_0042 elided: close view of MRZ, OCR read "P<CAN..."]. The model can call view("a_0042") to see it again.
The ledger enforces verification. Claims carry one of four statuses:
| Status | Requirement |
|---|---|
verified |
At least one evidence artifact and at least one passing independent check |
supported |
At least one evidence artifact |
contested |
Checks disagree |
hypothesis |
No evidence; reported in a separate section |
Two methods count as independent only if they do not share a model. A VLM count checked against a detector count qualifies. SAM masks prompted from detector boxes do not, because they inherit the detector's errors. verified comes only from the harness's cross_check tool, never from a check the model writes out itself.
Model-agnostic backends. The Anthropic API for Claude, and an OpenAI-compatible endpoint (vLLM) for open VLMs.
Tools
| Group | Tool | Purpose | Default backing |
|---|---|---|---|
| Navigate | list_assets |
Filter assets by name, type, metadata | Registry |
view |
Render a region at the model's max resolution, optional source-pixel grid | Pillow | |
sample_frames |
Contact sheet of N frames over a time range | PyAV | |
| Search | search |
Text query over the embedding index; video hits merge into time windows | SigLIP |
detect |
Open-vocabulary boxes, rendered as marks | OWLv2 or Grounding DINO | |
segment |
Masks from points, boxes, or marks | SAM 2 | |
track |
Propagate masks through a video from one frame; when an object is present | SAM 2 (video) | |
ocr |
Text with boxes | PaddleOCR | |
| Measure | python |
Sandboxed kernel with numpy, OpenCV, workspace mounted read-only | Jupyter kernel |
depth |
Monocular depth | Depth Anything V2 | |
pointmap |
Multi-view pointmaps, poses, reprojection error | VGGT or DUSt3R | |
| Annotate | annotate |
Draw boxes, masks, labels, arrows | Pillow |
note |
Append a finding to session notes | Harness | |
| Verify | overlay |
Render claimed geometry on the source and return it for re-inspection | Pillow |
cross_check |
Answer the same question with independent methods and compare | Harness | |
coverage |
Viewed regions and frames, by scale | Context manager | |
| Delegate | delegate |
One subagent per time window of a video (visru loop only, not MCP) | Harness |
| Finish | submit_report |
Submit claims with evidence IDs; rejects malformed claims | Ledger |
In fp16, OWLv2, SAM 2, SigLIP, and Depth Anything V2 fit on one 24 GB GPU. VGGT memory grows with the number of views.
Quick start
git clone git@github.com:engichang1467/VisRU.git && cd visru
uv venv && source .venv/bin/activate
uv pip install -e ".[tools]"

# Build the registry and embedding index for a folder
visru index "$(pwd)/sample_data" --embed

# Draft sample_data/VISRU.md (the model survey needs a key; add --no-model to skip it)
export ANTHROPIC_API_KEY=...
visru init sample_data

visru run sample_data --task "In trial_01.mp4, when is the street-name sign legible?" --max-steps 30
With Claude Code
claude mcp add -s user visru -- "$(pwd)/.venv/bin/python" -m visru.servers.vision_mcp \
  --workspace "$(pwd)/sample_data"

# Claude Code reads CLAUDE.md, so point it at VISRU.md with an import
visru init sample_data --no-model
echo "@VISRU.md" > sample_data/CLAUDE.md
cd sample_data/ && claude
Then ask something like:
In the scene_b stills, read every storefront sign on the right side of the street,
citing the artifact ID of the view you read it from. In trial_01.mp4, find the frame
window where the street-name sign becomes legible. Tell me which assets you did not
inspect at native scale. Finish with submit_report.
With visru's own loop
visru run sample_data --task "What store name is on the tall vertical neon sign?" --max-steps 20
This uses the model in visru.toml (Anthropic by default; export ANTHROPIC_API_KEY, since visru does not read .env files). It prints the report and writes the trajectory, ledger, and an HTML report under sample_data/.visru/. Re-render a report with visru report sample_data [session]. Pass --backend replay --script turns.json to run the loop without API spend.
To switch models without a visru.toml, use --backend, --model and --base-url on visru run, or set VISRU_BACKEND, VISRU_MODEL and VISRU_BASE_URL. Flags override env vars, and env vars override visru.toml. openai is shorthand for openai_compatible pointed at https://api.openai.com/v1:
# Method 1
visru run sample_data --task "..." --backend openai --model gpt-5.4-2026-03-05

# Method 2
VISRU_BACKEND=openai_compatible VISRU_BASE_URL=http://localhost:23203/v1 \
  VISRU_MODEL=Qwen/Qwen3-VL-32B-Thinking-FP8 visru run sample_data --task "..."
Open models still need their image limits (patch, max_edge, max_visual_tokens) set in visru.toml; see below.
Project context
VISRU.md carries whatever the model cannot see in the pixels:
# Workspace: warehouse inspection set

- 1,240 RGB images, 4032x3024, phone camera, no intrinsics.
- "Torn" means a visible tear through the printed area. Creases do not count.
- Labels are 10x15 cm. Anything smaller is a different sticker.
- Report findings per image ID. Measurements in pixels unless a ruler is visible.
visru run appends the workspace's VISRU.md to the system prompt. visru init <folder> drafts one, the way /init drafts a CLAUDE.md:
- Assets and Other files, read off the registry: filename groups with sizes, frame rates and durations, plus any non-media files (calibration, labels, metadata). Exact and free.
- Observed, from a short model survey (about 15 steps over 1–2 assets per filename group): the domain, what each group shows, visible text, and what makes the images hard to read. Each line cites the artifact it came from. Guesses the pixels cannot confirm, such as the camera model, go under Unconfirmed for you to check or delete.
- Domain notes, left blank for you: intrinsics, class definitions, defect criteria, units. The survey never fills these in.
- Rules, the standing instructions from
VISRU.md.example.
--no-model skips the survey and spends nothing. If a VISRU.md already exists, init writes VISRU.md.new for you to diff instead of overwriting your edits. init takes the same --backend, --model and --base-url flags as run.
Configuration
Model image limits change between models, so they live in visru.toml:
[model]
backend = "anthropic"        # or "openai_compatible"
name = "claude-sonnet-5"
max_edge = 2576
max_visual_tokens = 4784
patch = 28
max_upscale = 2.0

[context]
max_live_images = 16         # stays under the API's 20-image threshold
elide_batch = 8              # elide in batches to keep the cached prefix stable
compact_at_tokens = 150_000

[coverage]
inspected_scale = 1.0        # rendered px per source px that counts as "inspected"
See the Claude vision docs for current limits.
Evaluation
Three arms on the same questions: single pass on the downsized image, view only (zoom-only), and the full tool set.
python -m evals.import_bench vstar          # also: hrbench_4k, hrbench_8k, charades_sta
B=bench/vstar; Q=$B/questions.jsonl

python -m evals.baseline --workspace $B --questions $Q --sample 100
python -m evals.agent --workspace $B --questions $Q --sample 100 --arm zoom_only \
    --out evals/runs/zoom_only_vstar.jsonl
python -m evals.agent --workspace $B --questions $Q --sample 100 --arm full \
    --out evals/runs/full_vstar.jsonl
python -m evals.score --questions $Q evals/runs/baseline_*.jsonl \
    evals/runs/zoom_only_vstar.jsonl evals/runs/full_vstar.jsonl
--sample N --seed S draws the same questions for every arm. Every arm accepts --backend openai_compatible --config open.toml to run against an open model. The scorer prints accuracy per arm and category, cost per question, and accuracy grouped by ledger status, which measures whether verified claims are actually more accurate than supported ones. Answers it cannot grade mechanically are marked review; settle them by adding "correct": true or false to the run file.
Custom question sets are JSONL:
{"id": "q01", "asset": "scene_b_1546479680612194.jpg",
 "question": "What does the vertical neon sign on the right read?",
 "answer": "TRADER JOE'S", "accept": ["trader joes"], "kind": "text"}
kind is one of text, count, localize, temporal (answered as start..end seconds, with a tolerance). Validate a set with python -m evals.suite questions.jsonl --workspace sample_data. Charades-STA is licensed for non-commercial research use only.
Open questions
- Do the checks predict correctness? If
verifiedclaims are no more accurate thansupportedones, the verification layer needs redesigning. - Where should looking happen: inside the model through learned token selection (LookWhere-style), or outside through tool calls? At what resolution or corpus size does the answer flip?
- Can trajectories ending in verified, correct claims train an open VLM (SFT, then RL) to reach the same answers with fewer visual tokens?
- What stopping rule tells the agent it has looked enough?
- How much of the gain comes from zoom alone?
References
- Gupta and Kembhavi. Visual Programming: Compositional Visual Reasoning without Training. CVPR 2023.
- Surís, Menon, Vondrick. ViperGPT: Visual Inference via Python Execution for Reasoning. ICCV 2023.
- Hu et al. Visual Sketchpad: Sketching as a Visual Chain of Thought for Multimodal Language Models. NeurIPS 2024.
- Wu and Xie. V*: Guided Visual Search as a Core Mechanism in Multimodal LLMs. CVPR 2024.
- Yang et al. Set-of-Mark Prompting Unleashes Extraordinary Visual Grounding in GPT-4V. arXiv 2023.
- Zheng et al. DeepEyes: Incentivizing "Thinking with Images" via Reinforcement Learning. arXiv 2025.
- Fuller et al. LookWhere? Efficient Visual Recognition by Learning Where to Look and What to See from Self-Supervision. arXiv 2025.
- Ravi et al. SAM 2: Segment Anything in Images and Videos. ICLR 2025.
- Minderer et al. Scaling Open-Vocabulary Object Detection (OWLv2). NeurIPS 2023.
- Liu et al. Grounding DINO. ECCV 2024.
- Zhai et al. Sigmoid Loss for Language Image Pre-Training (SigLIP). ICCV 2023.
- Yang et al. Depth Anything V2. NeurIPS 2024.
- Wang et al. DUSt3R: Geometric 3D Vision Made Easy. CVPR 2024.
- Wang et al. VGGT: Visual Geometry Grounded Transformer. CVPR 2025.
- Wang et al. Divide, Conquer and Combine (HR-Bench). AAAI 2025.
- Zhang et al. MME-RealWorld. ICLR 2025.
- Fu et al. Video-MME. CVPR 2025.
- Wu et al. LongVideoBench. NeurIPS 2024 Datasets and Benchmarks.
1 maintainer

Metadata
1 maintainer
Release files for visru 0.2.0
For a detailed explanation of source distributions (sdists) and built distributions (wheels), please see the package formats documentation.
Source distribution (sdist)
| File | Size | Uploaded | |
|---|---|---|---|
| visru-0.2.0.tar.gz | 81.5 kB | Details |
Built distribution (wheel)
| File | Interpreter | ABI | Platform | Reset |
|---|---|---|---|---|
| visru-0.2.0-py3-none-any.whl | Python 3 | none | any | Details |
Total release size: 179.2 kB
Release files / visru-0.2.0.tar.gz
| Download URL | visru-0.2.0.tar.gz |
|---|---|
| Size | 81.5 kB |
| Tags | Source |
|
SHA-256 checksum How to use checksums |
a0bb101b8da4cb4b7716921ba0322b04c5893b88ecabec316e05e4f7c2ecfd70
|
|
BLAKE2b-256 checksum How to use checksums |
6b69ae1da9c25b206437d1b8b7c0fe1033cd35521cf145801afc053c4c651967
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
No |
| Uploaded via |
twine/7.0.0 CPython/3.11.14
|
Release files / visru-0.2.0-py3-none-any.whl
| Download URL | visru-0.2.0-py3-none-any.whl |
|---|---|
| Size | 97.7 kB |
| Tags | Python 3 |
|
SHA-256 checksum How to use checksums |
6bf913fa5d70e4e7b0fa4bf547dd28d6419baf97c6bca7b1d8bfd31f94f54f70
|
|
BLAKE2b-256 checksum How to use checksums |
df825c1428957d51972d1f2eb79e4ce0cdc6c3d41a1d22f817ad4254309e25c6
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
No |
| Uploaded via |
twine/7.0.0 CPython/3.11.14
|














