
VLM Eval Harness


CLI-first Python harness for evaluating vision-language models (VLMs) and multimodal LLMs across multiple benchmarks with unified logging and reports.
Run many VLM benchmarks with one command, with typed configs and reproducible JSON/CSV logs.
Status: ✨ Planning / scaffolding — API and benchmark list may evolve.
Why you might care
- You want a single CLI to run many VLM benchmarks without copy‑pasting ad‑hoc scripts.
- You care about reproducible JSON/CSV logs instead of screenshots of leaderboards.
- You want a typed benchmark protocol so new tasks and model adapters plug in cleanly.
10-second example
Run the working slice — the in-repo toy_qa benchmark against the trivial
echo model — straight from the CLI:
# 10-second example: run the toy QA benchmark with the echo model
vlm-eval run \
  --benchmark toy_qa \
  --model echo \
  --config configs/toy_qa_echo.yml
This writes records.jsonl, records.csv, and summary.json under
runs/toy_qa_echo/. The echo model only echoes the question, so its accuracy
is honestly 0.0 — the example proves the pipeline runs end to end, not model
quality. See Quickstart for details.
Architecture
The CLI parses flags into a config, which selects a benchmark and a model adapter; the benchmark yields examples, the model adapter answers them, the evaluation step scores the answers, and everything is written to JSON/CSV logs.
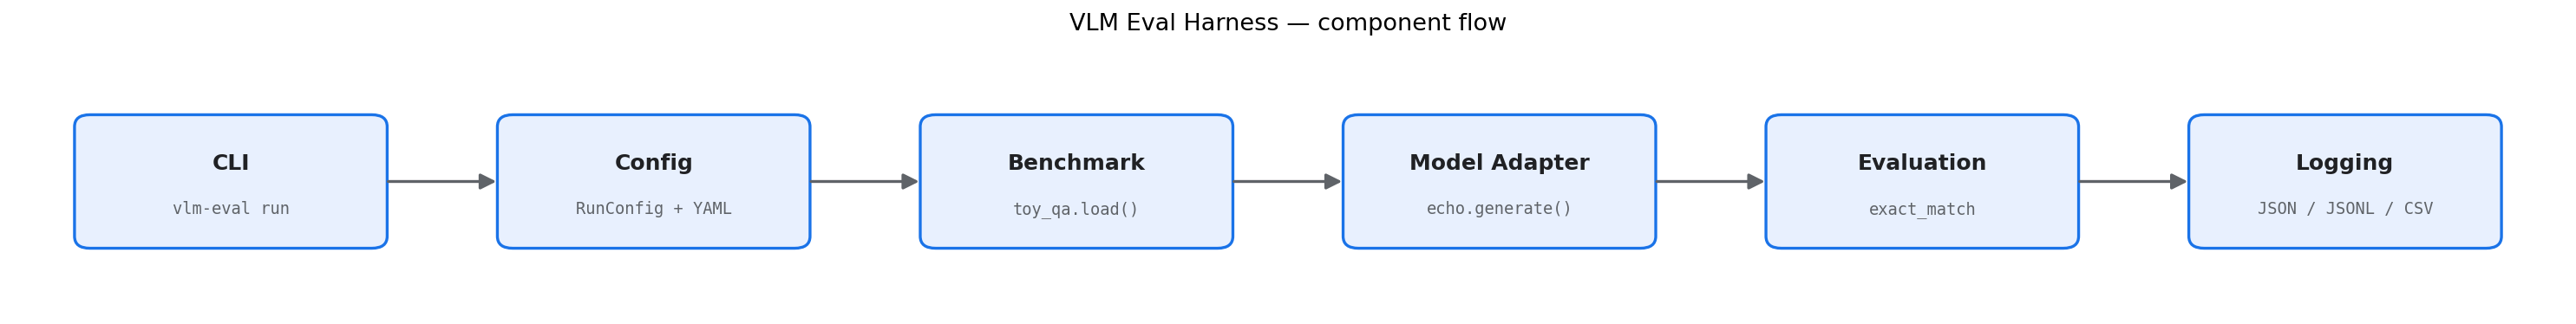
Regenerate the diagram with python scripts/generate_architecture_diagram.py.
Goals
- Provide a single CLI to run multiple VLM benchmarks.
- Support both hosted APIs (e.g., OpenAI, Anthropic) and local models.
- Log results in a unified JSON / CSV schema for leaderboard analysis.
- Make it easy to plug in new tasks, prompts, and models.
Planned Features
vlm-eval run \with:--benchmark(or--suite) flag--model/--provider(openai,local, etc.)--configYAML for prompts, decoding, and logging
- Built-in adapters for common VLM / MLLM APIs
- Evaluation datasets wired through the
awesome-vlm-evaluationlist - Simple Python API on top of the CLI
Repository Layout (planned)
vlm-eval-harness/
  vlm_eval/
    cli.py           # Typer / Click CLI entrypoint
    config.py        # Pydantic / OmegaConf config definitions
    models/          # Model adapters (OpenAI, local, etc.)
    benchmarks/      # Benchmark runners and task definitions
    logging/         # JSON / CSV logging utilities
    evaluation/      # Metric computation, aggregation
  scripts/
    run_benchmark.py # Example invocations
  configs/
    openai-gpt4o.yml
    local-llava.yml
  tests/
  README.md
  pyproject.toml
Getting Started
This repository is currently in the design and scaffolding phase.
Planned steps:
- Finalize the minimal benchmark set and logging schema.
- Implement a thin model adapter interface.
- Add 1–2 reference configs and example runs.
- Tag an
0.1.0pre-release once something reproducible and useful exists.
If you are interested in collaborating, feel free to open an issue with suggestions on:
- Benchmarks you would like to see wired in first.
- Model providers you care about.
- Logging / schema constraints you need for your own analysis.
Quickstart (minimal working slice)
A first runnable vertical slice is implemented: a toy_qa in-repo benchmark
and a trivial echo model adapter, wired through the CLI with unified
JSON / JSONL / CSV logging.
⚠️ This slice exists to prove the pipeline runs end to end. The
echomodel only echoes the question back, so it answers nothing correctly — its accuracy ontoy_qais honestly 0.0. There are no real benchmark numbers here yet; real benchmarks and model adapters are TODO.
Install
pip install -e .          # installs the `vlm-eval` CLI
# optional: dev/test extras
pip install -e ".[dev]"
Requires Python 3.10+. Runtime deps are intentionally small: typer,
pydantic, pyyaml (plus pytest for tests).
Run the toy benchmark
vlm-eval run --benchmark toy_qa --model echo --config configs/toy_qa_echo.yml
CLI flags (--benchmark, --model, --output-dir, --limit) override the
YAML config. Helpers:
vlm-eval list        # show registered benchmarks and models
vlm-eval --version
You can also drive it from Python instead of the CLI:
python scripts/run_toy_qa.py
Output files
Each run writes to <output_dir>/<run_name>/ (default runs/toy_qa_echo/):
| File | Contents |
|---|---|
records.jsonl |
One record per example: {id, question, expected_answer, model_answer, correct} |
records.csv |
The same per-example records as CSV |
summary.json |
Aggregated metrics {num_examples, num_correct, accuracy} + run metadata |
All metrics are computed from actual model outputs — nothing is hard-coded.
Tests
pytest
The tests run the full toy pipeline and check the log files; they need no API keys and no network access.
What's real vs. TODO
- ✅ CLI (
vlm-eval run/list), YAML config, model-adapter interface, toy benchmark, exact-match metric, JSON/JSONL/CSV logging, tests. - ⏳ TODO: real benchmarks, hosted-API and local-model adapters, richer
metrics, and true image inputs (the toy data already carries an
imageplaceholder field so image paths can be plugged in later).
Package layout (as implemented)
vlm_eval_harness/
  cli.py             # Typer CLI: `vlm-eval`
  config.py          # Pydantic RunConfig + YAML loader
  core.py            # shared run_evaluation() orchestrator
  models/            # base adapter + echo adapter + registry
  benchmarks/        # toy_qa benchmark + registry
  evaluation/        # exact-match metric + aggregation
  logging/           # JSON / JSONL / CSV logger
scripts/run_toy_qa.py
configs/toy_qa_echo.yml
tests/
1 maintainer

Metadata
1 maintainer
Release files for vlm-eval-harness 0.1.1
For a detailed explanation of source distributions (sdists) and built distributions (wheels), please see the package formats documentation.
Source distribution (sdist)
| File | Size | Uploaded | |
|---|---|---|---|
| vlm_eval_harness-0.1.1.tar.gz | 16.0 kB | Details |
Built distribution (wheel)
| File | Interpreter | ABI | Platform | Reset |
|---|---|---|---|---|
| vlm_eval_harness-0.1.1-py3-none-any.whl | Python 3 | none | any | Details |
Total release size: 31.8 kB
Release files / vlm_eval_harness-0.1.1.tar.gz
| Download URL | vlm_eval_harness-0.1.1.tar.gz |
|---|---|
| Size | 16.0 kB |
| Tags | Source |
|
SHA-256 checksum How to use checksums |
fcfc1423ee49a9babc6506e98400d5368108dd482052d3507a4e9060782c06bc
|
|
BLAKE2b-256 checksum How to use checksums |
be9d2ab0d5f22983cd30fd2336aa60ca026a6ead893dbc87df7cb6353e502db2
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
Yes |
| Uploaded via |
twine/6.1.0 CPython/3.13.12
|
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.


PyPI Publish Attestation
PyPI verified that this artifact, at this checksum, originated from the publisher listed below.
Signed by GitHub Actions, verified by PyPI on Jun 19, 2026.
Transparency logRelease files / vlm_eval_harness-0.1.1-py3-none-any.whl
| Download URL | vlm_eval_harness-0.1.1-py3-none-any.whl |
|---|---|
| Size | 15.8 kB |
| Tags | Python 3 |
|
SHA-256 checksum How to use checksums |
820690da01cc40532546ea0b2ebefe0a16de5e8afe06d568b5c5d3933e0341d9
|
|
BLAKE2b-256 checksum How to use checksums |
6e1e3d10e4bb46e1cd817fa6a05cb927968432157b693ef4c338ea99d113ca38
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
Yes |
| Uploaded via |
twine/6.1.0 CPython/3.13.12
|
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.
PyPI Publish Attestation
PyPI verified that this artifact, at this checksum, originated from the publisher listed below.
Signed by GitHub Actions, verified by PyPI on Jun 19, 2026.
Transparency log













