
VLM Probing
Exploring Model Internals Beyond the Answer

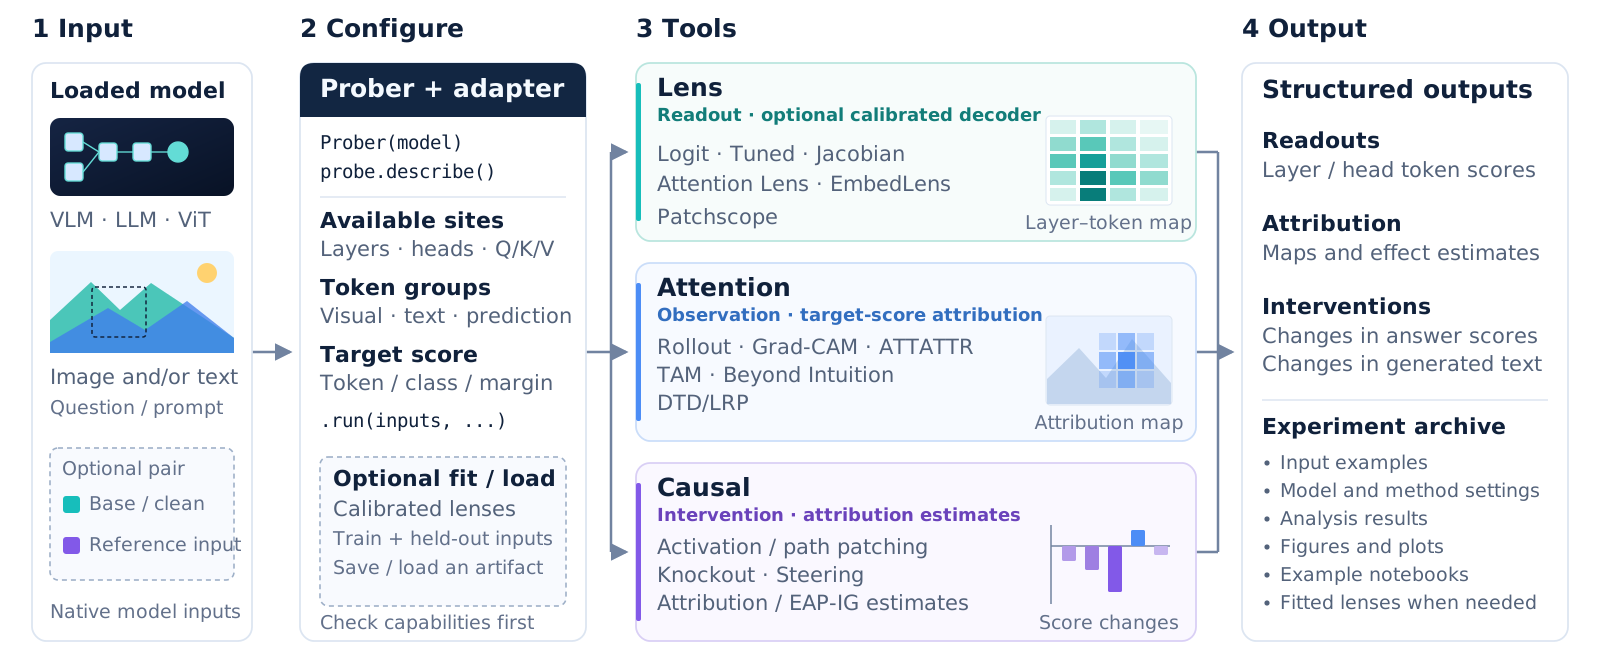
VLM Probing brings lens readouts, attention explanations, and causal interventions into one model-bound interface. It supports vision-language models, language models, and a ViT image-classification control. Bind a loaded model once, select layers and token groups, and inspect how its internal computation relates to a chosen answer.
- Lens: read vocabulary predictions from residual states, attention heads, or projected visual embeddings.
- Attention: compare attention patterns and target-conditioned spatial attributions on the same input.
- Causal: replace activations, isolate paths, block attention routes, or steer residual states and measure the resulting change.
Explicit adapters handle hook locations, expanded visual-token coordinates, and model readouts. Results retain tensors and experiment metadata; shared visualization functions turn them into heatmaps, image overlays, curves, and connection graphs. Capability checks distinguish an unsupported operation from a measured zero effect.
Project Page · Documentation · Demos · Visualization · Technical report · Papers and datasets
Installation
Python 3.10+ is required. Install directly from GitHub; no manual clone or
PYTHONPATH setup is needed:
python -m pip install "vlmprobe[transformers,visualization] @ git+https://github.com/gexinh/vlm-probing.git"
For tensor methods and custom PyTorch adapters, install the base package:
python -m pip install "vlmprobe @ git+https://github.com/gexinh/vlm-probing.git"
The Python import name is vlmprobe. Existing vlm_probing imports remain
compatible, including adapter registration and saved Python objects.
import vlmprobe

probe = vlmprobe.Prober(model, processor)  # use your loaded model
result = probe.lens.logit(tokens="last_prompt").run(inputs)
The base package requires only PyTorch. The transformers extra targets
Transformers 5.3.x and includes Accelerate, Torchvision, and Pillow;
visualization provides the plotting dependencies. Add notebooks when using
Jupyter. Model weights and complete datasets are downloaded separately.
To develop the library in a checkout, use
python -m pip install -e ".[transformers,visualization,notebooks]".
The package guide covers wheels and PyPI publication.
The short PyPI command pip install vlmprobe becomes available after the first
PyPI release; the GitHub installation above works independently of PyPI.
Quick Start
This example loads Qwen3-VL-2B-Instruct on one CUDA GPU. Replace
example.jpg with your image, or use an image from the bundled demos.
import torch
from PIL import Image
from transformers import AutoModelForImageTextToText, AutoProcessor
from vlmprobe import Prober

model_id = "Qwen/Qwen3-VL-2B-Instruct"
model = AutoModelForImageTextToText.from_pretrained(
    model_id, dtype=torch.bfloat16, device_map={"": "cuda:0"},
    attn_implementation="eager",
)
processor = AutoProcessor.from_pretrained(model_id)
probe = Prober(model, processor)

messages = [{"role": "user", "content": [
    {"type": "image"},
    {"type": "text", "text": "What is in this image?"},
]}]
prompt = processor.apply_chat_template(
    messages, tokenize=False, add_generation_prompt=True,
)
inputs = probe.prepare(
    prompt=prompt, image=Image.open("example.jpg").convert("RGB"), device="cuda:0",
)

print(probe.describe()["methods"]["lens.logit"])
result = probe.lens.logit(layers=[0, 13, 27], tokens="last_prompt").run(inputs)
token_id = result.tensors["logits"][-1, 0].argmax().item()
print(processor.tokenizer.decode([token_id]))
result.save("outputs/logit_lens")

# Read projected image tokens in the input embedding space.
visual = probe.lens.embed(tokens="visual").run(inputs, top_k=5)

# Observe the attention actually used by the language decoder.
attention = probe.attention.profile(
    layers=[27], queries="last_prompt", include_attention=True,
).run(inputs)
Use a model you have already loaded, and pass its native processor dictionary
directly to .run(...) when convenient. Layer indices are zero-based; tokens
refer to the expanded sequence, including image positions. The
model guides explain each architecture's input contract.
from vlmprobe import visualization as viz

answer_id = processor.tokenizer.encode(" yellow", add_special_tokens=False)[0]
ax = viz.plot_lens_heatmap(result, target_token_id=answer_id)
ax.figure.savefig("outputs/lens.png", bbox_inches="tight")
This plots one vocabulary token's rank across selected layers and positions. A complete answer can contain several tokens; choose the intended subword explicitly, or use complete-answer metrics for interventions.
| Common operation | Purpose |
|---|---|
Prober(model, processor=None) |
Bind a caller-owned model and resolve its adapter. |
probe.describe() |
Inspect available methods, sites, and missing capabilities. |
probe.prepare(prompt=..., image=..., device=...) |
Convert formatted text and images into native inputs. |
probe.lens / probe.attention / probe.causal |
Configure a method in one of three families. |
method.run(inputs, ...) |
Execute a probe and return ProbeResult. |
method.fit_batches(...) / method.load(...) |
Calibrate or restore Tuned/Attention Lens; Jacobian Lens has a separate estimator. |
result.save(directory) |
Save CPU tensors and JSON metadata. |
The API guide covers selectors, complete-answer metrics, paired-input alignment, and result shapes. Visualization describes reusable plotting functions. The demos include saved real measurements and input images for offline replay; rerunning a model is an explicit option. A small CPU example exercises the API without downloading pretrained weights.
Model Support
Eight VLM families have explicit adapters. Text-only GPT-2/Llama and a ViT classifier provide complementary controls. Availability is method-specific; see the capability matrix.
| Family | Example checkpoint | Guide |
|---|---|---|
| Qwen3-VL | Qwen3-VL-2B-Instruct | Usage |
| Qwen2.5-VL | Qwen2.5-VL-3B-Instruct | Usage |
| Qwen2-VL | Qwen2-VL-2B-Instruct | Usage |
| Qwen3.5 | Qwen3.5-4B; hybrid attention restrictions | Usage |
| SmolVLM | SmolVLM-500M-Instruct | Usage |
| InternVL | InternVL3-1B-hf | Usage |
| LLaVA | llava-1.5-7b-hf | Usage |
| Pixtral | Pixtral-12B-2409 | Usage |
| Language models | GPT-2 / Llama | GPT-2 · Llama |
| Vision classifier | ViT-B/16 | Usage |
Methods
Each guide explains the implemented computation, parameters, outputs, and relationship to its original paper. Reusable primitives are labeled separately from paper methods.
| Family | Method guides |
|---|---|
| Lens | Logit · Tuned · Attention Lens · Jacobian · EmbedLens · Patchscopes |
| Attention | Rollout · Grad-CAM, ATTATTR, TAM, Beyond Intuition · Generic relevance · ViT DTD/LRP |
| Causal | Activation patching · IOI-style path patching · Attribution patching · Attention Knockout · EAP / EAP-IG · Residual steering / VSV |
| Supporting tools | Attention profile · Head logit attribution · Probability reweighting · Temperature |
Package Architecture
src/vlmprobe/    # public import name; shares the implementation below
src/vlm_probing/
  prober.py       # shared model-bound entry point
  api/           # method factories, capture and replay
  adapters/      # explicit architecture and token-layout contracts
  lenses/        # BaseLens and concrete readout methods
  attention/     # BaseAttention and concrete attention methods
  causal/        # BaseCausal and concrete interventions/estimators
  training/      # calibration, checkpoint import and resume
  visualization/ # shared heatmaps, overlays, curves and graphs
  core/          # results and execution traces
demos/           # runnable notebooks, compact measurements and input images
docs/            # model, method, API and source guides
Family base classes keep algorithm implementations small; adapters let them share model execution. Architecture and adapter contracts describe these boundaries.
References
The paper and dataset index links the original method papers, author implementations, and datasets used for demonstrations and lens calibration. The technical report compares real readouts, explanations, and interventions on shared cases across five pretrained VLMs, with language and vision controls.
1 maintainer

Metadata
1 maintainer
Release files for vlmprobe 0.9.0
For a detailed explanation of source distributions (sdists) and built distributions (wheels), please see the package formats documentation.
Source distribution (sdist)
| File | Size | Uploaded | |
|---|---|---|---|
| vlmprobe-0.9.0.tar.gz | 111.0 kB | Details |
Built distribution (wheel)
| File | Interpreter | ABI | Platform | Reset |
|---|---|---|---|---|
| vlmprobe-0.9.0-py3-none-any.whl | Python 3 | none | any | Details |
Total release size: 250.9 kB
Release files / vlmprobe-0.9.0.tar.gz
| Download URL | vlmprobe-0.9.0.tar.gz |
|---|---|
| Size | 111.0 kB |
| Tags | Source |
|
SHA-256 checksum How to use checksums |
f0516111d429a8b9fb3de8c853a8c2de292df77b351a2525919709432c38f828
|
|
BLAKE2b-256 checksum How to use checksums |
2833164edae398b9fcde65eb57bf243ec580516aeabd5926134d66dd8de0296e
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
Yes |
| Uploaded via |
twine/7.0.0 CPython/3.13.14
|
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.


PyPI Publish Attestation
PyPI verified that this artifact, at this checksum, originated from the publisher listed below.
Signed by GitHub Actions, verified by PyPI on Oct 11, 2026.
Transparency logRelease files / vlmprobe-0.9.0-py3-none-any.whl
| Download URL | vlmprobe-0.9.0-py3-none-any.whl |
|---|---|
| Size | 139.9 kB |
| Tags | Python 3 |
|
SHA-256 checksum How to use checksums |
06066f8b88eaec2fc33cc9084a0963d5cafa60162637b8454193047cd9b2b2dc
|
|
BLAKE2b-256 checksum How to use checksums |
6073c859bc0d7b2c47c34ed3e0490979ccedcbdd7d1fc2c2a353c4410e3a7529
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
Yes |
| Uploaded via |
twine/7.0.0 CPython/3.13.14
|
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.
PyPI Publish Attestation
PyPI verified that this artifact, at this checksum, originated from the publisher listed below.
Signed by GitHub Actions, verified by PyPI on Oct 11, 2026.
Transparency log












