
voice-tunnel


Talk to your coding agent from your phone. One command opens a page any phone browser can load — no app, no App Store — and carries audio both ways.
Watch it work
https://github.com/user-attachments/assets/a5be07a0-b1dc-446d-919f-c9351a583a2f
A real session, phone in hand: "can you hear me", then shipping a release end to end. The
skipped Ns badges are the agent thinking — that time is real and this cut discloses it rather
than editing it out. The tunnel's own half of the round trip is about a second.
Quick start
npm install -g @juanjofuchs/voice-tunnel
voice-tunnel setup                     # engines + models, one command
voice-tunnel serve --wake claude       # use YOUR agent's name
Open the printed URL on your phone, tap once, and say "hey Claude, what's the status?"
The npm package is a launcher, not a bundle: it needs Python 3.10+ on PATH and builds a
private environment inside itself, touching nothing else on your machine. If you would rather
skip that layer, pipx install voice-tunnel is the same tool with one fewer wrapper, and
WinGet needs nothing installed at all.
Everything runs on your machine. No GPU. No account. No speech API.
Driving this from an agent
Point it at describe before anything else:
voice-tunnel describe # the whole contract, as JSON
That one call is the entire onboarding — no MCP server, no daemon, no separate documentation to
keep in sync. It returns the loop to run, the turn schema, every command and argument, the exit
codes, and the two rules an agent gets wrong first: watch blocks, so an agent not sitting in
it has left you talking to nobody; and one thought arrives as several turns, so answering the
first one answers the wrong question. Every command also returns a next field telling the agent
what to do at the moment it applies, rather than in a document it read once.
describe is generated from the same source as the behaviour, so it cannot drift from the tool
the way a README can. When something is wrong, voice-tunnel doctor says what and hands back the
command that fixes it — read its degraded list even when ok is true, because a machine can
have a neural voice and a fast recognizer sitting on disk while this process uses neither.
The wedge is borrowed from agent-mail.
What this is
The tool holds no model and makes no decisions. It turns your speech into lines in a log and text into speech; the agent that started it does the thinking. That is why it works with any agent — Claude Code, Codex and Grok have each driven it unchanged.
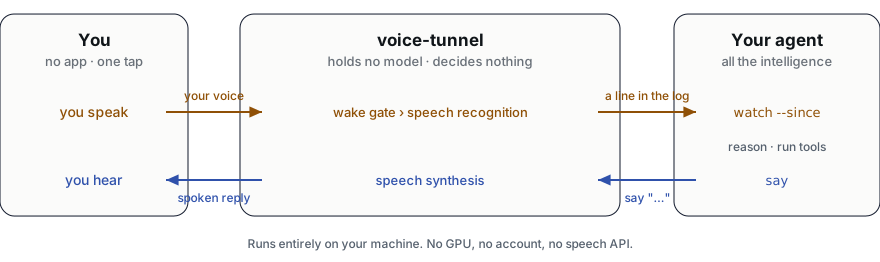
The cursor is what makes the split safe. watch --since <cursor> blocks until a turn lands and
returns everything after the cursor, so nothing you said is dropped while the agent spends thirty
seconds thinking about the last thing.
Install
npm
npm install -g @juanjofuchs/voice-tunnel
voice-tunnel setup
Needs Python 3.10+ on PATH. The postinstall builds a private virtualenv inside the package and
installs the matching PyPI release into it — your global Python environment is never modified, and
npm uninstall removes all of it. A failed postinstall is not fatal: it reports what is missing
and the launcher repeats the guidance when you actually run the tool.
pipx
pipx install voice-tunnel
voice-tunnel setup
The canonical artifact — this is a Python package, and pipx installs it isolated without the npm layer in between.
pip
pip install voice-tunnel
WinGet (Windows, no Python needed)
winget install JuanjoFuchs.voice-tunnel
The only channel that needs nothing else installed. Windows may flag it on first run: the bundle is unsigned, and Defender's heuristic dislikes unsigned Python bundles.
Better voice and better recognition
voice-tunnel setup does all of this in one command. The pieces, if you want them individually:
pip install voice-tunnel[all]      # or [piper] / [parakeet]

voice-tunnel download asr          # Parakeet — 8x faster than whisper, more accurate
voice-tunnel download voice        # a neural voice instead of the robotic one
voice-tunnel download voiceprint   # learns your voice, so the wake phrase becomes optional
voice-tunnel download turn         # ends your turn when you SOUND finished, not on a timer
voice-tunnel download --list       # what is available, what you already have
Two independent things are involved and having one does not get you the other: the extras
supply the engines, the downloads supply the models. voice-tunnel doctor says which of them
this process is actually using, which is not always the best one present.
Models are downloaded, never bundled — a Parakeet checkpoint is 631 MB and would make the package unusable on a slow connection.
Use it
Start the tunnel with your agent's own name, and put its page somewhere your phone can reach.
voice-tunnel serve --wake claude # or codex, grok, whatever is driving
Your phone needs HTTPS to reach a microphone at all — that is a browser rule, and a plain LAN
address like http://192.168.1.20:8765 gives no microphone, not a broken one. The simplest
fix:
tailscale serve --bg 8765
voice-tunnel config set VOICE_TUNNEL_ALLOW_CIDRS 100.64.0.0/10
Then, from the agent's side, this is the whole loop:
voice-tunnel watch --session dev --since -1   # BLOCKS until you speak; returns turns + a cursor
voice-tunnel say   --session dev "All green." # speaks back
voice-tunnel watch --session dev --since 7    # always resume from the cursor you were given
Saying its name
The summons is a greeting plus a name: "hey claude", "hi codex", "ok grok". The greeting
is always required, which is what makes any name safe — grok is an English verb and cursor
is a word you say constantly, but nobody says "hey grok" by accident.
voice-tunnel wake --name codex # change it, live, no restart
Once the voiceprint knows you, you are addressed without saying anything.
Interrupting it
Start talking while it is speaking and it stops — but only for your voice. The voiceprint has to agree before a reply is cut off, so the television, someone else in the room, and the agent's own voice coming back through your speakers all leave it talking.
That last one is not a corner case. Without echo cancellation a reply leaks into the microphone on almost any device, and "the agent interrupts itself" is the default failure. Measured here: the owner's voice scores 0.23 against a 0.15 threshold, the agent's own voice scores 0.000.
Needs voice-tunnel download voiceprint and a voice it has learned. Without one it stays quiet
rather than guessing, because a tunnel that stops whenever the room makes a noise is worse than
one you cannot interrupt.
Knowing when you have finished
By default a turn ends after a fixed silence — 1.5 seconds. That number is a compromise: shorter cuts you off while you are still thinking, longer makes every quick question wait for nothing.
voice-tunnel download turn replaces it with Smart Turn v3.2 (8 MB, CPU, BSD-2-Clause),
which listens to how the sentence ended. A finished question closes early; a trailing "I was
thinking that maybe we could…" gets more room. It runs once at each pause, not continuously, and
if it is not installed the timer works exactly as it always has.
Requirements
No GPU. Every model here is CPU inference by construction — nothing in the codebase can use a graphics card. Measured on a 20-core desktop CPU:
| Memory | Disk | Speech recognition | |
|---|---|---|---|
Minimum — system voice + whisper base.en |
219 MB | ~150 MB | usable |
| Recommended — Parakeet + neural voice + voiceprint | ~1.0 GB | 788 MB | RTF 0.11 — 7.4 s of speech in 0.85 s |
- Python 3.10+ for pip and npm. WinGet needs nothing.
- A phone browser. Android Chrome is what this is tested on. The tab must stay in the foreground — background recording needs a native app, which this deliberately is not.
- HTTPS to the phone, via Tailscale or any tunnel. See Privacy.
- A slower CPU raises the real-time factor but does not break anything; the recognizer runs faster than real time with a lot of headroom.
Privacy
Speech recognition, synthesis, the voiceprint, and every turn of the transcript stay on your machine. There is no account and nothing is sent to a speech API.
The transport is your choice and they are not equivalent. Tailscale terminates TLS on your own device, so nobody else can decrypt the audio. An ngrok or Cloudflare tunnel terminates it at the vendor's edge — which puts the plaintext of everything you say on a machine you do not control. Sometimes that is the only thing that works, and it is still a trade worth making knowingly. If you expose it publicly, put real authentication in front of it: the built-in CIDR allowlist cannot help you there, because a tunnel forwards from localhost and every request therefore arrives from an allowed peer.
Your files are plain files. voice-tunnel config path says where. The voiceprint is a
192-dimension centroid — speech cannot be reconstructed from it.
Settings
voice-tunnel config show           # every setting, its value, and where it came from
voice-tunnel rate --speed 1.4      # talk faster — applies now and every session after
voice-tunnel verbose on            # narrate every action before doing it
voice-tunnel timing                # where the time actually went, per exchange
Precedence is process env > settings file > built-in default. .env.example documents every
variable.
Development
python -m venv venv
venv/Scripts/python -m pip install -e ".[dev,all]"

venv/Scripts/python -m pytest tests/ -q     # unit tests, no mic and no model
venv/Scripts/python scripts/e2e.py          # the pipeline, through a real browser
venv/Scripts/python scripts/layout.py       # page geometry, at five viewports
venv/Scripts/python scripts/channel.py      # the orb, mute and the speaking signal
venv/Scripts/python scripts/diagram.py      # regenerate the diagram above, both themes
| Path | What |
|---|---|
voice_tunnel/ |
store, asr, wake, tts, voiceprint, security, server, cli, config |
voice_tunnel/web/index.html |
the phone client, self-contained, no build step |
docs/ |
the README diagram, generated by scripts/diagram.py |
specs/ |
001 the tunnel · 002 packaging · 003 npm · 004 turn detection |
ai-docs/reference/ |
security model, turn-log contract, browser constraints |
License
MIT.
1 maintainer

Release files for voice-tunnel 0.2.6
For a detailed explanation of source distributions (sdists) and built distributions (wheels), please see the package formats documentation.
Source distribution (sdist)
| File | Size | Uploaded | |
|---|---|---|---|
| voice_tunnel-0.2.6.tar.gz | 222.2 kB | Details |
Built distribution (wheel)
| File | Interpreter | ABI | Platform | Reset |
|---|---|---|---|---|
| voice_tunnel-0.2.6-py3-none-any.whl | Python 3 | none | any | Details |
Total release size: 389.6 kB
Release files / voice_tunnel-0.2.6.tar.gz
| Download URL | voice_tunnel-0.2.6.tar.gz |
|---|---|
| Size | 222.2 kB |
| Tags | Source |
|
SHA-256 checksum How to use checksums |
c994f5dcb9caae6250fce66ad3184c5ccd180d4b094a22dda4b670bf7da5c8ef
|
|
BLAKE2b-256 checksum How to use checksums |
0a7580b7a7463563c8e0f33e39fa41a21095c5576181a27d9a9fc2770af73b6e
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
Yes |
| Uploaded via |
twine/7.0.0 CPython/3.13.14
|
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.


PyPI Publish Attestation
PyPI verified that this artifact, at this checksum, originated from the publisher listed below.
Signed by GitHub Actions, verified by PyPI on Aug 10, 2026.
Transparency logRelease files / voice_tunnel-0.2.6-py3-none-any.whl
| Download URL | voice_tunnel-0.2.6-py3-none-any.whl |
|---|---|
| Size | 167.4 kB |
| Tags | Python 3 |
|
SHA-256 checksum How to use checksums |
2d90e5ab1a90811a8bf160ea867015b2efbad2b2a392d6403a141d0b05fad3c9
|
|
BLAKE2b-256 checksum How to use checksums |
d0a7de746d9e617763415bac544ea4f2cd24d8bfdd36db12b8578e3445228943
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
Yes |
| Uploaded via |
twine/7.0.0 CPython/3.13.14
|
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.
PyPI Publish Attestation
PyPI verified that this artifact, at this checksum, originated from the publisher listed below.
Signed by GitHub Actions, verified by PyPI on Aug 10, 2026.
Transparency log













