
Waldean
Code linters check style. Waldean checks whether the analysis is a lie.
Waldean is a deterministic statistical-integrity linter for Python analysis. It flags a defined set of methodological hazards in notebooks and scripts, with evidence, and needs no LLM to do it.
Your model scores 0.99. Waldean asks whether the experiment that produced that number was valid: was the scaler fitted on the test rows, did the cross-validation shuffle a time series, were twenty tests run with no correction?
pip install waldean
waldean check your_notebook.ipynb
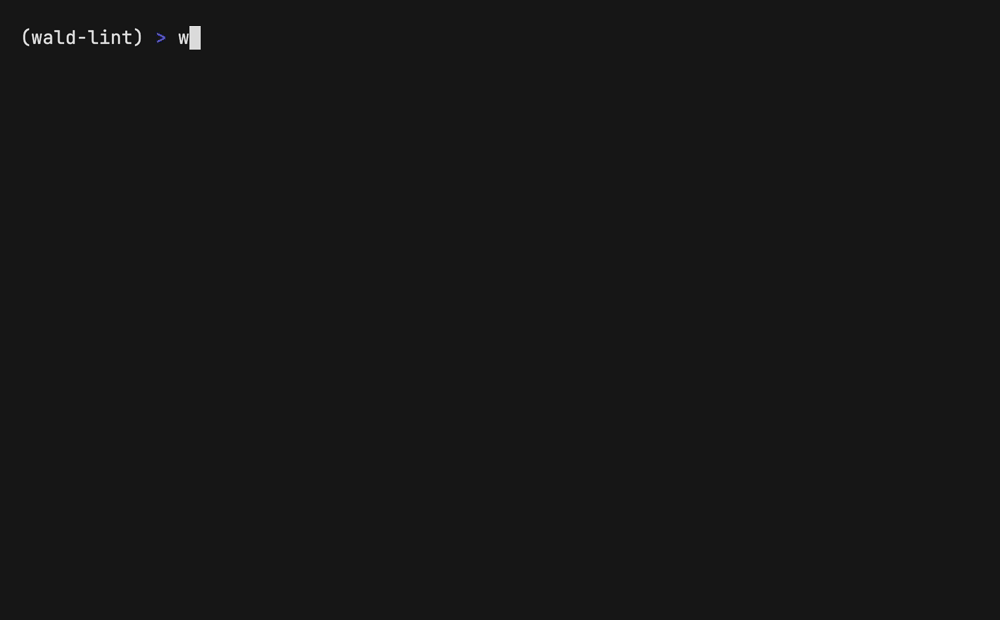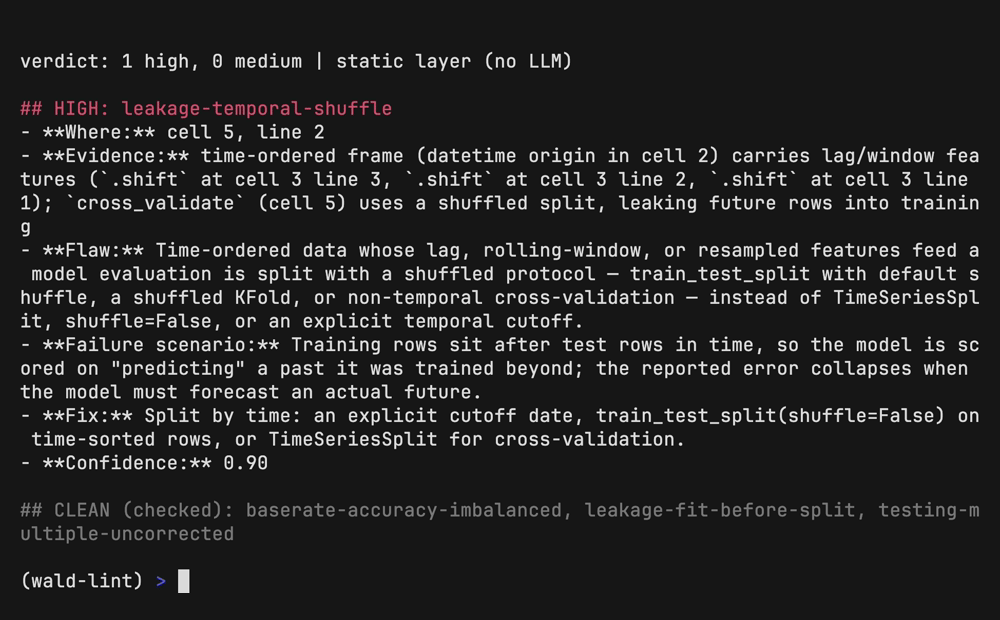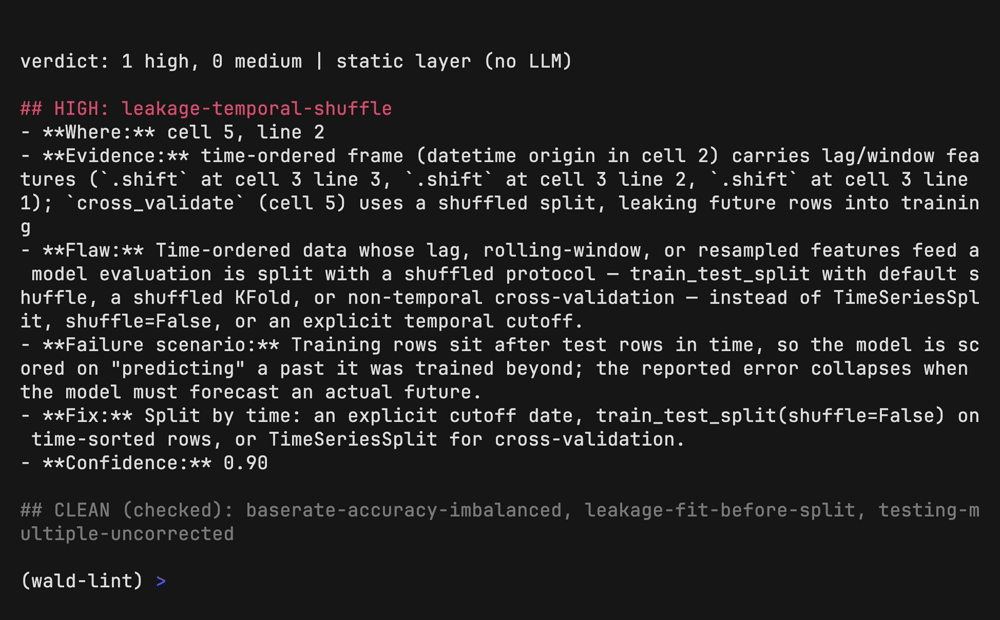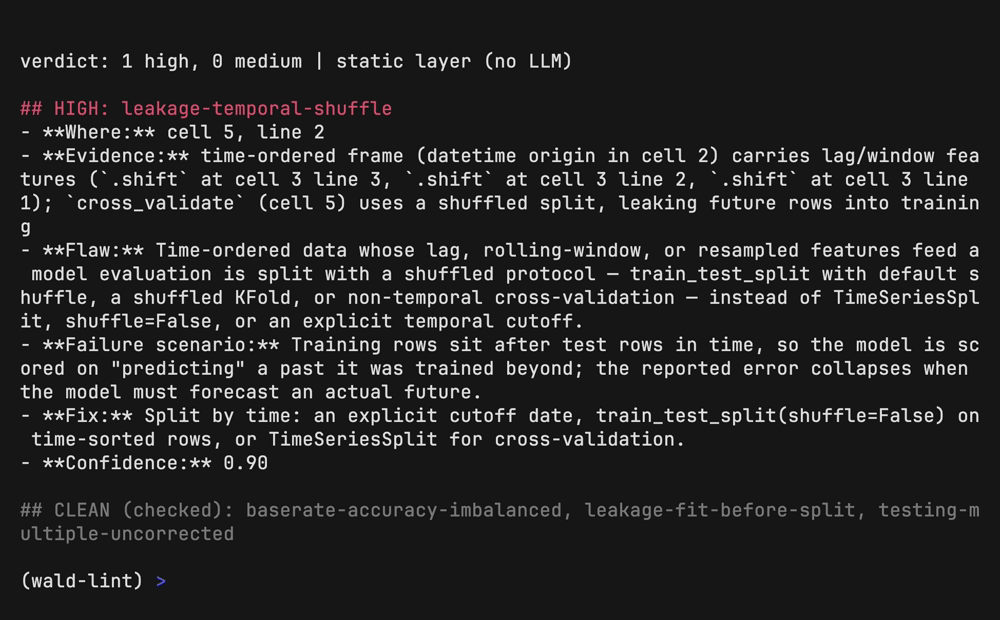
A real report, on examples/leaky.ipynb:
$ waldean check examples/leaky.ipynb

# Waldean report — examples/leaky.ipynb

verdict: 1 high, 0 medium | static layer (no LLM)

## HIGH: leakage-fit-before-split
- **Where:** cell 5, line 2
- **Evidence:** `scaler.fit_transform(...)` consumes X, feeding `train_test_split` (cell 5) — the fit happened before the split
- **Flaw:** A transformation (scaler, imputer, encoder, feature selector, PCA, vectorizer) is fitted on data that contains the test set.
- **Failure scenario:** Test metrics are inflated; the production model will underperform the reported numbers.
- **Fix:** Fit the transformer on the training split only; apply transform to the test split.
- **Confidence:** 0.92

## CLEAN (checked): baserate-accuracy-imbalanced, leakage-temporal-shuffle, testing-multiple-uncorrected
Exit codes: 0 clean, 1 medium findings, 2 high findings, 3 input
error. Usable as a pre-merge gate.
examples/temporal-cv-before-after.ipynb
shows the effect on a metric: the same model scored with shuffled CV and
with TimeSeriesSplit, numbers computed in the notebook
(run record:
evals/2026-10-12-temporal-cv-demo.md).
Status
| What | |
|---|---|
| Available now | waldean check on .ipynb and .py (plain and # %%); four static flaw classes (below); a survivorship candidate; Markdown, JSON and SARIF output; GitHub Action; pre-commit hooks; waldean rules; waldean eval --predictions for scoring other tools on the corpus |
| Experimental | --llm / --llm-subscription narrative layer (prose claims vs computation). No validated precision or recall; its quality gates never ran |
| Planned | Generated fixes: a reviewable patch plus a verification recipe for one canonical leakage shape (waldean propose), then opt-in sandboxed verification. Not shipped |
Tested on Python 3.10 to 3.13 (Linux CI; unit tests also on Windows).
Rules
| Flaw class | What triggers it |
|---|---|
leakage-fit-before-split |
A scaler, imputer, encoder, selector or vectorizer is fitted on data that later feeds train_test_split or cross-validation |
leakage-temporal-shuffle |
Lag or rolling features on time-ordered data, evaluated with a shuffled split instead of TimeSeriesSplit or a time cutoff |
testing-multiple-uncorrected |
Many statistical tests with no multiple-comparison correction; reports the implied family-wise error rate |
baserate-accuracy-imbalanced |
Accuracy as the only metric while stored outputs show class imbalance |
selection-survivorship-cohort |
Candidate only: a filter on a survival-correlated column before aggregation |
waldean rules prints the full list from waldean/taxonomy/flaws.yaml.
Known limitations
- On 60 fresh GitHub notebooks, 25 of 28 flags were real (0.89 precision)
and Waldean caught 12 of 20 leaky notebooks in the audited subset (0.60
recall; audited subset, one seed, likely lower over all 60). That
evidence covers the two leakage classes only
(
evals/2026-07-07-dogfood-wide.md). - On the 100 labeled notebooks of Yang et al. (ASE'22),
leakage-fit-before-splitreached 0.58 precision and 0.37 recall against the authors'prelabel (evals/2026-10-12-yang-pre.md). - Misses cluster in pandas-arithmetic leaks with no syntactic anchor
(per-group imputation,
fillna(df[col].mean())before the split), and in named transformers whose fit Waldean does not connect tocross_val_scoreor that are fit on a whole text corpus. - The 0.0% false-positive rate holds on the curated corpus, not on messy real code.
- Flaws with no imprint in code, outputs or prose are invisible to Waldean.
- Waldean never executes your notebook.
Full evaluation, corpus method and dogfood history:
docs/EVALUATION.md.
How Waldean is measured
Detectors are scored by mutation testing: clean notebooks get flaws
injected, and every mutant must mechanically prove the flaw before it
counts. Corpus tables, dogfood runs and detector scope:
docs/EVALUATION.md.
GitHub Action
Wake360/waldean@v0.4.0 is a composite action that installs waldean, runs
waldean check on the paths you pass, writes a SARIF 2.1.0 log, and reports a
gate-exit-code mapped through fail-on (high, medium, or never). The
action never fails the job itself — it exposes the code and lets your
workflow upload SARIF before gating, so findings show up as inline PR
annotations even on a red run. The consumer must grant security-events: write for the SARIF upload, put Python >= 3.10 on PATH (via
actions/setup-python), and run on a Linux or macOS runner (the steps are
bash).
name: waldean
on: [pull_request]

jobs:
  check-notebooks:
    runs-on: ubuntu-latest
    permissions:
      contents: read
      security-events: write
    steps:
      - uses: actions/checkout@v4
        with:
          fetch-depth: 0

      - uses: actions/setup-python@v5
        with:
          python-version: "3.13"

      - name: Find changed notebooks
        id: changed
        run: |
          files=$(git diff --name-only \
            origin/${{ github.base_ref }}...${{ github.sha }} -- '*.ipynb')
          echo "files=$files" >> "$GITHUB_OUTPUT"

      - name: waldean
        id: waldean
        if: steps.changed.outputs.files != ''
        uses: Wake360/waldean@v0.4.0
        with:
          paths: ${{ steps.changed.outputs.files }}
          fail-on: high

      - name: Upload SARIF
        if: always() && steps.changed.outputs.files != ''
        uses: github/codeql-action/upload-sarif@v3
        with:
          sarif_file: ${{ steps.waldean.outputs.sarif-file }}

      - name: Gate on waldean
        if: steps.changed.outputs.files != ''
        run: exit ${{ steps.waldean.outputs.gate-exit-code }}
Pre-commit
.pre-commit-hooks.yaml ships two hooks: waldean for .ipynb files,
waldean-scripts for .py files.
repos:
  - repo: https://github.com/Wake360/waldean
    rev: v0.4.0
    hooks:
      - id: waldean
      - id: waldean-scripts
pre-commit fails the hook on any nonzero exit, so both exit 1 (a medium
finding) and exit 2 (a high finding) block the commit — raise --floor
via args if you want fewer low-confidence findings to count as
confident. waldean-scripts runs on every changed .py file, so if your
repo has many non-analysis scripts, scope it with files:/exclude:
in your own pre-commit config.
Architecture
notebook ──> ingest (nbformat) ──> layer A: static detectors ──> report
                                    - libcst def-use dataflow      md / json
                                    - deterministic, key-free      exit code
                                    - exact cell:line + evidence

             layer B (--llm): LLM narrative detector
             claims <-> computation consistency, closed taxonomy,
             span-grounded, verified by a second provider; fuses with
             layer A candidates (filter + population claim = flag)
The hybrid split is the point: leakage is an AST pattern — an LLM has no business there. The LLM layer handles only what statics cannot: whether the prose claims match what the code computes. Its quality gates (G2/G3) never ran, so no narrative-layer numbers are claimed; the static linter is the validated product.
The narrative layer runs through the claude/codex CLIs on
subscription billing: waldean check --llm --llm-subscription <notebook>.
Its numbers are dev-split and indicative by construction
(gate_evidence: false); it has not passed a quality gate. An
indicative dev-split run is at
evals/2026-07-25-llm-eval-dev-subscription-indicative-rerun.md —
unpinned models, not reproducible (the prior 2026-07-09 run lost 17/45
files to backend errors; the rerun after hook isolation completed all
files). Static-only is the default; without --llm, Waldean calls no LLM.
Taxonomy is data (flaws.yaml): 9 flaw classes with definition, book
anchor, mutation recipe and severity (waldean rules lists them). Adding a
class = a record + a detector + a mutation; prompts and reports generate
from the same file, so documentation and detector cannot drift.
Install & use
pip install waldean
waldean check notebook.ipynb            # exit 0 clean / 1 medium / 2 high / 3 input or usage error
waldean check analysis.py               # plain script, or percent-format (# %% cell markers)
waldean check notebooks/ --keep-going   # continue past unreadable files; exit 3 if any file failed
waldean rules                           # list the flaw classes waldean checks; --format json for machines
Contributing to Waldean itself:
python -m venv .venv && source .venv/bin/activate
pip install -e ".[corpus,dev]"       # or: uv sync --all-extras

waldean check examples/leaky.ipynb      # exit 0 clean / 1 medium / 2 high / 3 input or usage error
waldean check examples/leaky.ipynb --format json   # one object; a JSON array for multiple notebooks
waldean corpus build                    # build clean corpus + verified mutants
waldean eval                            # confusion matrix -> evals/<date>-eval.md
pytest                               # unit tests + golden gates G0/G1
examples/leaky.ipynb ships in the repo and reproduces the report shown
at the top of this file. examples/leaky.py is the same analysis as a
percent-format script.
Directory arguments still collect only *.ipynb; pass a .py file
explicitly. Reported lines for .py input are file-absolute (not
relative to the cell); the markdown report keeps cell N, line M, where
N is the percent-cell's ordinal position in the file.
By default waldean check aborts on the first unreadable file. --keep-going
continues instead: each unreadable file is reported to stderr and the run
still exits 3 if any file failed — even alongside a high-severity finding
elsewhere in the batch, which would otherwise exit 2. The multi-file TTY
summary line gains a , N failed suffix.
waldean rules lists the flaw classes from the taxonomy (id, layer, severity,
definition); --format json emits the same data as a JSON array.
Waldean never executes your notebook (static analysis + stored outputs only). Only self-authored corpus notebooks are executed, at corpus build time, to verify mutations.
Roadmap
- M2 — LLM narrative layer + cross-provider verifier + fusion: built,
tested against replay fixtures (
plans/m2.md), and runs on subscription CLIs (waldean check --llm --llm-subscription). The G2/G3 gates never ran; narrative numbers stay dev-split and indicative (gate_evidence: false). - M3 — table consistency checks (cohort sums vs. declared population).
- Benchmark — the corpus is scoreable by external tools:
waldean eval --predictions(docs/benchmark.md). - M4 — GitHub Action with PR annotations: shipped in 0.2.1
(
action.yml). Severity calibration stays parked until flag volume exists. (Dogfood on real licensed notebooks: done,evals/2026-07-04-dogfood.md.) - Corpus contributions welcome: see
CONTRIBUTING.mdfor the clean-corpus criteria, real-notebook licensing rules, and the flaw-class contribution shape (taxonomy record, detector, mutation with mechanicalverify()).
License
MIT.
1 maintainer

Metadata
1 maintainer
Release files for waldean 0.4.0
For a detailed explanation of source distributions (sdists) and built distributions (wheels), please see the package formats documentation.
Source distribution (sdist)
| File | Size | Uploaded | |
|---|---|---|---|
| waldean-0.4.0.tar.gz | 107.4 kB | Details |
Built distribution (wheel)
| File | Interpreter | ABI | Platform | Reset |
|---|---|---|---|---|
| waldean-0.4.0-py3-none-any.whl | Python 3 | none | any | Details |
Total release size: 179.1 kB
Release files / waldean-0.4.0.tar.gz
| Download URL | waldean-0.4.0.tar.gz |
|---|---|
| Size | 107.4 kB |
| Tags | Source |
|
SHA-256 checksum How to use checksums |
f712738050a92a5c000e606f58507e298020d24325e56367fa08f2033deb49d2
|
|
BLAKE2b-256 checksum How to use checksums |
c02497d0f750319f3902f9deb01ce7308dbea75afd403e7f0ee4e9db070d2295
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
Yes |
| Uploaded via |
twine/7.0.0 CPython/3.13.14
|
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.


PyPI Publish Attestation
PyPI verified that this artifact, at this checksum, originated from the publisher listed below.
Signed by GitHub Actions, verified by PyPI on Oct 12, 2026.
Transparency logRelease files / waldean-0.4.0-py3-none-any.whl
| Download URL | waldean-0.4.0-py3-none-any.whl |
|---|---|
| Size | 71.7 kB |
| Tags | Python 3 |
|
SHA-256 checksum How to use checksums |
732bedf994f65906993bd1efa753728b311346f5661f92d1c8d7579cc0f9d458
|
|
BLAKE2b-256 checksum How to use checksums |
8c3275b82320e1d31bb2e9f2cc4d2265edaa2aab0dc273a931341b8836c90076
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
Yes |
| Uploaded via |
twine/7.0.0 CPython/3.13.14
|
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.
PyPI Publish Attestation
PyPI verified that this artifact, at this checksum, originated from the publisher listed below.
Signed by GitHub Actions, verified by PyPI on Oct 12, 2026.
Transparency log












