



Find the tokens your AI agent wasted — in dollars, with the fix — and fail the PR when a change makes your agent more expensive.
Wattage reads the traces and session logs your agents already produce — your local Claude Code sessions, or any OpenTelemetry GenAI trace export — prices every call against a verified, dated pricing snapshot (52 models across Anthropic, OpenAI, Google, Mistral, and xAI), runs ten waste-pattern detectors that each name a dollar figure and a concrete fix, and ships the one thing no dashboard gives you: a CI cost-regression gate that fails the build when an agent quietly gets more expensive. Fully offline, no API key, nothing phones home.
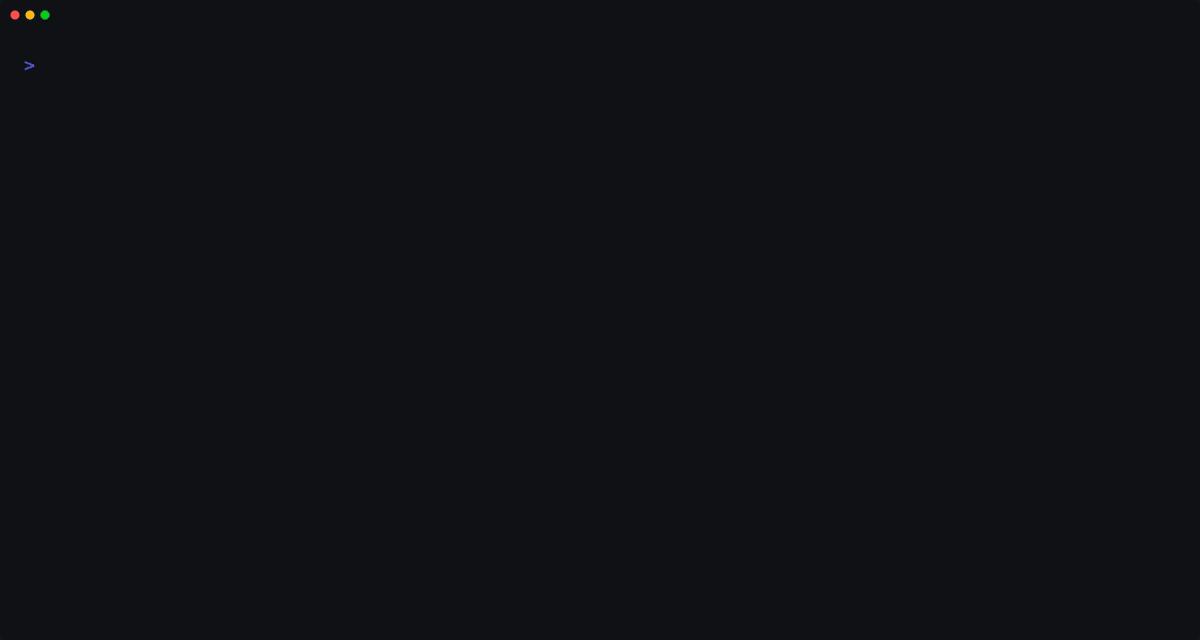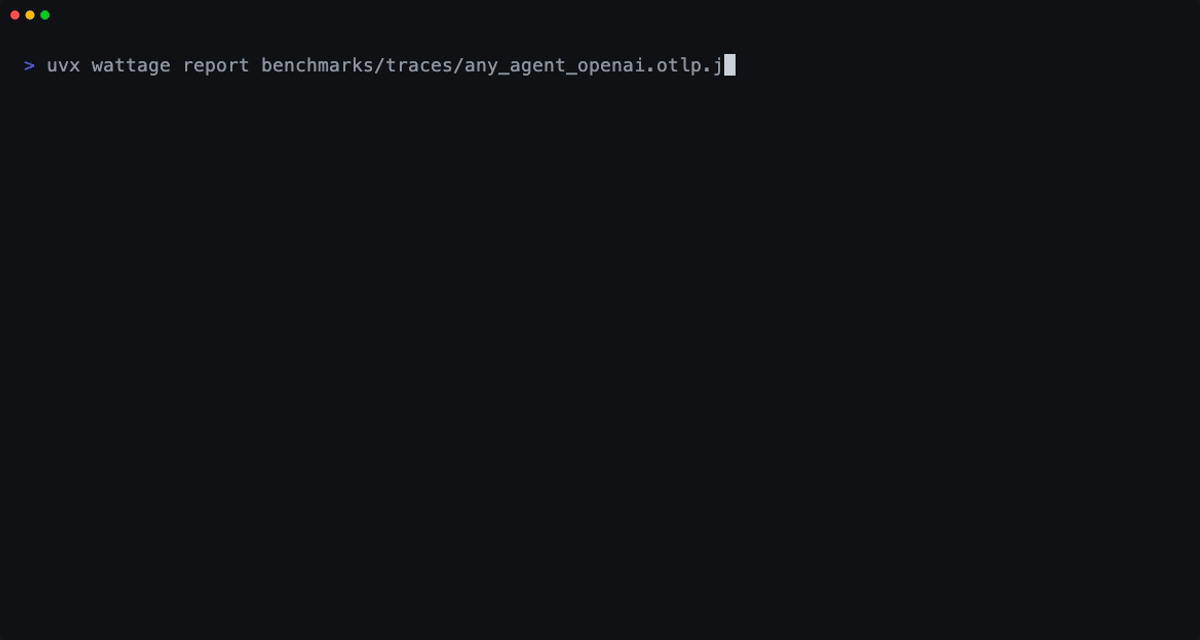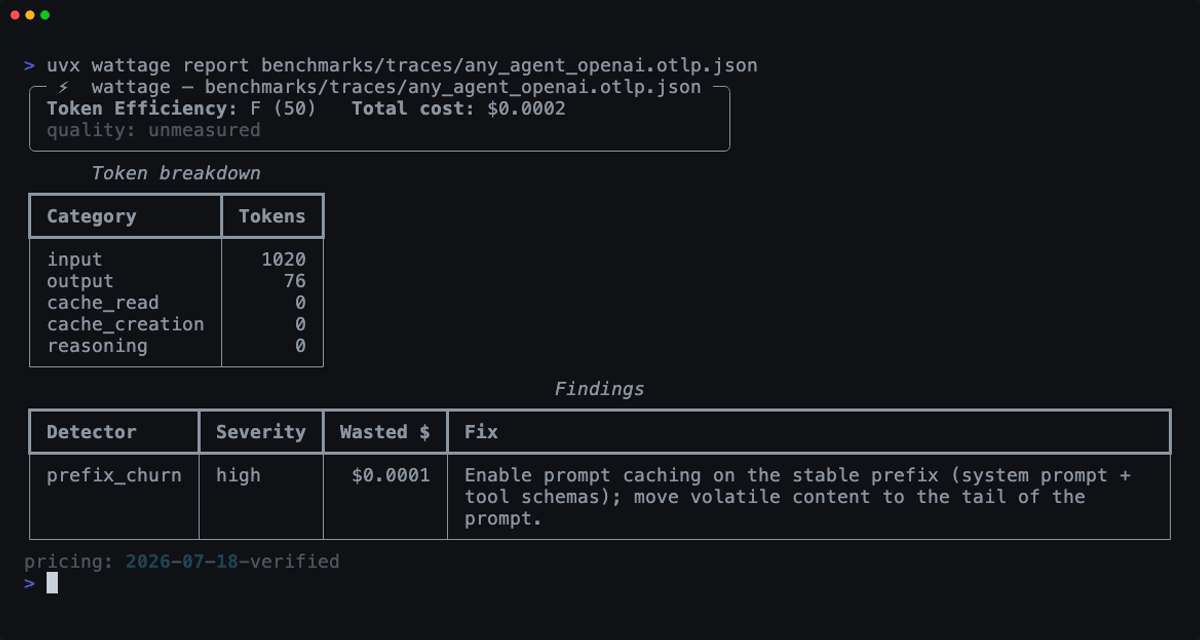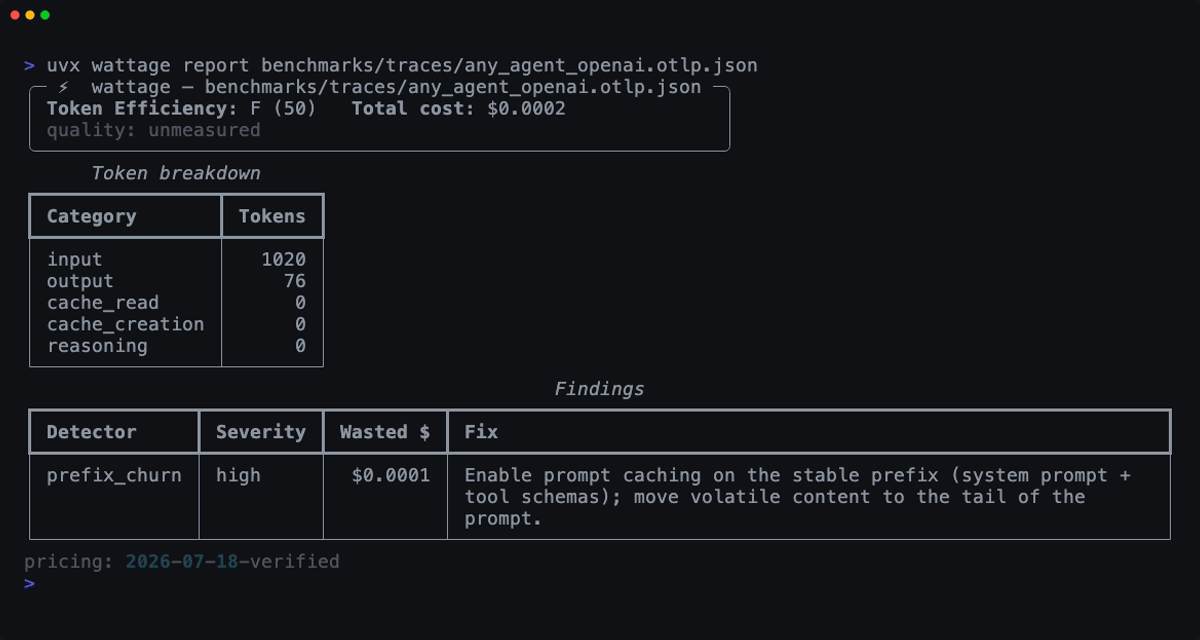
Real output of uvx wattage demo — regenerate this GIF with vhs docs/assets/demo.tape.
30 seconds to your first report
uvx wattage demo                    # findings-rich sample report, zero setup
uvx wattage report --claude-code    # your latest Claude Code session — data you already have
uvx wattage report trace.json       # any OTLP GenAI trace export
The demo trace is a deliberately wasteful synthetic agent — here's what Wattage does to it (abridged; every number below is the command's real output):
╭─ ⚡ wattage — demo_trace.json ─────────────────────╮
│ Token Efficiency: D (67)   Total cost: $0.0557    │
╰───────────────────────────────────────────────────╯
┃ Detector             ┃ Severity ┃  Wasted $ ┃ Fix                                        ┃
│ nonconvergence       │ critical │   $0.0037 │ Add a convergence stop after repeated      │
│                      │          │           │ non-productive iterations…                 │
│ prefix_churn         │ high     │   $0.0123 │ Enable prompt caching on the stable prefix │
│                      │          │           │ (system prompt + tool schemas)…            │
│ cache_gap            │ high     │   $0.0001 │ Move volatile fields after the cache       │
│                      │          │           │ breakpoint…                                │
│ reasoning_overspend  │ medium   │  ~$0.0060 │ Lower reasoning_effort (or disable         │
│                      │          │           │ extended thinking) for this step.          │
measured waste: $0.0187 (counts toward the grade) · estimated (~) findings: $0.0065 (reported, never graded)
Prefer a visual? --html writes a self-contained, shareable burn map —
an interactive flame graph of every token, with a stat strip and findings
that light up the exact frames that burned the money:
uvx wattage report --claude-code --html burn.html
Fail the PR when your agent gets more expensive
This is the part no other open-source tool ships: a cost-regression gate over real measured traces (not tokenized prompt-diff predictions), with a committed baseline that only advances on passing runs.
# .github/workflows/wattage.yml
name: Wattage
on:
  pull_request:
    paths: ["agents/**", "prompts/**", "src/**"]
permissions:
  pull-requests: write   # for the sticky PR comment (report still lands in the step summary without it)
concurrency:
  group: wattage-${{ github.ref }}
  cancel-in-progress: true
jobs:
  token-efficiency:
    runs-on: ubuntu-latest
    steps:
      - uses: actions/checkout@v4
      - name: Generate trace fixture
        run: python scripts/run_agent_fixture.py > trace.json   # replace with whatever produces a trace for YOUR agent
      - name: Wattage cost-regression gate
        uses: faizannraza/wattage@v0.2.0
        with:
          source: trace.json
          baseline: .wattage/baseline.json
          fail-on: "score_below:80,cost_delta_pct_above:5,any_critical:true"
          pr-comment: "true"
Fails the build (exit 1) on a regression, posts one sticky PR comment
with a per-detector delta table (updated in place on every push, never
spammed), writes the report to the job's step summary, and emits SARIF and
JUnit XML for any other CI system. any_critical is a hard stop for
runaway loops: a non-convergent loop that burned half its own spend after
its last productive step escalates to critical severity. One more workflow
(runs on merge, keeps the committed baseline fresh) completes the setup —
copy-paste pair in CI Integration.
What it is — and what it isn't
Wattage is diagnosis + prescription + gate, not another dashboard. It consumes the traces your existing tools already produce; it replaces none of them.
| Wattage | ccusage / spend counters | Langfuse / Helicone / dashboards | tokencost | promptfoo | |
|---|---|---|---|---|---|
| Prices calls from a trace | ✅ | ✅ (totals) | ✅ | pricing lookup only | per-call |
| Names the waste pattern + a fix | ✅ 10 detectors | — | — | — | — |
| Fails a PR on measured cost regression | ✅ | — | — | — | per-call threshold only |
| Live dashboard / runtime proxy | — | — | ✅ | — | — |
Who it's for: teams shipping LLM agents who've been surprised by a bill. You have (or can get) a trace — a Claude Code session on your laptop already counts — you review PRs, and you want "did this change make the agent more expensive?" answered automatically, in CI, for free.
Works with
- Claude Code / Claude Agent SDK sessions — reads the session
.jsonlfiles under~/.claude/projectsdirectly, validated against real sessions. Includes the 5-minute/1-hour cache-write TTL split, so 1-hour cache writes price at their real 2x rate (a distinction the OTel format can't even express). Costs are standard API rates — for subscription users that's the API-equivalent value of the session, and the report says so. - OpenTelemetry GenAI semconv traces — every attribute generation ever
shipped: current names (
gen_ai.provider.name,gen_ai.usage.input_tokens), the pre-v1.37/v1.27 names most deployed instrumentation still emits (gen_ai.system,gen_ai.usage.prompt_tokens), OpenLLMetry/Traceloop variants, and OpenInferencellm.*attributes (the default instrumentation for OpenAI Agents SDK, CrewAI, and LangGraph via Arize). Single-object OTLP JSON and spec-standard JSON Lines (what the OTel Collector file exporter actually writes), camelCase or snake_case. - mozilla-ai/any-agent —
validated against a real captured trace (provenance),
including LiteLLM-style
"provider/model"strings.
The format is auto-detected — wattage report <file> just works. Full
matrix and honesty notes: Adapters.
The ten detectors
| Detector | Catches |
|---|---|
prefix_churn |
Stable context re-sent instead of cached |
cache_gap |
Caching attempted but under-redeemed by later reads |
nonconvergence |
Loops that thrash, oscillate, or stall without progress |
retry_storm |
The same request re-sent back-to-back — a retry loop billing the full prompt every attempt |
tool_result_bloat |
Oversized tool results re-fed into every later call's context |
verbosity |
Output far beyond what the step needed |
redundant_tool_calls |
The same tool call repeated (exact or fuzzy) |
retrieval_thrash |
Repeated retrieval that never yields new evidence |
model_mismatch |
A pricier model doing work a cheaper one could handle |
reasoning_overspend |
Heavy reasoning-token spend on a simple step |
Every finding is priced, comes with a concrete fix, and carries two honesty
labels. A basis: measured findings (real billed tokens at the real
rate card) drive the grade and the CI gate; estimated findings (chars÷4
projections, policy ceilings, hypothetical downgrades) are reported with a
~ and can never fail a build. And a quality risk: a fix that could
plausibly change output quality (a model downgrade, less reasoning) only
counts once a --quality map backs it with real evidence. Full detail:
Detectors.
Honest numbers, structurally
- An unpriced model leaves that call's cost at zero and fails
wattage ciloudly (exit 4) — never a guessed rate. - A trace with zero captured usage refuses to grade instead of printing a vacuous A (100).
- Dropped or duplicated spans are counted and reported, never silently swallowed.
- The pricing snapshot is dated and source-cited
(
2026-08-23-verified, every number from the provider's own pricing page), context-tier aware (Gemini/Grok reprice whole requests above 200k prompt tokens), and effective-date aware (promo rates that expire price by the call's own timestamp). A published-but-rateless range (OpenAI above 272K context) is left unpriced, not billed at the wrong tier.
Benchmarked, reproducibly
On a real captured agent trace, Wattage's prefix_churn fix simulation
shows a 44.7% cost reduction ($0.000199 → $0.000110) from enabling
prompt caching on the stable prefix — small absolute dollars because it's a
3-turn demo trace; the mechanism is identical at production scale.
The convergence engine's classifier scores 1.00 F1 vs 0.25 for a real SHA-256 exact-match baseline on a 10-loop hand-labeled suite. Read that number for what it is: the suite is small, written by us, and deliberately constructed to demonstrate the blind spots exact-match loop guards structurally cannot see (fresh timestamps every retry, oscillating strategies, productive-looking stalls) — it's a blind-spot demonstration and regression suite, not a field study. Both numbers reproduce from the shipped code with no hidden setup:
uv run python -m benchmarks.harness
uv run python -c "from benchmarks.frontier import build_frontier; print(build_frontier())"
Full methodology, including what the benchmark does not show: The Convergence Engine.
The badge
uvx wattage badge trace.json --out wattage-badge.svg
[](https://github.com/faizannraza/wattage)
Wire --badge-out into the post-merge CI job and your README carries a
live, provable claim that your agent is efficient.
Contributing
Detectors are discovered through a Python entry-point group, so adding one
doesn't require touching this repo's core pipeline — see
CONTRIBUTING.md for the full "write a detector" walkthrough,
using cache_gap as the reference
example.
If Wattage found real waste in your traces, a star helps other teams find it — and tells us which parts of the roadmap (Langfuse export adapter, live OTLP tail, runtime loop guard) to build first.
License
1 maintainer

Metadata
1 maintainer
Release files for wattage 0.2.0
For a detailed explanation of source distributions (sdists) and built distributions (wheels), please see the package formats documentation.
Source distribution (sdist)
| File | Size | Uploaded | Provenance | |
|---|---|---|---|---|
| wattage-0.2.0.tar.gz | 984.8 kB | Without provenance | Details |
Built distribution (wheel)
| File | Interpreter | ABI | Platform | Reset |
|---|---|---|---|---|
| wattage-0.2.0-py3-none-any.whl | Python 3 | none | any | Details |
Total release size: 1.1 MB
Release files / wattage-0.2.0.tar.gz
| Download URL | wattage-0.2.0.tar.gz |
|---|---|
| Size | 984.8 kB |
| Tags | Source |
|
SHA-256 checksum How to use checksums |
17b2b3f33feeb1b95e810e49dcdebd92d415f5daebbfad735456c6b7574c1e0b
|
|
BLAKE2b-256 checksum How to use checksums |
d55757d8b7f43b5505ecf03383559c5f58b5c6cc831bdc6a5d3336880bc8ab91
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
No |
| Uploaded via |
uv/0.11.29 {"installer":{"name":"uv","version":"0.11.29","subcommand":["publish"]},"python":null,"implementation":{"name":null,"version":null},"distro":{"name":"macOS","version":null,"id":null,"libc":null},"system":{"name":null,"release":null},"cpu":null,"openssl_version":null,"setuptools_version":null,"rustc_version":null,"ci":null}
|
Release files / wattage-0.2.0-py3-none-any.whl
| Download URL | wattage-0.2.0-py3-none-any.whl |
|---|---|
| Size | 122.6 kB |
| Tags | Python 3 |
|
SHA-256 checksum How to use checksums |
d4c3d751a5206ce93a9a88e86f5da66ebd809404f2cbd64d59e3705e56a3141d
|
|
BLAKE2b-256 checksum How to use checksums |
611b302c93609a2a6627336dcf3d4e9defea04e05da54fa5b4698f3bf29ab33d
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
No |
| Uploaded via |
uv/0.11.29 {"installer":{"name":"uv","version":"0.11.29","subcommand":["publish"]},"python":null,"implementation":{"name":null,"version":null},"distro":{"name":"macOS","version":null,"id":null,"libc":null},"system":{"name":null,"release":null},"cpu":null,"openssl_version":null,"setuptools_version":null,"rustc_version":null,"ci":null}
|
Security for wattage 0.2.0
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.
No provenance found
None of the files in this release were uploaded with provenance metadata.
A note on package security
PyPI is a repository for distributing packages, not a service for auditing them. While third-party security researchers and our staff do their best to detect and remove malicious packages, PyPI cannot guarantee the quality, security or suitability of any given package.
To learn more about protecting yourself from malicious actors, visit our package security documentation.














