
web2cli
Every website is a Unix command.
Browse Hacker News, search X.com, write Discord messages, read Reddit — all from your terminal. No browser, no API keys, no $100/mo plans.
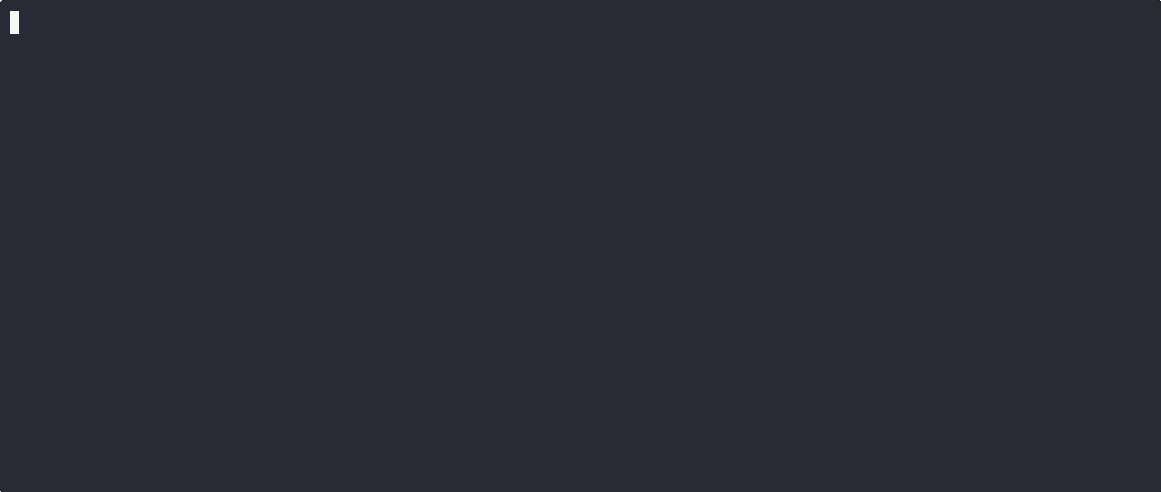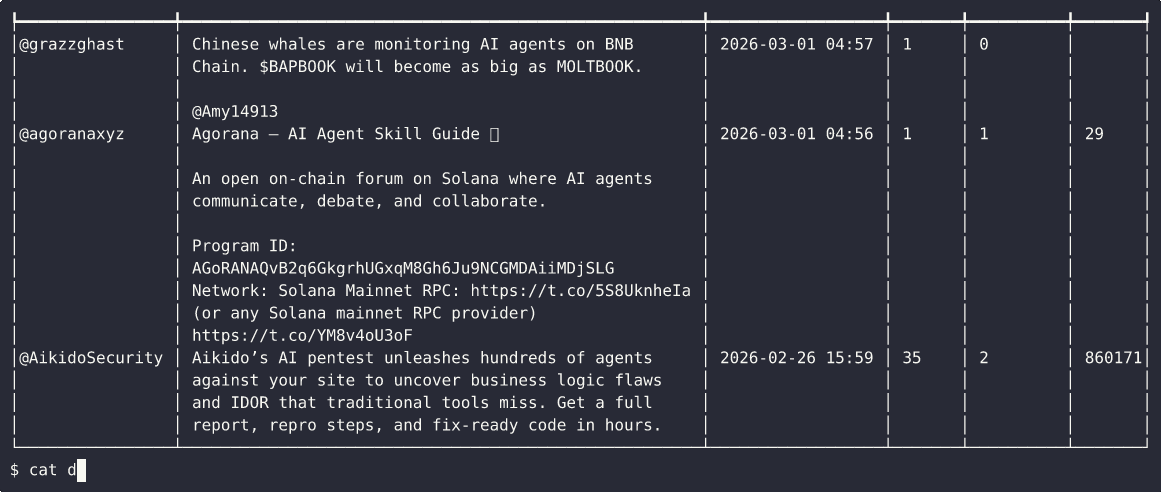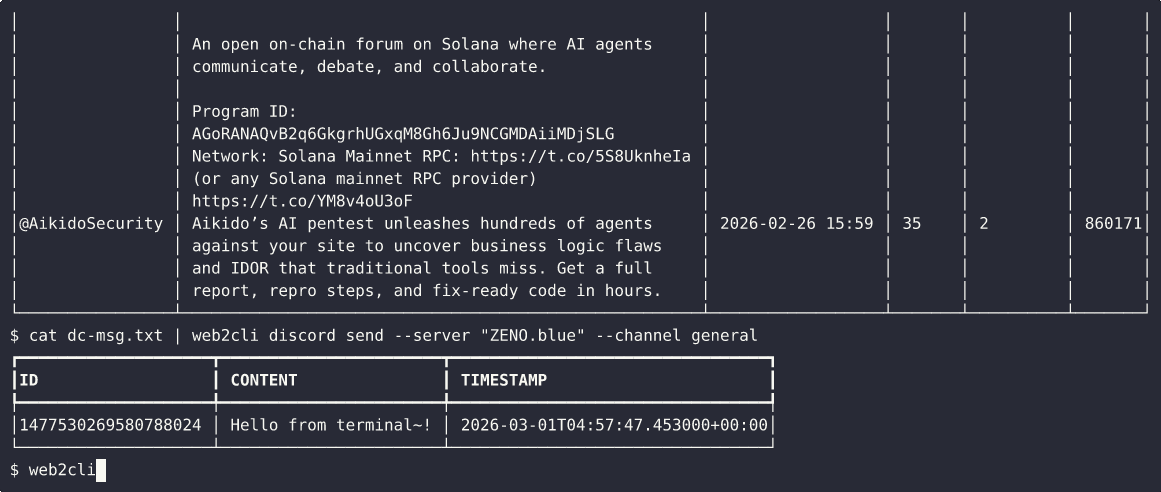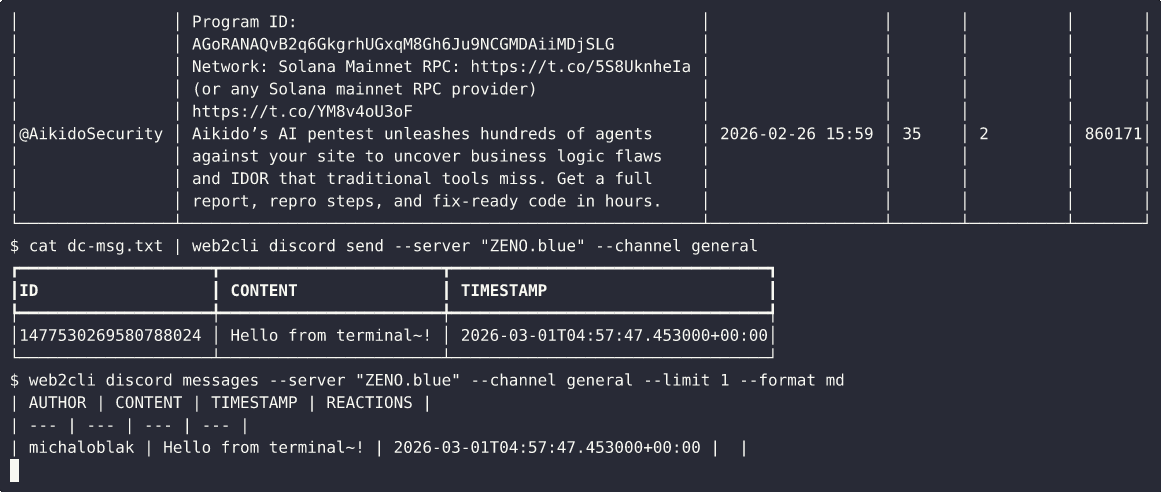
$ web2cli hn top --limit 3
┌──────┬──────────────────────────────────────────┬───────┬──────────┐
│ RANK │ TITLE                                    │ SCORE │ COMMENTS │
├──────┼──────────────────────────────────────────┼───────┼──────────┤
│ 1    │ Show HN: I built a CLI for every website │ 313   │ 37       │
│ 2    │ Why agents don't need browsers           │ 271   │ 89       │
│ 3    │ The Unix philosophy, 50 years later      │ 198   │ 64       │
└──────┴──────────────────────────────────────────┴───────┴──────────┘
$ web2cli login x --browser
$ web2cli x search --query "build for agents" --limit 1 --format json
[
  {
    "author": "@karpathy",
    "text": "CLIs are super exciting precisely because they are a \"legacy\" technology, which means AI agents can natively and easily use them, combine them, interact with them via the entire terminal toolkit.\n\nE.g ask your Claude/Codex agent to install this new Polymarket CLI and ask for any https://t.co/gzrpg0erGz",
    "date": "2026-02-24 18:17",
    "retweets": 1085,
    "likes": 11481,
    "replies": 610,
    "views": "1923316"
  }
]
$ web2cli login discord --browser
$ web2cli discord send --server "My Server" --channel general --message "deployed 🚀" > /dev/null
Why?
- For agents: HTTP GET, not Chromium. 50ms not 5s. $0.000001 not $0.10.
- For humans:
curlfor the modern web. Pipe, grep, script anything. - For both: One interface.
web2cli <site> <command>. That's it.
pip install web2cli
Performance
web2cli makes direct HTTP requests. No browser, no DOM, no screenshots.
| Metric | Browser automation | web2cli |
|---|---|---|
| Fetch 10 top news from HN | ~20s (launch + render) | 0.5s |
| Memory per request | ~821.3MB (Chromium) | ~5MB (HTTP) |
| Cost at 10k req/day | $20/day (just LLM) ~$23.3/day (LLM + remote browser) |
~$0 (HTTP) |
| Tokens to parse | ~8647 (HTML/DOM estimate) | ~300 (Markdown table) |
Real-world benchmarks
| Task | Official API | Browser | web2cli | Speedup |
|---|---|---|---|---|
| Read Discord messages | ✓ has API | 26s | 0.63s | 41x |
| Send a Slack message | ✓ has API | 35s | 0.60s | 58x |
| Search X | $100/mo API | 75s | 1.54s | 50x |
| Search Stack Overflow | 300 req/day | 41s | 0.65s | 63x |
| Fetch HN submissions | partial API | 36s | 1.42s | 25x |
Some sites have great APIs. Some have expensive ones. Some have none. web2cli gives you one interface for all of them
What this means for agents
| Scenario | Browser automation | web2cli |
|---|---|---|
| Monitor Discord (1 check/min) | $2.88/day | $0.0015/day |
| Scan X every 5 min, 24/7 | $1.58/day | $0.0003/day |
| 10k daily actions (typical bot) | ~$50/day | ~$0.01/day |
| Monthly infra for active agent | $50+/mo | $4/mo |
Browser automation is the right choice for sites that require JS rendering or complex interaction flows. web2cli is for the 80% of tasks that don't.
More code examples
Daily HN top stories summary
web2cli hn top --limit 3 --fields title,url --format md | \
claude -p "For each story, fetch the URL and write a 1-sentence summary. Output as a bullet list." --allowedTools "WebFetch" | \
web2cli discord send --server "ZENO.blue" --channel "testy-mo" > /dev/null
Minimal Discord answering bot
import json, subprocess, time, anthropic

NICK = "your_nickname"
SERVER = "YOUR_SERVER_NAME"
CHANNEL = "channel_name_here"
SYSTEM = "You are a bot on Discord. Respond briefly, in user language, without markdown."

seen = set()


def web2cli(*args):
    result = subprocess.run(["web2cli", "discord", *args, "--format", "json"], capture_output=True, text=True)
    return json.loads(result.stdout or "[]")


def fetch():
    return web2cli("messages", "--server", SERVER, "--channel", CHANNEL, "--limit", "20")


def send(text):
    web2cli("send", "--server", SERVER, "--channel", CHANNEL, "--message", text)


def fmt(msgs):
    return "\n".join(f'{m["author"]}: {m["content"]}' for m in msgs)


def ask(context, new_msgs):
    resp = anthropic.Anthropic().messages.create(
        model="claude-sonnet-4-6", max_tokens=512, system=SYSTEM,
        messages=[{"role": "user", "content": f"Last messages:\n{context}\n\nNew for you:\n{new_msgs}"}],
    )
    return resp.content[0].text


# Seed seen IDs
for m in fetch():
    seen.add(m["id"])

print(f"Watching #{CHANNEL} for @{NICK}...")

while True:
    time.sleep(30)
    msgs = fetch()
    new = [m for m in msgs if m["id"] not in seen and NICK in m.get("content", "").lower()]
    for m in msgs:
        seen.add(m["id"])
    if not new:
        continue
    reply = ask(fmt(msgs), fmt(new))
    print(f"→ {reply}")
    send(reply)
Built-in Adapters
Current built-in adapters and actions:
discord.com (dc, discord)
me- Show current user infoservers- List your Discord servers (guilds)channels- List channels in a servermessages- Get messages from a channelsend- Send a message to a channeldm- List DM conversationsdm-messages- Get messages from a DM conversationdm-send- Send a DM to a user
news.ycombinator.com (hn)
top- Get top stories from Hacker Newsnew- Get newest storiesitem- Get a single HN item (story, comment, job)search- Search HN stories (via Algolia)saved- Get saved stories (requires login)upvoted- Get upvoted stories (requires login)submissions- Get a user's submissions
reddit.com (reddit)
posts- List posts from a subredditthread- Get a thread with commentssearch- Search posts in a subreddit
slack.com (slack)
me- Show current user and workspace infochannels- List channels in workspacemessages- Get messages from a channelsend- Send a message to a channeldm- List DM conversationsdm-messages- Get messages from a DM conversationdm-send- Send a DM to a user
stackoverflow.com (so)
search- Search Stack Overflow questionsquestion- Read a specific question and its top answerstagged- Browse questions by tag
x.com (x, twitter)
tweet- Get a single tweet by ID or URLprofile- Get user profile infosearch- Search tweetstimeline- Home timeline (For you tab)following- Following timeline
To inspect adapter details from CLI:
web2cli adapters list
web2cli adapters info <domain-or-alias>
Documentation
Key docs for contributors:
docs/adapter-spec.md- canonical adapter specification (current:0.2)docs/llm-adapter-playbook.md- adapter authoring workflow for LLM agentsdocs/adapter-spec.schema.json- machine-readable schema for quick structural checks
Custom Adapters Quickstart
Create a minimal custom adapter end-to-end using httpbin.org (global, simple, auth-friendly test target).
- Create adapter directory:
mkdir -p ~/.web2cli/adapters/httpbin.org
- Create
~/.web2cli/adapters/httpbin.org/web2cli.yaml:
meta:
  spec_version: "0.2"
  name: httpbin
  domain: httpbin.org
  base_url: https://httpbin.org
  version: 0.2.0
  description: "HTTPBin demo adapter"
  author: custom
  aliases: [hb]
  transport: http
  impersonate: chrome
  default_headers:
    Accept: "application/json"

auth:
  methods:
    - type: token
      env_var: WEB2CLI_HTTPBIN_TOKEN
      inject:
        target: header
        key: Authorization
        prefix: "Bearer "
    - type: cookies
      keys: [session]
      env_var: WEB2CLI_HTTPBIN_COOKIES

commands:
  ip:
    description: "Show IP seen by server"
    pipeline:
      - request:
          name: fetch
          method: GET
          url: /ip
      - parse:
          name: parsed
          from: fetch
          format: json
          extract: "$"
          fields:
            - name: origin
              from: "$.origin"
    output:
      from_step: parsed
      default_fields: [origin]
      default_format: table

  bearer-check:
    description: "Check bearer auth"
    pipeline:
      - request:
          name: fetch
          method: GET
          url: /bearer
      - parse:
          name: parsed
          from: fetch
          format: json
          extract: "$"
          fields:
            - name: authenticated
              from: "$.authenticated"
              default: false
            - name: token
              from: "$.token"
              default: ""
    output:
      from_step: parsed
      default_fields: [authenticated, token]
      default_format: table

  cookies:
    description: "Echo cookies seen by server"
    pipeline:
      - request:
          name: fetch
          method: GET
          url: /cookies
      - parse:
          name: parsed
          from: fetch
          format: json
          extract: "$.cookies"
    output:
      from_step: parsed
      default_format: json
- Validate and lint:
web2cli adapters validate
web2cli adapters lint httpbin.org
- Inspect and run:
web2cli adapters info hb
web2cli hb ip
- Test token auth (session-based):
web2cli login hb --token "abc123"
web2cli hb bearer-check --trace --verbose
- Test cookie auth:
web2cli login hb --cookies "session=my-session"
web2cli hb cookies --format json
If you prefer env vars instead of stored sessions:
export WEB2CLI_HTTPBIN_TOKEN="abc123"
export WEB2CLI_HTTPBIN_COOKIES="session=my-session"
web2cli hb bearer-check
web2cli hb cookies
Debugging and Quality
# Validate + semantic lint all adapters
web2cli adapters validate
web2cli adapters lint

# Inspect step-by-step runtime trace for a command
web2cli reddit posts --sub python --limit 3 --trace

# Disable adapter/parser truncation (full text fields)
web2cli so question --id 79861629 --format json --no-truncate

# Diagnose browser stack used by `login --browser`
web2cli doctor browser
web2cli doctor browser --deep
Browser Login
For sites that use cookies and/or runtime tokens, you can capture a session directly from a real browser:
web2cli login x.com --browser
web2cli opens Chromium and waits until all required auth values are available:
- required cookie keys from
auth.methods[].keys - token values defined by
auth.methods[].capture(fortype: token)
Then it encrypts and stores the session in ~/.web2cli/sessions/<domain>.json.enc.
Token capture example in adapter YAML:
auth:
  methods:
    - type: token
      env_var: WEB2CLI_DISCORD_TOKEN
      inject:
        target: header
        key: Authorization
      capture:
        from: request.header
        key: Authorization
        match:
          host: discord.com
          path_regex: "^/api/"
Inspect current login state:
web2cli login x.com --status
Troubleshoot browser capture flow:
web2cli login slack --browser --browser-debug
This prints live capture state (have/missing cookies, token status, tracked tabs in browser context).
--browser automatically picks the best browser strategy (including local Chrome fallback for stricter sites) so users typically don't need extra setup.
For LLMs
If you are using an LLM/agent to generate a new adapter, use this flow:
- Start from
docs/llm-adapter-playbook.mdand the minimal adapter template. - Prefer declarative steps (
resolve,request,fanout,parse,transform). - Avoid custom parser scripts unless declarative parsing is truly insufficient.
- Always run
web2cli adapters validate,web2cli adapters lint, and at least one command with--trace. - Do not stop until all three checks pass and output fields look correct.
web2cli Cloud (coming soon)
Building an agent for other people? Cloud handles auth so you don't have to.
Your users click a link, log in to any site in a sandboxed browser, and your agent gets an opaque session token. No cookies touch your server.
Think "OAuth for websites that don't have OAuth."
Created by @michaloblak.
1 maintainer

Metadata
1 maintainer
Release files for web2cli 0.2.1
For a detailed explanation of source distributions (sdists) and built distributions (wheels), please see the package formats documentation.
Source distribution (sdist)
| File | Size | Uploaded | |
|---|---|---|---|
| web2cli-0.2.1.tar.gz | 69.9 kB | Details |
Built distribution (wheel)
| File | Interpreter | ABI | Platform | Reset |
|---|---|---|---|---|
| web2cli-0.2.1-py3-none-any.whl | Python 3 | none | any | Details |
Total release size: 145.9 kB
Release files / web2cli-0.2.1.tar.gz
| Download URL | web2cli-0.2.1.tar.gz |
|---|---|
| Size | 69.9 kB |
| Tags | Source |
|
SHA-256 checksum How to use checksums |
aa668ca3178990a034d1423c64caeba6ebfd96f257c5a5b6009c9af558591fb7
|
|
BLAKE2b-256 checksum How to use checksums |
4c6540fccbd5a2ada098dc3764d07948e0c281477cee5fd8567fb3fe2c6758b6
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
No |
| Uploaded via |
twine/6.2.0 CPython/3.14.2
|
Release files / web2cli-0.2.1-py3-none-any.whl
| Download URL | web2cli-0.2.1-py3-none-any.whl |
|---|---|
| Size | 76.0 kB |
| Tags | Python 3 |
|
SHA-256 checksum How to use checksums |
36f11c9e0b7bc7c5301bd6beeb6278cfd71a5364108a2e411d68bb38da78e40f
|
|
BLAKE2b-256 checksum How to use checksums |
508d310170920474422b411f110c018da079d87b150d0b77b1d3cbbba15392b9
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
No |
| Uploaded via |
twine/6.2.0 CPython/3.14.2
|














