
WhisperS2T-Reborn ⚡
An Optimized Speech-to-Text Pipeline for the Whisper Model Using CTranslate2
WhisperS2T-Reborn is a modernized fork of WhisperS2T, an optimized lightning-fast Speech-to-Text (ASR) pipeline. It is tailored for the Whisper model using the CTranslate2 backend to provide faster transcription. It includes several heuristics to enhance transcription accuracy.
Whisper is a general-purpose speech recognition model developed by OpenAI. It is trained on a large dataset of diverse audio and is also a multitasking model that can perform multilingual speech recognition, speech translation, and language identification.
Installation
pip install -U whisper-s2t-reborn
[!NOTE]
load_model()defaults todevice="cuda", which requires an NVIDIA GPU with CUDA 12.x and a CUDA-enabled build of PyTorch. The defaulttorchwheel from PyPI on Windows is CPU-only — install the CUDA build explicitly:pip install torch --index-url https://download.pytorch.org/whl/cu128No NVIDIA GPU? See Running on CPU.
Quick Start
Transcribe a single file
import whisper_s2t

model = whisper_s2t.load_model(model_identifier="large-v3")

files = ['audio1.wav']
lang_codes = ['en']
tasks = ['transcribe']
initial_prompts = [None]

out = model.transcribe_with_vad(files,
                                lang_codes=lang_codes,
                                tasks=tasks,
                                initial_prompts=initial_prompts,
                                batch_size=32)

print(out[0][0]) # Print first utterance for first file
"""
[Console Output]

{'text': "Let's bring in Phil Mackie who is there at the palace...",
 'avg_logprob': -0.25426941679184695,
 'no_speech_prob': 8.147954940795898e-05,
 'start_time': 0.0,
 'end_time': 24.8}
"""
Batch across multiple files
Passing multiple files allows segments from different files to be batched together, making better use of the GPU:
import whisper_s2t

model = whisper_s2t.load_model(model_identifier="large-v3")

files = ['audio1.wav', 'audio2.wav', 'audio3.wav']
lang_codes = ['en', 'en', 'en']
tasks = ['transcribe', 'transcribe', 'transcribe']
initial_prompts = [None, None, None]

out = model.transcribe_with_vad(files,
                                lang_codes=lang_codes,
                                tasks=tasks,
                                initial_prompts=initial_prompts,
                                batch_size=32)

# out[0] = results for audio1.wav, out[1] = results for audio2.wav, etc.
for file_idx, transcript in enumerate(out):
    print(f"File {files[file_idx]}: {len(transcript)} segments")
Word-level alignment
To enable word-level timestamps, load the model with:
model = whisper_s2t.load_model("large-v3", asr_options={'word_timestamps': True})
Running on CPU
model = whisper_s2t.load_model("large-v3", device="cpu", compute_type="float32")
Pass compute_type="float32" — CTranslate2 does not run float16 on CPU. Smaller models (base, small) are much more practical for CPU inference.
Supported Models
| Model | Identifier |
|---|---|
| Tiny | tiny / tiny.en |
| Base | base / base.en |
| Small | small / small.en |
| Medium | medium / medium.en |
| Large V3 | large-v3 |
| Large V3 Turbo | large-v3-turbo |
| Distil Small | distil-small.en |
| Distil Medium | distil-medium.en |
| Distil Large V3 | distil-large-v3 |
| Distil Large V3.5 | distil-large-v3.5 |
All models are available in float16, float32, and bfloat16 compute types via CTranslate2-4you on Hugging Face.
Benchmarks
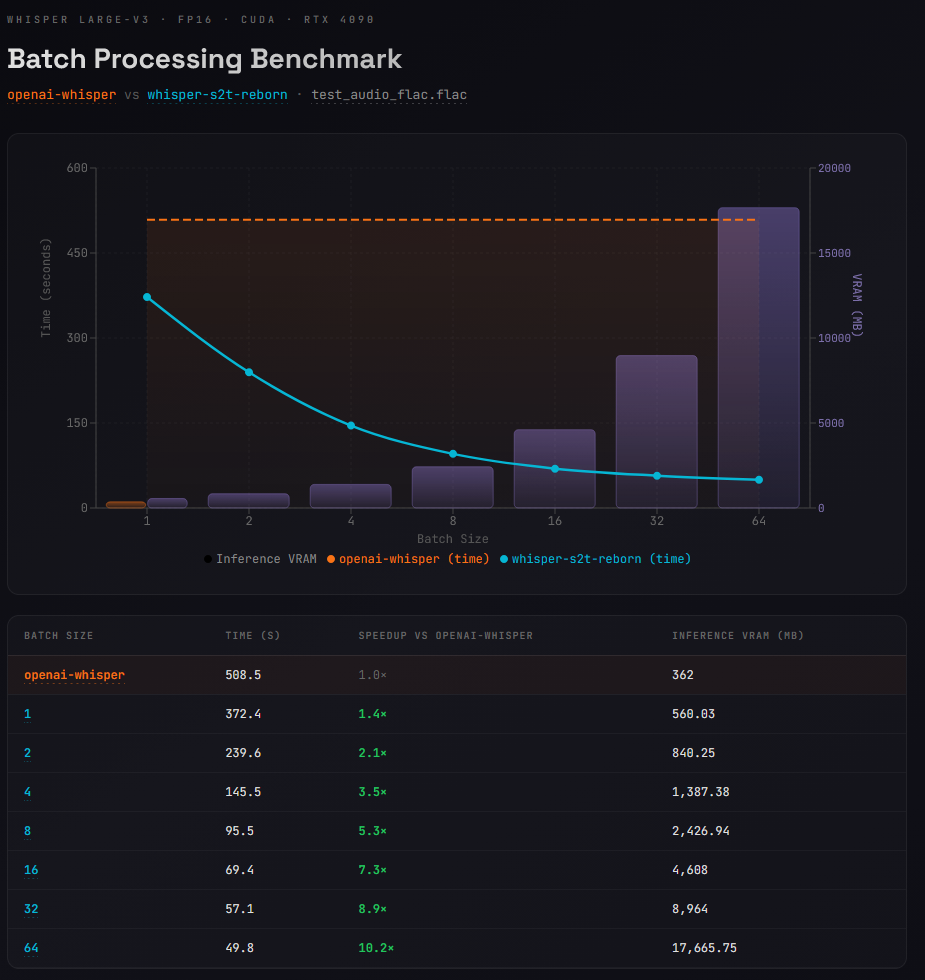
Model: Whisper large-v3 · FP16 · CUDA · RTX 4090
Audio: sam_altman_lex_podcast_367.flac
Comparing openai-whisper (no batch support) against whisper-s2t-reborn.
| Backend | Batch Size | Time (s) | Speedup | Inference VRAM (MB) |
|---|---|---|---|---|
| openai-whisper | 1 | 508.5 | 1.0× | 362 |
| whisper-s2t-reborn | 1 | 372.4 | 1.4× | 560 |
| whisper-s2t-reborn | 2 | 239.6 | 2.1× | 840 |
| whisper-s2t-reborn | 4 | 145.5 | 3.5× | 1,387 |
| whisper-s2t-reborn | 8 | 95.5 | 5.3× | 2,427 |
| whisper-s2t-reborn | 16 | 69.4 | 7.3× | 4,608 |
| whisper-s2t-reborn | 32 | 57.1 | 8.9× | 8,964 |
| whisper-s2t-reborn | 64 | 49.8 | 10.2× | 17,665.75 |
The increased VRAM usage even at batch size 1 is largely due to the VAD model. Openai's implementation doesn't use voice activity detection. The
benchmarksfolder has the actual scripts used.
VISUAL OF BENCHMARK RESULTS
Acknowledgements
- Original WhisperS2T: Thanks to shashig for the original WhisperS2T project that this fork is based on.
- OpenAI Whisper Team: Thanks to the OpenAI Whisper Team for open-sourcing the Whisper model.
- CTranslate2 Team: Thanks to the CTranslate2 Team for providing a faster inference engine for Transformers architecture.
- NVIDIA NeMo Team: Thanks to the NVIDIA NeMo Team for their contribution of the open-source VAD model used in this pipeline.
License
This project is licensed under MIT License - see the LICENSE file for details.
1 maintainer

Release files for whisper-s2t-reborn 1.7.1
For a detailed explanation of source distributions (sdists) and built distributions (wheels), please see the package formats documentation.
Source distribution (sdist)
| File | Size | Uploaded | |
|---|---|---|---|
| whisper_s2t_reborn-1.7.1.tar.gz | 1.4 MB | Details |
Built distribution (wheel)
| File | Interpreter | ABI | Platform | Reset |
|---|---|---|---|---|
| whisper_s2t_reborn-1.7.1-py3-none-any.whl | Python 3 | none | any | Details |
Total release size: 2.9 MB
Release files / whisper_s2t_reborn-1.7.1.tar.gz
| Download URL | whisper_s2t_reborn-1.7.1.tar.gz |
|---|---|
| Size | 1.4 MB |
| Tags | Source |
|
SHA-256 checksum How to use checksums |
d2d36693a6a9df5957d2055eb538ce8ef0bd46aa732ef566bc4f6bf63ef362d1
|
|
BLAKE2b-256 checksum How to use checksums |
b7b41585cee8154c35cef2b8c714dfef1094e33e4e4e1d303a13e5386fcb9e23
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
Yes |
| Uploaded via |
twine/7.0.0 CPython/3.13.14
|
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.


PyPI Publish Attestation
PyPI verified that this artifact, at this checksum, originated from the publisher listed below.
Signed by GitHub Actions, verified by PyPI on Aug 5, 2026.
Transparency logRelease files / whisper_s2t_reborn-1.7.1-py3-none-any.whl
| Download URL | whisper_s2t_reborn-1.7.1-py3-none-any.whl |
|---|---|
| Size | 1.4 MB |
| Tags | Python 3 |
|
SHA-256 checksum How to use checksums |
8a2cc44301091020740f973fd5c7b2804b73a1101bc6271dd27675e028f8d1a3
|
|
BLAKE2b-256 checksum How to use checksums |
7d20bd6ef2d24f3da33b347d97ca3751af13fed3e07510db4cb5e27bd6e7ed7d
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
Yes |
| Uploaded via |
twine/7.0.0 CPython/3.13.14
|
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.
PyPI Publish Attestation
PyPI verified that this artifact, at this checksum, originated from the publisher listed below.
Signed by GitHub Actions, verified by PyPI on Aug 5, 2026.
Transparency log













