
WTM (Whisper Turbo MLX)
Fast, lightweight Whisper transcription using MLX, in a single file under 300 lines.
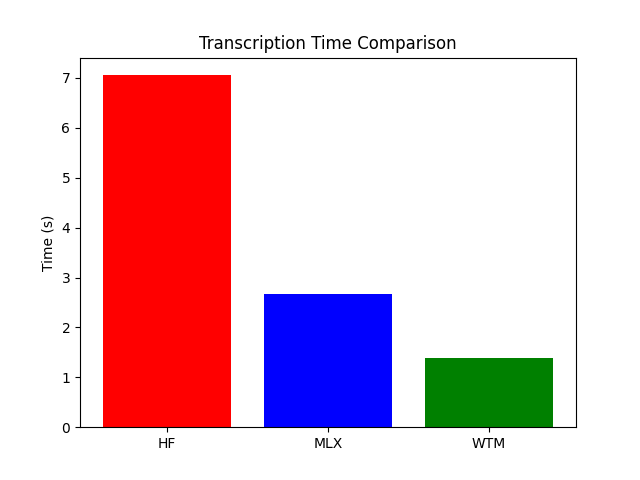
Installation
pip install whisper-turbo-mlx
FFmpeg is recommended for faster audio decoding, but optional — the library falls back to librosa automatically if it's not installed.
brew install ffmpeg # macOS, optional
For CUDA (Linux):
pip install whisper-turbo-mlx[cuda]
For CPU-only (Linux):
pip install whisper-turbo-mlx[cpu]
Usage
CLI
wtm audio.mp3
wtm audio.mp3 --multilingual
wtm audio.mp3 --timestamps
wtm audio.wav --quick
Python
from whisper_turbo import transcribe

txt, segs = transcribe('audio.wav')
txt, segs = transcribe('audio.mp3', multilingual=True, timestamps=True)
Parameters
| Parameter | Default | Description |
|---|---|---|
timestamps |
False |
Include timestamps |
quick |
False |
Faster but choppier |
multilingual |
False |
Multilingual transcription |
Example Output
$ wtm test.mp3 -t

[0.00s -> 4.96s]  A coding agent is a language model placed inside a loop, with access to tools that let it interact
[4.96s -> 10.08s]  with a codebase. Instead of just generating text, it can take actions and iterate on them.
[10.72s -> 16.24s]  MLX code packages that into a small Python library, with support for both local inference
[16.24s -> 22.72s]  and external APIs. You start it, give it a task, and it runs a loop. It calls tools,
[22.72s -> 25.84s]  gets results back, and keeps going until it decides it's done.
[26.56s -> 31.92s]  One of those tools is the Agent tool, which lets it spawn a child agent and delegate a task.
[32.48s -> 37.84s]  This exists because of context decay. As sessions get longer, performance drops,
[37.84s -> 44.72s]  history grows, attention spreads, and outputs get worse. Delegating a heavy subtask to a sub-agent
[44.72s -> 50.16s]  keeps both contexts focused. You can customize the agent through command line arguments.
[50.16s]  You can set the system prompt for the agent with "double dash system" or point "double dash skill"
[55.60s -> 62.08s]  at a folder to load skills from. On the back-end side, it can connect to a local model or APIs like
[62.08s -> 68.46s]  Gemini or DeepSeq with DoubleDash API. And if you're running locally, you can also plug in
[68.46s -> 75.52s]  other harnesses like Codex, Gemini CLI, or Claude Code with DoubleDash Leash. You can also sandbox
[75.52s]  your agent however you want. For instance, you can run the harness inside a virtual machine
[80.56s -> 85.38s]  and connect it to an LLM server running on the host or outside APIs.
[86.10s -> 89.78s]  You can use it conversationally, but there's also a set of slash commands.
[90.36s -> 94.90s]  For example, slash branch forks the current conversation into a child agent,
[95.36s -> 99.78s]  runs your prompt there, and returns just the result, leaving the main session clean.
[100.04s -> 104.90s]  So you can ask a side question and get an answer without polluting your working context.
[105.70s -> 111.22s]  When a session starts, the working directory is snapshotted into a fresh Git work tree on a new branch.
[111.92s -> 116.28s]  After every tool round trip, every action and result, it creates a commit.
[116.98s -> 121.58s]  That commit includes both the file changes and the full conversation up to that point.
[122.12s -> 125.56s]  So your Git history becomes a step-by-step trace of the agent's behavior.
[125.96s -> 132.74s]  Each commit captures both the code and the conversation that produced it, so you can restore any point and resume from there.
[133.46s -> 140.46s]  When the agent goes off the rails, which it will, you're not stuck debugging the final state, you have a full timeline of how it got there.
[141.24s -> 145.80s]  While MLX code provides command line interfaces, it's really designed as a library.
[146.50s -> 151.88s]  For example, instead of giving the agent full file system access, you can define a custom toolset.
[152.20s -> 156.04s]  Read KB, Comment KB, and Submit KB.
[156.74s -> 160.24s]  Now the agent is restricted to operating on a structured knowledge base.
[160.84s]  You seed it with documents and start the agent.
[163.00s -> 168.60s]  The main agent reads the material and drafts a synthesis. Then it spawns a sub-agent.
[169.28s -> 173.60s]  That sub-agent acts as a reviewer. It reads the draft and posts critiques.
[174.18s -> 179.00s]  The main agent reads those critiques, revises the draft, and produces a final version.
[179.74s -> 183.02s]  Because everything is modular, you can wire it however you want.
[183.58s -> 186.26s]  An agent triggered by a scheduler instead of a REPL.
[186.70s -> 189.16s]  A tool that takes piped input as a prompt.
[189.36s]  Or multi-agent handoffs, one agent commits a state, another resumes from it. These aren't special modes, they fall out naturally from the components being composable. That's MLX code, composable pieces you can rearrange however you want, and a system you can shape to your own workflows.

Segments: [(0.0, 4.96, 'A coding agent is a language model placed inside a loop, with access to tools that let it interact'), (4.96, 10.08, 'with a codebase. Instead of just generating text, it can take actions and iterate on them.'), (10.72, 16.240000000000002, 'MLX code packages that into a small Python library, with support for both local inference'), (16.240000000000002, 22.72, 'and external APIs. You start it, give it a task, and it runs a loop. It calls tools,'), (22.72, 25.84, "gets results back, and keeps going until it decides it's done."), (26.56, 31.919999999999998, 'One of those tools is the Agent tool, which lets it spawn a child agent and delegate a task.'), (32.48, 37.839999999999996, 'This exists because of context decay. As sessions get longer, performance drops,'), (37.839999999999996, 44.72, 'history grows, attention spreads, and outputs get worse. Delegating a heavy subtask to a sub-agent'), (44.72, 50.16, 'keeps both contexts focused. You can customize the agent through command line arguments.'), (50.16, None, 'You can set the system prompt for the agent with "double dash system" or point "double dash skill"'), (55.6, 62.08, 'at a folder to load skills from. On the back-end side, it can connect to a local model or APIs like'), (62.08, 68.46000000000001, "Gemini or DeepSeq with DoubleDash API. And if you're running locally, you can also plug in"), (68.46000000000001, 75.52000000000001, 'other harnesses like Codex, Gemini CLI, or Claude Code with DoubleDash Leash. You can also sandbox'), (75.52000000000001, None, 'your agent however you want. For instance, you can run the harness inside a virtual machine'), (80.56, 85.38, 'and connect it to an LLM server running on the host or outside APIs.'), (86.10000000000001, 89.78, "You can use it conversationally, but there's also a set of slash commands."), (90.36, 94.9, 'For example, slash branch forks the current conversation into a child agent,'), (95.36, 99.78, 'runs your prompt there, and returns just the result, leaving the main session clean.'), (100.04, 104.9, 'So you can ask a side question and get an answer without polluting your working context.'), (105.7, 111.22, 'When a session starts, the working directory is snapshotted into a fresh Git work tree on a new branch.'), (111.92, 116.28, 'After every tool round trip, every action and result, it creates a commit.'), (116.98, 121.58, 'That commit includes both the file changes and the full conversation up to that point.'), (122.12, 125.56, "So your Git history becomes a step-by-step trace of the agent's behavior."), (125.96000000000001, 132.74, 'Each commit captures both the code and the conversation that produced it, so you can restore any point and resume from there.'), (133.46, 140.46, "When the agent goes off the rails, which it will, you're not stuck debugging the final state, you have a full timeline of how it got there."), (141.24, 145.8, "While MLX code provides command line interfaces, it's really designed as a library."), (146.5, 151.88, 'For example, instead of giving the agent full file system access, you can define a custom toolset.'), (152.20000000000002, 156.04000000000002, 'Read KB, Comment KB, and Submit KB.'), (156.74, 160.24, 'Now the agent is restricted to operating on a structured knowledge base.'), (160.84, None, 'You seed it with documents and start the agent.'), (163.0, 168.6, 'The main agent reads the material and drafts a synthesis. Then it spawns a sub-agent.'), (169.28, 173.6, 'That sub-agent acts as a reviewer. It reads the draft and posts critiques.'), (174.18, 179.0, 'The main agent reads those critiques, revises the draft, and produces a final version.'), (179.74, 183.02, 'Because everything is modular, you can wire it however you want.'), (183.58, 186.26, 'An agent triggered by a scheduler instead of a REPL.'), (186.7, 189.16, 'A tool that takes piped input as a prompt.'), (189.36, None, "Or multi-agent handoffs, one agent commits a state, another resumes from it. These aren't special modes, they fall out naturally from the components being composable. That's MLX code, composable pieces you can rearrange however you want, and a system you can shape to your own workflows.")]
License
MIT
1 maintainer

Release files for whisper-turbo-mlx 0.0.3
For a detailed explanation of source distributions (sdists) and built distributions (wheels), please see the package formats documentation.
Source distribution (sdist)
| File | Size | Uploaded | |
|---|---|---|---|
| whisper_turbo_mlx-0.0.3.tar.gz | 385.2 kB | Details |
Built distribution (wheel)
| File | Interpreter | ABI | Platform | Reset |
|---|---|---|---|---|
| whisper_turbo_mlx-0.0.3-py3-none-any.whl | Python 3 | none | any | Details |
Total release size: 767.7 kB
Release files / whisper_turbo_mlx-0.0.3.tar.gz
| Download URL | whisper_turbo_mlx-0.0.3.tar.gz |
|---|---|
| Size | 385.2 kB |
| Tags | Source |
|
SHA-256 checksum How to use checksums |
0530a4385b77d06a5244439a7a2935cd96f76eddc0ebf879bbeab7d6c7adf944
|
|
BLAKE2b-256 checksum How to use checksums |
8140b8b140a549eb1d5a1a34861e4f0951cebf851e4406037aefefd71b1d6000
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
No |
| Uploaded via |
twine/6.2.0 CPython/3.12.8
|
Release files / whisper_turbo_mlx-0.0.3-py3-none-any.whl
| Download URL | whisper_turbo_mlx-0.0.3-py3-none-any.whl |
|---|---|
| Size | 382.5 kB |
| Tags | Python 3 |
|
SHA-256 checksum How to use checksums |
a4145dd13fbfae45dc5d1a60ecb210677eb018f009fe7b78a1603d6324c74300
|
|
BLAKE2b-256 checksum How to use checksums |
26d21bb1da10176487b023851b5f454bd4063fafb8f77d16234a97db5d4c4f12
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
No |
| Uploaded via |
twine/6.2.0 CPython/3.12.8
|














