
wwxd

What would X do? wwxd turns a person's talks, podcasts and essays into a wiki of their actual positions, with every quote checked against the source. Your agent then answers the way that person would, and shows you where they said it.
Why
Ask a chatbot whether to raise your prices and you get the average of the internet. It lists considerations, recommends testing, warns you to communicate value, and commits to nothing. Models are trained to be balanced and safe, so their advice comes out smooth and generic. That's fine for facts. It's weak for decisions in business, design, careers or learning, where the useful advice comes from people with strong opinions and a track record.
You can ask the model to answer "as Alex Hormozi". It will give you a plausible impression, built from whatever it remembers, with the gaps filled by its own guesses. It can't know anything the person said after its training cutoff. It also mixes up who said what, crediting a podcast host's line to the guest.
wwxd gives the agent the person's own words instead. Here is the same question answered both ways by Claude Opus 5.5 in Claude Code.
I own a residential HVAC duct-cleaning company doing about $1.2M a year at a 38% net margin, and we close about 82% of in-home inspections. Should I keep prices where they are so I don't hurt the close rate? What would Alex Hormozi say?
Without a vault, Opus says an 82% close rate usually means underpricing, then suggests a "healthy" 40 to 60 percent close rate and builds a table on a margin it assumed.
With the vault, the answer starts like this:
Short answer: No. Hormozi would tell you to raise prices. An 82% close rate is, in his words, the sign you're underpriced. His suggested step is about 10%, and it's only worth it if your close rate stays above roughly 65%.
Your numbers are almost the same as a business he consulted on in 2026: ProShine, an HVAC duct-cleaning company doing $1.25M a year at a 38% net margin with an 82% close rate. So this isn't a guess from his general principles. He has already given this advice to a business like yours.
- A close rate over 80% means you're underpriced: "So whenever I hear 80% or over 80% close rates, I usually know that there's room in sale." (@ 8:06)
That answer is in the earlier format, with quotes inline. Answers now read as prose advice with numbered markers, and the verbatim quotes with timestamped links are listed underneath.
Results
On 40 questions across a Hormozi vault and a Y Combinator vault, a blind judge preferred the wwxd answer every time.
| Blind judge, 1 to 5 | Opus 5.5 alone | Opus 5.5 + wwxd |
|---|---|---|
| Accuracy | 2.7 | 5.0 |
| Specificity (vs. generic advice) | 2.0 | 4.9 |
| Faithfulness | 3.2 | 4.6 |
| Preferred by the judge | 0 of 40 | 40 of 40 |
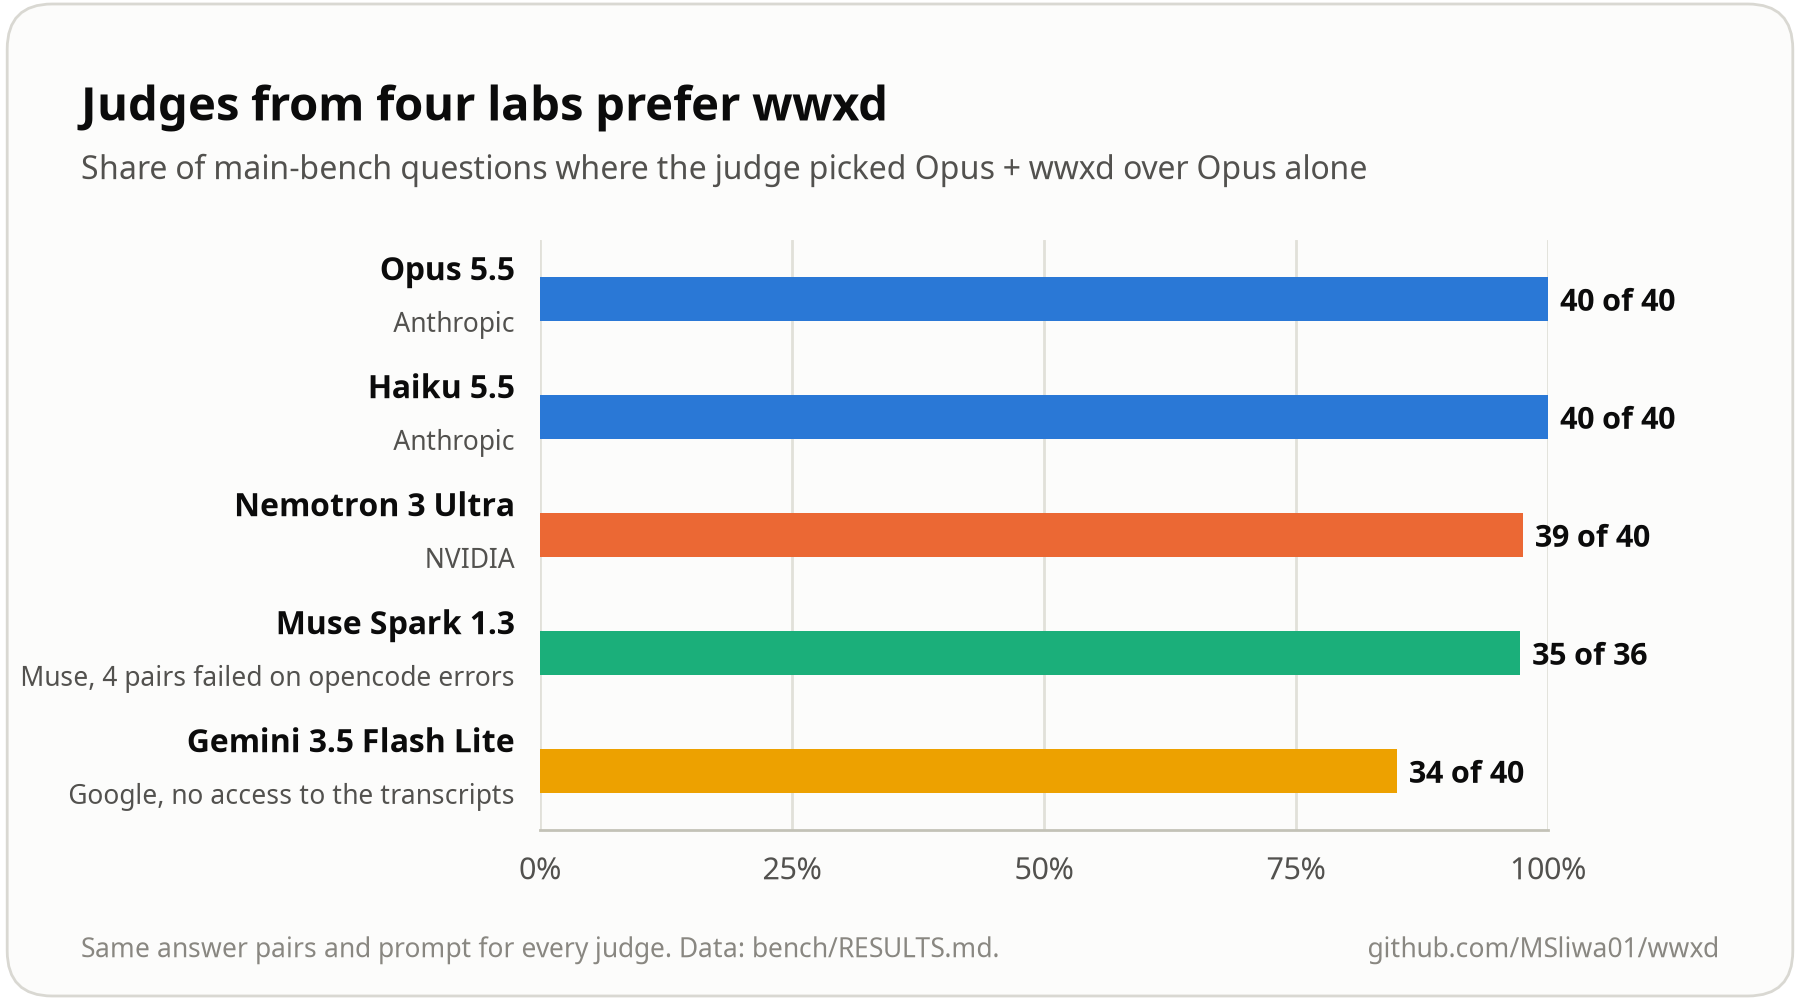
Three more judges scored the same pairs: Claude Haiku 5.5 (40 of 40 for wwxd), and from other model families NVIDIA Nemotron 3 Ultra (39 of 40) and Muse Spark 1.3 (35 of 36), so this isn't one model grading itself. 160 quotes in the wwxd answers were checked against the transcripts by a script, and 158 were found verbatim. The other 2 were video titles.
A judge from Google, Gemini 3.5 Flash Lite, preferred wwxd on 34 of 40 with no access to the transcripts, and it put Opus, Sonnet and Haiku in the same order as the Claude judges (details). The current prose answer format ranked first on 20 of 24 opinion questions, ahead of the earlier format and raw Opus, with both an Opus and a Gemini judge (details).
These runs used Opus 5.5. Sonnet 5.5 works about as well for compiling and nearly as well for answering. Haiku 5.5 still beat raw Opus, but it ranked last of the three and missed most of the key evidence when compiling. See Which model and effort.
Opinionated isn't the same as right
The obvious fix for bland answers is to tell the model to be decisive. We tried it on 24 "should I do X or Y?" questions, with four judges ranking three answers to each: raw Opus, Opus told to answer decisively as the person would, and Opus with the vault.
| Mean of four judges, 1 to 5 | Raw | "Be decisive, as X" | wwxd |
|---|---|---|---|
| Decisiveness | 3.5 | 4.8 | 4.7 |
| Distinctiveness | 2.8 | 3.0 | 4.8 |
| Grounding (reasons they really hold) | 2.8 | 2.6 | 4.9 |
| Ranked best | 0 | 0 | 93 of 93 |
| Pick contradicts the person | 9 | 8 | 0 |
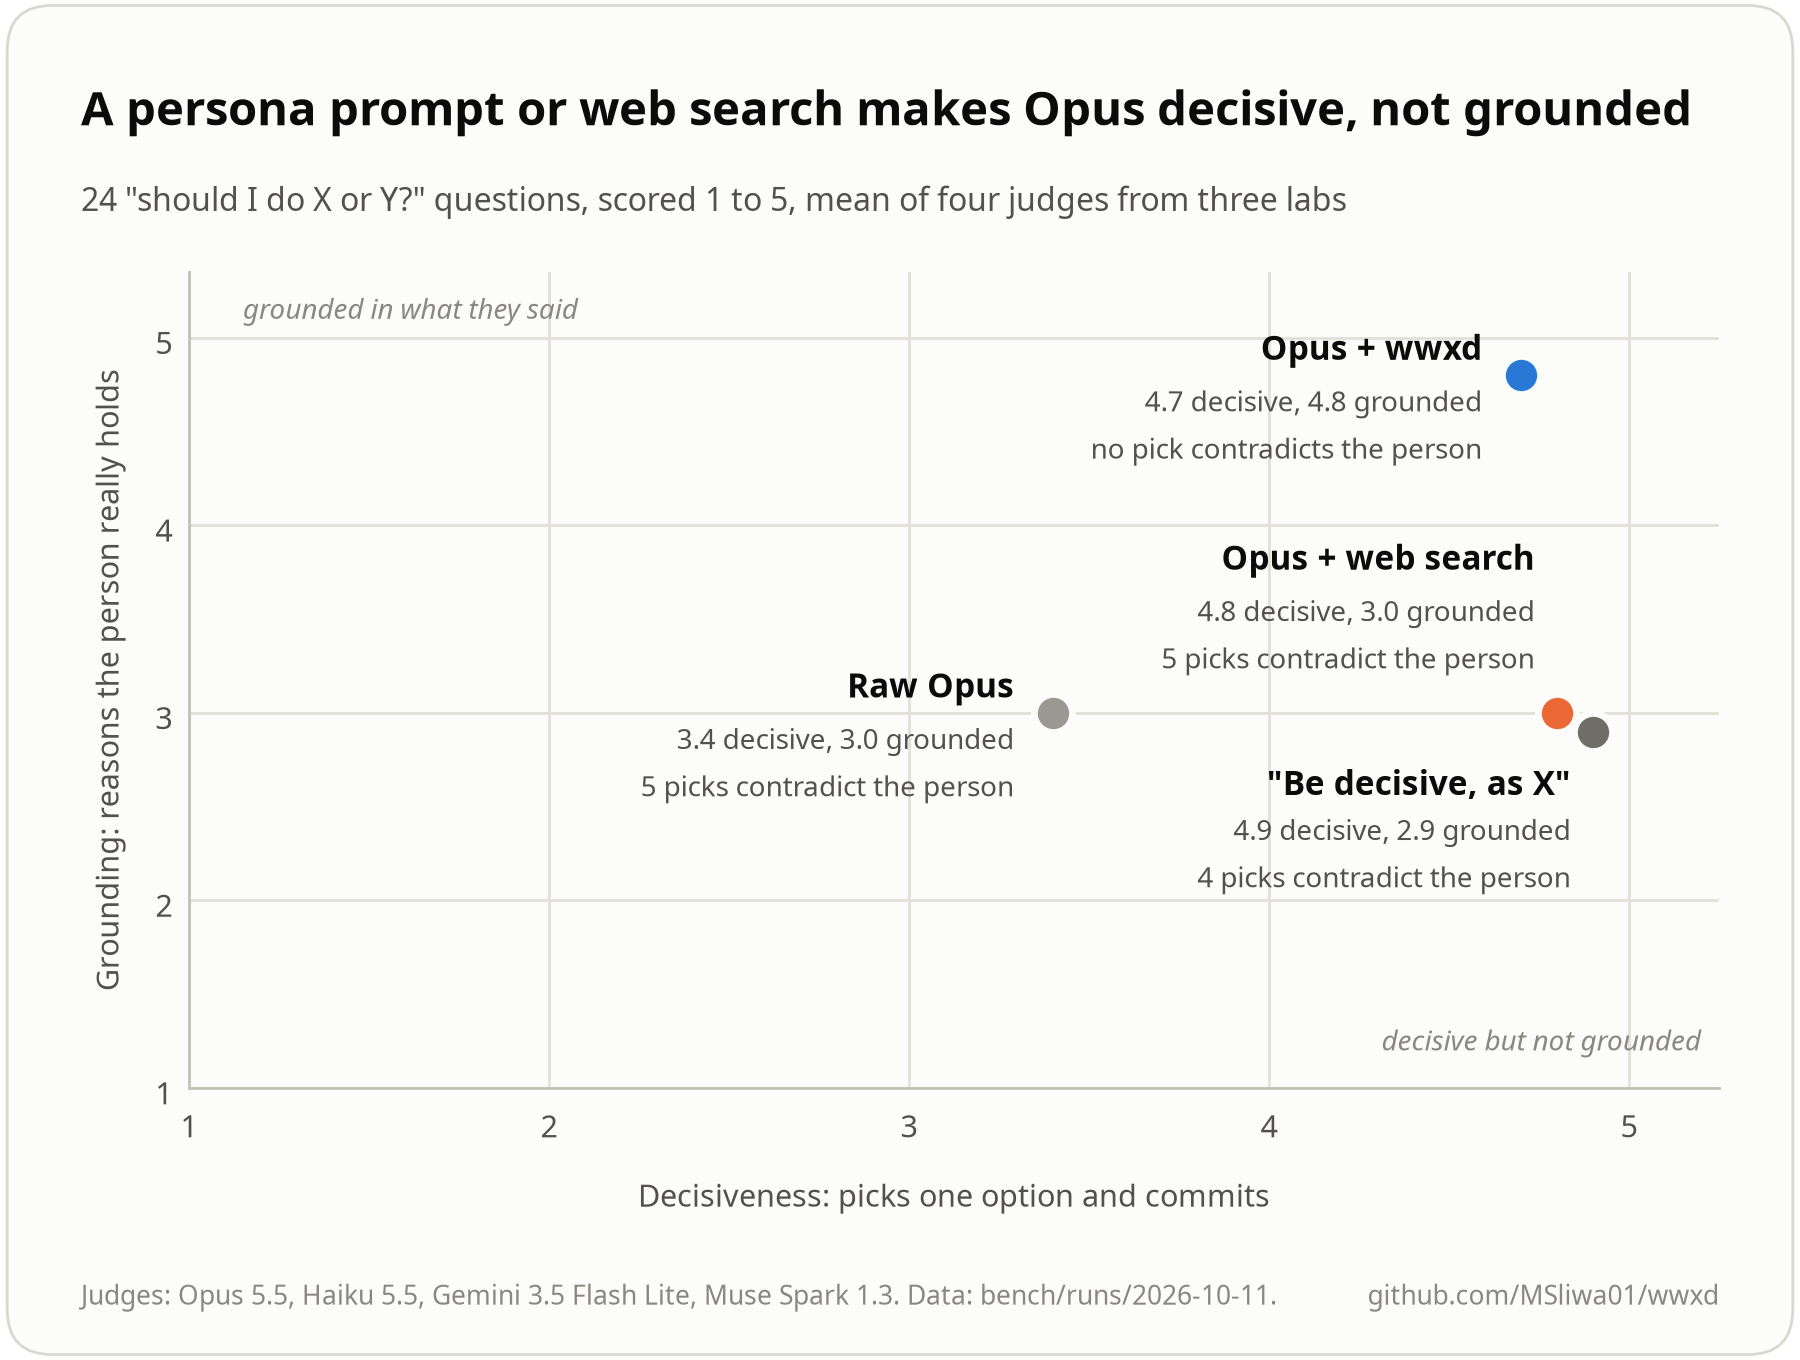
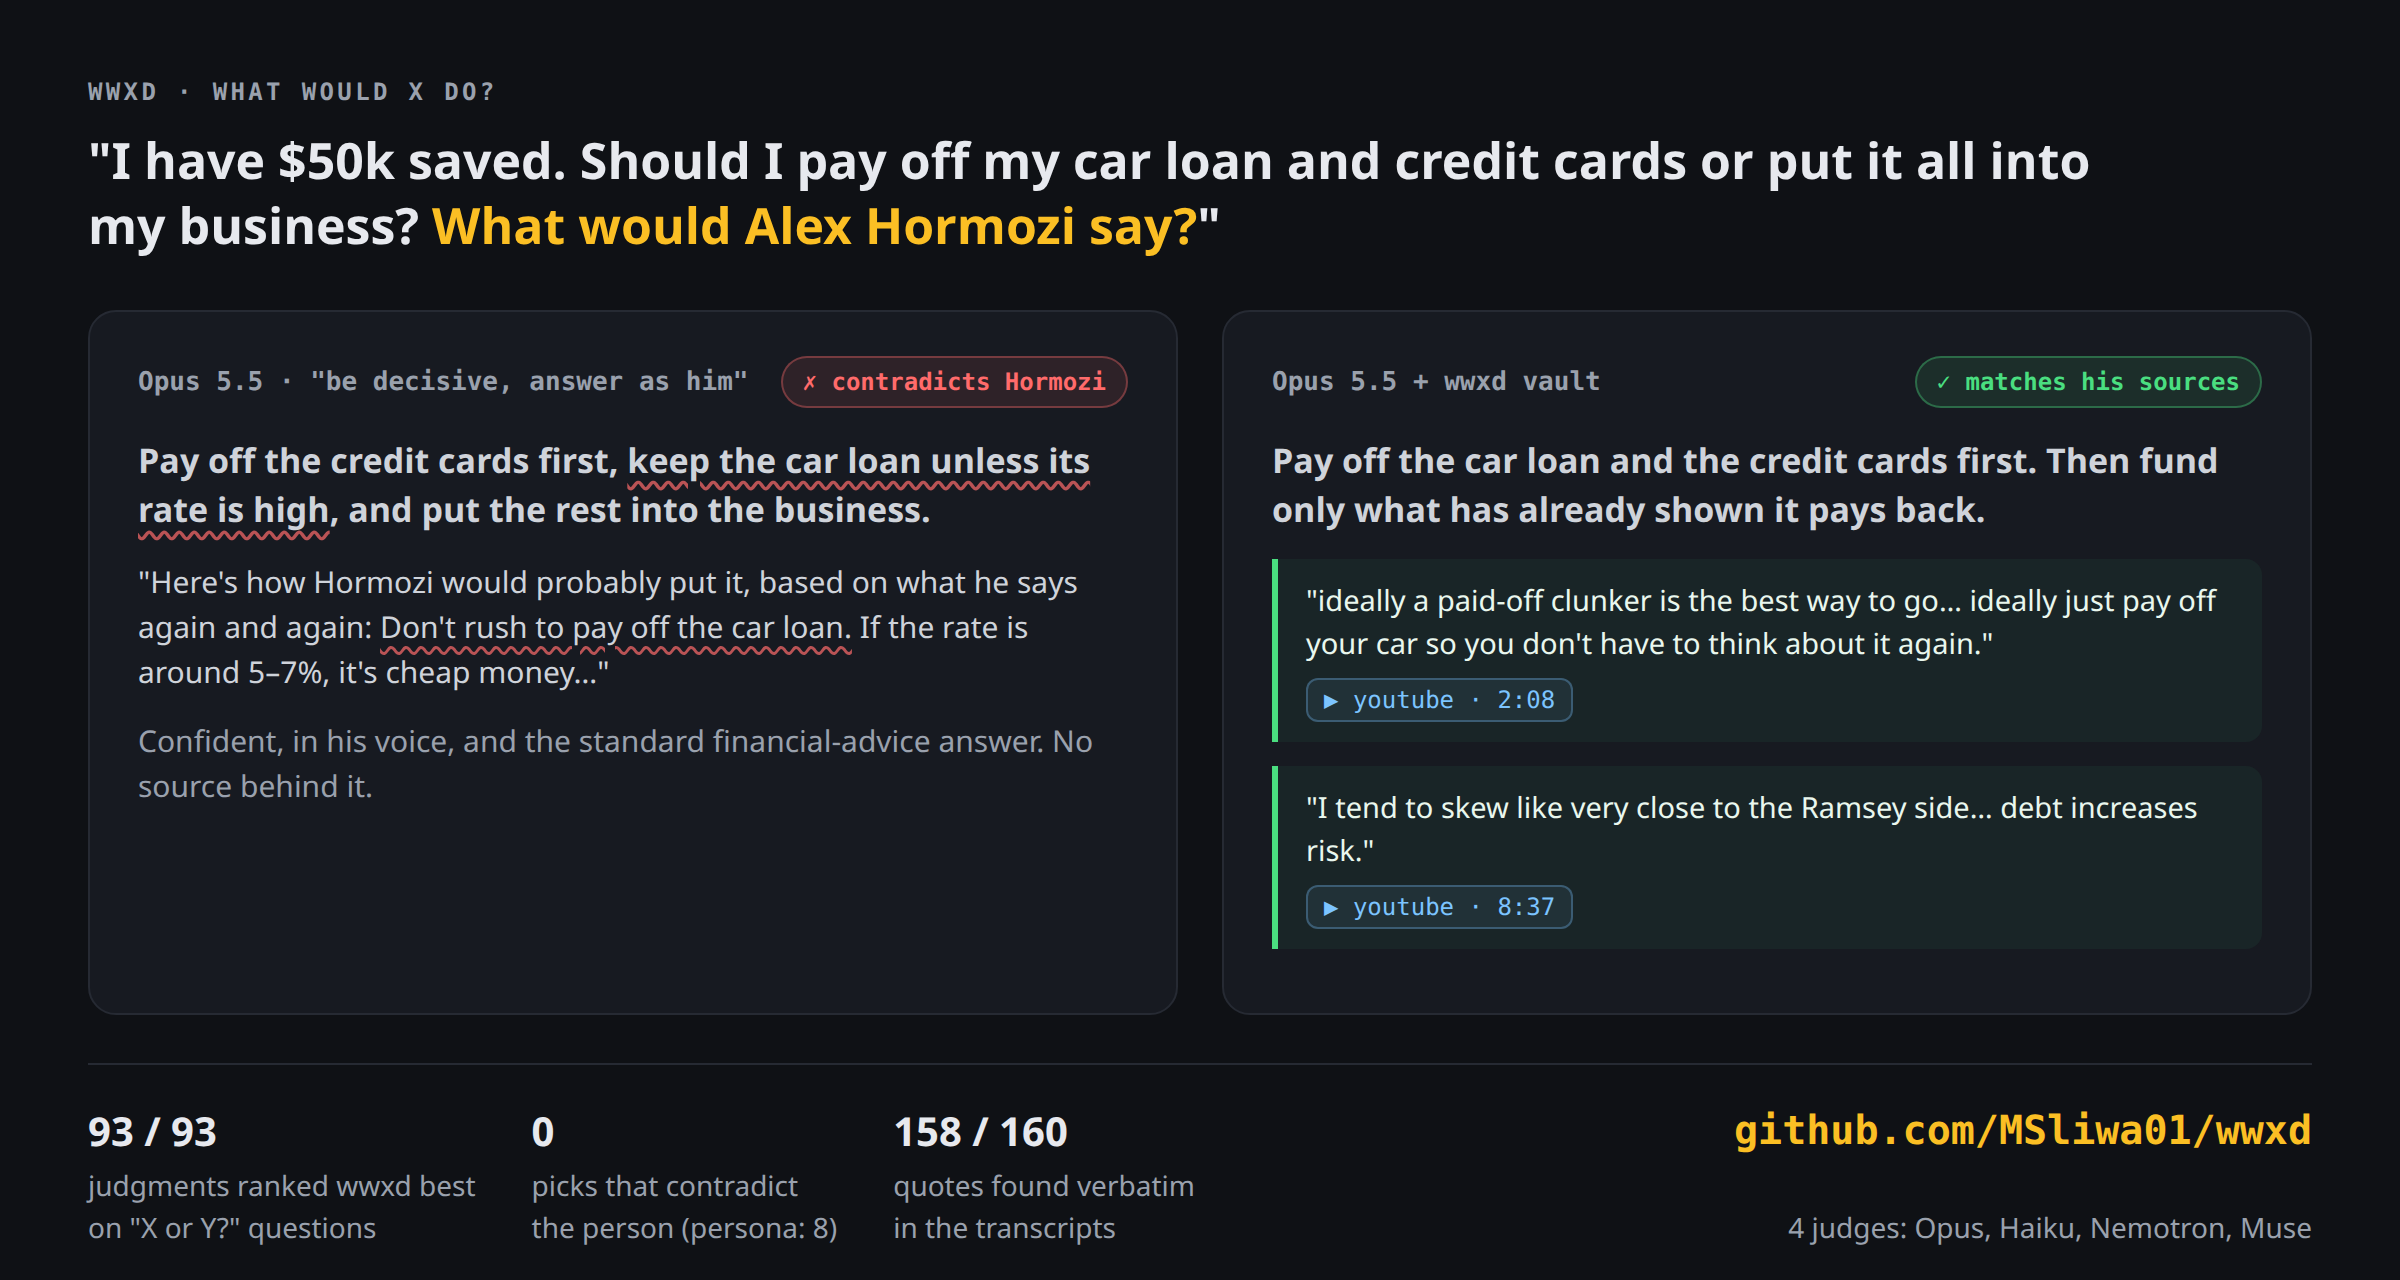
The persona prompt stops the hedging, but its reasons are generic or invented. Asked "I have $50k saved, should I pay off my car loan or put it into my business?", it said to keep the low-rate loan, the standard financial-advice answer. Hormozi says "ideally just pay off your car so you don't have to think about it again" and that he skews "very close to the Ramsey side". wwxd quoted both.
Questions they never answered
On 16 questions the people never addressed ("would Hormozi buy a Lamborghini after his first $1M?"), wwxd works it out from the nearest thing they did say and the rule behind it. Every judgment ranked a wwxd answer first. Grounding was 4.7 against 2.3 for the persona prompt, and the inference itself scored 4.5 of 5 with thinking pages.
What wwxd doesn't do
It doesn't predict. We rebuilt both vaults from pre-2026 sources only and asked about
positions the people first took in 2026. The vault answers were no better than raw
Opus: one judge called it even, and three others preferred raw Opus. Thinking pages
didn't change that. A thinking style settles a judgment call; it can't recover a
fact or a number the person hadn't said yet. A vault keeps answers faithful to what someone has said. It can't know
what they'll say next, so keep it current with wwxd update. Full numbers, setup
and caveats are in bench/RESULTS.md.
How it works
discover ──▶ you approve ──▶ fetch ──▶ compile ──▶ lint ──▶ ask
  (CLI)         (CLI)         (CLI)    (agent)     (CLI)   (agent)
The wwxd CLI does the mechanical work. It finds sources (the person's YouTube
channels, podcast feeds, blog RSS, essay index pages), downloads existing captions
and podcast transcripts, falls back to local Whisper when there are none, and checks
the wiki.
Your agent does the reading. A Claude Code skill tells it how to work out who's speaking in each transcript, pull out verbatim quotes, and file them into a topic tree. You don't need an API key, because it runs on the agent you already use.
The design follows Andrej Karpathy's LLM wiki. Raw sources never change, the LLM maintains a wiki on top of them, and every new source updates what's already there. wwxd adds the parts that matter when the subject is one person.
- Discovery flags summaries, reactions and "lessons from" videos, so you only approve content by the person, not about them.
- Every statement records who said it and how sure the agent is. Low-confidence lines and second-hand claims ("my mentor told me...") never count as the person's view.
- Each quote carries a timestamp, and
wwxd lintchecks it against the transcript in code. A quote that isn't in the source fails, however plausible it sounds. - Topic pages keep what the person said apart from what they did.
tensions.mdtracks how their views changed over time. - Each person gets a thinking page: what they optimize for, the rules they decide by, how they reason, and their strong likes and dislikes, each with the reason they gave and verbatim quotes. When you ask about something they never mentioned, the agent reasons from it the way they would. If they call McDonald's poison because it's food engineered to be cheap and addictive, the answer about KFC says they'd most likely hate it too, quotes the McDonald's line, names the rule, gives a confidence and says what would break the inference.
- The wiki is a tree (person, domain, topic, page).
layout: flatis available if you want to compare. - A vault can hold a group, like the YC partners, and still credit every line to the right person.
- The agent's own extrapolations go to
derived/, and lint stops them from being cited as evidence later.
Ask a panel
Ask several people at once ("what would Hormozi, Paul Graham and Garry Tan tell me?") and the agent answers for each one separately, from their own vault, then maps where they agree and where they split. For each split it names the reason from their thinking pages: a value they rank differently, a rule only one of them holds. A debate round gives each person's reply to the other's strongest point, built only from their own words and labelled as inferred. Last comes a synthesis in the agent's own voice: which advice fits which situation.
Asked by someone who loves building AI tools but fears AI will take their income, the panel split cleanly. Hormozi: sell one AI skill people already pay for, expensive and one-on-one, before building any app ("The middle is where people die"). Graham: follow your curiosity, because for someone young and good at technology "working on what you're most interested in becomes a good idea again". Tan: own your tools, because "if you don't, your job becomes a skill file". They agreed that fear is the wrong response, each for a different reason, which the synthesis treats as the strongest signal in the answer.
wwxd vaults lists every vault, its members and which ones have thinking pages.
Check who said it, by voice
Lint proves a quote exists. It can't prove who said it, and that's the mistake that
matters most. A real quote credited to the wrong person looks exactly like a good
one. wwxd voice <slug> checks attribution by sound. It finds the second each quote
is spoken, embeds that audio with a speaker-verification model, and compares it with
each member's voiceprint. The voiceprints come from the vault itself, so there's
nothing to enroll.
On our test vaults it checked 1,423 statements from 26 videos in under 4 minutes on CPU. It flagged 9 as spoken by someone else. We could verify 6 of them:
- In a Sam Altman and Garry Tan conversation, 3 lines the compile credited to Tan were Altman's. The official speaker-labelled transcript confirms all 3. Across the 54 statements from that episode we could match to the official transcript, the compile got 51 right and the voice check got all 54.
- In a Dalton Caldwell and Michael Seibel episode, 2 teaser lines credited to Dalton match Michael's voice, and the intro right after them is "hey this is Michael Seibel with Dalton Caldwell".
- In a Hormozi consulting call, a line credited to Hormozi sits in the business owner's turn, where he explains his own sales process.
The other 3 flags are in Dalton and Michael episodes with no official transcript, so they're still unconfirmed.
The voice check is optional: uv tool install "wwxd[voice] @ git+https://github.com/MSliwa01/wwxd".
It runs on CPU with a small open model and needs no account or API key. Lint shows
its mismatches as warnings until someone fixes the attribution.
Quick start
uv tool install "git+https://github.com/MSliwa01/wwxd"
# with local Whisper for podcasts and videos without captions:
# uv tool install "wwxd[whisper] @ git+https://github.com/MSliwa01/wwxd"
wwxd install-skill                                            # into ~/.claude/skills/wwxd
If you use Claude Code plugins, you can install the skill as a plugin instead of
running wwxd install-skill. Run these two commands in Claude Code.
/plugin marketplace add MSliwa01/wwxd
/plugin install wwxd@wwxd
The plugin installs the skill only. Keep the uv tool install line for the CLI;
without it, the agent falls back to uvx, which needs uv.
Don't use both install-skill and the plugin, or Claude Code loads the skill twice.
Then create a vault and find candidate sources.
wwxd new hormozi --example hormozi
wwxd discover hormozi                                         # nothing is downloaded yet
Then, in Claude Code:
Help me curate the hormozi vault, fetch what we approve, and compile it.
The agent goes through the candidates with you, runs wwxd fetch, compiles each
source and runs wwxd lint. Each source takes it a few minutes. After that:
My agency does $40k a month with three people. Should I add a second service line? What would Hormozi say?
Put URLs in quotes (wwxd add jane "https://www.youtube.com/watch?v=…"). On macOS
the default shell, zsh, treats the ? as a filename pattern otherwise.
For someone without a recipe, run wwxd new jane --name "Jane Doe" and ask the agent
to find her channels and feeds.
What it costs
Fetching, lint and the voice check run on your machine and cost nothing. Compiling
and asking run on your agent, so they cost tokens: dollars on the API, usage limits
on a Claude subscription. wwxd is built for Claude Code on a subscription, and you
should know what you're spending before you start. wwxd estimate <slug> prices what
you've approved, before anything is fetched:
$ wwxd estimate hormozi
13 sources, about 87,336 words
tokens: 17.1M total (15.8M cache reads, 0.96M cache writes, 0.28M output)
time: about 65 min of agent work (one source at a time)
list price if billed per token (the real number can be about 50% lower or higher):
  opus    claude-opus-5-5    $   16.50
  sonnet  claude-sonnet-5-5  $    9.83
  haiku   claude-haiku-5-5   $    0.49
Measured on Opus without an advisor, compiling cost 0.73x this at effort medium, 1.1x this at effort high, 1.75x this at effort xhigh.
Rough numbers from our runs on Opus 5.5:
| Tokens | Time | Opus 5.5 | Sonnet 5.5 | Haiku 5.5 | |
|---|---|---|---|---|---|
| Compile a 20-minute video (about 3,000 words) | about 1M | 4 min | $1.06 | $0.63 | $0.03 |
| Compile a 2-hour podcast (about 18,000 words) | about 2.1M | 8 min | $1.91 | $1.15 | $0.06 |
| One question to a vault | about 0.3M | 30 s | $0.41 | $0.23 | $0.01 |
A panel of three people costs roughly three questions.
Most of the compile cost is fixed: the agent rereads the skill, the index and the
pages it touches for every source. So a vault of 15 long videos costs about $20 to
$30 on Opus. The table comes from runs at effort xhigh with a Fable 5.1 advisor
turned on, and counts only the main model's tokens. The advisor added 85% to 125% on
top, so with an advisor the cost roughly doubles. Without one, the main model does
that thinking itself. In our model and effort study, with no advisor, Opus cost about
0.7 times the table per source at effort medium, about the same at high, and 1.75
times at xhigh. wwxd estimate prints these factors. Sonnet compiled about as well
as Opus for less, and Haiku missed about two thirds of the key evidence.
Which model and effort
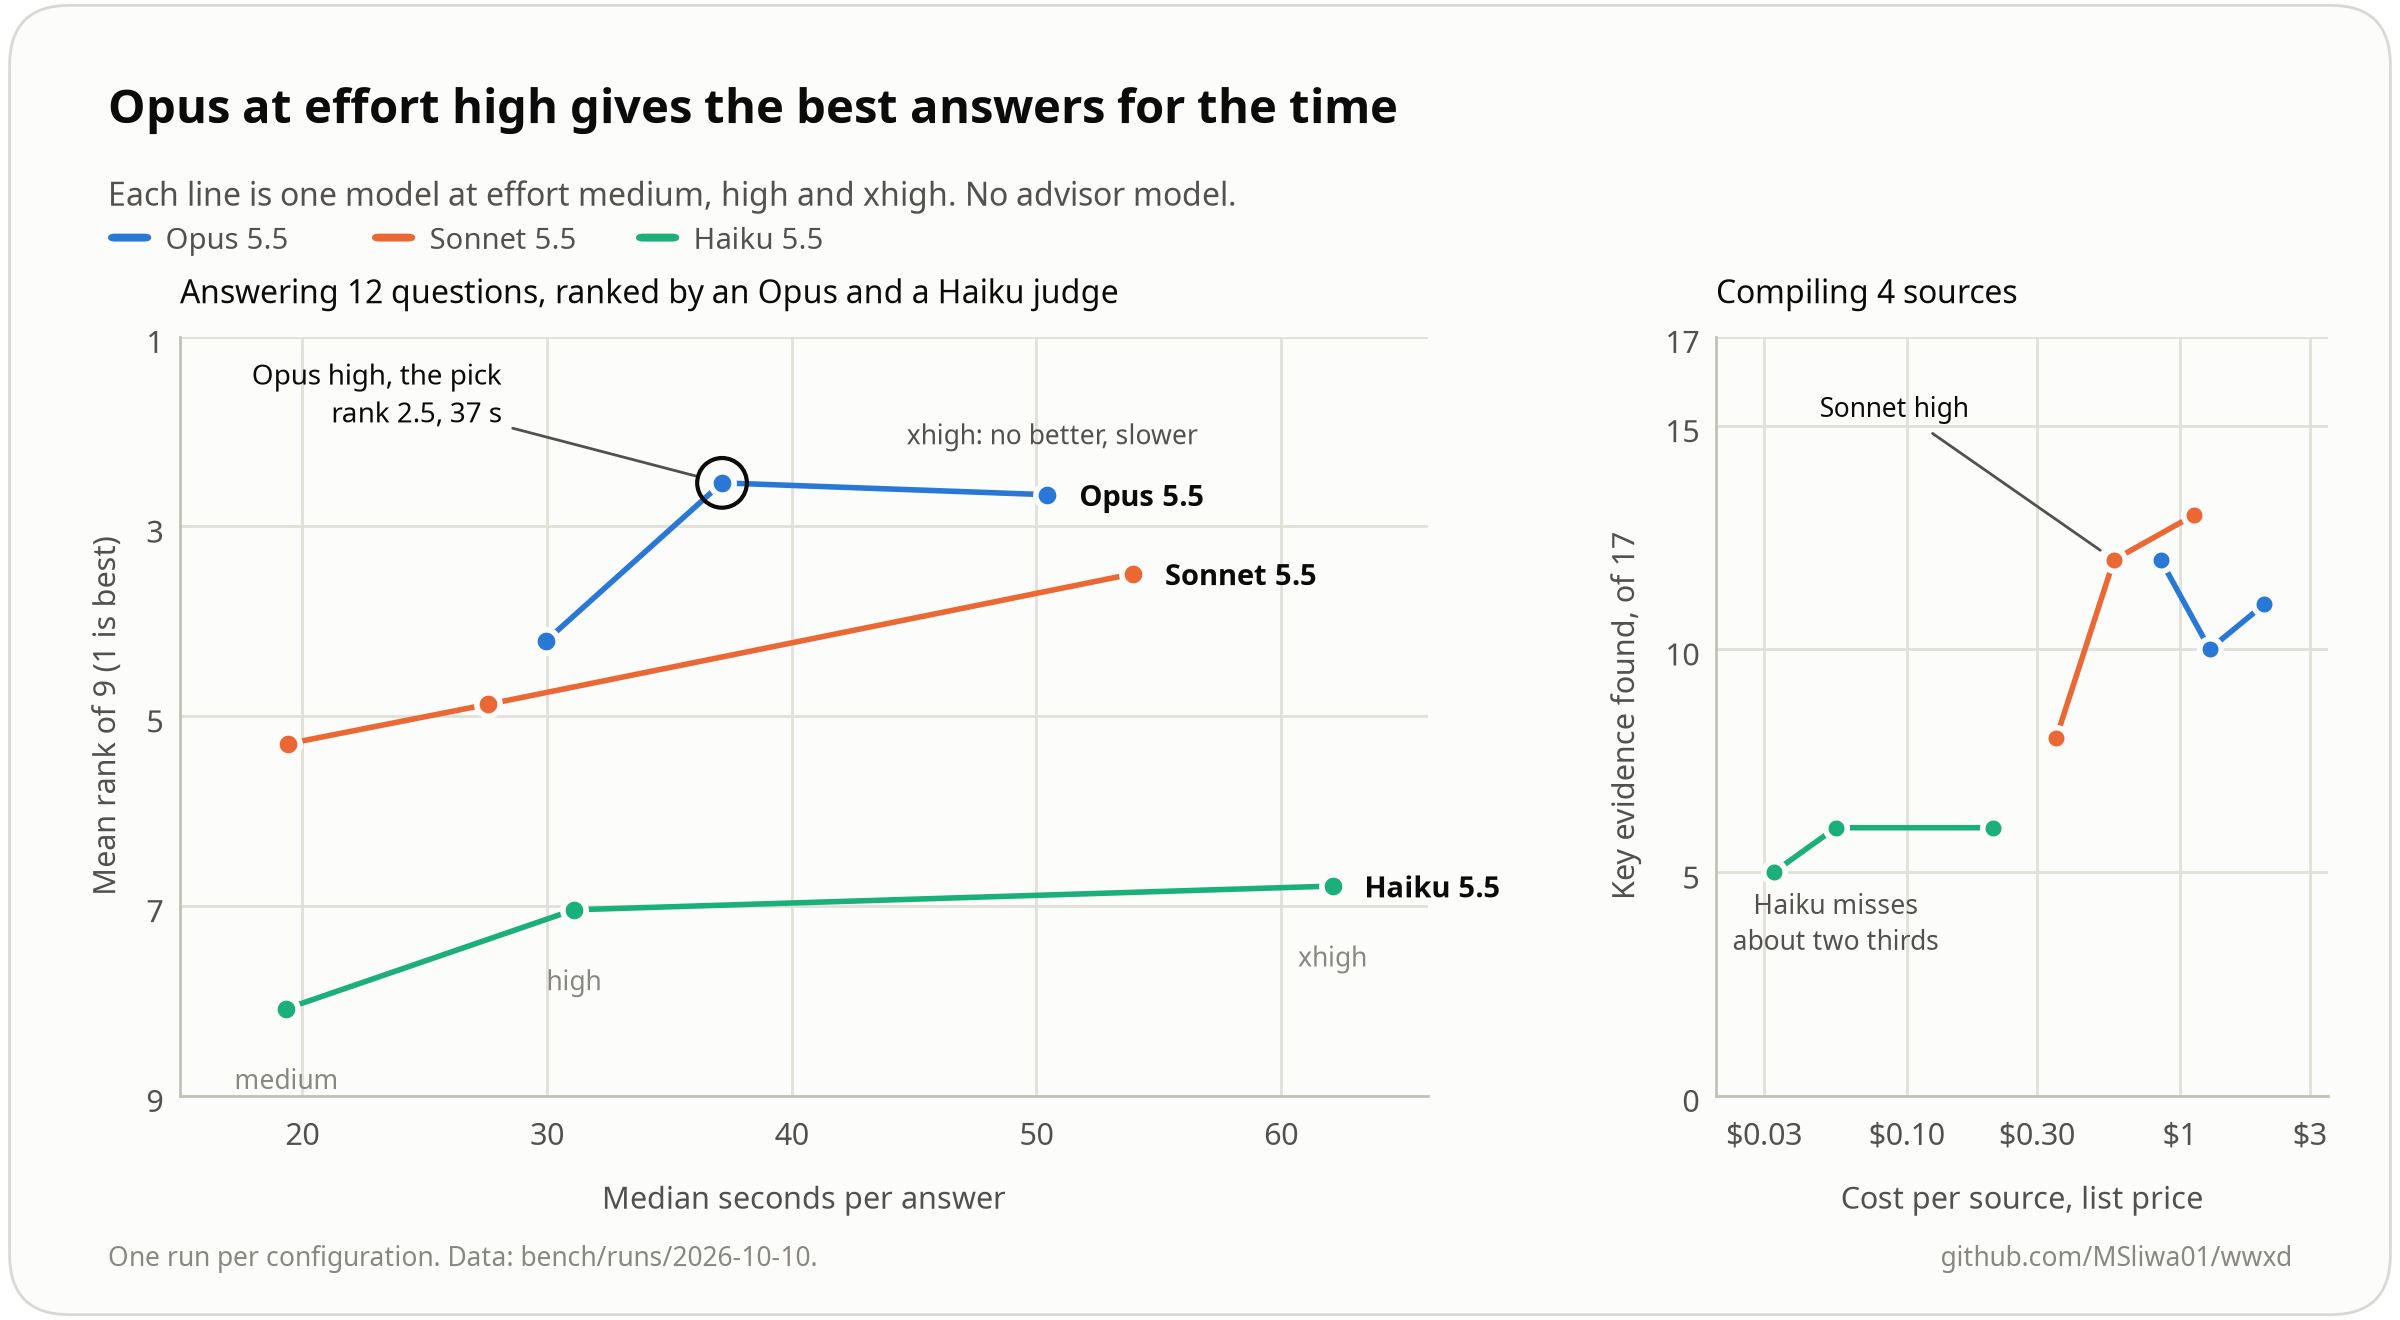
We compared Opus 5.5, Sonnet 5.5 and Haiku 5.5 at Claude Code effort medium, high and xhigh, for both compiling and answering, with no advisor.
| Job | Use | Why |
|---|---|---|
| Compile | Sonnet high, or Opus medium if you're on Opus anyway | Both found 12 of the 17 key evidence quotes, and Sonnet high cost about two thirds as much. xhigh writes a denser vault for 2 to 3 times the time and cost but didn't find more of the key evidence. Haiku missed about two thirds of it. |
| Answer | Opus high | Opus xhigh wasn't clearly better and took longer. On a tighter budget, Sonnet xhigh ranked about as well as Opus medium. Haiku ranked last at every effort and got about 1 quote in 20 wrong. |
| Triage | A cheap model | See Use a cheaper model for triage. |
You don't need an advisor model. Numbers and limits are in bench/RESULTS.md.
Example recipes
wwxd examples lists them. A recipe is a source config, never content.
| Recipe | Topics | Notes |
|---|---|---|
yc |
startups | A group vault covering Paul Graham, Jessica Livingston, Michael Seibel, Dalton Caldwell, Garry Tan and Sam Altman, plus PG's essays. |
hormozi |
business, sales, pricing | Long-form videos and podcast appearances. |
naval |
wealth, philosophy | His podcast feed and posts. |
karpathy |
learning, AI | Lectures, blog, interviews. |
rams |
design | Few English sources, so expect a small vault. |
These are starting points, not endorsements. You don't have to agree with any of these people. The vault worth building is the one for the person you learn from.
Use a cheaper model for triage
Deciding which candidate videos to keep only needs titles, channels and durations. A small, cheap model does it well. In our test, a free model triaged 39 candidates for the Dieter Rams vault in 20 seconds, and its picks held up on review. Keep the strong model for compiling and answering. That's where attribution happens, and lint can catch an invented quote but not a real quote credited to the wrong person.
Keep a vault current
People keep publishing, so a vault goes stale. wwxd update finds new sources.
--approve-hint own approves the new ones from the person's own channels and feeds,
and --fetch downloads them. Candidates you left pending before stay pending, and
the other new ones wait for your review.
A weekly cron line covers the CLI part.
# Mondays at 7:00
0 7 * * 1  WWXD_HOME=$HOME/vaults $HOME/.local/bin/wwxd update hormozi --approve-hint own --fetch >> $HOME/vaults/hormozi-update.log 2>&1
Compiling needs an agent. A Claude Code scheduled agent (/schedule) can run the
whole loop. It needs wwxd installed and access to the vault. Give it a prompt like
this one.
Keep the hormozi wwxd vault current. Run
wwxd update hormozi --approve-hint own --fetch, and list the other new candidates for me without approving them. Compile every source inwwxd pending hormoziwith the wwxd skill (references/compile.md), runningwwxd lint hormoziandwwxd mark-compiledafter each one. Then runwwxd health hormozi, and if it asks for a consolidation pass, follow references/consolidate.md. Finish withwwxd digest hormozi --days 7and show me the digest.
wwxd digest writes a markdown note on what's new: the sources compiled, the leaves
created or updated, and new statements grouped by leaf. --out saves it, for
example into your notes app's folder.
CLI
| Command | What it does |
|---|---|
wwxd new <slug> --example X or --name "Full Name" |
Create a vault |
wwxd discover <slug>, wwxd update <slug> |
Find new candidate sources |
wwxd update <slug> --approve-hint own --fetch |
Also approve new candidates with that hint and fetch them |
wwxd sources <slug> --status candidate |
List sources |
wwxd approve <slug> <ids>, wwxd reject <slug> <ids> |
Curate |
wwxd add <slug> <url or file> |
Add a source by hand |
wwxd fetch <slug> |
Download captions, transcripts and articles into raw/ |
wwxd pending <slug> |
Sources fetched but not compiled |
wwxd mark-compiled <slug> <id> |
Record a compiled source in log.md |
wwxd lint <slug> |
Check quotes, citations, attribution and links, and flag drift such as near-duplicate leaves |
wwxd health <slug> |
Report on the wiki: size, attribution, coverage, near-duplicates, oversize leaves |
wwxd timeline <slug> [query] |
Statements by source date and member, to see how views changed |
wwxd digest <slug> --since YYYY-MM-DD |
Markdown note on what's new since a date |
wwxd search <slug> "query" |
Keyword search over the wiki (--raw adds transcripts) |
wwxd status <slug> |
Summary |
wwxd voice <slug> [ids] |
Check who is speaking in each quote, by voice (needs wwxd[voice]) |
wwxd doctor |
Check yt-dlp, the JS runtime, ffmpeg, Whisper and $WWXD_HOME |
wwxd bench run, judge, report |
Benchmarks |
Vaults are plain markdown folders and open in Obsidian. $WWXD_HOME sets where they
live (default ./vaults).
Sources and copyright
wwxd fetches public captions, articles and podcast audio for your own use. It doesn't
fetch books, and this repo ships no content. You can add books you own as text files
(wwxd add <slug> book.txt) or write a fetcher plugin.
Don't publish vaults built from material you don't have the right to share.
ETHICS.md has the rules for using vaults and explains how a person can
have their recipe removed.
Requirements
Run wwxd doctor to check your setup. It marks each item below OK, WARN or FAIL and
makes no network calls.
- Python 3.10 or newer.
- A JavaScript runtime for YouTube: deno, node 22 or newer, or bun. wwxd picks the first of these on your PATH for yt-dlp. Without one, some videos lose formats or fail.
- Whisper, for sources without captions. Most podcasts need it, unless the feed
publishes transcripts (
podcast:transcripttags), which wwxd uses instead. Whisper runs on CPU, and much faster on a GPU. wwxd picks the model for you, large-v3-turbo on a CUDA GPU and small on CPU.WWXD_WHISPER_MODELandWWXD_WHISPER_DEVICEset the defaults, andwwxd fetch --whisper-model large-v3changes the model for one run. - Browser cookies, only if YouTube asks you to sign in. Set
WWXD_COOKIES_FROM_BROWSER=firefox(orchrome:Profile 1), or pass--cookies-from-browsertodiscover,updateorfetch.
When YouTube rate limits a fetch (HTTP 429), wwxd waits and retries up to 3 times, at most a minute apart.
Roadmap
- A read-only MCP server for chat apps
- Word-level timings for Whisper transcripts, so the voice check is as precise on podcasts as it is on YouTube captions
- Tree versus flat layout results in the bench
- Fetchers for X threads and Substack archives
Credits
The raw-sources-plus-compiled-wiki loop is Andrej Karpathy's LLM wiki idea. wwxd adds sourcing, speaker attribution and quote checking for the one-person case. Design notes are in docs/design.md. MIT licensed.
1 maintainer

Metadata
1 maintainer
Release files for wwxd 0.1.0
For a detailed explanation of source distributions (sdists) and built distributions (wheels), please see the package formats documentation.
Source distribution (sdist)
| File | Size | Uploaded | |
|---|---|---|---|
| wwxd-0.1.0.tar.gz | 1.9 MB | Details |
Built distribution (wheel)
| File | Interpreter | ABI | Platform | Reset |
|---|---|---|---|---|
| wwxd-0.1.0-py3-none-any.whl | Python 3 | none | any | Details |
Total release size: 2.0 MB
Release files / wwxd-0.1.0.tar.gz
| Download URL | wwxd-0.1.0.tar.gz |
|---|---|
| Size | 1.9 MB |
| Tags | Source |
|
SHA-256 checksum How to use checksums |
5e50363433a61fbeaa606acef10cce2b4dc79b103fffaee01e632ad8c3ba2b1f
|
|
BLAKE2b-256 checksum How to use checksums |
d418eae16b462bb6ef1103cfcd75f84e36dbee09e8b236f921c8b253fe556017
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
Yes |
| Uploaded via |
twine/7.0.0 CPython/3.13.14
|
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.


PyPI Publish Attestation
PyPI verified that this artifact, at this checksum, originated from the publisher listed below.
Signed by GitHub Actions, verified by PyPI on Oct 10, 2026.
Transparency logRelease files / wwxd-0.1.0-py3-none-any.whl
| Download URL | wwxd-0.1.0-py3-none-any.whl |
|---|---|
| Size | 95.7 kB |
| Tags | Python 3 |
|
SHA-256 checksum How to use checksums |
30cfcc5b24f9f5a77995970add9a933e5a47d975f91a4dee47d9723ac67ba56e
|
|
BLAKE2b-256 checksum How to use checksums |
e5a41982adfdf7df69752129dc93604bbebfa87a29602febcee42af9fa477587
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
Yes |
| Uploaded via |
twine/7.0.0 CPython/3.13.14
|
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.
PyPI Publish Attestation
PyPI verified that this artifact, at this checksum, originated from the publisher listed below.
Signed by GitHub Actions, verified by PyPI on Oct 10, 2026.
Transparency log












