
This release is a pre-release and may not be stable for production use.
Xaytune
Xaytune is an agent-native experiment control plane for model post-training and adaptation.
It records what an experiment is testing, compiles each candidate into a plan a trainer can run, submits that plan to a runtime, and keeps a durable record of everything that happened. That record is what lets a restarted controller pick up running work instead of losing it or starting it twice. The question it is built to answer is:
What should this training experiment do next?
Xaytune controls the experiment. Trainer integrations compile training intent. Runtime integrations execute it. Infrastructure schedules and runs the workloads.
Documentation | Control-plane getting started | Examples | Architecture specification
Alpha.
1.0.0a2is the second pre-release of the control plane: declare an experiment, and it trains, evaluates, decides, plans and branches to the next candidate on its own, on a durable record. It is a pre-release, sopip install xaytunestill installs0.6.0; see Install. Expect the control-plane API to change before1.0.0. The trainer library from0.6.0is still included, as the Legacy trainer API.
What Xaytune owns, and what it delegates
| Xaytune owns | Today |
|---|---|
| Experiment lifecycle and durable controller state | Available |
| Candidate identity and scientific lineage | Available |
| Training orchestration across trainer backends | Available: Native and TRL, on a local runtime |
| Evaluation orchestration | Available: the built-in native evaluator, and lm-eval benchmark tasks pinned at submission (on main, unreleased) |
| Decisions and branching | Decisions available: deterministic thresholds on the objective; branching planned |
| Resilience policy and semantic recovery | Planned |
| Policy gates, budgets and agent-driven control | Budgets available: runs, failures and parallel runs, on a durable ledger (on main, unreleased); policy gates and agent control planned |
| Xaytune delegates |
|---|
| Tensor execution and distributed training |
| Worker management and second-scale worker recovery |
| GPU scheduling and infrastructure admission |
| Cluster and Kubernetes workload execution |
The boundary is experiment topology, not GPU count. Xaytune may control a large distributed training job while the runtime stays responsible for distributed tensor execution and for recovering individual workers.
Available today
Status as of 1.0.0a2.
- A durable record. SQLite persistence with versioned migrations and
optimistic concurrency. Every state change commits in one transaction with
its event and outbox entry. A
RuntimeOperationjournal records every external effect before it is attempted. Cancellation is a recorded Action whose outcome is also recorded. - Candidates with identities.
CandidateSpecdeclares everything that changes what a model learns.CandidateFingerprintis a versioned projection of it, so later schema additions cannot silently change the identity of candidates already recorded. - Compilation.
TrainerCompilerturns a candidate into a serializableTrainingExecutionSpecand never executes anything.NativeCompilerandTRLCompilercover full-parameter SFT. A candidate that leaves a training-relevant value to a trainer default is refused, with every reason listed. - A restart-safe local runtime.
LocalRuntimeruns workers as separate processes and streams versioned telemetry. It takes submissions throughsubmit_or_get, so re-submitting under the same operation id returns the existing workload instead of starting a new one. - An embedded controller.
EmbeddedControllerHost.submit()returns anExperimentHandlewithstatus,wait,cancelandevents. A new process canattach()to the experiment and adopt its running workload, without orphaning it or submitting it twice. - Durable evaluation, with a built-in evaluator. An
ExperimentSpeccan name anEvaluationSpec. After training, the host evaluates the trained model through the same journal, runtime and telemetry, records the result, and moves the candidate toDECIDING. Evaluation runs, attempts, results and cycles survive a restart. The built-innativeevaluator measures next-token loss, perplexity and token accuracy on a local held-out file pinned by its content digest. An evaluation it cannot run exactly as declared is refused at submission, before anything trains. - Durable decisions. Once a candidate is evaluated, a decision engine
decides it from the record alone: the experiment's objective and that
evaluation's results. The built-in engine compares the recorded values with
the objective's target and constraints. A target met gives a
COMPLETEDcandidate and aSUCCEEDEDexperiment, which names it as its best candidate. A target missed givesREJECTEDandFAILED. A violated constraint rejects the candidate but leaves the experiment open for another. The decision is recorded, with the evidence and a fingerprint of its inputs, in the same commit that applies it. A candidate it cannot decide (no target, a missing metric) staysDECIDING, with the reason recorded; nothing is guessed. - The adaptive loop. A missed target can branch instead of failing
(
AdaptiveThresholdDecisionEngine). ARuleBasedPlannerproposes the next candidate from the record, branching records it as a child node with its proposal's provenance, and the controller trains it, all from one submission and after any restart. - Budgets, policy and approval. Run, failure, parallelism and wall-time
limits on an append-only ledger. Typed, versioned actions are validated and
judged by a
PolicyEngine, with human approval when it asks for one. - Incidents, checkpoints and recovery. Failures are classified into durable incidents. A CUDA OOM is recovered by a governed micro-batch resize that resumes from an exact checkpoint, and a numerical blow-up by a governed learning-rate intervention on the same run.
- A local daemon and CLI.
python -m xaytune.daemonruns a controller with a durable lease;xaytune submit,attach,status,watch,events,results,actions,cancel,approveandrejecttalk to it. - Ray, KubeRay, Ray Tune and TorchFT.
RayJobsRuntimeandRayTrainRuntimerun on an existing Ray cluster or as KubeRayRayJobs.RayTuneSearchProviderproposes candidates. TorchFT is a checked resilience request on a training plan, which no built-in runtime hosts yet. - An LLM planner, audited.
LLMPlannerproposes typed actions through theAgentModelboundary, and every model call is a durable record. Its proposals are recorded and escalated, never carried out. - Studio.
xaytune studio-webserves a read-only HTTP API over the record and a React client: the candidate graph, runs with their loss charts, decisions, actions, budget, incidents and comparisons. - Agent harness building blocks, local only. Harness candidates and their identity, a compiler and deterministic runner, pinned benchmarks, trajectory artifacts, harness evaluation and a local harness search. A harness cannot yet be submitted to a controller.
- Upgrade safety. A build refuses a state database that a newer Xaytune migrated, before reading or writing it.
- A reproducible environment.
uv.lockpins every dependency, and a CI job tests the locked environment. The TRL worker refuses any TRL or Transformers release it has not been classified against.
Seen from a caller:
from xaytune.experiment import EmbeddedControllerHost

host = EmbeddedControllerHost("xaytune-workdir/state.db")
handle = await host.submit(spec)        # spec: an ExperimentSpec
result = await handle.wait()            # quiescent: every piece of work is settled
print(result.status, result.next_stage) # SUCCEEDED, None once evaluated and decided
wait() returns when the controller has nothing left it can run, which is not
the same as the experiment being finished. The result says which stage would
run next, if any. See
the control-plane examples for runnable code.
Planned
In the order the implementation plan builds them:
- Durable harness execution: harness candidates as experiment nodes, their attempts and runtime execution, through the same controller.
- Durable harness evaluation and search: H06 evaluations and H07 proposals on the record, branched like training candidates.
- Budgets on what nothing measures yet (GPU-hours, tokens, cost).
- Decisions that compare candidates: promotion, and noise-aware comparison across replicates.
- Hosting TorchFT in Ray Train, and Training Hub.
None of these exist yet, and nothing in this repository should be read as claiming they do.
Architecture
The target architecture keeps scientific intent, compilation, capability resolution and execution separate. The diagram shows the status after PR-015: solid green boxes were implemented then, dashed boxes planned; Available today is current. The runtime feedback path is separate from the path that submits work.
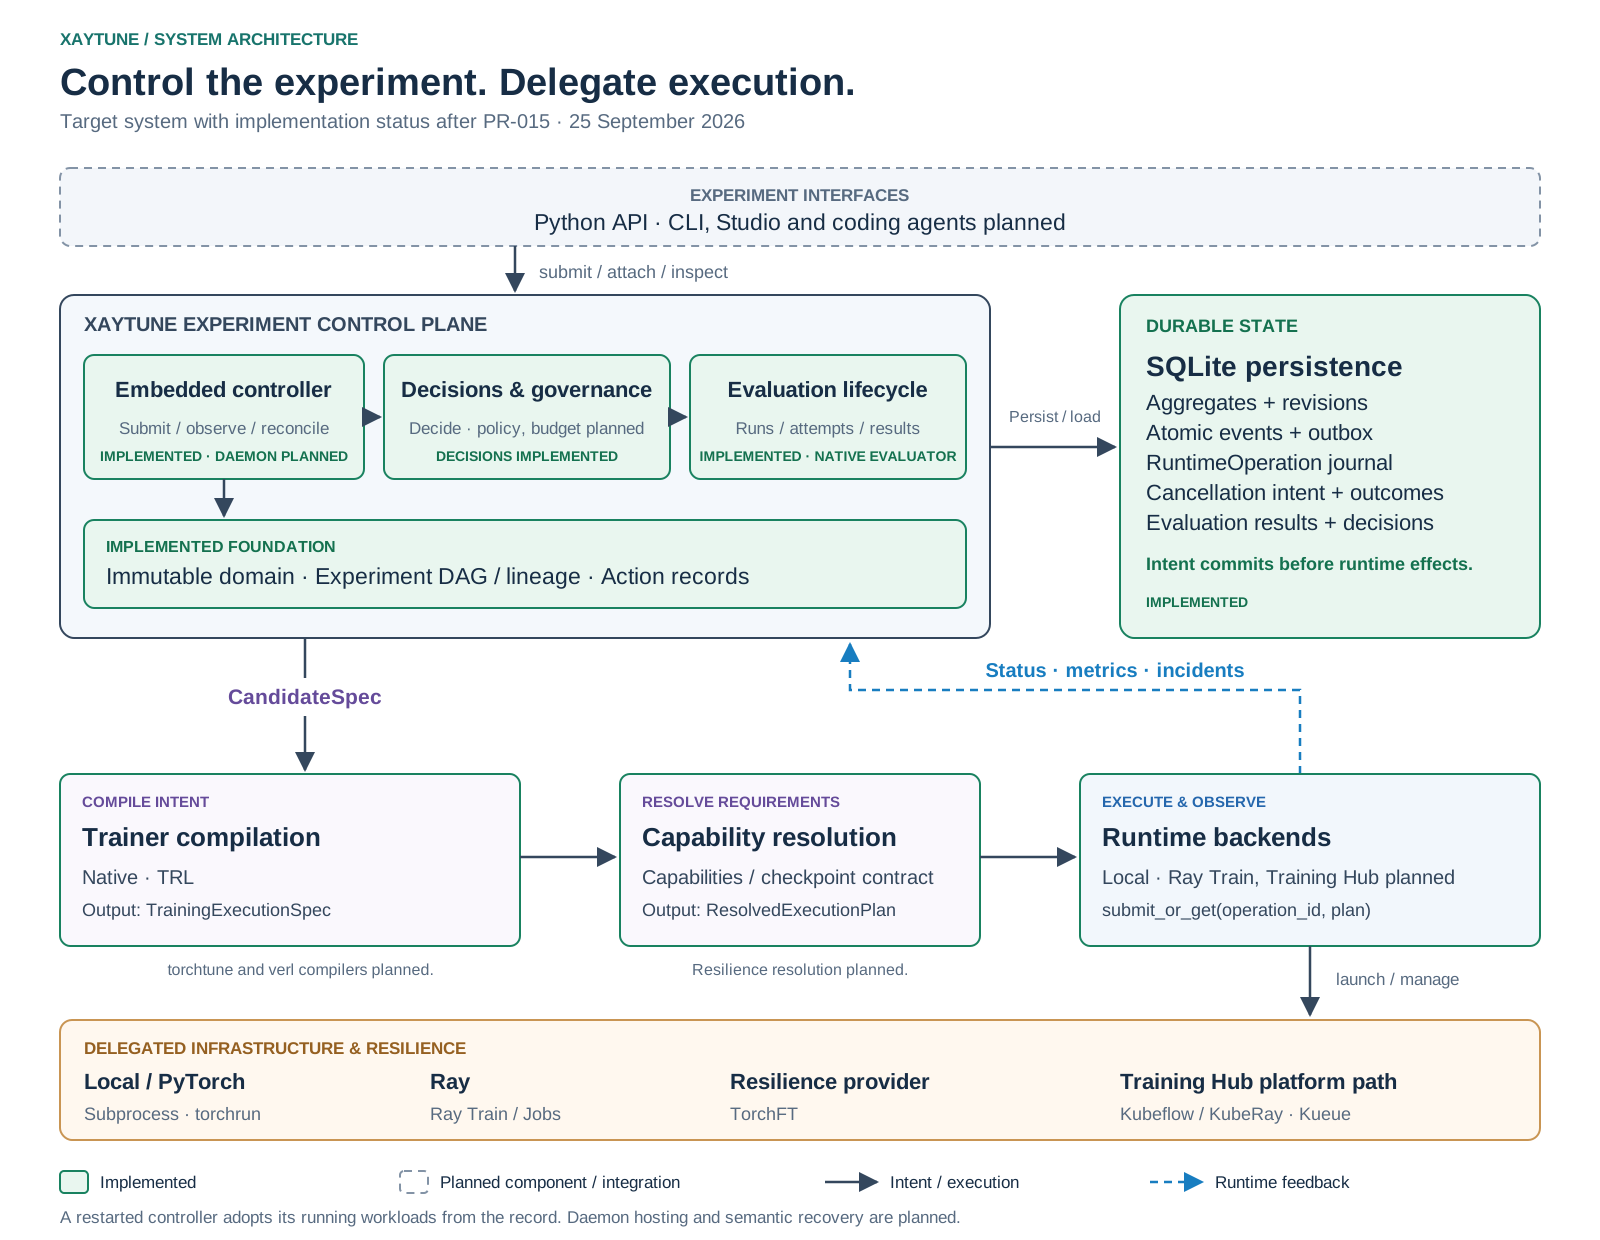
See the architecture specification for protocol and dependency boundaries.
Implementation history
Persistence (band B): SQLite repository (#18), events, outbox, and journal (#19), Action substrate (#20), experiment graph (#21), persistence hardening (#22).
Compile/execute (band C): CandidateSpec and fingerprints (#24), compile/execute contracts (#25), LocalRuntime (#26), telemetry contracts (#27), NativeCompiler and NativeWorker (#28), TRLCompiler and TRLWorker (#29), EmbeddedControllerHost and ExperimentHandle (#30), runtime-operation reconciliation (#31), dependency reproducibility (#32).
Evaluation (band D): durable evaluation lifecycle (#33).
Roadmap
| Architectural band | Status |
|---|---|
| A — domain foundation | Complete |
| B — persistence and control records | Complete |
| C — compile/execute, local runtime, runtime reconciliation | Complete |
| D — durable evaluation and decisioning | Complete: lifecycle, native and lm-eval evaluators, threshold and adaptive decisions |
| E — policy and budget over the Action substrate | Complete: budget ledger, typed actions, policy and approval |
| F — checkpoints, semantic recovery, interventions | Complete: incidents, checkpoints, CUDA OOM and numerical recovery |
| G — rule-based planner and experiment branching | Complete: the adaptive loop |
| H — daemon hosting and whole-controller restart | Complete: local daemon, durable lease, CLI |
| I — LLM planner | Complete for proposals and audit; its actions are escalated, not carried out |
| J — Ray / TorchFT / Training Hub integrations | Ray, KubeRay and Ray Tune complete; TorchFT as a request only; Training Hub planned |
| Harness track (H02–H07) | Local building blocks complete; durable execution in progress (ADR-019 M1–M6) |
Install
pip install "xaytune==1.0.0a2"          # the control plane, and the legacy trainer API
pip install "xaytune[trl]==1.0.0a2"     # adds the TRL trainer
1.0.0a2 is a pre-release, so pip installs it only when asked: by version, as
above, or unpinned with pip install --upgrade --pre xaytune (--upgrade
matters where 0.6.0 is already installed, which pip would otherwise keep). A
plain pip install xaytune still installs 0.6.0, the legacy trainer API
alone.
To install exactly what CI tests, or to work on Xaytune, install from a clone:
git clone https://github.com/szaher/xaytune && cd xaytune
uv sync --locked                # or: pip install -e .
uv sync --locked --extra trl    # adds the TRL trainer; or: pip install -e ".[trl]"
import xaytune does not import torch, transformers or TRL. The control plane
imports without them, and training runs in separate worker processes that do.
Legacy trainer API
Xaytune began as an opinionated PyTorch training library, and that library is
still here: finetune, pretrain, align, evaluate, the xaytune CLI, and
multi-stage pipelines. It is what PyPI's 0.6.0 contains, and 1.0.0a2 still
includes it. It stays available
through the transition, and its trainer is what NativeCompiler runs, behind
the new compile/execute boundary.
The maturity labels in this section refer to this trainer library, not to the control plane.
Core (tested, recommended for use):
- SFT fine-tuning — full, LoRA, QLoRA with proper prompt masking (only response tokens contribute to loss)
- Multi-turn conversation masking — per-turn label masking for chat and ShareGPT formats
- DPO alignment — Direct Preference Optimization with response-only log-probability scoring
- GRPO alignment — Group Relative Policy Optimization, reference-model-free by default
- 5 data formats — Alpaca, ShareGPT, OpenAI chat, raw text, preference pairs
- Multi-stage pipelines — chain SFT → merge → DPO → eval → export in a single command
- Evaluation — built-in metrics (loss, perplexity, token accuracy) + lm-eval-harness benchmarks
- Export — merge LoRA adapters, push to HuggingFace Hub
- Config system — YAML configs with inheritance, CLI overrides, Pydantic validation
- Callbacks — event-driven hooks for checkpointing, early stopping, progress, custom logic
- 4 logging backends — console, TensorBoard, W&B, MLflow
Experimental (limitations vary; see Maturity):
- ORPO / SimPO alignment — implemented with numerically stable loss, needs real-world validation
- REINFORCE alignment — vanilla policy gradient, functional but minimal
- PPO — value head, rollout buffer, and multi-epoch training; requires online RL
- Online RL — generate→score→train pipeline for RL methods
- DeepSpeed — partial ZeRO integration; optimizer/scheduler and checkpoint ownership remain open (TASK-029)
- FSDP — wrapping with sharding strategy, CPU offload, mixed precision
- GGUF conversion — delegates to llama.cpp tools (requires separate installation)
- Model merging — Linear, SLERP, TIES, DARE weight interpolation
- Agent fine-tuning — tool-use data formats with per-message loss masking
- Training Studio — Gradio web UI for configuring and launching runs
- Data preparation — generate, filter, deduplicate, convert pipeline
Legacy quickstart
pip install xaytune installs it (0.6.0), as does 1.0.0a2; optional extras include
[wandb], [mlflow], [tensorboard], [deepspeed], [eval] (lm-eval-harness),
[studio] and [all]. The notebooks in examples/ use this API.
Python API
import xaytune

# LoRA fine-tuning (prompt tokens masked, trains on response only)
state = xaytune.finetune(
    model="meta-llama/Llama-3.1-8B",
    dataset="data/train.jsonl",
    method="lora",
    format="alpaca",
    num_epochs=3,
)

# DPO alignment (response-only log-prob scoring)
state = xaytune.align(
    model="output/sft-model",
    dataset="data/preferences.jsonl",
    method="dpo",
    format="preference",
)

# Evaluation
results = xaytune.evaluate(
    model="output/my-model",
    dataset=[{"input_ids": [1, 2], "labels": [1, 2]}],
    metrics=["loss", "perplexity", "token_accuracy"],
)
Multi-Stage Pipeline
Chain training stages in a single command:
# pipeline.yaml
name: sft-to-aligned
output_dir: output/pipeline
stages:
  - name: sft
    recipe: finetune
    method: lora
    model_name: "meta-llama/Llama-3.1-8B"
    data: { path: "data/train.jsonl", format: alpaca }
    trainer: { num_epochs: 3, learning_rate: 2e-4 }

  - name: merge
    export: merge

  - name: dpo
    recipe: align
    method: dpo
    data: { path: "data/prefs.jsonl", format: preference }
    trainer: { num_epochs: 1, learning_rate: 5e-6 }

  - name: eval
    eval: { metrics: [loss, perplexity], benchmarks: [mmlu] }
xaytune pipeline --config pipeline.yaml
xaytune pipeline --config pipeline.yaml --dry-run
xaytune pipeline --config pipeline.yaml --resume-from dpo
CLI
# Train
xaytune train --config configs/examples/lora_finetune.yaml
xaytune train --config configs/examples/lora_finetune.yaml --override model.name=mistralai/Mistral-7B-v0.3

# Evaluate
xaytune eval --model output/my-model --benchmarks mmlu,gsm8k
xaytune eval --model output/my-model --dataset data/eval.jsonl --metrics loss,perplexity

# Export
xaytune export merge --checkpoint output/lora-ckpt --output output/merged
xaytune export push --model output/merged --repo username/my-model

# Distributed training
xaytune launch --config configs/examples/lora_finetune.yaml --nproc-per-node 4

# Training Studio (experimental)
xaytune studio --port 7860
Config file
recipe: finetune
method: lora

model:
  name: meta-llama/Llama-3.1-8B

data:
  path: data/train.jsonl
  format: alpaca
  eval_split: 0.05
  packing: true
  max_seq_length: 2048

lora:
  rank: 16
  alpha: 32

trainer:
  batch_size: 4
  learning_rate: 2e-4
  num_epochs: 3
  mixed_precision: bf16
  checkpoint_every_n_steps: 500

eval:
  every_n_steps: 500
  metrics: [loss, perplexity]

logging:
  backends: [console, tensorboard]
Recipes
| Recipe | Methods | Use case |
|---|---|---|
finetune |
full, lora, qlora |
Supervised fine-tuning on instruction data |
pretrain |
full |
Pre-training or continued pre-training on raw text |
align |
dpo, grpo |
Alignment with human preferences (recommended) |
align |
orpo, simpo, reinforce, ppo |
Alignment (experimental — see Maturity) |
Maturity
| Feature | Status | Notes |
|---|---|---|
| SFT (full/LoRA) | Stable | Prompt masking, multi-turn, sequence packing |
| QLoRA | Stable | Uses prepare_model_for_kbit_training |
| DPO | Stable | Response-only log-probs, frozen reference model |
| GRPO | Stable | Reference-model-free, optional KL via kl_coeff |
| Multi-stage pipeline | Stable | Sequential chaining with auto-inheritance |
| Evaluation | Stable | Metrics + lm-eval benchmarks |
| Export (merge, Hub push) | Stable | LoRA merge, HF Hub push |
| Config system | Stable | YAML, inheritance, Pydantic validation |
| Callbacks + logging | Stable | 4 backends, exception isolation |
| ORPO | Experimental | Numerically stable, needs real-world validation |
| SimPO | Experimental | Length-normalized, reference-free |
| REINFORCE | Experimental | Vanilla policy gradient |
| PPO | Experimental | Full PPO trainer with value head, rollout buffer, multi-epoch training. Requires online_rl.enabled=True |
| DeepSpeed | Experimental / partial | Optimizer/scheduler and checkpoint ownership remain open; see TASK-029 |
| FSDP | Experimental | Sharding, offload, mixed precision wrapping |
| GGUF export | Experimental | Requires llama.cpp tools installed separately |
| Model merging | Experimental | TIES, DARE, SLERP, linear interpolation |
| Agent fine-tuning | Experimental | Tool-use formats with per-message masking |
| Training Studio | Experimental | Gradio UI for job configuration and launch |
| Data preparation | Experimental | Generate, filter, deduplicate, convert |
| Online RL | Experimental | Generate→score→train for RL methods |
Extensibility
Register custom components with decorators:
from xaytune.data import register_format
from xaytune.eval import register_metric
from xaytune.recipes.align.rewards import register_reward
from xaytune.trainer import on

@register_format("my-format")
def parse_my_data(sample):
    return {"text": f"Q: {sample['q']}\nA: {sample['a']}"}

@register_metric("domain-accuracy")
def domain_accuracy(predictions, references, **kwargs):
    return sum(p == r for p, r in zip(predictions, references)) / len(predictions)

@register_reward("brevity")
def brevity_reward(prompt, response, *, max_len=100):
    return 1.0 if len(response) <= max_len else 0.0

@on("step_end")
def log_memory(state):
    print(f"Step {state.global_step}: loss={state.metrics.get('loss', 'N/A')}")
License
Apache 2.0
1 maintainer

Metadata
1 maintainer
Release files for xaytune 1.0.0a2
For a detailed explanation of source distributions (sdists) and built distributions (wheels), please see the package formats documentation.
Source distribution (sdist)
| File | Size | Uploaded | Provenance | |
|---|---|---|---|---|
| xaytune-1.0.0a2.tar.gz | 1.4 MB | With provenance | Details |
Built distribution (wheel)
| File | Interpreter | ABI | Platform | Reset |
|---|---|---|---|---|
| xaytune-1.0.0a2-py3-none-any.whl | Python 3 | none | any | Details |
Total release size: 3.0 MB
Release files / xaytune-1.0.0a2.tar.gz
| Download URL | xaytune-1.0.0a2.tar.gz |
|---|---|
| Size | 1.4 MB |
| Tags | Source |
|
SHA-256 checksum How to use checksums |
b91778504f6d51da237132f1de83b6d6983a3a35d8c2275641229174acb98924
|
|
BLAKE2b-256 checksum How to use checksums |
ff2b1c6d6de18f12d50fda080554dacd8d21b4ed8e3486f33dc73fd8e9b215c0
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
Yes |
| Uploaded via |
twine/7.0.0 CPython/3.13.14
|
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.


PyPI Publish Attestation
PyPI verified that this artifact, at this checksum, originated from the publisher listed below.
Signed by GitHub Actions, verified by PyPI on Oct 18, 2026.
Transparency logRelease files / xaytune-1.0.0a2-py3-none-any.whl
| Download URL | xaytune-1.0.0a2-py3-none-any.whl |
|---|---|
| Size | 1.6 MB |
| Tags | Python 3 |
|
SHA-256 checksum How to use checksums |
8363e8badfab798933b3107be24cbaa798230279105b7d337ce0f5de047f8738
|
|
BLAKE2b-256 checksum How to use checksums |
1114dabfb9c66cb536c7350fc5fe6e3193a17aa85e0c0b8726f59bf16274b388
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
Yes |
| Uploaded via |
twine/7.0.0 CPython/3.13.14
|
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.
PyPI Publish Attestation
PyPI verified that this artifact, at this checksum, originated from the publisher listed below.
Signed by GitHub Actions, verified by PyPI on Oct 18, 2026.
Transparency logSecurity for xaytune 1.0.0a2
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.
Full provenance
All 2 files in this release have been uploaded with provenance metadata.
Attestation for xaytune-1.0.0a2.tar.gz
PyPI Publish Attestation
PyPI verified that this artifact, at this checksum, originated from the publisher listed below.
Signed by GitHub Actions, verified by PyPI on Oct 18, 2026.
Transparency logA note on package security
PyPI is a repository for distributing packages, not a service for auditing them. While third-party security researchers and our staff do their best to detect and remove malicious packages, PyPI cannot guarantee the quality, security or suitability of any given package.














