
xlsxwriter-tables
Easily export nested data to Excel
This class is intended to be used with XlsxWriter. It serves several purposes:
- Co-location of column info and data-generation logic
- Easily specify deeply nested data as the source for column data
- Reference column headers dynamically in column formulas
The example.py file shows basic usage; excel_table.py is also thoroughly documented. I intend to document more examples of usage in the future.
API
Sample data
``` py
serialized_data = [
    {
        'alpha': {
            'oscar': True,
            'papa': {
                'romeo': State(
                    name='Alabama',
                    statehood_granted=date(1819, 12, 14),
                    symbols={
                        'bird': 'Yellowhammer',
                        'flower': 'Camellia',
                    },
                ),
                'sierra': State(
                    name='Georgia',
                    statehood_granted=date(1788, 1, 2),
                    symbols={
                        'bird': 'Brown Thrasher',
                        'flower': 'Cherokee Rose',
                    },
                ),
            }
        },
        'bravo': 22,
        'charlie': 4,
    },
    {
        'alpha': {
            'oscar': False,
            'papa': {
                'romeo': State(
                    name='Minnesota',
                    statehood_granted=date(1858, 5, 11),
                    symbols={
                        'bird': 'Common Loon',
                        'flower': 'Ladys Slipper',
                    },
                ),
                'sierra': State(
                    name='Wisconsin',
                    statehood_granted=date(1848, 5, 29),
                    symbols={
                        'bird': 'Robin',
                        'flower': 'Wood Violet',
                    },
                ),
            }
        },
        'bravo': 32,
        'charlie': 30,
    },
    {
        'alpha': {
            'oscar': None,
            'papa': {
                'romeo': State(
                    name='Maryland',
                    statehood_granted=date(1776, 7, 4),
                    symbols={
                        'bird': 'Baltimore Oriole',
                        'flower': 'Black-Eyed Susan',
                    },
                ),
                'sierra': State(
                    name='Virginia',
                    statehood_granted=date(1788, 6, 25),
                    symbols={
                        'bird': 'Cardinal',
                        'flower': 'Flowering Dogwood',
                    },
                ),
            }
        },
        'bravo': 7,
        'charlie': 10,
    },
]
```
Given the sample data above, we can generate an Excel table for export using XlsxWriter with the following code:
excel_table = ExcelTable(

    data=serialized_data,

    columns=dict(
        oscar='alpha.oscar',
        state_name='alpha.papa.romeo.name',
        statehood_granted='alpha.papa.romeo.statehood_granted',
        state_bird='alpha.papa.romeo.symbols.bird',
        state_flower='alpha.papa.romeo.symbols.flower',
        other_states_bird='alpha.papa.sierra.symbols.bird',
        bravo=None,
        charlie=None,
        average_bravo_charlie=dict(
            header='Avg of Bravo/Charlie',
            data_accessor=lambda item: None,
            formula='=AVERAGE({bravo}, {charlie})',
        ),
    )
)
Co-location of Column and Data Accessor Code
One advantage to this approach is that everything pertaining to a single column is in one place! The alternative approach force columns to be specified in one place, and data generated in another. This means that to make a change to a column or columns, you have to change it in multiple places. As the size of your tables grow, it becomes more difficult to maintain.
With this style, columns are defined with the logic used to generate the data in each row for that column. If columns need to be reordered, headers renamed, or additional info updated, there is only one place that these changes need to be made.
Easily Flatten Nested Data Into Row
The next advantage is that it provides a concise, readable style for accessing nested data by chaining properties together (dot-syntax is the default, but custom separators can be specified). This makes it much easier to spot inconsistencies across multiple columns, and identify why a cell is showing up blank or generating an AttributeError.
Unbreakable Formula References
With XlsxWriter, column formulas can be defined with references to other columns in the table (formula='=SUM([@Qty] * [@Price]). Hard-coding column headers is a bad idea, however, as this is subject to break if the referenced column header changes. In this case, it can be difficult to notice that a formula broke, especially in large Excel tables.
xlsxwriter-tables solves this by using the columns' keys to generate dynamic references to each column in column formulas. This approach will fail at runtime if the keys change, alerting you that a change needs to be made.
Nesting Classes and Dicts
The class is flexible enough to handle both class instances and dicts. Classes can be nested inside of dicts (romeo is an instance of State in the example). Likewise, dicts can be properties of class instances (symbols, a dict, is a property of each State instance). The same syntax is used to access nested values of both classes and dicts.
Field Separator Syntax
The default field separator is the dot (.), but custom characters can be specified. For instance, to assimilate Django's ORM-style "dunder" syntax for querying fields, use separator='__'. Columns would then use this like so:
...
separator='__',
columns=dict(
    oscar='alpha__oscar',
    state_name='alpha__papa__romeo__name',
    ...
Specifying column=None
In the simplest cases where the column key is also the top-level attribute that is desired, and the column key is the desired column header, set the column's value to None.
For example, these column definitions will generate the header, 'Bravo', and access data on each item using item.bravo (class) or item['bravo'] (dict):
bravo=None,
bravo={},
bravo=(),
AttributeErrors and KeyErrors
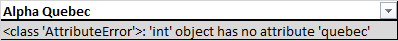
By default, if attributes or keys cannot be found, they fail gracefully - meaning they return the value None, and cell values for those fields are blank. This is useful for cases where the shape of each item is not expected to conform perfectly to the column schema.
For debugging purposes, or in other cases where the data is expected to be uniform, you can set raise_attribute_errors=True:
excel_table = ExcelTable(
    ...
    raise_attribute_errors=True,

    columns=dict(
        alpha_quebec='alpha.quebec',
        ...
    )
)
This will result in:
Other Exceptions
Any other error is printed to the cell in which it occurred, to help diagnose.
Column Header Text
The header attribute defaults to the title-cased dictionary key, unless a header is explicitly provided. For example:
THIS COLUMN                                 BECOMES THIS HEADER
-------------------------------------------------------------------
oscar=...,                              --> 'Oscar'
state_name=...,                         --> 'State Name'

average_bravo_charlie=dict(             --> 'Avg of Bravo/Charlie'
    header='Avg of Bravo/Charlie',
    ...
)
Additional Column Attributes
Column attributes can be supplied in each column's dictionary, following XlsxWriter's docs. With the exception of formula, these attributes simply get passed through to XlsxWriter.
Column Formulas
Formulas can be specified per XlsxWriter's docs. To dynamically reference the calculated column header of another column in a formula, use curly braces and the column's kwarg.
For instance, the following code for average_bravo_charlie...
bravo=None,
charlie=None,
average_bravo_charlie=dict(
    ...
    formula='=AVERAGE({bravo}, {charlie})',
),
...will generate this column formula:
'=AVERAGE([@[Bravo]], [@[Charlie]])
This means that changing the header text in a referenced column will not break the formula! Further, changing the column's kwarg will break the formula if it is not also updated. However, it will raise an error at runtime, rather than failing silently in the Excel file.
Saving to Excel
To save the data to an Excel file, use XlsxWriter's worksheet.add_table() method as usual.
The ExcelTable class automatically calculates the top, left, bottom, and right coordinates of the table based on the size of the data. These values are available in excel_table.coordinates as a tuple, making it easy to spread them into the add_table() call.
import xlsxwriter

workbook = xlsxwriter.Workbook('example.xlsx')

worksheet = workbook.add_worksheet()

excel_table = ExcelTable(...)

worksheet.add_table(
    *excel_table.coordinates,
    {
        'columns': excel_table.columns,
        'data': excel_table.data,
        'total_row': excel_table.include_total_row,
        ...
    }
)

workbook.close()
1 maintainer

Metadata
1 maintainer
Release files for xlsxwriter-tables 0.0.1
For a detailed explanation of source distributions (sdists) and built distributions (wheels), please see the package formats documentation.
Source distribution (sdist)
| File | Size | Uploaded | Provenance | Actions |
|---|---|---|---|---|
| xlsxwriter-tables-0.0.1.tar.gz | 8.2 kB | Without provenance | Details for xlsxwriter-tables-0.0.1.tar.gz |
Built distribution (wheel)
| File | Interpreter | ABI | Platform | Actions Reset |
|---|---|---|---|---|
| xlsxwriter_tables-0.0.1-py3-none-any.whl | Python 3 | none | any | Details for xlsxwriter_tables-0.0.1-py3-none-any.whl |
Total release size: 16.1 kB
Release files / xlsxwriter-tables-0.0.1.tar.gz
| Download URL | xlsxwriter-tables-0.0.1.tar.gz |
|---|---|
| Size | 8.2 kB |
| Tags | Source |
|
SHA-256 checksum How to use checksums |
4e62be129a77670ff1036a5151e6f16798098a391a9ba8bb41563fe02ce6b108
|
|
BLAKE2b-256 checksum How to use checksums |
7fa2bf179a33f997bc8fbd871b2a20b6501c2b20ac4df14703894887ade04bbd
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
No |
| Uploaded via |
twine/3.7.1 importlib_metadata/4.10.0 pkginfo/1.8.2 requests/2.27.1 requests-toolbelt/0.9.1 tqdm/4.62.3 CPython/3.9.0
|
Release files / xlsxwriter_tables-0.0.1-py3-none-any.whl
| Download URL | xlsxwriter_tables-0.0.1-py3-none-any.whl |
|---|---|
| Size | 7.9 kB |
| Tags | Python 3 |
|
SHA-256 checksum How to use checksums |
7d14233825e8b5b69bb202e497e804bd8c520d0c4c390666a8432d0508b85482
|
|
BLAKE2b-256 checksum How to use checksums |
7815420a9388982c94b7d653ae49c1d2168fea41a0fac951dd1ec41dff9b32cb
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
No |
| Uploaded via |
twine/3.7.1 importlib_metadata/4.10.0 pkginfo/1.8.2 requests/2.27.1 requests-toolbelt/0.9.1 tqdm/4.62.3 CPython/3.9.0
|
Security for xlsxwriter-tables 0.0.1
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.
No provenance found
None of the files in this release were uploaded with provenance metadata.
A note on package security
PyPI is a repository for distributing packages, not a service for auditing them. While third-party security researchers and our staff do their best to detect and remove malicious packages, PyPI cannot guarantee the quality, security or suitability of any given package.
To learn more about protecting yourself from malicious actors, visit our package security documentation.













