


Tabular foundation models
The usual way to predict something from a table (churn, fraud, default, demand) is to train a model for that problem: pick an algorithm, tune it, validate it, retrain it when the data changes.
Tabular foundation models work differently. They are pretrained once, on millions of synthetic datasets, to learn in context: you give them your labeled rows as context and they predict new rows in a single forward pass, with no training and no hyperparameters. On small and medium tables they are competitive with tuned gradient boosting.
Several research groups have released them: TabPFN (Prior Labs), TabICL (Inria), Mitra (Amazon), TabDPT (Layer 6) and others. Each comes with its own package, checkpoints, preprocessing and license.
What ZeroGrad does
ZeroGrad puts them behind one interface. The same two calls, create and predict, work with every model, on your
machine or on the ZeroGrad platform. On top of that:
- A championship instead of a guess. Which model is best depends on the data. ZeroGrad scores every model on the same holdout of your rows and keeps the best one as the champion, with the comparison in a table.
- Licenses you can see. Some models allow commercial use and some do not.
zerograd.list_models()shows each license and where the weights come from; non-commercial models stay off unless you enable them by name. - Local or cloud, same code. Locally, nothing leaves your machine. With
remote=Truethe same capability runs on the platform, with versions, scheduled championships, monitoring and batch pipelines.
Quickstart
pip install zerograd
from zerograd import ZeroGrad

zg = ZeroGrad()                                        # local: runs on your machine
cap = zg.create("churn", examples=history, target="churned")
cap.evaluation                                         # every model on the same holdout; the champion is marked
cap.predict(new_customers)                             # prediction, score and probability per class
Open source under Apache 2.0. Try it without installing anything, in Colab:
| Notebook | What it shows | |
|---|---|---|
| Quickstart | Model catalog, a championship on breast cancer data, predictions, saving, and a context curve on Adult | Open in Colab |
| Titanic | A championship you check against your own holdout, one-row predictions, how much history you need, multiclass | Open in Colab |
| Evaluate and decide | Cross-validation at random, by customer and by date, a threshold by the cost of each mistake, column importance, scikit-learn | Open in Colab |
| Without a target | Anomalies with the columns why, imputation, synthetic rows scored by detection AUC, clustering with profiles | Open in Colab |
Install
pip install zerograd                  # local engine with TabPFN v2 and TabICLv2
pip install "zerograd[all]"           # adds Mitra-v2 and TabDPT
Python 3.10+. A GPU helps but is not required: on CPU, histories up to a few thousand rows take seconds to
minutes. Weights download from each model's official Hugging Face repository the first time you use it and
are cached there (HF_HOME); ZeroGrad hosts none.
What models are there?
import zerograd

zerograd.list_models()                                  # every model: tasks, license, commercial use, installed
zerograd.list_models(task="classification", commercial=True)
zerograd.list_tasks()                                   # every task and which models do it
zerograd.list_models().to_frame()                       # as a DataFrame
In a notebook these render as tables with a badge for commercial and non-commercial use. In this version:
| Model | Name | License | Commercial use | Default |
|---|---|---|---|---|
| TabPFN v2 | tabpfn-v2 |
Prior Labs License (Apache 2.0 + attribution) | yes | yes |
| TabICLv2 | tabicl-v2 |
BSD-3-Clause | yes | yes |
| Mitra-v2 | mitra-v2 |
Apache 2.0 | yes | yes, with pip install "zerograd[mitra]" |
| TabDPT | tabdpt |
Apache 2.0 | yes | yes, with pip install "zerograd[tabdpt]" |
| Mitra | mitra |
Apache 2.0 | yes | by name |
| FoMo-0D | fomo-0d |
MIT | yes | anomaly detection |
| ZEUS | zeus |
Apache 2.0 | yes | clustering |
The full list, with sources and the models that are off by default, is in MODELS.md.
This version runs classification (binary and multiclass, up to 10 classes) and regression (locally, with
TabPFN v2, TabICLv2 and TabDPT), plus four tasks with no target: anomaly detection, imputation, synthetic data and
clustering (below). zerograd.list_tasks() shows which models run each task.
The championship
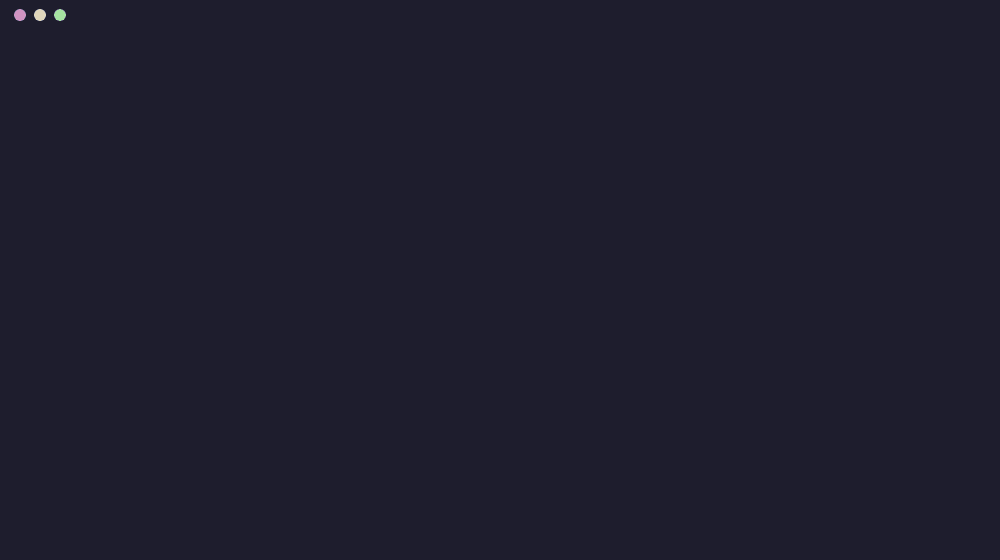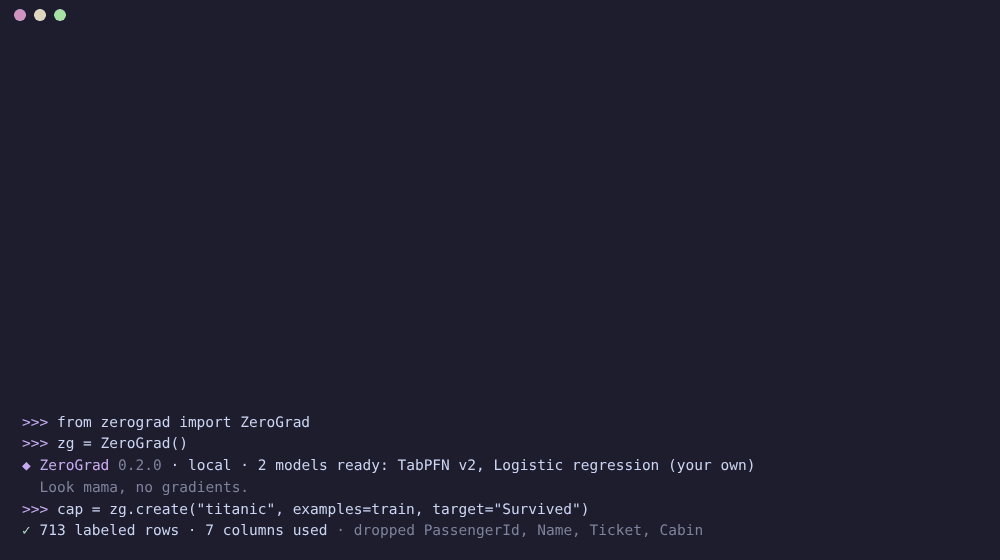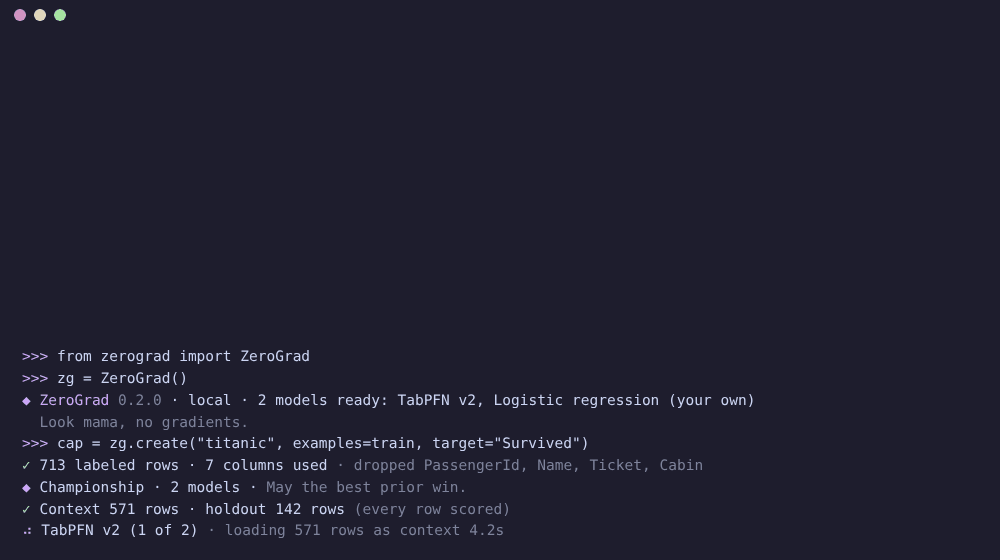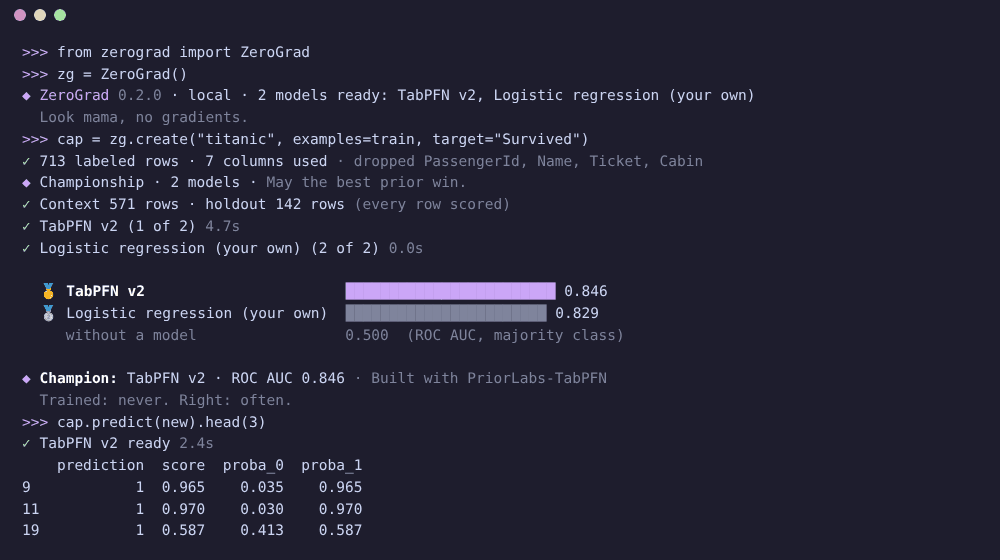
cap = zg.create(
    "titanic-survival",
    examples="train.csv",          # a DataFrame or a CSV/Parquet path
    target="Survived",
    drop=["boat", "body"],         # columns only known after the outcome
    metric="roc_auc",              # or pr_auc, log_loss, accuracy, balanced_accuracy, f1, precision, recall, f1_macro
)
cap.evaluation       # one row per model: metrics on the holdout, seconds, champion
cap.baselines        # the same holdout scored without a model (random, majority class)
cap.columns          # which columns were used and why the others were dropped
What happens:
- Columns that cannot help are dropped and reported: identifiers, free text, constant and empty columns.
- 20% of the labeled rows are held out (stratified) and every holdout row is scored by every model.
- The context the models read is the rest, or a stratified sample of up to 10,000 rows.
- The champion keeps a context drawn from all labeled rows for predictions.
Pick the competitors with ZeroGrad(models=["tabpfn-v2", "mitra-v2"]).
Benchmark
We ran 12 OpenML classification datasets and 6 regression datasets, 3 seeds each, on GitHub Actions CPUs. The champion is picked on the training rows only, and every number below comes from a 20% test split that nothing saw during selection. The baseline is scikit-learn's HistGradientBoosting with default settings, and regression also gets Ridge as a linear baseline.
| champion against HistGradientBoosting (wins / ties / losses) | |
|---|---|
| ROC AUC | 11 / 0 / 1 (mean 0.894 against 0.866) |
| Log loss | 12 / 0 / 0 (0.323 against 0.454) |
| Brier score | 12 / 0 / 0 |
| Accuracy | 10 / 1 / 1 |
| Regression RMSE | 6 / 0 / 0 (and 6 / 0 / 0 against Ridge) |
The one loss is churn, by 0.004 of ROC AUC: TabPFN v2 alone would have won it, but the championship picked another
model on the training rows. Per-dataset tables for every model are in benchmarks/RESULTS.md, and
python benchmarks/run.py reproduces them.
Predict
preds = cap.predict(new_df)            # DataFrame aligned to new_df's index
cap.predict({"Pclass": 3, "Sex": "male", "Age": 22, "Fare": 7.25})   # one row -> dict
cap.update(threshold=0.3)              # binary: score >= 0.3 predicts the positive class
Context size: speed against quality
Foundation models read their context (your labeled rows) on every prediction, so more rows usually score better
and answer slower. context_curve fits one model on growing samples of the context, scores each on the same test
rows and times it:
curve = zg.context_curve(train_df, "Survived", test=test_df)   # sizes: 250, 500, 1K, 2K, 5K, 10K... up to all rows
curve                    # per size: the metric, fit and predict seconds, ms per row, and the recommended size
curve.recommended        # the smallest context within 0.005 of the best score (tolerance=...)
curve.plot()             # score and latency on two axes, the recommended size marked (needs matplotlib)

curve = cap.context_curve(test_df)               # the champion, on samples of the capability's own context
cap.update(context_rows=curve.recommended)       # predict with the smaller, faster context

On 12,000 rows of the Adult census (TabPFN v2 on a GitHub Actions CPU, 2,000 test rows), 1,000 rows of context score
ROC AUC 0.913 against 0.915 with 10,000, and predict about 17× faster (61 vs 1,012 ms per row).
python scripts/context_curve_figure.py reproduces it; docs/context-curve.csv has the numbers.
Options: sizes=[...], model="tabicl-v2" (default: the first selected model), metric="log_loss", tolerance=0.01.
Without test, a stratified 20% of the rows is held out. With remote=True the curve runs a championship per size
on the platform and returns the same kind of table.
Regression
A numeric target with decimals, or with more distinct values than classes allowed (10), is a regression:
cap = zg.create("prices", examples=listings, target="price")   # or task="regression" to say so
cap.evaluation       # RMSE, MAE and R² per model on the same holdout; the champion has the lowest RMSE
cap.baselines        # always the average, always the median
cap.predict(new_listings)                    # one column: prediction
cap.predict(one_listing)                     # a dict in, {"prediction": 154230.5} out
metric="mae" or metric="r2" picks the champion by another metric. The holdout and the context are stratified on
deciles of the target, so both see cheap and expensive rows. Context curves work the same way; for RMSE and MAE the
tolerance is relative (within 0.5% of the best). Mitra-v2 sits regression out in this version, and the platform
(remote=True) runs classification only for now.
Evaluate honestly, pick the cut, read the columns
cv = zg.cross_validate(df, "default", folds=5)                     # stratified k-fold
cv = zg.cross_validate(df, "default", groups="customer_id")        # a customer never sits on both sides
cv = zg.cross_validate(df, "default", time="date", gap=30)         # train on the past, score the next block
cv.summary           # per model: mean metrics, spread, KS and lift in the top 10% (binary), next to a baseline
cv.folds             # one row per model and fold

cap.optimize_threshold("cost", cost_fp=1, cost_fn=20)     # a missed default costs 20 false alarms
cap.optimize_threshold("recall", min_precision=0.8)       # catch the most while 8 in 10 flags are right
cap.importance(test_df)                                   # how much the metric drops when each column is shuffled
A random split rewards a model that remembers a customer or peeks at the future; split by group or by time when
that is how the model will be used. The group and time columns are left out of the features. optimize_threshold
reads the championship holdout (or data= rows with the target), also takes "f1", "youden" and "precision"
(with min_recall), and sets the capability's threshold unless apply=False. importance wants rows the model
did not see as context.
scikit-learn
from zerograd import ZeroGradClassifier, ZeroGradRegressor
from sklearn.model_selection import cross_val_score

clf = ZeroGradClassifier(model="tabicl-v2")       # or tabpfn-v2, mitra-v2, ...; default: the first installed
cross_val_score(clf, X, y, cv=5, scoring="roc_auc")
The estimators fit by keeping a context (a stratified sample of up to max_context_rows, 10,000 by default) and
predict with it, so they work in a Pipeline, GridSearchCV, TunedThresholdClassifierCV or
permutation_importance. Columns get the same preprocessing as zg.create. You pick the model; there is no
championship inside.
No target: anomalies, gaps, synthetic rows, segments
Four tasks need no labels. Each runs on your machine, compares the foundation models with the classic scikit-learn method whenever there is something to measure, and says which one won.
found = zg.anomalies(transactions)           # every row scored; the top 5% flagged
found.top(10)                                 # the most unusual rows, with the columns that make them unusual
zg.anomalies(transactions, labels="fraud")    # known cases? a championship by ROC AUC, against Isolation Forest, LOF, kNN
zg.anomalies(today, reference=last_month)     # score new rows against rows you trust

filled = zg.impute(customers)                 # hide 10% of the known cells, score every model, fill with the champion
filled.data, filled.filled, filled.evaluation

fake = zg.synthesize(customers, n=5_000)      # new rows; detection AUC near 0.5 = hard to tell from yours
fake.data, fake.evaluation                    # also the share of exact copies of a real row

groups = zg.cluster(customers)                # k picked between 2 and 10, or cluster(df, k=4)
groups.labels, groups.profiles                # segment per row, and what sets each segment apart
TabPFN v2 and TabICLv2 do the first three with the chain rule: the probability of a row is the product of
"how likely is this column, given the ones before it", and each factor is a classification question they answer
in context (the method of the TabPFN paper, for any classifier in the registry). The same factors say why a row
is unusual. FoMo-0D (MIT) detects anomalies zero-shot and
ZEUS (Apache 2.0) embeds rows for clustering zero-shot; both are commercial
use. Synthetic rows are not anonymous by themselves: check exact_copies and drop identifying columns first.
These run locally for now, not with remote=True.
Save and open
cap.save("titanic.zg")                 # preprocessing, evaluation and context rows; no weights
cap = zerograd.load("titanic.zg")
The file holds a sample of your labeled rows as the model's context: treat it like the data itself.
Licenses and attribution
The SDK is Apache 2.0. Each model has its own license, shown by zerograd.list_models(), and you are
responsible for complying with it (TERMS.md). If you build a product with TabPFN v2, its license
asks you to show "Built with PriorLabs-TabPFN"; cap.attribution tells you when the champion needs it.
Some newer models are released under non-commercial licenses. They are off by default, can be enabled one by one by name for research and evaluation, and never run on the ZeroGrad platform. See MODELS.md and TERMS.md.
Bring your own model
Anything with fit and predict_proba can compete (and with predict, in regression):
from zerograd.models import Aligned, ModelSpec, register_model

def fit(X, y, n_classes, serving):
    model = MyClassifier().fit(X, y)
    return Aligned(model, n_classes)

register_model(ModelSpec(
    name="my-model", display="My model", family="mine", license="MIT", license_url="https://...",
    source="local", commercial=True, install="-", fit_fn=fit, check_fn=lambda: None,
    regress_fn=lambda X, y, serving: MyRegressor().fit(X, y),   # optional: also compete in regression
))
ZeroGrad(models=["tabpfn-v2", "my-model"])
The ZeroGrad platform (remote=True)
The same calls run on the ZeroGrad platform with an API key:
zg = ZeroGrad(remote=True)             # reads ZEROGRAD_API_KEY; an API key alone also selects it
cap = zg.create("churn", examples=history, target="churned")
The platform adds what a team needs to run predictions in production: managed GPU inference with SLAs, versions and promotion, scheduled
championships on fresh history, batch pipelines from your bucket, monitoring, thresholds chosen by cost,
Explain and Ask, and workspaces for teams. zerograd.privacy (scan, drop_sensitive, Vault) keeps
personal data on your side before anything is sent. See zerograd.dev.
On the platform every prediction has a prediction_id. When the real outcomes arrive, weeks or months later,
send them back and see how each version does in production, by cohort, next to its holdout score:
preds = cap.predict(applications, id_column="loan_id")    # your own id is kept as the reference
cap.send_outcomes([{"reference": "L-10293", "outcome": 1, "decision": "approved"}])
cap.update(maturity_days=90)                               # cohorts count once outcomes had time to happen
cap.performance(cohort="week")
remote=None (the default) picks the platform when an API key is given or ZEROGRAD_API_KEY is set;
pass remote=False to stay local.
Output
The SDK talks on stderr: a greeting, a spinner per model, a podium at the end. Off a terminal (CI, logs) it prints
plain lines; progress=False or ZEROGRAD_QUIET=1 silences it, and NO_COLOR turns colors off. License warnings
are never silenced.
Development
pip install -e ".[dev]"
pytest                                        # fast tests, no models, no network
ZEROGRAD_REAL_MODELS=1 pytest tests/test_real_models.py   # the real models (downloads weights)
Security
See SECURITY.md. Releases are published from GitHub Actions with PyPI trusted publishing.
License
Apache License 2.0. See LICENSE and NOTICE. The models have their own licenses: MODELS.md.
1 maintainer

Metadata
1 maintainer
Release files for zerograd 0.2.0
For a detailed explanation of source distributions (sdists) and built distributions (wheels), please see the package formats documentation.
Source distribution (sdist)
| File | Size | Uploaded | Provenance | Actions |
|---|---|---|---|---|
| zerograd-0.2.0.tar.gz | 131.2 kB | With provenance | Details for zerograd-0.2.0.tar.gz |
Built distribution (wheel)
| File | Interpreter | ABI | Platform | Actions Reset |
|---|---|---|---|---|
| zerograd-0.2.0-py3-none-any.whl | Python 3 | none | any | Details for zerograd-0.2.0-py3-none-any.whl |
Total release size: 263.1 kB
Release files / zerograd-0.2.0.tar.gz
| Download URL | zerograd-0.2.0.tar.gz |
|---|---|
| Size | 131.2 kB |
| Tags | Source |
|
SHA-256 checksum How to use checksums |
64f186983866c88db5720fc0c4fdb4aac89fda1927095beb552be78729ee7f8b
|
|
BLAKE2b-256 checksum How to use checksums |
68a992a76908cbc6f61fbf30cc3d7a8e2c6fb5e45d23134097ec5c43840b97e1
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
Yes |
| Uploaded via |
twine/7.0.0 CPython/3.13.16
|
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.


PyPI Publish Attestation
PyPI verified that this artifact, at this checksum, originated from the publisher listed below.
Signed by GitHub Actions, verified by PyPI on Nov 14, 2026.
Transparency logRelease files / zerograd-0.2.0-py3-none-any.whl
| Download URL | zerograd-0.2.0-py3-none-any.whl |
|---|---|
| Size | 131.9 kB |
| Tags | Python 3 |
|
SHA-256 checksum How to use checksums |
385e99729c8b618814c8738b84828d11c8e169da882fd58b88a6d7b9d6d8db46
|
|
BLAKE2b-256 checksum How to use checksums |
7c4b9dcb91a3d8609863af695ec141973c023e5df3216bb58142f617c57fbf54
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
Yes |
| Uploaded via |
twine/7.0.0 CPython/3.13.16
|
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.
PyPI Publish Attestation
PyPI verified that this artifact, at this checksum, originated from the publisher listed below.
Signed by GitHub Actions, verified by PyPI on Nov 14, 2026.
Transparency logSecurity for zerograd 0.2.0
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.
Full provenance
Both files in this release have been uploaded with provenance metadata.
Attestation for zerograd-0.2.0.tar.gz
PyPI Publish Attestation
PyPI verified that this artifact, at this checksum, originated from the publisher listed below.
Signed by GitHub Actions, verified by PyPI on Nov 14, 2026.
Transparency logA note on package security
PyPI is a repository for distributing packages, not a service for auditing them. While third-party security researchers and our staff do their best to detect and remove malicious packages, PyPI cannot guarantee the quality, security or suitability of any given package.
To learn more about protecting yourself from malicious actors, visit our package security documentation.














