
The complete post-training stack for LLMs + RL for any problem
Visit our website. View documentation.
Join the Discord Server for questions, help and collaboration.




🚀 Train and deploy at scale with Arena from AgileRL 🚀
AgileRL takes an open-weights LLM from supervised fine-tuning through preference tuning to multi-turn agentic RL, in one library. The same library covers classic deep RL (single-agent, multi-agent, offline and bandits) with evolutionary hyperparameter optimization built in.
Table of Contents
- LLM Post-Training
- Get Started
- Train at Scale on Arena
- Train an LLM Locally
- Classic RL
- Tutorials
- Algorithms
- Citing AgileRL
LLM Post-Training
- The whole pipeline. SFT and DPO, then RL with GRPO, CISPO, GSPO, REINFORCE or PPO.
- Multi-turn agentic RL. Train on any OpenEnv environment: a Python class, a library entrypoint such as GEM, or a remote env server. Or use a dataset plus a reward function. See Environments.
- LoRA. Train small adapters on a frozen base. For RL post-training, LoRA can match full fine-tuning at a fraction of the memory. QLoRA squeezes in bigger models for colocated local runs.
- Torch-native parallelism. Data parallel or FSDP2 sharding, launched with
torchrun. OneFSDPConfigworks for every LLM algorithm. See Multi-GPU LLM training. - Memory optimizations. Chunked fused log-probs, activation checkpointing and offload, CPU offload for optimizer state or parameters, and trainer offload during rollout.
- Model-specific optimizations. Per-family kernels and settings for high throughput at the lowest memory, on dense, MoE and hybrid Mamba models. MoE LoRA runs per expert without materializing full tensors, and hybrid models like Nemotron-H get fused kernels and fixes for Mamba2.
- Fast rollouts. vLLM generation, with the option to colocate the trainer and vLLM on a single GPU.
- Evolutionary HPO for LLMs. Train a population and let learning rate, KL penalty and more tune themselves during the run.
- Agent-friendly CLI. A training run is one YAML manifest and one command. Your coding agent can read the manifest schema, validate its own config and launch runs on Arena without a human in the loop. See Built for coding agents.
- Async training at scale. Move to Arena for async training on managed GPU clusters, with models up to 120B such as Nemotron 3.5 Super VL. We keep adding models.
- Deploy and chat. Deploy the best checkpoint on Arena and chat with it from the CLI with
arena agent generate.
Benchmark
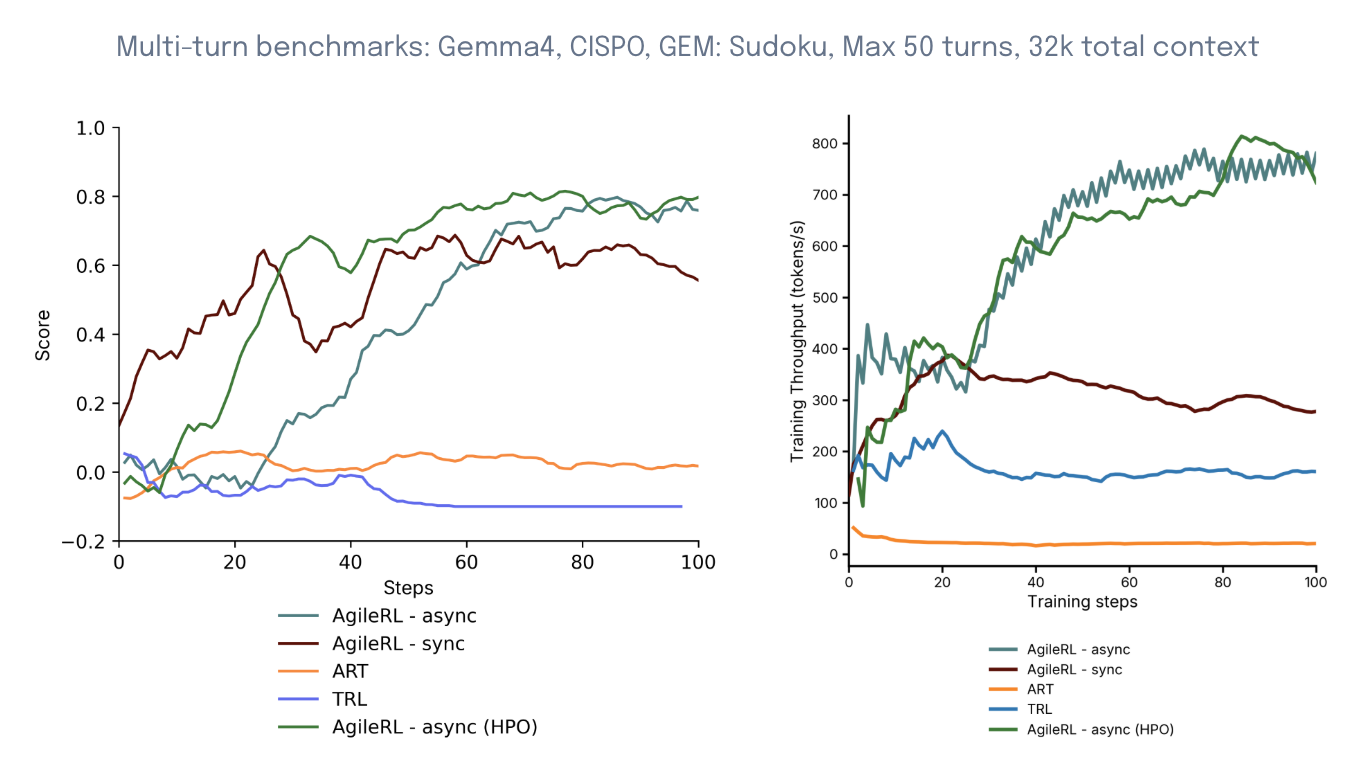
AgileRL trains on over 4x more tokens/s than ART and TRL, and reaches higher reward on half the GPU memory.
AgileRL's CISPO against ART and TRL on the GEM Sudoku Hard task: 32k-token context, up to 50 turns per rollout. The async and HPO runs were on Arena. AgileRL ran on A100 40GB nodes. ART and TRL needed A100 80GB. All runs used the same starting hyperparameters.
Get Started
pip install "agilerl[llm]"        # LLM post-training
pip install agilerl               # classic RL + the Arena CLI
| Installation | Description |
|---|---|
agilerl[llm] |
Hugging Face transformers, PEFT, datasets, Liger, bitsandbytes, and vLLM (Linux). |
agilerl[cpu-llm] |
Same Hugging Face stack as [llm], without vLLM. Use this when you do not need the vLLM engine (for example with [cpu]). |
agilerl[box2d] |
Box2D physics engine for Gymnasium environments. |
agilerl[cpu] |
CPU-only PyTorch wheels (no NVIDIA stack). |
agilerl[all] |
Box2D and LLM extras. |
agilerl-arena |
Arena SDK and CLI only, no torch. Included with agilerl. |
For the development tip of main: pip install git+https://github.com/AgileRL/AgileRL.git@main. For development mode: clone the repo and run pip install -e ..
Train at Scale on Arena
Every training run is a YAML manifest. Arena runs it on managed GPU clusters, with async rollouts and population-based HPO across nodes. Supported base models range from Qwen, Granite and Gemma up to 100B+ models such as Nemotron 3.5 Super VL 120B-A12B, and the list keeps growing. The arena CLI ships with agilerl:
arena login
arena models list                                   # supported base models
arena experiments submit my_manifest.yaml --project my-project
arena agent deploy my-experiment                    # deploy the best checkpoint
arena agent run my-deployment
arena agent generate --prompt "What is 17 * 23?"
Built for coding agents
Point Cursor, Claude Code or Codex at the arena CLI and it can run the whole loop itself: write a manifest, check it, launch it, pull metrics and deploy.
export ARENA_API_KEY="arena_pat_..."                # no interactive login
arena manifest schema                               # JSON Schema the agent writes against
arena manifest validate my_manifest.yaml --json     # one JSON verdict, stable exit codes
arena experiments submit my_manifest.yaml --project my-project
arena experiments metrics my-experiment             # download metrics to judge the run
Upload your own data with arena datasets create, or your own environment with arena env validate. The same operations are on ArenaClient in Python. See the Arena docs and the agilerl-arena README.
Train an LLM Locally
The same manifests run on your own GPU. This one trains Qwen2.5-0.5B with GRPO on GEM's multi-turn Guess the Number game:
pip install gem-llm
python -m agilerl.train configs/training/llm_finetuning/grpo_env.yaml
Or from Python:
from agilerl import LocalTrainer

trainer = LocalTrainer.from_manifest("configs/training/llm_finetuning/grpo_env.yaml")
population, fitnesses = trainer.train()
More manifests for SFT, DPO, CISPO, GSPO, LLM PPO and LLM REINFORCE are in configs/training/llm_finetuning.
Classic RL
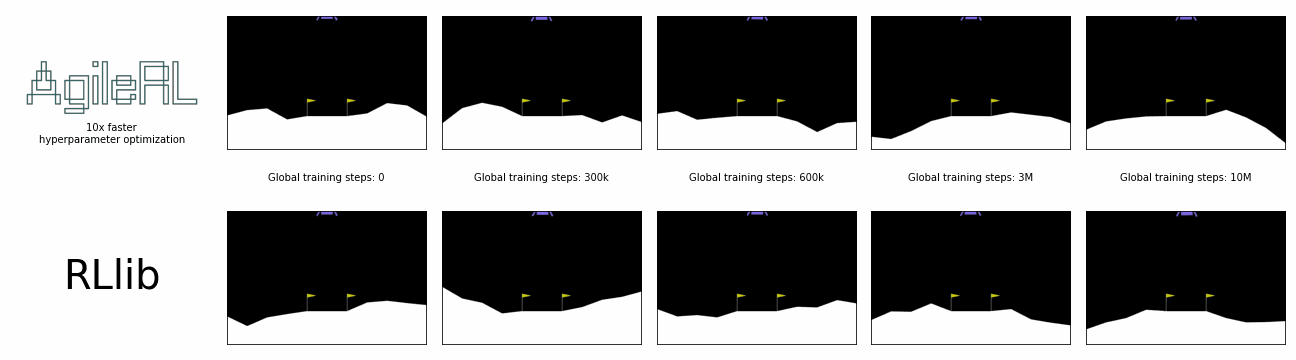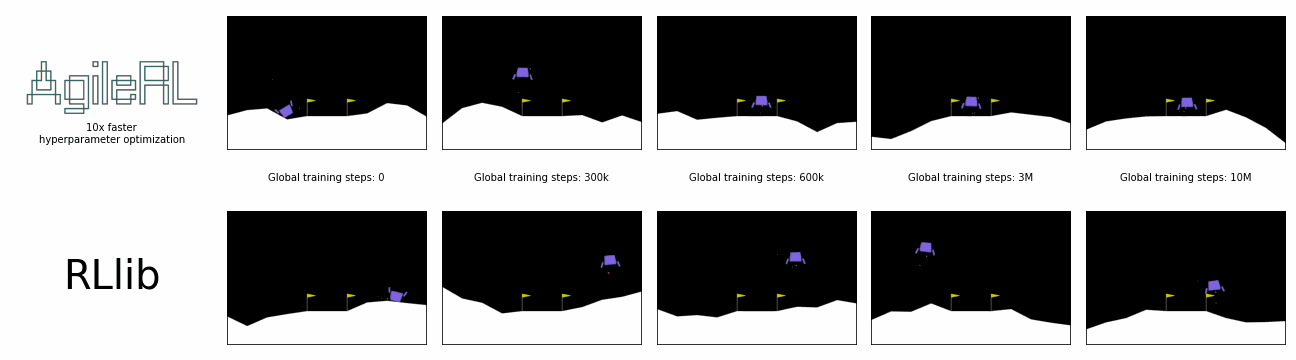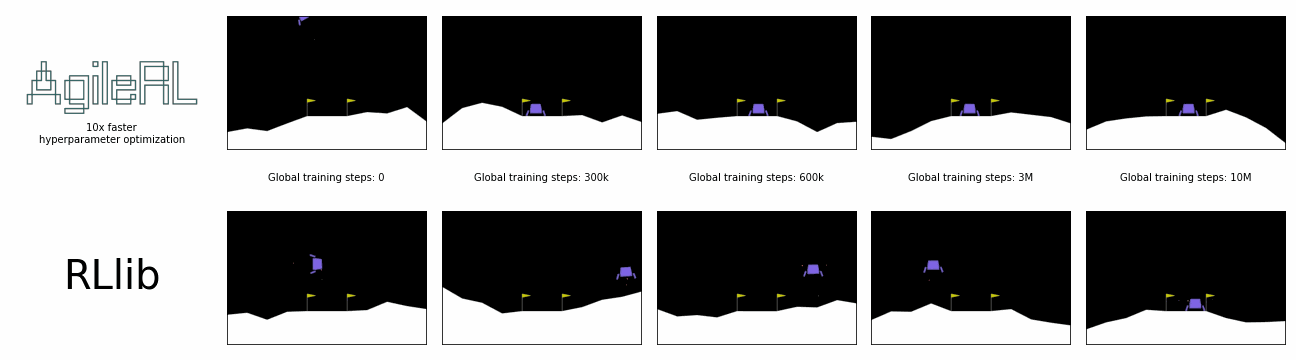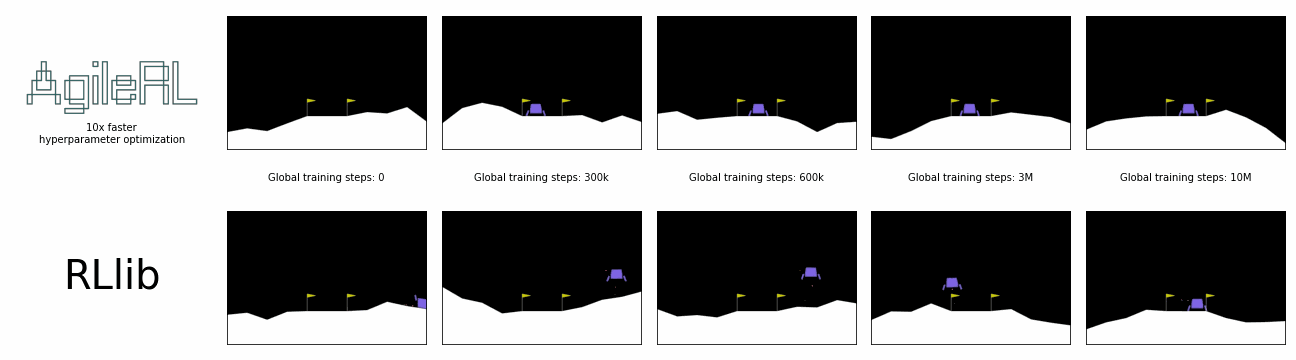
On-policy, off-policy, offline, multi-agent and contextual bandit algorithms, all with evolutionary HPO. Train a population of agents and the hyperparameters evolve during a single run, instead of running hundreds of trials first.
from agilerl import LocalTrainer
from agilerl.models import TrainingSpec

trainer = LocalTrainer(
    algorithm="DQN",
    environment="LunarLander-v3",
    training=TrainingSpec(pop_size=4),
    hpo=True,
)
population, fitnesses = trainer.train()
Or from a manifest: python -m agilerl.train configs/training/dqn/dqn.yaml. You can swap in your own Gymnasium or PettingZoo environments, evolvable networks, algorithms or training loops. See Trainers.
A single AgileRL run with evolutionary HPO against the multiple Optuna runs needed to tune other frameworks. Global steps counts every step taken by every agent in the population:
Tutorials
| Tutorial Type | Description | Tutorials |
|---|---|---|
| LLM Fine-tuning | SFT, DPO, single- and multi-turn RL, HPO and remote environments. | GRPO reasoning SFT and DPO GRPO with HPO Multi-turn GRPO and PPO Remote env server |
| Training on Arena | Upload and validate custom environments, submit training jobs on managed cloud infrastructure, and deploy trained agents for inference. | PPO - Acrobot Custom Environment |
| Single-agent tasks | Train on- and off-policy agents on Gymnasium environments. | PPO - Acrobot TD3 - Lunar Lander Rainbow DQN - CartPole Recurrent PPO - Masked Pendulum |
| Multi-agent tasks | PettingZoo environments, including Connect Four with curriculum learning and self-play. | DQN - Connect Four MADDPG - Space Invaders MATD3 - Speaker Listener |
| Hierarchical curriculum learning | Teach agents skills and combine them to reach an end goal. | PPO - Lunar Lander |
| Contextual multi-arm bandits | Make the right decision in single-timestep environments. | NeuralUCB - Iris Dataset NeuralTS - PenDigits |
| Custom Modules & Networks | Build custom evolvable modules and networks. | Dueling Distributional Q Network EvolvableSimBa |
Algorithms
LLM Post-Training
Single-agent
Multi-agent
| RL | Algorithm |
|---|---|
| Multi-agent | Multi-Agent Deep Deterministic Policy Gradient (MADDPG) Multi-Agent Twin-Delayed Deep Deterministic Policy Gradient (MATD3) Independent Proximal Policy Optimization (IPPO) |
Contextual multi-armed bandit
| RL | Algorithm |
|---|---|
| Bandits | Neural Contextual Bandits with UCB-based Exploration (NeuralUCB) Neural Contextual Bandits with Thompson Sampling (NeuralTS) |
Citing AgileRL
If you use AgileRL in your work, please cite the repository:
@software{Ustaran-Anderegg_AgileRL,
author = {Ustaran-Anderegg, Nicholas and Pratt, Michael and Sabal-Bermudez, Jaime and Doherty, Michael},
license = {Apache-2.0},
title = {{AgileRL}},
url = {https://github.com/AgileRL/AgileRL}
}
5 maintainers


Metadata
5 maintainers
Release files for agilerl 2.50.0
For a detailed explanation of source distributions (sdists) and built distributions (wheels), please see the package formats documentation.
Source distribution (sdist)
| File | Size | Uploaded | |
|---|---|---|---|
| agilerl-2.50.0.tar.gz | 774.5 kB | Details |
Built distribution (wheel)
| File | Interpreter | ABI | Platform | Reset |
|---|---|---|---|---|
| agilerl-2.50.0-py3-none-any.whl | Python 3 | none | any | Details |
Total release size: 1.7 MB
Release files / agilerl-2.50.0.tar.gz
| Download URL | agilerl-2.50.0.tar.gz |
|---|---|
| Size | 774.5 kB |
| Tags | Source |
|
SHA-256 checksum How to use checksums |
9cc6a8781174d4d22fc8fd4b260a40e29afbbb5c5be56475e50ecd025a56829b
|
|
BLAKE2b-256 checksum How to use checksums |
0027c859617d75279cf9151beccdcce8771c6ab1bbf76dfa5c9fb3b601239bb6
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
Yes |
| Uploaded via |
uv/0.12.23 {"installer":{"name":"uv","version":"0.12.23","subcommand":["publish"]},"python":null,"implementation":{"name":null,"version":null},"distro":{"name":"Ubuntu","version":"24.04","id":"noble","libc":null},"system":{"name":null,"release":null},"cpu":null,"openssl_version":null,"setuptools_version":null,"rustc_version":null,"ci":true}
|
Release files / agilerl-2.50.0-py3-none-any.whl
| Download URL | agilerl-2.50.0-py3-none-any.whl |
|---|---|
| Size | 912.5 kB |
| Tags | Python 3 |
|
SHA-256 checksum How to use checksums |
483b587f819a653a416ad974f2fea8d84d089a8fbb54ce12ff946312d285851e
|
|
BLAKE2b-256 checksum How to use checksums |
02cc7a27d0173ba7e0fb111c055eefb7fc6f75f090478fa4f868d780b3e7f6fb
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
Yes |
| Uploaded via |
uv/0.12.23 {"installer":{"name":"uv","version":"0.12.23","subcommand":["publish"]},"python":null,"implementation":{"name":null,"version":null},"distro":{"name":"Ubuntu","version":"24.04","id":"noble","libc":null},"system":{"name":null,"release":null},"cpu":null,"openssl_version":null,"setuptools_version":null,"rustc_version":null,"ci":true}
|














