
allisbns


allisbns is a Python package to work with the packed ISBN codes from Anna's Archive. It helps you to examine, manipulate, and plot such data that represent the largest fully open list of all known ISBNs.
(This project is not affiliated with Anna's Archive.)
Source Documentation Changelog
Introduction
Anna's Archive, besides books and datasets, provides a large amount of metadata from different sources (including WorldCat, Google Books, the Chinese collections, and many others). Such an extensive collection presumably represents the largest openly available metadata about all known ISBNs ever published (see the figure below).
The derived metadata, periodically published by Anna and the team, includes the packed ISBN codes, a very compact representation of all ISBNs with distinction of original data sources: it can tell you what ISBNs are available in a dataset.
After the visualization contest, the beautiful interactive viewer exists to explore all ISBNs. However, sometimes you need more imperative control over the available data: check many ISBNs at once, analyze selected regions, compare different dumps, plot custom images, etc.
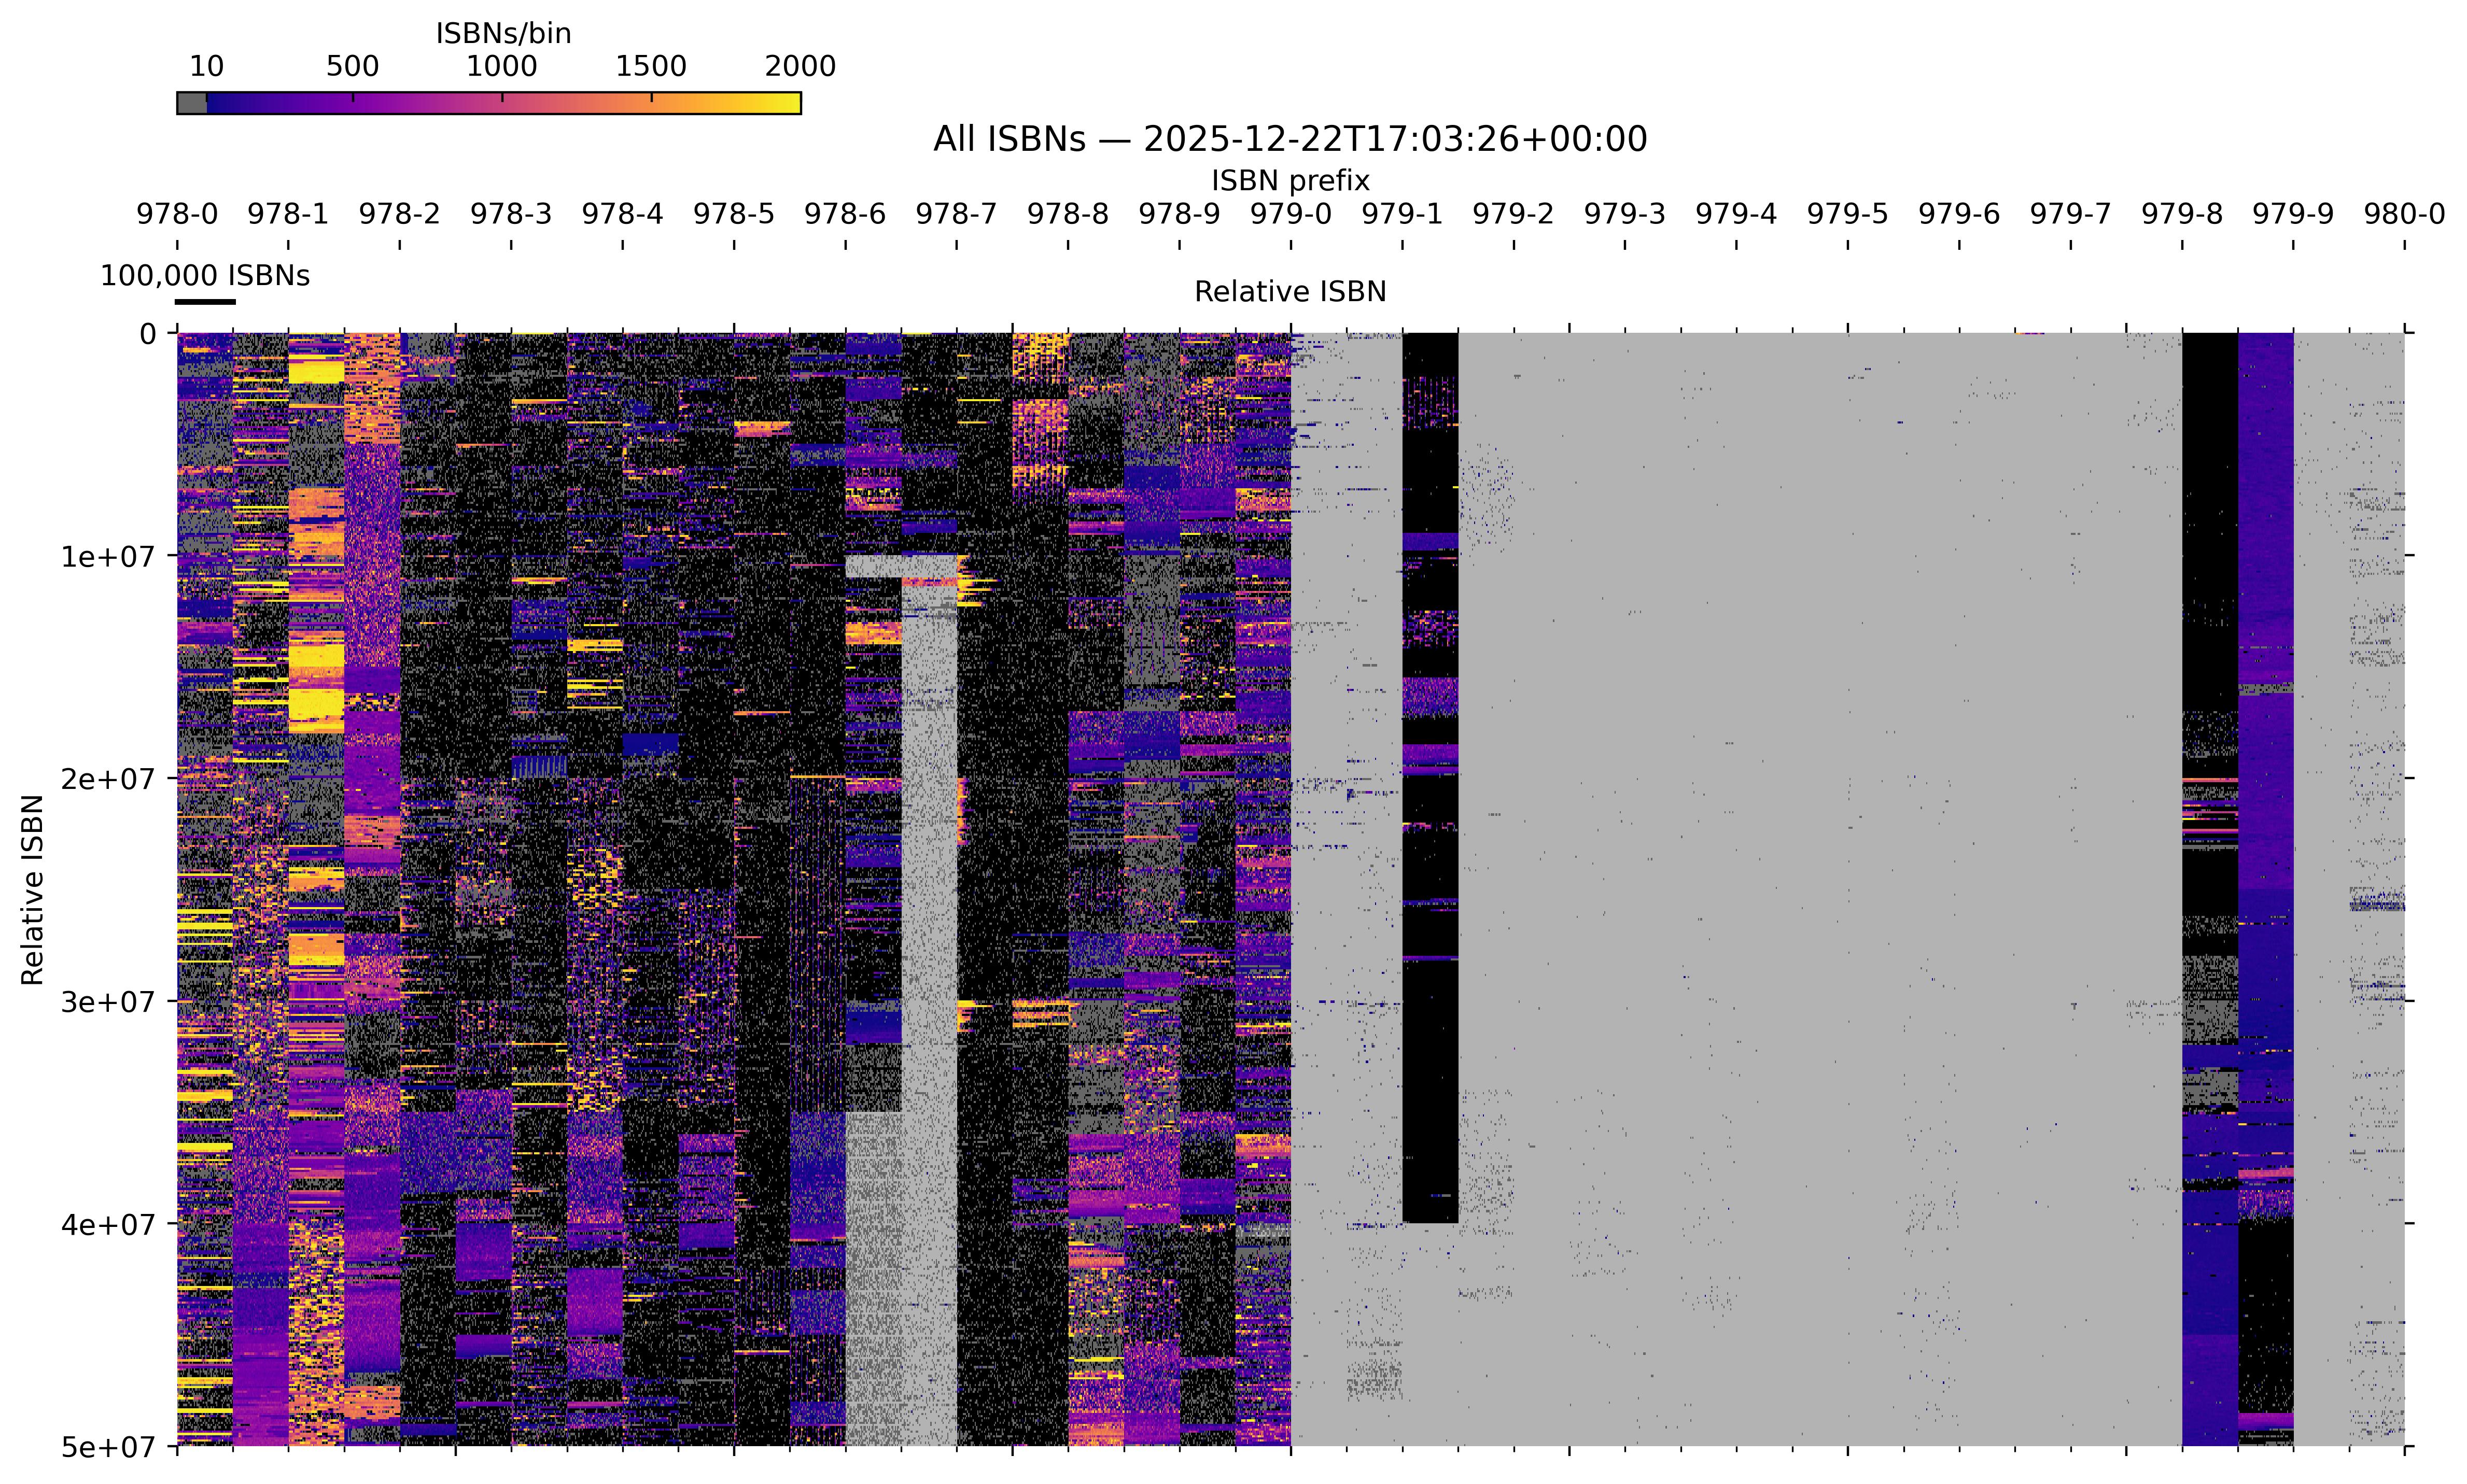
Binned image (hi-res version) of all known ISBNs (data source: Anna's Archive). The defined ISBN registration groups are underlaid in black. See here how it is plotted.
Installation
The package is available on PyPI:
pip install allisbns
To include optional plotting support, install it as:
pip install allisbns[plotting]
Quickstart
Download data
The package works with datasets provided as bencoded files named as
aa_isbn13_codes_*.benc.zst. Such files are located in the codes_benc
directory within the
aa_derived_mirror_metadata
torrents. One file contains ISBN codes for all datasets (collections). See
here for more
info about codes.
Work with datasets
Create a dataset from the downloaded file with ISBN codes:
    >>> from allisbns.dataset import CodeDataset
    >>> md5 = CodeDataset.from_file(
    ...     source="aa_isbn13_codes_20251118T170842Z.benc.zst",
    ...     collection="md5",
    ... )
    >>> md5
    CodeDataset(array([    6,     1,     9, ...,     1, 91739,     1],
      shape=(14737375,), dtype=int32), bounds=(978000000000, 979999468900))
The md5 collection represents files available in Anna's Archive. All available
collections are:
'airitibooks', 'bloomsbury', 'cadal_ssno', 'cerlalc', 'chinese_architecture',
'duxiu_ssid', 'edsebk', 'gbooks', 'goodreads', 'hathi', 'huawen_library', 'ia',
'isbndb', 'isbngrp', 'kulturpass', 'libby', 'md5', 'nexusstc',
'nexusstc_download', 'oclc', 'ol', 'ptpress', 'rgb', 'sciencereading', 'shukui',
'sklib', 'trantor', 'wanfang', 'zjjd'
Query one ISBN:
    >>> md5.query_isbn(978_2_36590_117)
    QueryResult(is_streak=True, segment_index=8652142, position_in_segment=0)
Check many ISBNs:
    >>> md5.check_isbns(range(978_2_36590_000, 978_2_36590_999 + 1))
    array([ True, False, False, ..., False, False, False], shape=(1000,))
Get all filled ISBNs:
    >>> md5.get_filled_isbns()
    array([978000000000, 978000000001, 978000000002, ..., 979999377030,
       979999377160, 979999468900], shape=(16916212,))
Crop the dataset to some ISBN region:
    >>> from prettyisbns.isbn import get_prefix_bounds
    >>> start_isbn, end_isbn = get_prefix_bounds("978")
    >>> md5.reframe(start_isbn, end_isbn)
    CodeDataset(array([6, 1, 9, ..., 1, 2, 2],
       shape=(14503001,), dtype=int32), bounds=(978000000000, 978999999999))
Further reading
After installing, check out the documentation. See Overview for the first guidance. The API reference describes modules, classes, and functions. There are practical examples that will demonstrate the main usage. Cookbook also contains useful examples. You want to contribute code? Contributing tells how to participate.
License
Creative Commons Zero v1.0 Universal.
1 maintainer

Metadata
1 maintainer
Release files for allisbns 0.2.0
For a detailed explanation of source distributions (sdists) and built distributions (wheels), please see the package formats documentation.
Source distribution (sdist)
| File | Size | Uploaded | |
|---|---|---|---|
| allisbns-0.2.0.tar.gz | 17.7 kB | Details |
Built distribution (wheel)
| File | Interpreter | ABI | Platform | Reset |
|---|---|---|---|---|
| allisbns-0.2.0-py3-none-any.whl | Python 3 | none | any | Details |
Total release size: 36.7 kB
Release files / allisbns-0.2.0.tar.gz
| Download URL | allisbns-0.2.0.tar.gz |
|---|---|
| Size | 17.7 kB |
| Tags | Source |
|
SHA-256 checksum How to use checksums |
3a1f9c89978b0c4e17099d1b71b921e3451cb563dd798e14eb3a71e0621e854e
|
|
BLAKE2b-256 checksum How to use checksums |
15641d07a08b0a6d5b214cf76cd4d2c8440b22b356746e6f251e67234610f1d9
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
No |
| Uploaded via |
uv/0.9.18 {"installer":{"name":"uv","version":"0.9.18","subcommand":["publish"]},"python":null,"implementation":{"name":null,"version":null},"distro":{"name":"Fedora Linux","version":"43","id":"","libc":null},"system":{"name":null,"release":null},"cpu":null,"openssl_version":null,"setuptools_version":null,"rustc_version":null,"ci":null}
|
Release files / allisbns-0.2.0-py3-none-any.whl
| Download URL | allisbns-0.2.0-py3-none-any.whl |
|---|---|
| Size | 18.9 kB |
| Tags | Python 3 |
|
SHA-256 checksum How to use checksums |
19869bf7d67b33c70059fb2deda776e66e28373bd84402002d5698eb0dd2dd73
|
|
BLAKE2b-256 checksum How to use checksums |
c096e66814aa01e70918ee0e06b04482c36c2f2b0b7ca825c19b8835101241e5
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
No |
| Uploaded via |
uv/0.9.18 {"installer":{"name":"uv","version":"0.9.18","subcommand":["publish"]},"python":null,"implementation":{"name":null,"version":null},"distro":{"name":"Fedora Linux","version":"43","id":"","libc":null},"system":{"name":null,"release":null},"cpu":null,"openssl_version":null,"setuptools_version":null,"rustc_version":null,"ci":null}
|














