
amos
| Version |   |
| Status |    |
| Documentation |  |
| Tools |         |
| Compatibility |     |
| Stats |      |
What is amos?
Automated Modeling for Open Scholarship.
Like the Rocinante's
mechanic in The Expanse, amos makes the dirty jobs of a data science
project (cleaning, describing, munging, preprocessing, modeling, evaluating,
and visualizing) easier.
You describe a study in a plain settings file (or a Python dict). amos
builds the workflow with chrisjen,
runs it on your data, compares every combination of the methods you list, and
records everything needed to reproduce the result.
Why use amos?
Accessible
amos is accessible to researchers at all levels. It uses one vocabulary for every stage of a
project. A project is made of workers (its stages), which use
techniques (the actual methods), sometimes organized in steps. The
settings file only names things, so it doubles as a readable description of
your methods:
The stages are only a convention: any technique can be used in any worker, and
you can name your workers whatever you like. And, any step can include none, which tests
whether a technique changes the result versus doing nothing at all.
Reproducible
Open scholarship means that others can check your work. amos helps by:
- Passing one seed to every tool that takes a
random_state, so a project yields the same result every time. - Applying a project to a copy of your data, so running it twice gives the same answer and your data is never changed.
- Keeping a history of every technique that was applied, with the exact tool and parameters it used.
- Isolating training and testing data. Every scaler, encoder, imputer, and sampler is fitted to the training rows and then applied to the test rows, so nothing leaks from the test set.
- All settings and parameters can be implemented through a single settings file that will produce the same results on any computer.
Flexible
amos wraps the major Python data science packages behind one interface, so you can compare their methods side by side without learning each package's quirks:
| Package | What amos uses it for |
|---|---|
| scikit-learn | Splitting, imputing, scaling, feature selection, models, cross-validation, metrics, and permutation importance. |
| category_encoders and skrub | Target, weight of evidence, and a dozen other data encoders. |
| imbalanced-learn | SMOTE and other ways to balance the classes of the training rows. |
| xgboost, lightgbm, and catboost | Gradient boosting. |
| InterpretML | Explainable boosting machines: accurate models whose every effect can be shown. |
| TabPFN | A pretrained model that is most accurate on small data. |
| Optuna | Hyperparameter searches that learn from each try. |
| statsmodels and pyfixest | Regressions with standard errors, p-values, and confidence intervals: least squares, generalized linear, quantile, robust, mixed, and GEE models; models of counts, of two or more classes, and of ordered classes; fixed effects and clustered standard errors; and principal component and factor analysis of the features. Survival analysis: Kaplan-Meier curves and Cox regression of the time until an event. |
| DoubleML, DoWhy, causalml, and tigramite | Causal inference: the effects of a treatment, estimated with double machine learning, regression, matching, weighting, instruments, regression discontinuities, and meta-learners, and causal discovery in time series. |
| fairlearn | Fairness metrics that compare a model across groups. |
| MAPIE | Conformal prediction: intervals and sets with a known rate of coverage. |
| shap and eli5 | Explaining models with SHAP values (and shap's plots of them) and weights. |
| matplotlib, seaborn, and SciencePlots | Figures and other visualizations, in the style of a scientific journal (Nature's, by default) and with colors that people with color blindness can tell apart. |
| great_tables and python-docx | Scorecards as HTML tables and Word documents. |
Robust and Transparent
A result that depends on one arbitrary choice of preprocessing or model is
fragile. The experiment design tries every combination of the techniques
you list for each step and reports how each one did, so readers can see that
your conclusions are robust (or not). The critic's scorecard puts every
combination side by side, on every metric, in a table (as
csv, Markdown, LaTeX, HTML, Word, or an image).
Name the columns that identify groups as groups, and amos keeps them out of the model's
features while it uses them to check fairness across groups, to add fixed
effects and cluster standard errors, and to keep each group in one set when
it splits the data.
Extensible
Every technique is a small Python class that is added to a library as soon as
it is defined, so it can be named in settings right away. To wrap a tool that
amos does not include, name its import path:
import amos

transformer = amos.Transformer(
    name = "yeo_johnson", contents = "sklearn.preprocessing.PowerTransformer")
print(transformer.name)
# yeo_johnson
You can use any naming convention you like, but, by default, amos uses snakecase
of a class name as the default key for accessing it from the stored technique library.
Getting started
Requirements
amos requires Python 3.11 or later. It runs on Linux, macOS, and Windows. It
is built on chrisjen, numpy,
pandas, and scikit-learn, which are installed automatically.
On a computer with an NVIDIA GPU, set use_gpu = true in the "general"
section of the settings, and the xgboost, catboost, lightgbm, and
tabpfn models are fitted on the GPU (and on the CPU if there is none). It
is false by default. See fitting models on a
GPU.
Installation
To install amos, use pip:
pip install amos
The other packages that amos wraps are optional. A technique imports its
package only when it is used, and tells you which extra to install if the
package is missing. Install them all (except TabPFN) with pip install amos[all], or choose:
| Extra | Installs | For |
|---|---|---|
boosting |
xgboost, lightgbm, catboost | Gradient boosting models. |
causal |
DoubleML (with rdrobust), tigramite, causalml (on Python 3.11 and 3.12), DoWhy (on Python 3.13 and later) | Inferers for causal inference, such as partially_linear, regression_discontinuity, propensity_matching, x_learner, and pcmci. |
encoders |
category_encoders, skrub | Target encoders, and encoders for text and dates. |
explain |
shap, eli5, InterpretML | shap_importance, the SHAP plots (such as shap_beeswarm), explain_weights, and explainable_boosting. |
fairness |
fairlearn | Fairness metrics and the fairness table. |
plots |
matplotlib, seaborn, SciencePlots | The artist's figures, and scorecards and regression tables as images. |
polars |
Polars, pyarrow | Reading Polars data frames. |
sampling |
imbalanced-learn | Samplers such as smote. |
statistics |
statsmodels, pyfixest | ols, glm, logit_sm, fixest, and the other models with inference (such as poisson, probit, and mixedlm). |
survival |
statsmodels | cox, kaplan_meier, survival_curves, and concordance. |
tables |
great_tables | Scorecards and regression tables as HTML tables. |
tuning |
Optuna | search = "optuna" for any model. |
uncertainty |
MAPIE | conformal intervals and sets. |
word |
python-docx | Scorecards and regression tables as Word documents. |
tabpfn |
TabPFN | The tabpfn model. It needs PyTorch, which is large, so it is not part of all. |
Usage
Describe your study
Most users describe a study in a settings file. This is a study of the Wisconsin breast cancer data that uses every stage, as an ini file:
[general]
seed = 43
label = target

[cancer_project]
cancer_workers = wrangler, explorer, analyst, critic, artist

[wrangler]
techniques = drop_duplicates, drop_constant

[explorer]
techniques = summarize, missing_values, label_balance

[analyst]
design = experiment
criterion = roc_auc
steps = split, scale, sample, model
split_techniques = stratified
scale_techniques = standard, min_max
sample_techniques = none, smote
model_techniques = logit, random_forest, xgboost

[critic]
techniques = scorecard, confusion, permutation_importance

[artist]
techniques = roc_curve, importance_plot, confusion_heatmap, shap_waterfall

[random_forest_parameters]
n_estimators = 100

[roc_curve_parameters]
title = How well the best model separates the classes

[importance_plot_parameters]
title = The ten features that matter most
limit = 10

[confusion_heatmap_parameters]
title = The test rows by their actual and predicted classes

[shap_waterfall_parameters]
title = How each feature moved the prediction for one tumor
limit = 30
height = 10
The "general" section names the label (the column that models predict) and
the seed. The project section lists the workers. In the "analyst", each
{step}_techniques setting lists alternatives, and the experiment design
tries every combination: 2 scalers, 2 samplers, and 3 models (scikit-learn's
logistic regression, a random forest, and xgboost's gradient boosting) make
12 combinations. Parameters for any technique go in a {technique}_parameters
section. The study uses optional packages (imbalanced-learn for smote,
xgboost, shap for shap_waterfall, and matplotlib, seaborn, and SciencePlots
for the figures), which pip install amos[all] installs.
This is the workflow that amos builds from those settings. The workers run
in order, and the analyst tries every path through its steps:
flowchart TB
    data[("breast cancer data")] --> wrangler

    subgraph wrangler ["wrangler"]
        direction LR
        drop_duplicates --> drop_constant
    end

    subgraph explorer ["explorer"]
        direction LR
        summarize --> missing_values --> label_balance
    end

    subgraph analyst ["analyst: an experiment of 12 combinations"]
        direction LR
        subgraph split ["split"]
            stratified
        end
        subgraph scale ["scale"]
            standard
            min_max
        end
        subgraph sample ["sample"]
            none
            smote
        end
        subgraph model ["model"]
            logit
            random_forest
            xgboost
        end
        split --> scale --> sample --> model
    end

    subgraph critic ["critic"]
        direction LR
        scorecard --> confusion --> permutation_importance
    end

    subgraph artist ["artist"]
        direction LR
        roc_curve --> importance_plot --> confusion_heatmap --> shap_waterfall
    end

    wrangler --> explorer --> analyst
    analyst -- "the combination with the best roc_auc" --> critic
    critic --> artist
Run it
Pass the settings and the data (a pandas.DataFrame, a path to a data file
in any format that nagata reads,
such as csv, Excel, parquet, Stata, SAS, or SPSS, or a scikit-learn dataset)
to Project.create:
import sklearn.datasets

import amos

cancer = sklearn.datasets.load_breast_cancer(as_frame = True)
project = amos.Project.create("cancer.ini", item = cancer, id = "first_run")
result = project.result
print(result.metrics["roc_auc"] > 0.95)
# True
print(sorted(result.figures))
# ['confusion_heatmap', 'importance_plot', 'roc_curve', 'shap_waterfall']
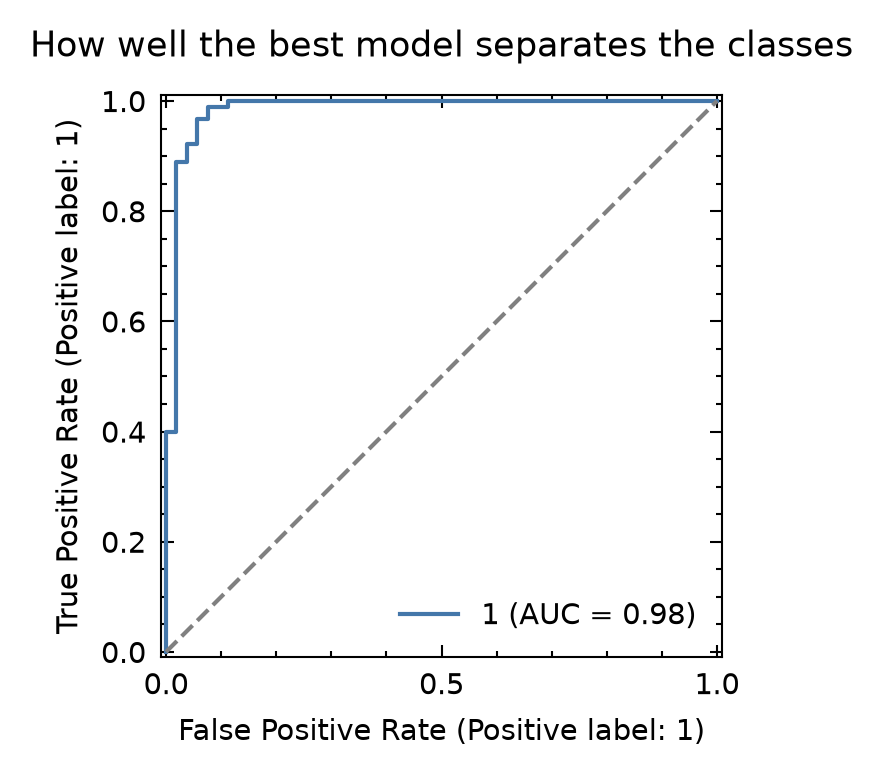
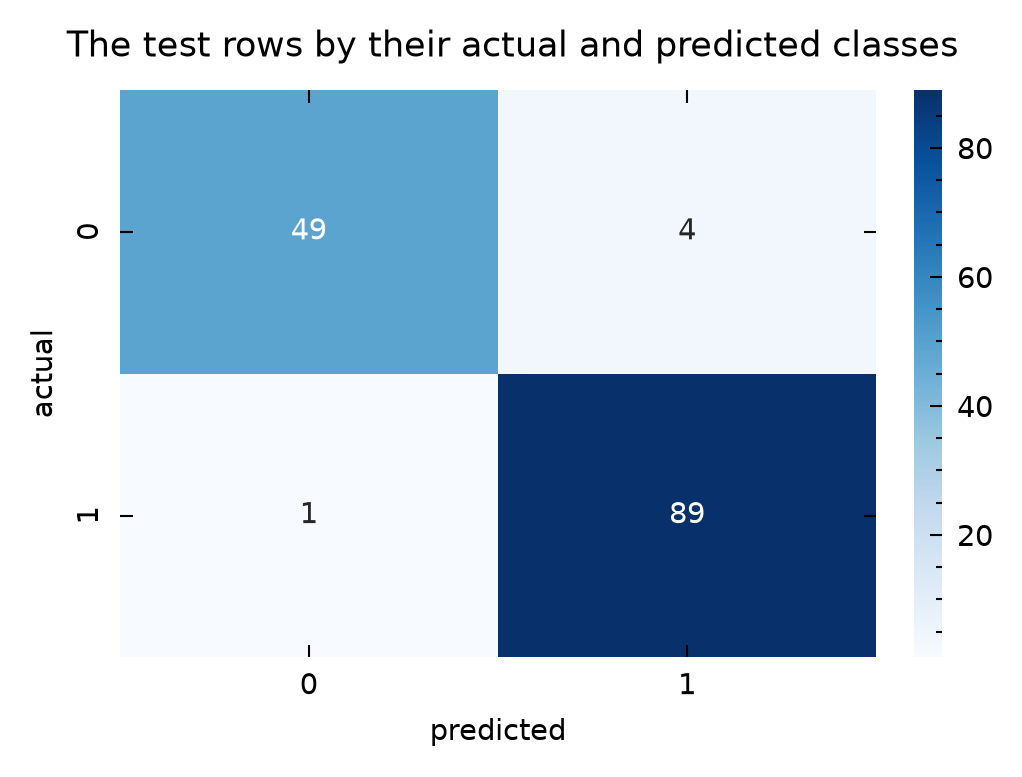
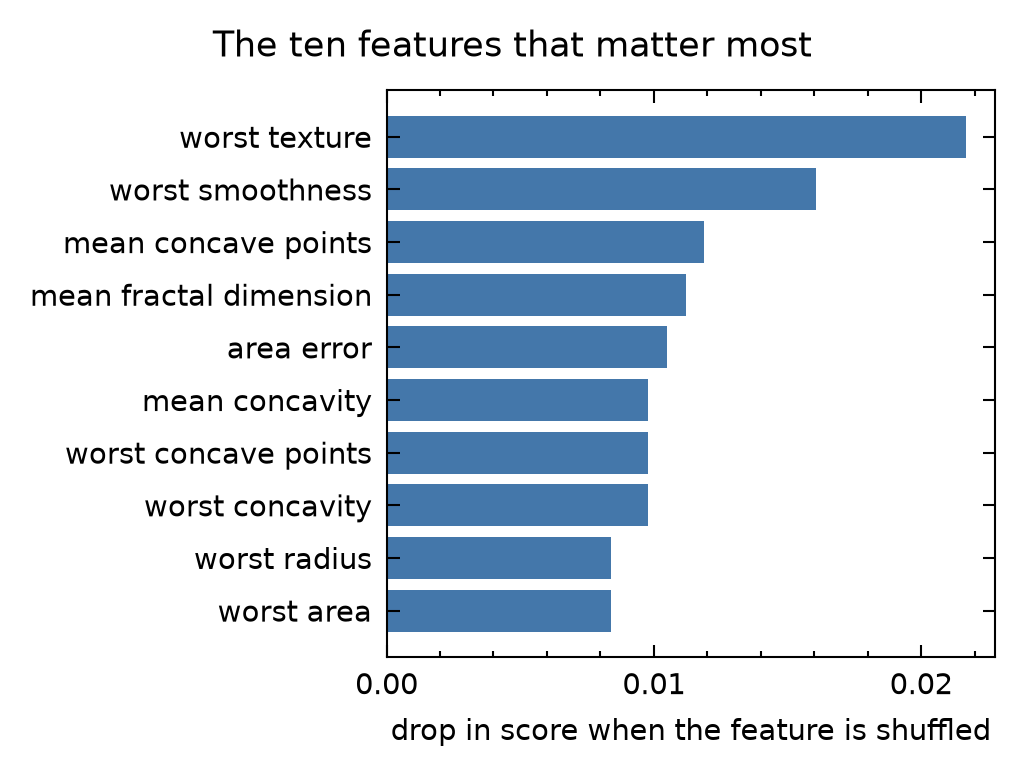
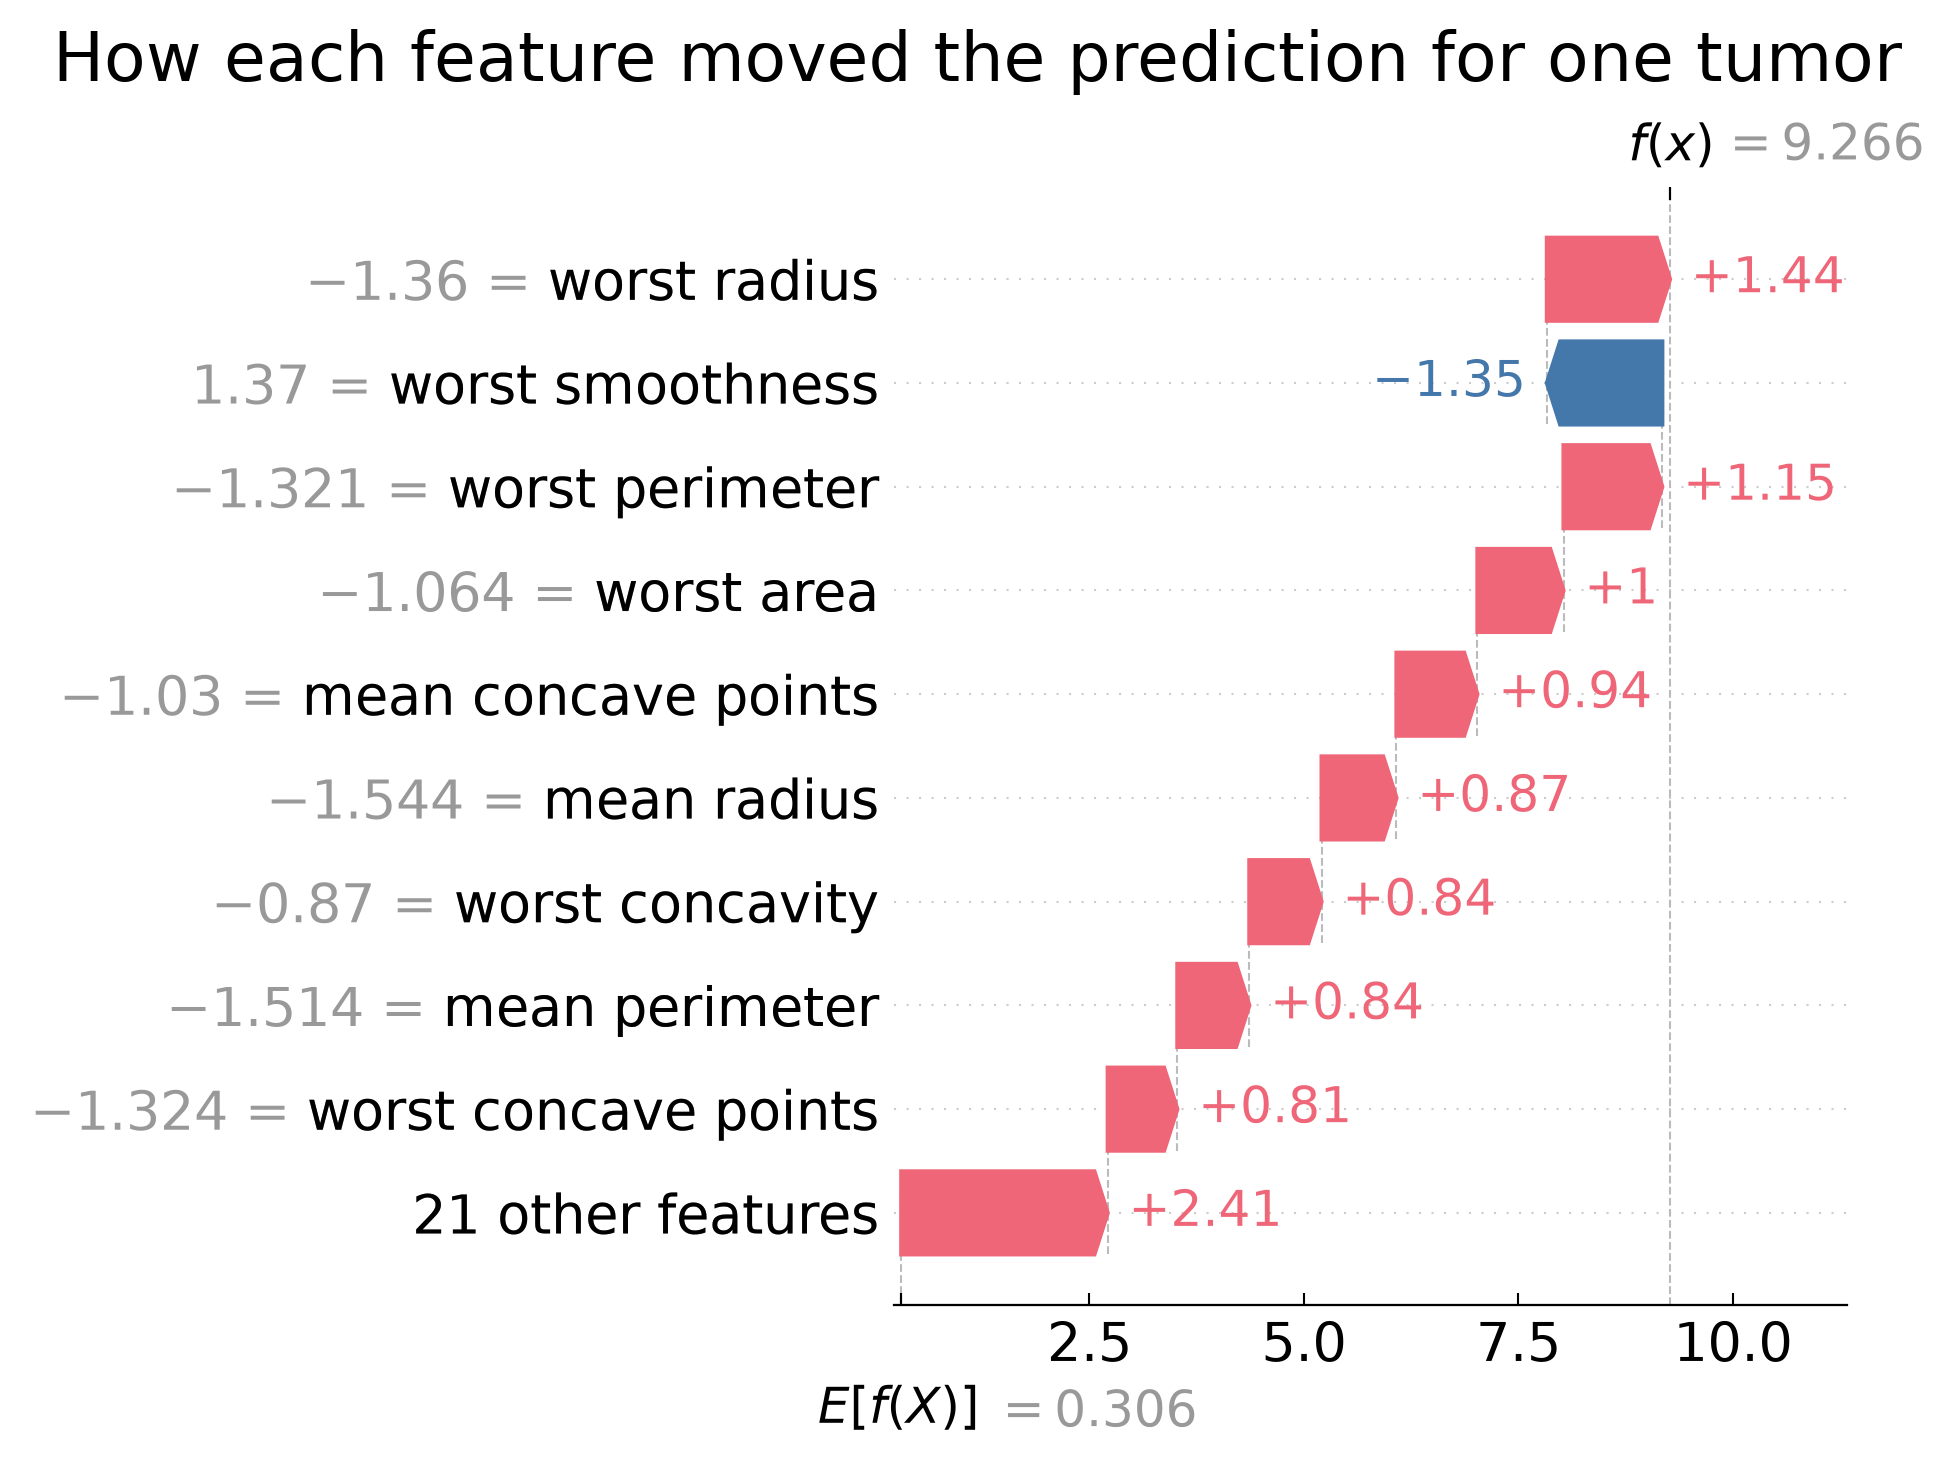
The artist drew four figures, titled by their {technique}_parameters
sections. The ROC curve shows how well the best combination tells the two
kinds of tumors apart on the test rows it never learned from, and the
confusion heatmap counts the test rows that it classified rightly and
wrongly. The importance plot shows how much its score drops when each feature
is shuffled, which works for any model, and the SHAP waterfall shows how every
feature (after scaling) moved its prediction for one tumor:
The result includes a Dataset, the fitted model, its predictions,
metrics, tables, figures, and the history of every technique.
The settings can also say where the data comes from. A loader in the
wrangler (load_file, download, or openml) loads a data file, or
downloads one first, with the project's file manager, and then the project
needs no item. See loading
data.
Compare every branch
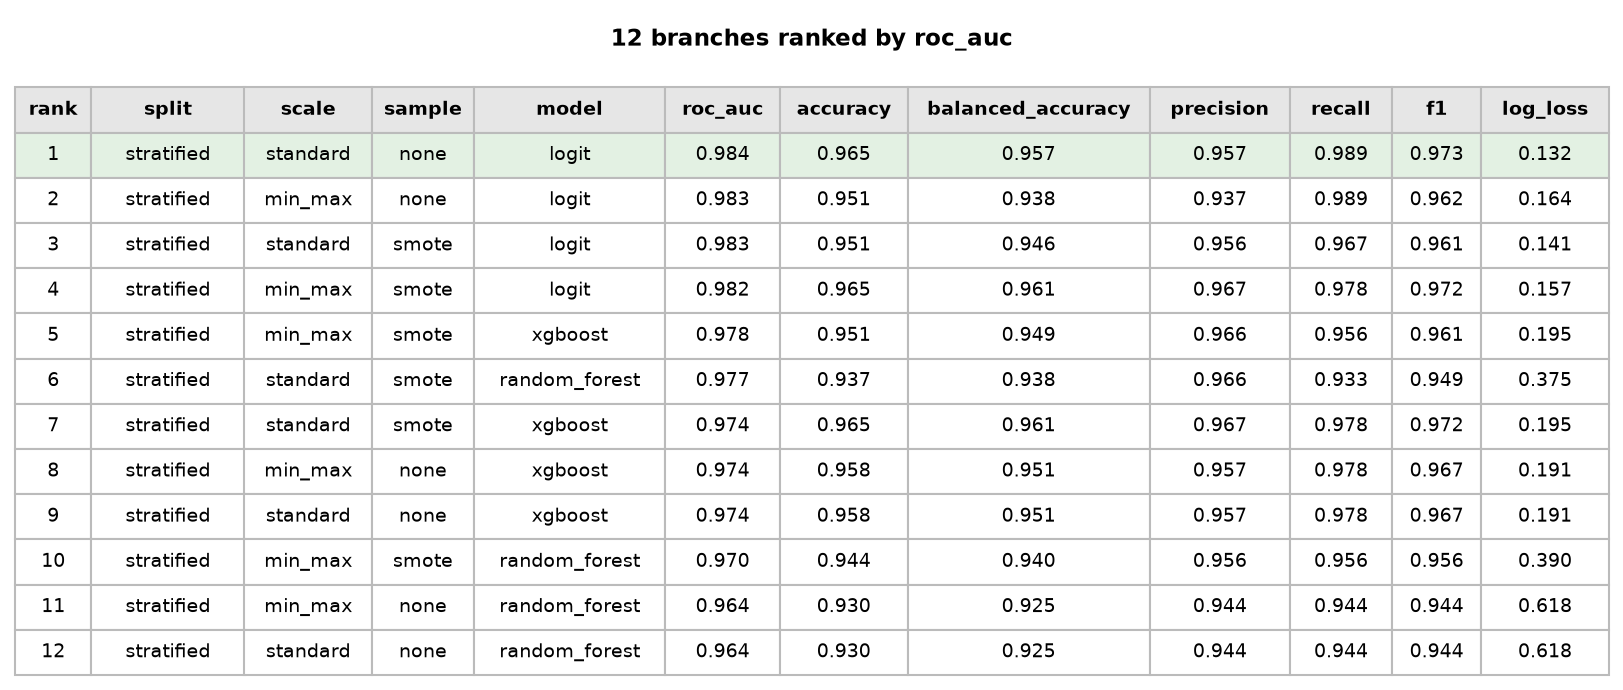
The critic's scorecard compares every branch of the analysis: each
combination of techniques that the experiment tried, ranked by the criterion,
with every standard metric for the task computed from that branch's own
predictions on the test rows. It can be saved as a csv file, a Markdown table,
a Word document, or an image:
scorecard = project.scorecard
print(len(scorecard.table), list(scorecard.table.columns[:5]))
# 12 ['rank', 'split', 'scale', 'sample', 'model']
scorecard.to_csv("scorecard.csv")
scorecard.to_markdown("scorecard.md")
scorecard.to_word("scorecard.docx")
scorecard.to_image("scorecard.png")
This is the scorecard of the study, saved as an image. The best branch is shaded:
Report the estimates
A regression_table reports models the way Stata reports a regression: for
each model, the number of observations and its fit statistics, then each
feature's estimate, standard error, test statistic, p-value, and 95%
confidence interval. Most machine learning models have no coefficients with
standard errors, so amos reports each feature's average marginal effect
(Stata's "dy/dx") instead: the average change in the prediction (here, the
predicted probability of a benign tumor) for a one-unit increase in the
feature. Its standard error comes from refitting the model to 100 bootstrap
samples of the training rows. The fit statistics are cross-validated, since a
flexible model can fit the rows that it learned from almost perfectly. Models
that report their own coefficients and standard errors, such as ols and
logit_sm, show those instead.
Every branch of the experiment is fitted and kept in memory, so the best logistic regression and the best boosted trees can each be reported, and saved as a Word document or an image:
branches = sorted(result.branches, key = lambda branch: branch.score, reverse = True)
tables = {}
for model in ("logit", "xgboost"):
    dataset = next(b.dataset for b in branches if b.steps["model"] == model)
    tables[model] = amos.evaluators.RegressionTable.create(
        {model: dataset}, title = f"The best {model} branch")
    tables[model].to_word(f"regression_{model}.docx")
    tables[model].to_image(f"regression_{model}.png")
print(tables["logit"].to_text().splitlines()[0].split())
# ['logit', 'Number', 'of', 'obs', '=', '426']
print(tables["logit"].estimates.loc[("logit", "mean radius"), "estimate"].round(3))
# -0.012
These are the two images. to_text prints the same table, and one table
can hold several models: as a block for each in Word documents and images,
or side by side, with stars, in csv, Markdown, LaTeX, and HTML.
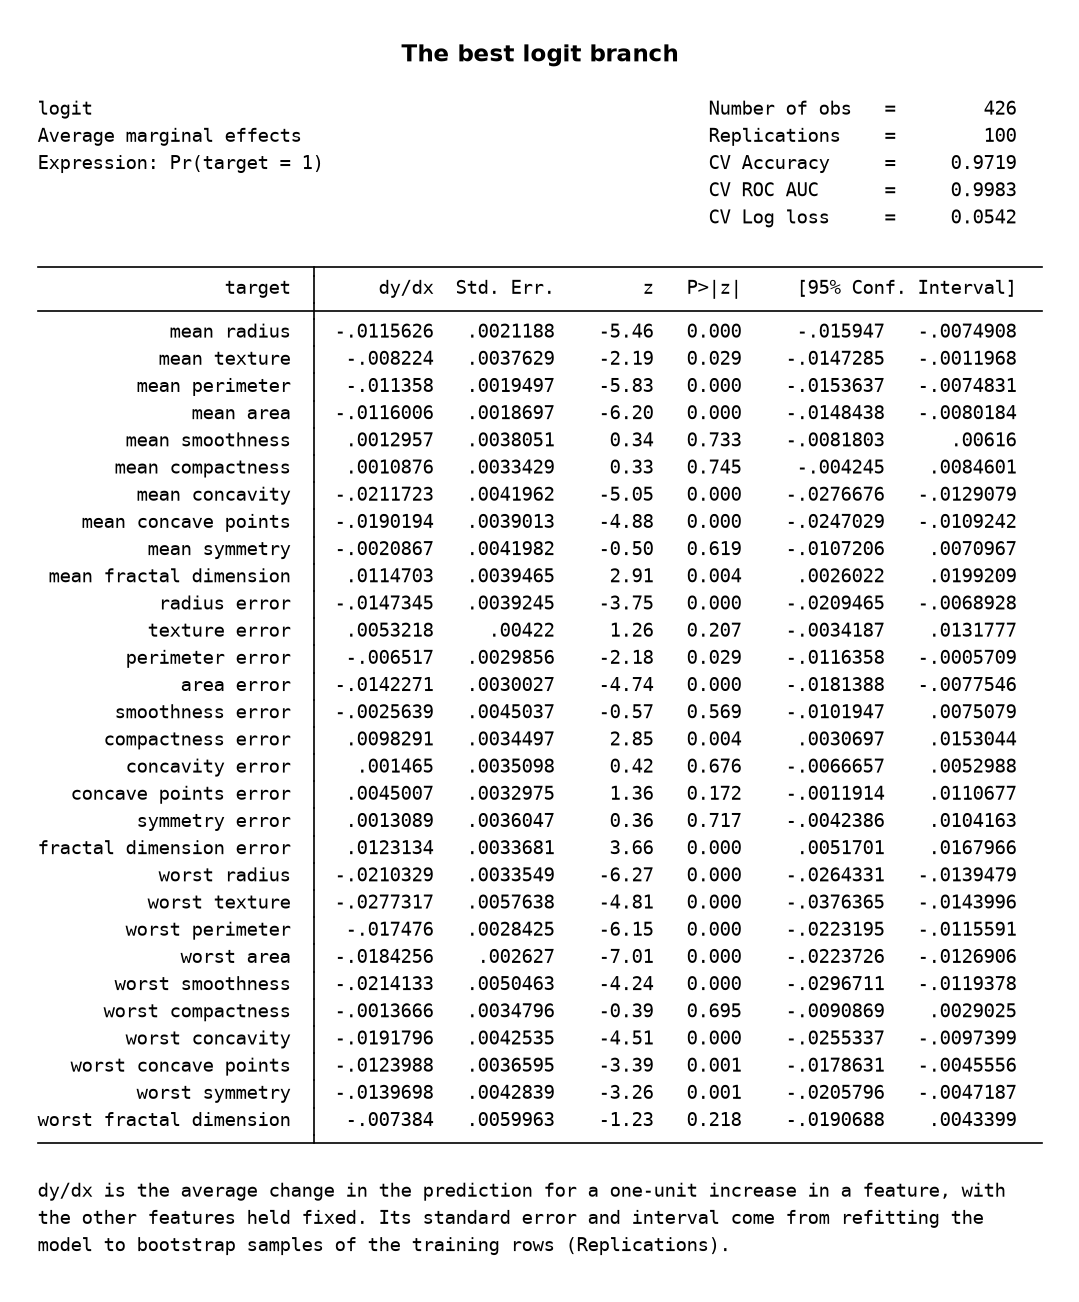
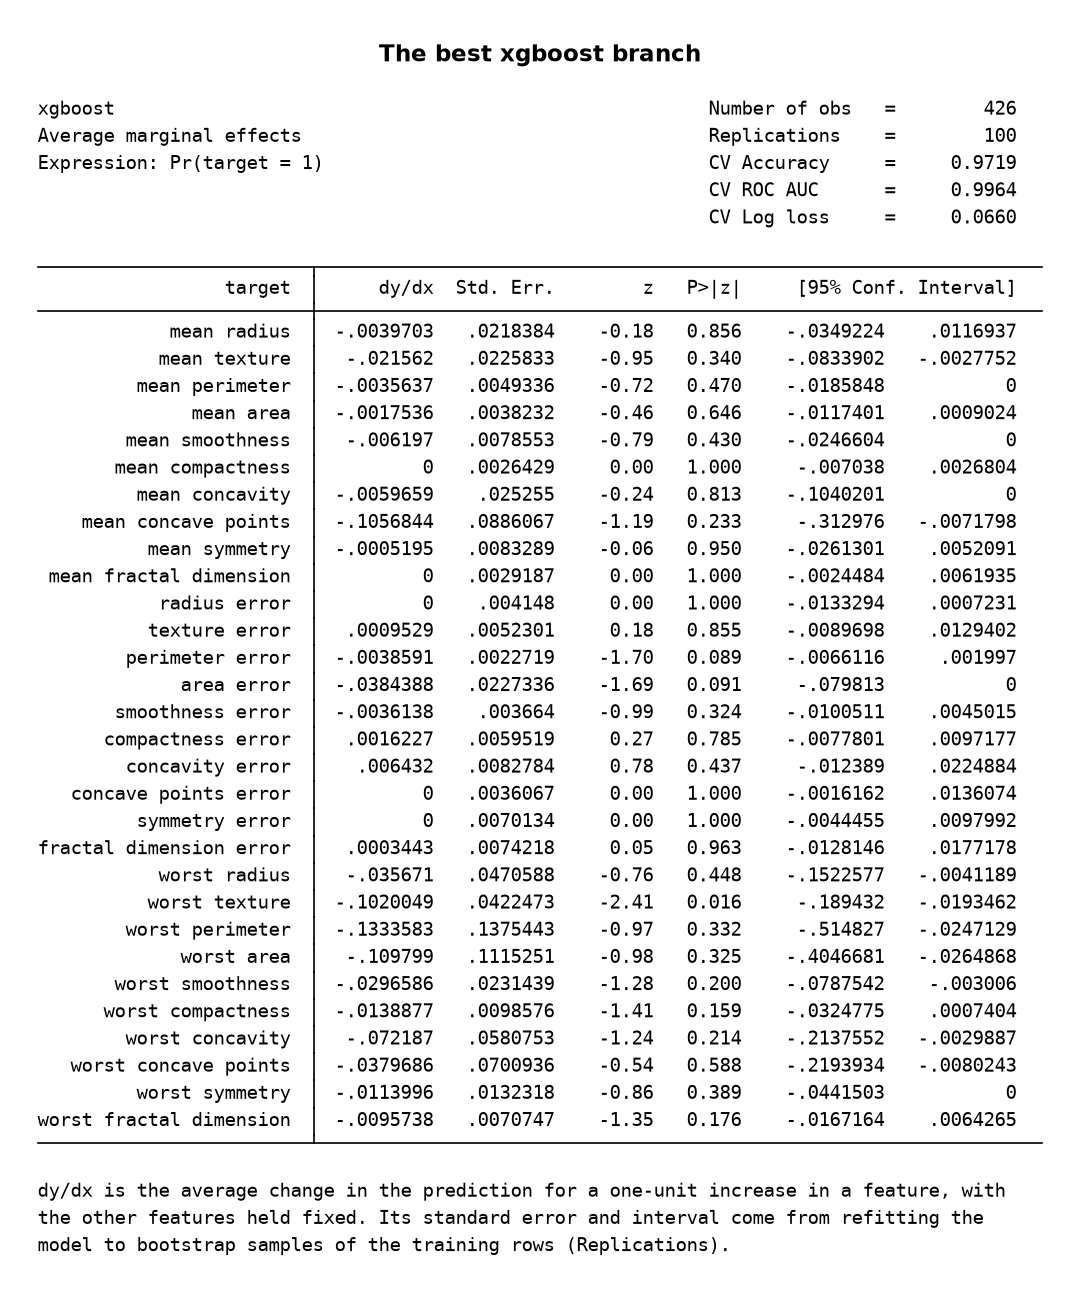
The best logit branch scaled the features with standard and the best
xgboost branch with min_max and smote. So one unit is a standard
deviation of the feature for logit and the feature's whole range for
xgboost. Read the signs, p-values, and fit statistics across the tables,
not the sizes of the estimates. Both models find that larger, more irregular
cells make a tumor less likely to be benign. The logistic regression is
confident about most features. The trees spread their effect over a few
correlated "worst" features, so each one's effect is uncertain on its own,
and a feature that no tree splits on has an effect of exactly 0.
Export the results
export saves everything needed to report and reproduce the results in a
folder named for the run.
There is much more to amos, including hyperparameter searches, statistical
inference with statsmodels, every technique and its parameters, and how to
write your own. See the documentation,
especially the tutorial, the
advanced user guide, the
technique catalog, and the
recipes.
Contributing
Contributors are always welcome. Feel free to grab an issue to work on or make a suggested improvement. If you wish to contribute, please read the Contribution Guide and Code of Conduct.
Similar Projects
- scikit-learn: its
PipelineandGridSearchCVcombine preprocessing and models and search over hyperparameters.amosuses scikit-learn throughout, and adds named columns, supervised encoders, samplers, comparisons of whole combinations of methods, and settings files. - PyCaret: a low-code library that compares many
models with a few function calls. It automates more choices for you, while
amosasks you to list your methods so that they can be reported. - Kedro: a framework for reproducible data pipelines, with more structure for large, long-running projects.
- MLflow and DVC: track experiments,
data, and models over time. They work well alongside
amos.
Citation
If you use amos in your research, please cite it. GitHub's "Cite this
repository" button reads the same information from
CITATION.cff.
@software{yung_amos,
  author  = {Yung, Corey Rayburn},
  title   = {amos: Automated Modeling for Open Scholarship},
  version = {0.4.0},
  year    = {2026},
  url     = {https://github.com/WithPrecedent/amos},
  license = {Apache-2.0}
}
License
Use of this repository is authorized under the Apache Software License 2.0.
1 maintainer

Metadata
1 maintainer
Release files for amos 0.4.0
For a detailed explanation of source distributions (sdists) and built distributions (wheels), please see the package formats documentation.
Source distribution (sdist)
| File | Size | Uploaded | Provenance | |
|---|---|---|---|---|
| amos-0.4.0.tar.gz | 1.8 MB | Without provenance | Details |
Built distribution (wheel)
| File | Interpreter | ABI | Platform | Reset |
|---|---|---|---|---|
| amos-0.4.0-py3-none-any.whl | Python 3 | none | any | Details |
Total release size: 2.0 MB
Release files / amos-0.4.0.tar.gz
| Download URL | amos-0.4.0.tar.gz |
|---|---|
| Size | 1.8 MB |
| Tags | Source |
|
SHA-256 checksum How to use checksums |
42263259860334584f02c76030abdda3c30888fddc6754e784d02ed48058124a
|
|
BLAKE2b-256 checksum How to use checksums |
f1a3d58724adf0632422e36f09e4702c751285f0ef3c6b06285a97e7287f3745
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
Yes |
| Uploaded via |
uv/0.13.4 {"installer":{"name":"uv","version":"0.13.4","subcommand":["publish"]},"python":null,"implementation":{"name":null,"version":null},"distro":{"name":"Ubuntu","version":"24.04","id":"noble","libc":null},"system":{"name":null,"release":null},"cpu":null,"openssl_version":null,"setuptools_version":null,"rustc_version":null,"ci":true}
|
Release files / amos-0.4.0-py3-none-any.whl
| Download URL | amos-0.4.0-py3-none-any.whl |
|---|---|
| Size | 222.4 kB |
| Tags | Python 3 |
|
SHA-256 checksum How to use checksums |
6cf9404a8430618f8cbbf2235bc148746b404a7495e7acc9a68a9e8f4d2e1ce6
|
|
BLAKE2b-256 checksum How to use checksums |
e659b705d4b8a414c1730cc0f96e400213c7e9006aae547e18d8b11b3cf30d49
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
Yes |
| Uploaded via |
uv/0.13.4 {"installer":{"name":"uv","version":"0.13.4","subcommand":["publish"]},"python":null,"implementation":{"name":null,"version":null},"distro":{"name":"Ubuntu","version":"24.04","id":"noble","libc":null},"system":{"name":null,"release":null},"cpu":null,"openssl_version":null,"setuptools_version":null,"rustc_version":null,"ci":true}
|
Security for amos 0.4.0
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.
No provenance found
None of the files in this release were uploaded with provenance metadata.
A note on package security
PyPI is a repository for distributing packages, not a service for auditing them. While third-party security researchers and our staff do their best to detect and remove malicious packages, PyPI cannot guarantee the quality, security or suitability of any given package.














