
ampliscan
Anchor-based amplicon demultiplexer — sort sequencing reads into per-sample bins by their barcodes.


ampliscan splits pooled sequencing reads into per-sample files by matching short
barcodes that sit immediately next to user-defined constant anchor sequences
(e.g. gctt and acag). Using the anchor + barcode together — an
octanucleotide in the common 4+4 case — gives much better discrimination than
the barcode alone, because the constant anchor pins the alignment even when the
barcode region has a sequencing error.
[adapter]  ANCHOR5  [F-barcode]  TARGET  [R-barcode]  ANCHOR3  [adapter]
           └──── octanucleotide ────┘              └──── octanucleotide ────┘
It's built for the second, inner level of demultiplexing that your sequencing facility's i5/i7 index demux does not do — separating samples tagged by barcodes carried on your custom PCR primers.
Features
- Two interfaces, one engine — a scriptable CLI for pipelines and a modern desktop GUI for bench scientists (zero extra dependencies).
- Fully configurable panel — anchor sequences, barcode length, barcode lists, and mismatch policy are all user-defined; nothing is hard-coded.
- Robust matching — Hamming (default) or Levenshtein matching, configurable mismatch budget, and paired-end reconciliation that refuses to guess.
- Transparent failures — unassigned reads are counted by reason
(
no_anchor,barcode_unmatched,barcode_ambiguous,paired_end_disagreement). - Flexible I/O — FASTQ and/or FASTA output, gzip-aware, optional per-strand
(
_fwd/_rev) splitting, streaming writes for bounded memory. - Fast — optional
isalacceleration; validated on real 6.6 M-read libraries.
Install
pip install ampliscan[fast,excel] # 'fast' = isal (2–5× faster gzip)
Or from source:
git clone https://github.com/Ayushmania2002/ampliscan
cd ampliscan
pip install -e .[fast,excel]
Workflow
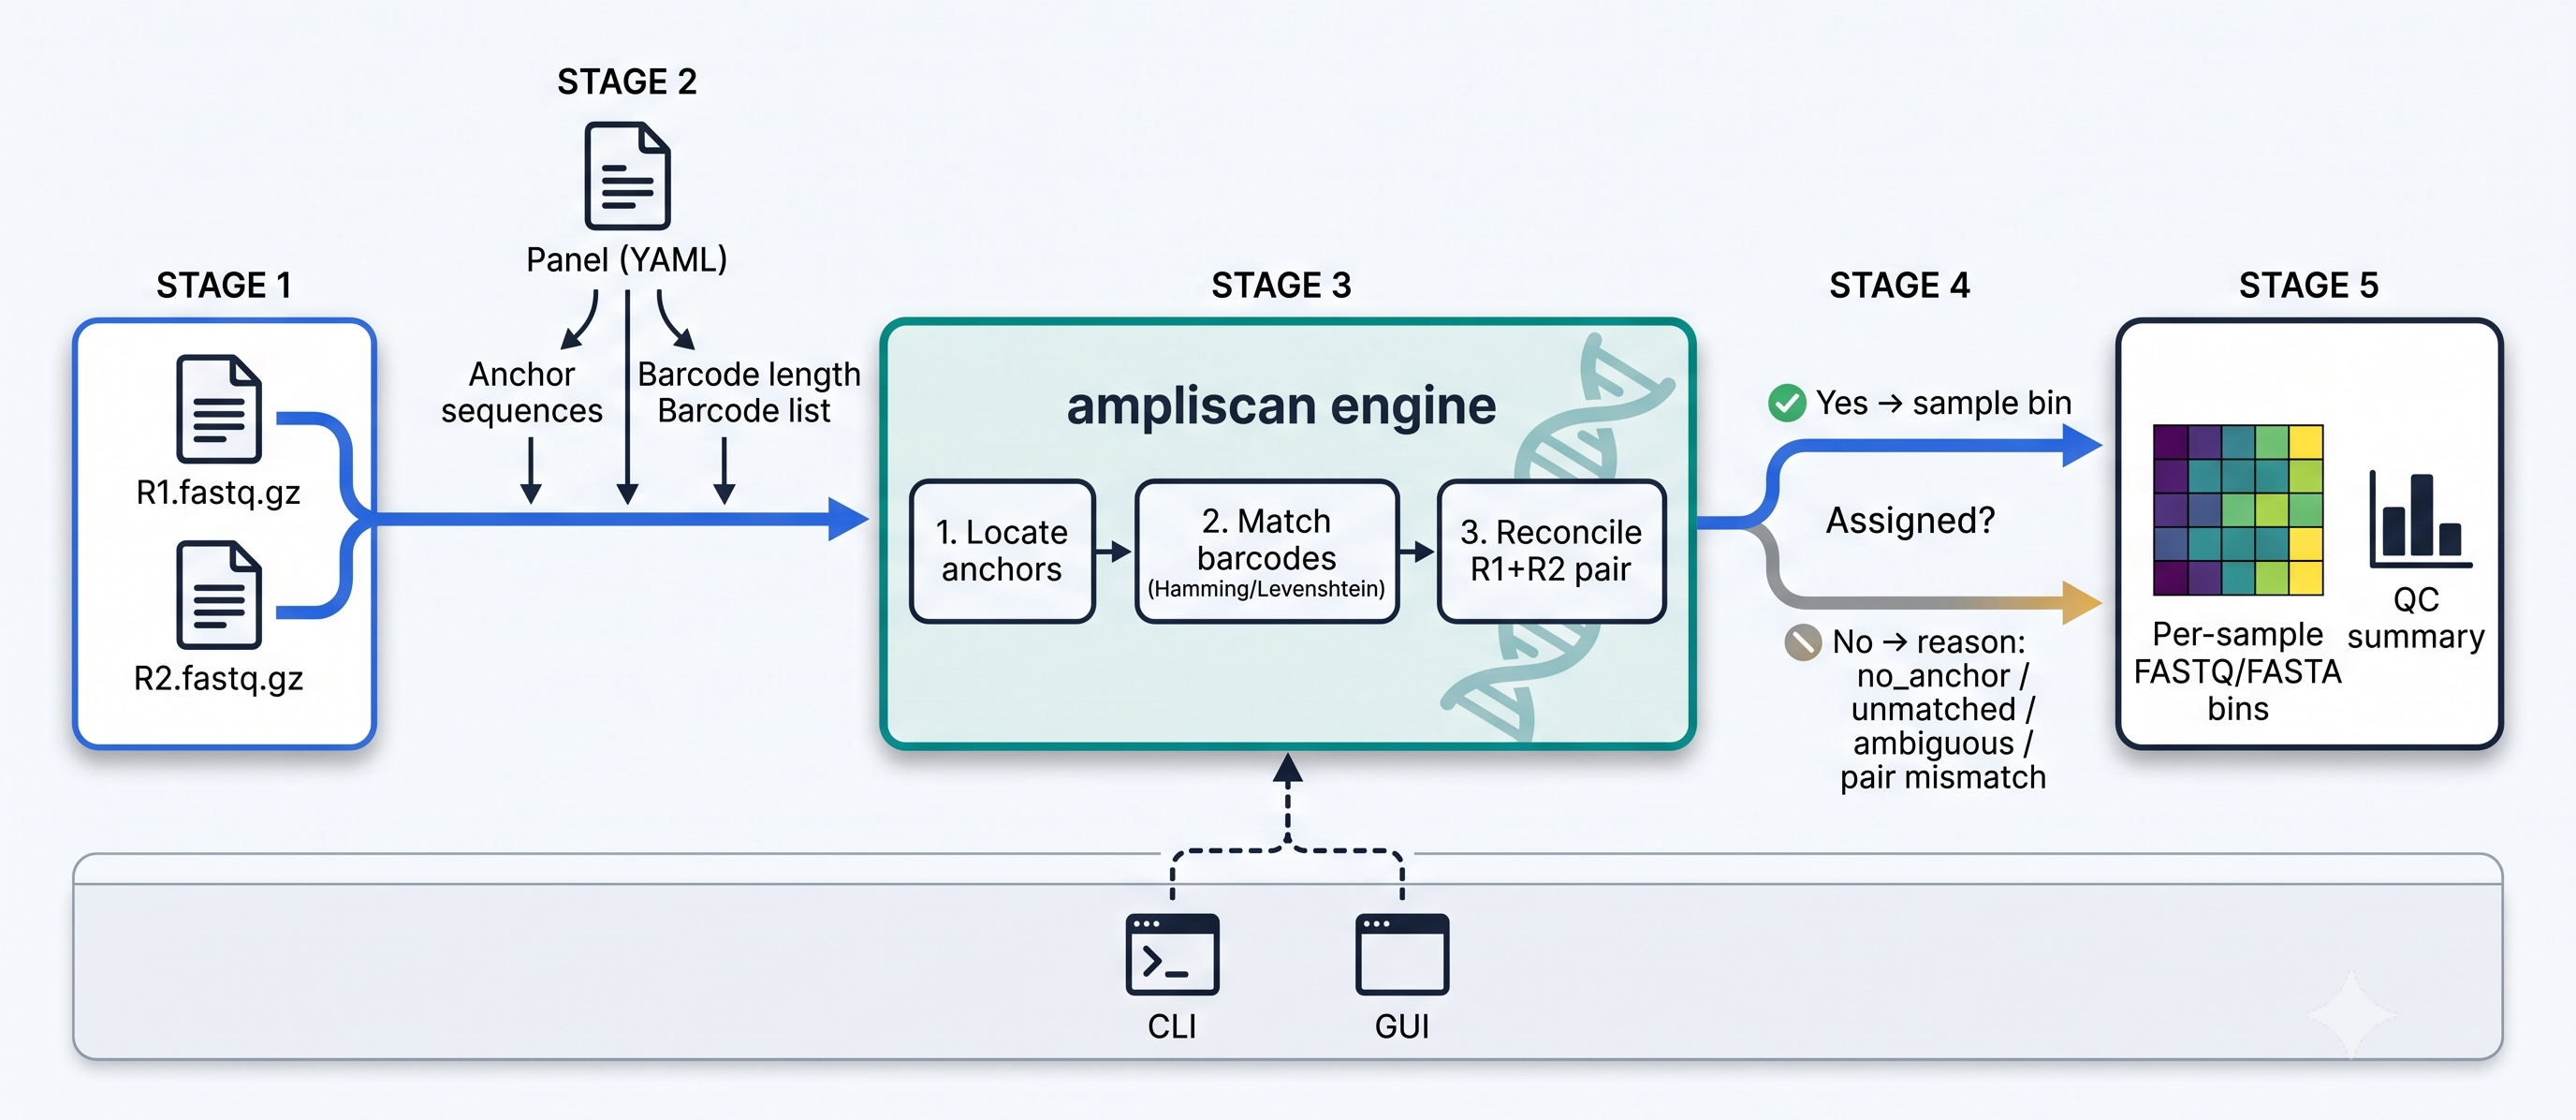
- Input — paired-end (or single-end) FASTQ/FASTA, gzip or plain.
- Panel — a YAML file (or the GUI form) declaring the anchor sequences, barcode length, and forward/reverse barcode lists.
- Engine — for each read: locate the anchors, match the adjacent barcodes (Hamming or Levenshtein), then reconcile the R1/R2 assignment.
- Decision — assigned reads go to their sample bin; unassigned reads are
kept with an explicit reason (
no_anchor,barcode_unmatched,barcode_ambiguous, orpaired_end_disagreement). - Output — one FASTQ/FASTA file per sample, plus a QC summary (heatmap of reads per bin + the unassigned-reason breakdown).
Drive the same engine from either the CLI (scripting/pipelines) or the GUI (point-and-click) — see below.
Usage
Desktop GUI (no terminal needed)
ampliscan gui # or just: ampliscan
Configure the panel (or load it from YAML/Excel), pick your R1/R2 files and an output folder, set options, and run — with a live progress bar, two side-by-side reads-per-bin heatmaps (R1's independent assignment vs R2's) for a quick visual QC check that both mates agree, and an "open output folder" button.
On Windows,
ampliscan-gui(and double-clicking it) opens with no console window. On Debian/Ubuntu, tkinter may needsudo apt install python3-tk.
Command line
ampliscan panel  Data.xlsx --out panel.yaml          # Excel -> panel YAML
ampliscan validate panel.yaml                        # lint it
ampliscan sniff  --r1 R1.fq.gz --r2 R2.fq.gz --config panel.yaml   # quick preview
ampliscan demux  --r1 R1.fq.gz --r2 R2.fq.gz --config panel.yaml --out bins/ --format both
Useful demux flags: --format {fastq,fasta,both}, --split-by-strand
(separate _fwd/_rev files), --workers N (CPU cores; see the speed note),
and --report [PATH] (a single self-contained HTML report with the F × R
heatmap, R1-vs-R2 heatmaps, and a chart of why reads were left unassigned;
defaults to <out>/report.html).
Python API
from ampliscan import Panel, MatchPolicy, demux_to_bins

panel = Panel.from_yaml("panel.yaml")
stats = demux_to_bins("R1.fq.gz", panel, out_dir="bins/",
                      r2_path="R2.fq.gz",
                      policy=MatchPolicy(barcode_mismatch=1),
                      output_format="both")
print(f"{stats.assigned_fraction:.1%} assigned")
See examples/ampliscan_demo.ipynb for an
interactive walkthrough.
A note on speed
For gzipped Illumina input the job is I/O-bound, not CPU-bound: gzip (de)compression dominates and the barcode matching is cheap.
- Installing
isal(pip install ampliscan[fast]) is the real speedup (~1.7× on a full pool) — used automatically when present. --workers > 1does not help gzipped input; raise it only for uncompressed input,--indelsmatching, or very large panels.
How it works
See the accompanying paper, PAPER.md, for the method, the
octanucleotide rationale, validation, and benchmarks.
Citing ampliscan
If you use ampliscan in your research, please cite it (see CITATION.cff):
Ayushman Mallick (2026). ampliscan: an anchor-based amplicon demultiplexer with a desktop GUI for barcode-tagged sequencing reads (Version 1.0.0) [Software]. Zenodo. https://doi.org/10.5281/zenodo.21505581
License
MIT © 2026 Ayushman Mallick.
1 maintainer

Metadata
1 maintainer
Release files for ampliscan 1.2.0
For a detailed explanation of source distributions (sdists) and built distributions (wheels), please see the package formats documentation.
Source distribution (sdist)
| File | Size | Uploaded | |
|---|---|---|---|
| ampliscan-1.2.0.tar.gz | 145.3 kB | Details |
Built distribution (wheel)
| File | Interpreter | ABI | Platform | Reset |
|---|---|---|---|---|
| ampliscan-1.2.0-py3-none-any.whl | Python 3 | none | any | Details |
Total release size: 232.1 kB
Release files / ampliscan-1.2.0.tar.gz
| Download URL | ampliscan-1.2.0.tar.gz |
|---|---|
| Size | 145.3 kB |
| Tags | Source |
|
SHA-256 checksum How to use checksums |
7f76faa06ed10d1a2299c6256a498be7a1d322c897e16e296e3a8b5a57499afa
|
|
BLAKE2b-256 checksum How to use checksums |
06b055624d64c509562ce02701d9b2c84597e947f0d3dbb260d959221d22ded2
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
No |
| Uploaded via |
twine/7.0.0 CPython/3.14.2
|
Release files / ampliscan-1.2.0-py3-none-any.whl
| Download URL | ampliscan-1.2.0-py3-none-any.whl |
|---|---|
| Size | 86.8 kB |
| Tags | Python 3 |
|
SHA-256 checksum How to use checksums |
3cdc5533ee043fb657f82e450446b27bd22a7396683f80619132143347b577d0
|
|
BLAKE2b-256 checksum How to use checksums |
83d11cb7bf545f0e50b9fa90ab409f3d7fb77b7d180fbc0fd7a3128788ead8ae
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
No |
| Uploaded via |
twine/7.0.0 CPython/3.14.2
|














