
async-batch-llm
Run independent LLM calls concurrently with production-grade retries, coordinated rate-limit cooldowns, bounded input buffering, resumable checkpoints, deadlines, and complete token accounting.
The execution pipeline is provider-neutral: wrap your existing async client or use the built-in OpenAI-compatible, Gemini, or PydanticAI conveniences. Use it when you need results during the current workflow; latency-tolerant jobs may be better suited to a provider's native batch API.


Documentation · Getting started · Examples · Changelog
Upgrading from v0.23? Read the v0.24 migration guide for changed cleanup ownership, cancellation, and stream failure behavior.
Quick start
Install the OpenAI and terminal-progress extras, then set OPENAI_API_KEY:
pip install 'async-batch-llm[openai,progress]'
export OPENAI_API_KEY='...'
import asyncio
from async_batch_llm import llm, process_prompts

async def main():
    batch = await process_prompts(
        llm("openai:gpt-4o-mini"), ["Summarize A", "Summarize B"],
        concurrency=10, progress=True,
    )
    print(batch.summary())

asyncio.run(main())
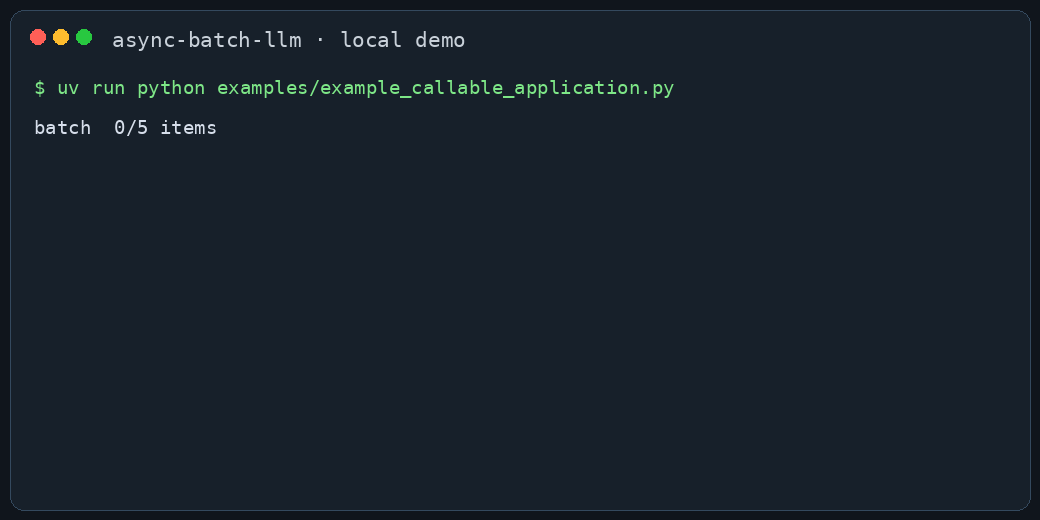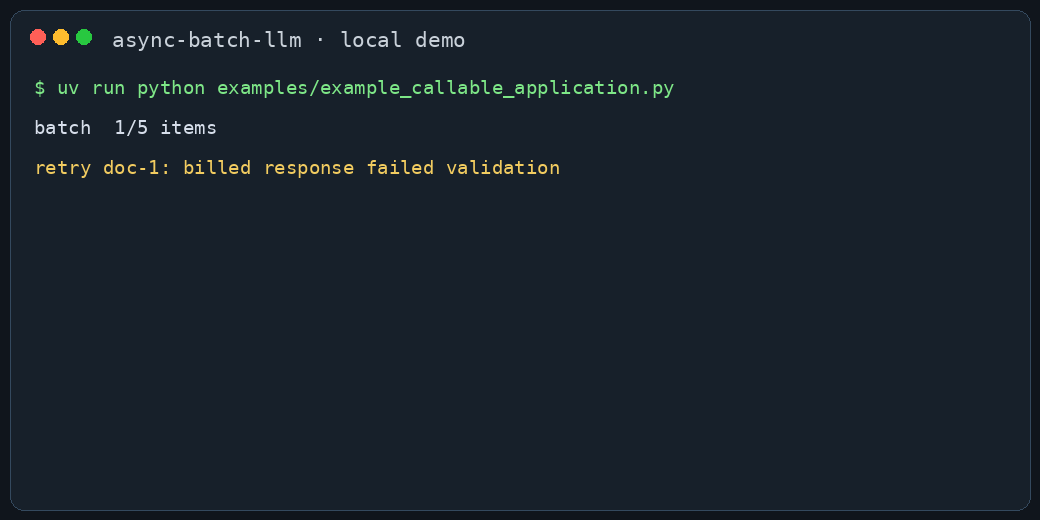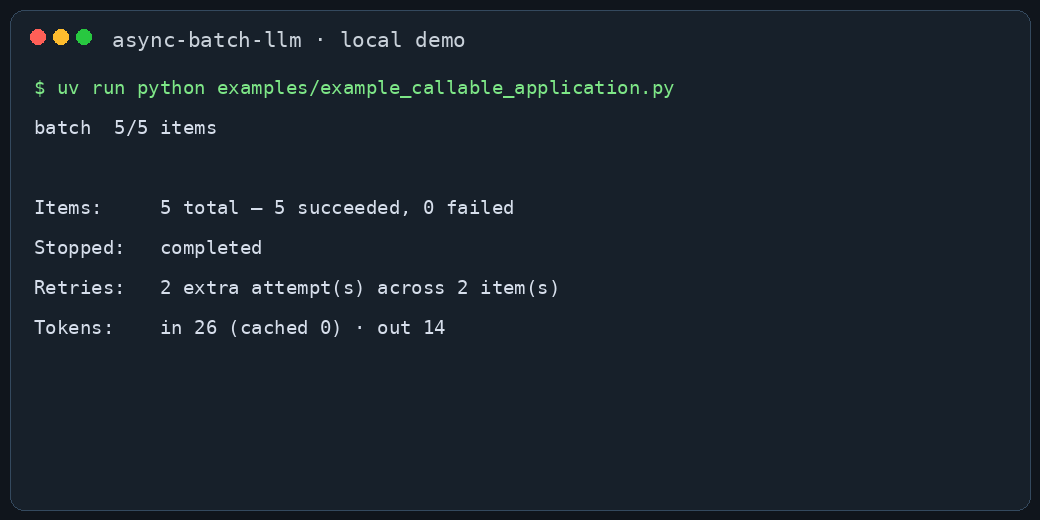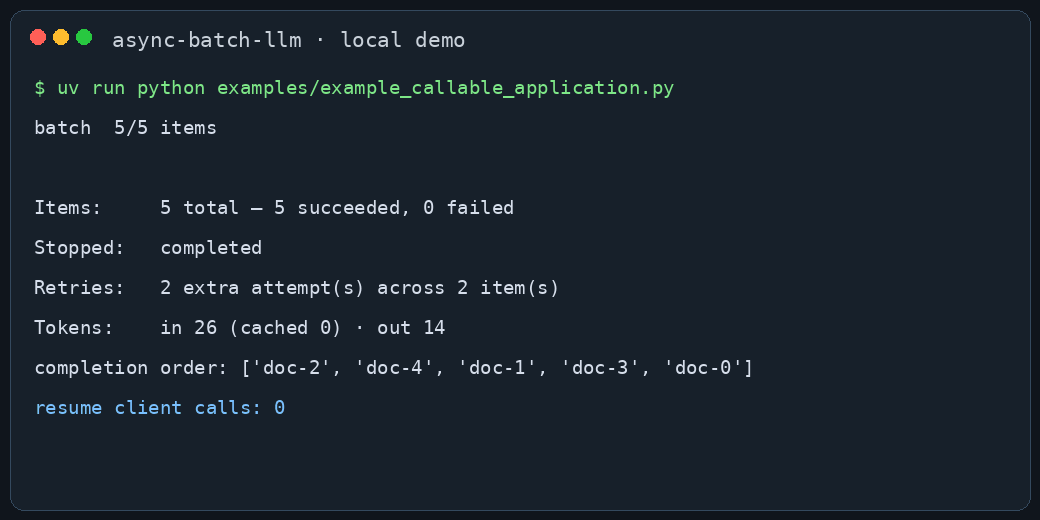
Run the credential-free embedded-application demo, or open the no-key notebook in Colab.
Other provider extras are gemini, openrouter, deepseek, and
pydantic-ai; progress installs tqdm. The core package has no provider SDK
dependency.
Use your existing async client
from async_batch_llm import (
    ArtifactIdentity,
    CallOutcome,
    CallableStrategy,
    ProcessorConfig,
    process_stream,
)


async def invoke(prompt, *, attempt, timeout, state):
    response = await existing_client.generate(prompt, timeout=timeout)
    return CallOutcome(
        response.text,
        token_usage=response.usage,
        metadata={"route": response.route},
    )


strategy = CallableStrategy(
    invoke,
    identity=ArtifactIdentity(provider="my-gateway", model="summary-route"),
)
config = ProcessorConfig(
    concurrency=32,
    max_queue_size=128,
    max_result_queue_size=64,
)

async for result in process_stream(strategy, database_prompt_source(), config=config):
    await save_result(result)
CallableStrategy is an adapter to the same execution path used by built-in
strategies—not a second runtime. It adds bounded input/output handoff,
concurrency admission, coordinated cooldowns, LLM-aware retries, per-item retry
state, deadlines, checkpoint/replay, accounting, and observers around one
existing async operation. See Use Your Existing Async Client.
Built-in providers and result handling
llm("provider:model") covers openai:, gemini:, openrouter:, and
deepseek:; keyword arguments forward to the model constructor (e.g.
llm("deepseek:deepseek-v4-flash", thinking=False, max_connections=150)).
For custom clients, cached models, or custom strategies, use the explicit
two-object form — OpenAIStrategy(OpenAIModel.from_api_key("gpt-4o-mini")) —
described in the provider guides.
Pass (item_id, prompt) pairs to control IDs, or (item_id, prompt, context)
triples to carry application data into each result. Collected results remain in
completion order by default. Pass preserve_order=True, or call
batch.in_input_order(), when stable submission order is required.
For incremental handling, stream results while a bounded work queue applies backpressure to the producer:
from async_batch_llm import ProcessorConfig, process_stream

config = ProcessorConfig(
    max_workers=50,
    max_queue_size=200,
    max_result_queue_size=100,
)

async for item in process_stream(strategy, huge_prompt_source, config=config):
    await save(item)  # completion order
max_queue_size bounds accepted input waiting for workers;
max_result_queue_size bounds completed results waiting for the consumer. Both
default to unbounded. process_prompts() retains every result by design.
Choose an execution surface
| Need | API |
|---|---|
| Collect a finite run | process_prompts() |
| Handle results incrementally | process_stream() |
| Execute one resilient request | call() / call_result() |
| Share limits across service requests | LLMCallPool (LLMGateway compatibility alias) |
| Customize queueing and lifecycle | ParallelBatchProcessor |
Batch, streaming, single-call, and shared-call execution share the same retry, timing, provider-admission, and token-accounting pipeline. See the single-call and shared-call guide and core API for the lower-level surfaces.
What the operational layer adds
| Capability | Behavior |
|---|---|
| Error-aware retries | Separate budgets for content/transport failures and rate limits |
| Coordinated cooldowns | One worker's rate limit pauses the shared execution scope |
| Token-aware admission | Atomic per-scope RPM+TPM reservation with usage reconciliation |
| Bounded streaming | Lazy sources and slow result consumers apply backpressure independently |
| Durable resume | Versioned JSONL or indexed SQLite checkpoints replay only compatible prior results |
| Guardrails | End-to-end item deadlines, batch deadlines, and category-based fail-fast |
| Accounting | Attempt timing and tokens include retries and failed provider calls |
| Observability | Typed lifecycle events, metrics, middleware, and progress callbacks |
For providers with both request and token quotas, enable token-aware admission explicitly (it is intentionally not part of the minimal quick start):
from async_batch_llm import CharacterTokenEstimator, ProcessorConfig

config = ProcessorConfig(
    concurrency=32,
    max_requests_per_minute=500,
    max_tokens_per_minute=200_000,
    token_estimator=CharacterTokenEstimator(expected_output_tokens=400),
)
The Token-Aware Admission guide explains estimators, shared quota scopes, refunds, underestimation debt, retries, and known-zero versus unknown usage.
Why not just use gather?
A semaphore plus asyncio.gather() is enough when all you need is a concurrency
cap. It does not provide coordinated 429 cooldowns, validation-aware retries,
lazy producer backpressure, checkpoint-before-publication durability, or token
accounting for failed attempts. return_exceptions=True also leaves application
code to interpret exception objects mixed into the result list.
Use gather() for a small script when those operational guarantees do not
matter. Use a provider's native batch API when delayed results are acceptable
and its current pricing or throughput is a better fit. See the
scenario-based comparison
for Bespoke Curator, gateways, native batch APIs, and workflow engines.
A dated benchmark snapshot
In a June 10, 2026 GSM8K benchmark using a pre-release v0.12-era build:
- Thirty serial calls took 39–65 seconds; bounded worker pools completed them in 2.1–4.2 seconds on the uncapped providers.
- At equal concurrency over 1,000 prompts, the framework processed 72 items/s on DeepSeek and 108 items/s on Gemini 3.1, compared with 58 and 55 items/s for the benchmark's semaphore pool.
- The full 1,319-item run exposed retries, model escalations, permanent errors, token use, and cost/latency/accuracy tradeoffs in one result model.
These figures are historical evidence, not current provider guarantees. See the methodology, model IDs, pricing snapshot, and complete tables.
An August 27, 2026 follow-up kept the original results and added a fresh
1,319-item provider bake-off: DeepSeek V4 Flash scored 96.9% at $0.1065,
Gemini 3.5 Flash-Lite scored 96.6% at $0.7118, and GLM 5.3 Flash scored 96.3%
at $0.0294. The GLM run was pinned through OpenRouter to Z.AI with fallbacks
disabled; all 1,319 responses confirmed that route, and its cost is the sum of
provider-reported usage.cost values rather than a catalog estimate.
Production checkpoints and guardrails
The complete
production resume example
is runnable. The core configuration looks like this once your strategy and
prompts are defined:
from pathlib import Path

from async_batch_llm import (
    AbortMode,
    ArtifactIdentity,
    GuardrailConfig,
    JsonlArtifactStore,
    ProcessorConfig,
    ResumePolicy,
    process_prompts,
)

store = JsonlArtifactStore(
    "runs/invoice-extraction.jsonl",
    identity=ArtifactIdentity(
        provider="openai",
        model="gpt-4o-mini",
        prompt_version="invoice-v4",
        parser_version="invoice-schema-v2",
        application_version="billing-pipeline-v7",
    ),
    fsync=True,
)
config = ProcessorConfig(
    max_workers=20,
    attempt_timeout=30,  # one provider attempt
    guardrails=GuardrailConfig(
        total_timeout_per_item=180,  # admission, waits, calls, and retries
        batch_timeout=3600,
        abort_on_error_categories=frozenset(
            {"authentication", "insufficient_balance"}
        ),
        abort_mode=AbortMode.DRAIN_ACTIVE,
    ),
)

batch = await process_prompts(
    strategy,
    prompts,
    config=config,
    artifact_store=store,
    resume=ResumePolicy.REUSE_SUCCESSES,
    preserve_order=True,
)

if batch.termination.kind != "completed":
    print("controlled stop:", batch.termination)
Path("summary.json").write_text(batch.to_json(), encoding="utf-8")
Important operational details:
-
Check
batch.termination. Batch deadlines and configured fail-fast stops return completed and collateral terminal results rather than disguising the controlled stop as an unexpected exception. -
Each newly executed terminal result is appended and flushed before it is returned or streamed.
fsync=Truerequests stronger durability; the default is flush-only. -
JsonlArtifactStoreserializes concurrent writes within one process. It does not claim cross-process append safety. -
Replay compatibility includes item ID, prompt, participating context, and the complete artifact identity—not merely
item_id. -
REUSE_SUCCESSESreruns prior failures.REUSE_ALLalso replays compatible terminal failures. -
Raw prompts and contexts are excluded by default. Outputs and metadata are included by default and may contain sensitive application data.
-
Historical replay tokens remain on each result for audit, while live processor statistics exclude them from current-run consumption.
-
For 100k+ restartable runs, swap in the indexed SQLite backend (v0.21) — same records, same replay semantics, no history decode on reopen:
from async_batch_llm import SqliteArtifactStore

store = SqliteArtifactStore("runs/invoice-extraction.sqlite")
JSONL remains the portable, human-inspectable option.
Read Results, Artifacts, and Resume, Large Runs, and Deadlines and Fail-Fast Guardrails for schema compatibility, privacy controls, abort modes, and deadline details.
Provider-neutral execution
Built-in strategies cover:
OpenAIStrategy,OpenRouterStrategy, andDeepSeekStrategythrough the shared OpenAI-compatible model layer.GeminiStrategy, including structured response parsing and shared context caching.PydanticAIStrategyfor PydanticAI agents and typed output.
Anthropic can be used through PydanticAI or CallableStrategy. Other
OpenAI-compatible services can reuse the common model layer or be wrapped as an
existing async client. Subclassing LLMCallStrategy remains available for more
specialized integrations; built-in provider models are not required.
Model identifiers and service limits change independently of this package. Confirm current provider documentation when choosing a model, connection pool, or concurrency limit. See the custom strategy guide and OpenAI-compatible high-throughput guide.
Timing, retry, and ordering semantics
The Choosing Your Limits guide
walks every limit below in decision order — from concurrency= through
connection pools, admission, timeouts, deadlines, ramp, and cooldown — with a
worked 10k-item sizing example.
attempt_timeoutlimits one provider execution attempt (renamed fromtimeout_per_itemin v0.20; the old name is a deprecated alias).GuardrailConfig.total_timeout_per_itemlimits the complete logical item, including coordinated cooldown, startup ramp, proactive rate limiting, provider-capacity admission, calls, retry cooldowns, and backoff.GuardrailConfig.batch_timeoutstarts when the processor run starts.- A fail-fast category triggers only after an item reaches terminal failure; retryable intermediate attempts do not abort the batch.
AbortMode.DRAIN_ACTIVElets an in-progress provider call finish.AbortMode.CANCEL_ACTIVEcancels unfinished accepted work while preserving external caller-cancellation semantics.- Collected and streamed results remain completion ordered by default.
process_prompts(..., preserve_order=True)orders a collected batch by its stable submission index. Streaming intentionally remains completion ordered to avoid blocking behind a slow early item and buffering later results.
See the production checklist and bounded-work guide for queue, connection-pool, and lifecycle guidance.
Results, serialization, and accounting
BatchResult aggregates input, cached, output, and total tokens across retries,
including usage recovered from failed attempts. Token accounting covers attempts
visible to ABL, including recoverable failed-attempt usage. Retries hidden inside
an upstream gateway require gateway-reported usage to be visible. Cost remains
caller-supplied; the package does not bundle a provider price table:
cost = batch.estimated_cost(
    input_per_mtok=current_input_rate,
    output_per_mtok=current_output_rate,
    cached_token_rate=current_cache_rate,
)
WorkItemResult and BatchResult support strict, versioned JSON and JSONL
serialization. Unsupported values raise instead of silently falling back to
repr(). Dataclasses, Pydantic models, enums, dates, UUIDs, paths, tuples, and
sets serialize to JSON-safe values; use an encoder/decoder pair when typed
reconstruction is required. Exception descriptors never restore arbitrary
classes or tracebacks.
See the artifact and serialization API and core API.
Testing without provider calls
Use the included fake strategies and MockAgent to exercise latency, rate
limits, retryable failures, and terminal failures without spending API quota.
The project test suite makes no live provider calls. See the
testing guide.
Examples
Start with these runnable examples:
- Existing async application client, bounded streaming, and replay
- Production checkpoints and guardrails
- OpenAI batch processing
- Single calls and a shared call pool
- Validation-aware model escalation
- Custom embedding strategies
Browse the complete examples directory for Gemini, DeepSeek, OpenRouter, Anthropic, LangChain, caching, grounding, and benchmark walkthroughs.
Documentation
- Getting Started
- Compare Alternatives
- Production Checklist
- Troubleshooting and FAQ
- Results, Artifacts, and Resume
- Deadlines and Fail-Fast Guardrails
- Bounded Work and Backpressure
- API Reference
Contributing
Clone the repository and use its pinned development environment:
git clone https://github.com/geoff-davis/async-batch-llm.git
cd async-batch-llm
uv sync --all-extras
make ci
See the contributing guide or open an issue. For operational help, start with the troubleshooting guide.
License
MIT License. See LICENSE.
1 maintainer

Metadata
1 maintainer
Release files for async-batch-llm 0.24.1
For a detailed explanation of source distributions (sdists) and built distributions (wheels), please see the package formats documentation.
Source distribution (sdist)
| File | Size | Uploaded | |
|---|---|---|---|
| async_batch_llm-0.24.1.tar.gz | 1.1 MB | Details |
Built distribution (wheel)
| File | Interpreter | ABI | Platform | Reset |
|---|---|---|---|---|
| async_batch_llm-0.24.1-py3-none-any.whl | Python 3 | none | any | Details |
Total release size: 1.3 MB
Release files / async_batch_llm-0.24.1.tar.gz
| Download URL | async_batch_llm-0.24.1.tar.gz |
|---|---|
| Size | 1.1 MB |
| Tags | Source |
|
SHA-256 checksum How to use checksums |
4dde594137cffcde862002d7727b65152ac8ce67f3f7e6f00401800a43cc0a8e
|
|
BLAKE2b-256 checksum How to use checksums |
3e7e1f3967703e983fe3816ed72d707f68a1b8017d30d5a275143cd52d57dccf
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
Yes |
| Uploaded via |
twine/7.0.0 CPython/3.13.14
|
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.


PyPI Publish Attestation
PyPI verified that this artifact, at this checksum, originated from the publisher listed below.
Signed by GitHub Actions, verified by PyPI on Sep 11, 2026.
Transparency logRelease files / async_batch_llm-0.24.1-py3-none-any.whl
| Download URL | async_batch_llm-0.24.1-py3-none-any.whl |
|---|---|
| Size | 219.4 kB |
| Tags | Python 3 |
|
SHA-256 checksum How to use checksums |
170f456675e758c89958875ca41e0675e0553f48d03d5578e25ac28fb4449628
|
|
BLAKE2b-256 checksum How to use checksums |
358720169b865d024e53b8872bb750ce378d1704a6a70f0d3e215d1ac512e543
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
Yes |
| Uploaded via |
twine/7.0.0 CPython/3.13.14
|
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.
PyPI Publish Attestation
PyPI verified that this artifact, at this checksum, originated from the publisher listed below.
Signed by GitHub Actions, verified by PyPI on Sep 11, 2026.
Transparency log













